Your plant releases batches against its own limits, but each customer holds a different specification in different words. This app checks a batch against both at once and flags any result that would fail the customer even though it passed at the plant.
PresenterOpens the private repo. Visible to admins only.
For the quality assurance deskCross-domain · Chemicals
Why it matters
Today's manual process, and the same job with the app
Batch quality operations at a chemical or industrial manufacturer that ships one product under several customer specifications.
✕Today's manual process
1Open the batch record and find the plant's own release limits for each determination.
2Find the customer's specification a different document, worded in the customer's own terms.
3Work out the gaps manually checking which results clear the plant's limit but not the customer's.
4One missed gap means a batch ships and gets rejected on the customer's incoming check.
Every batch checked against one specification
✓With the app
1The app reads both specifications the plant's release limits and the customer's own document, side by side.
2Every determination is judged twice once against each specification, in the customer's own wording.
3The gap is derived automatically in code, for any result that passes the plant but fails the customer.
4Nothing ships on its own a flag is raised for a person to check before the batch moves further.
Every batch checked against both, automatically
See it work
One real case, read by the app, step by step
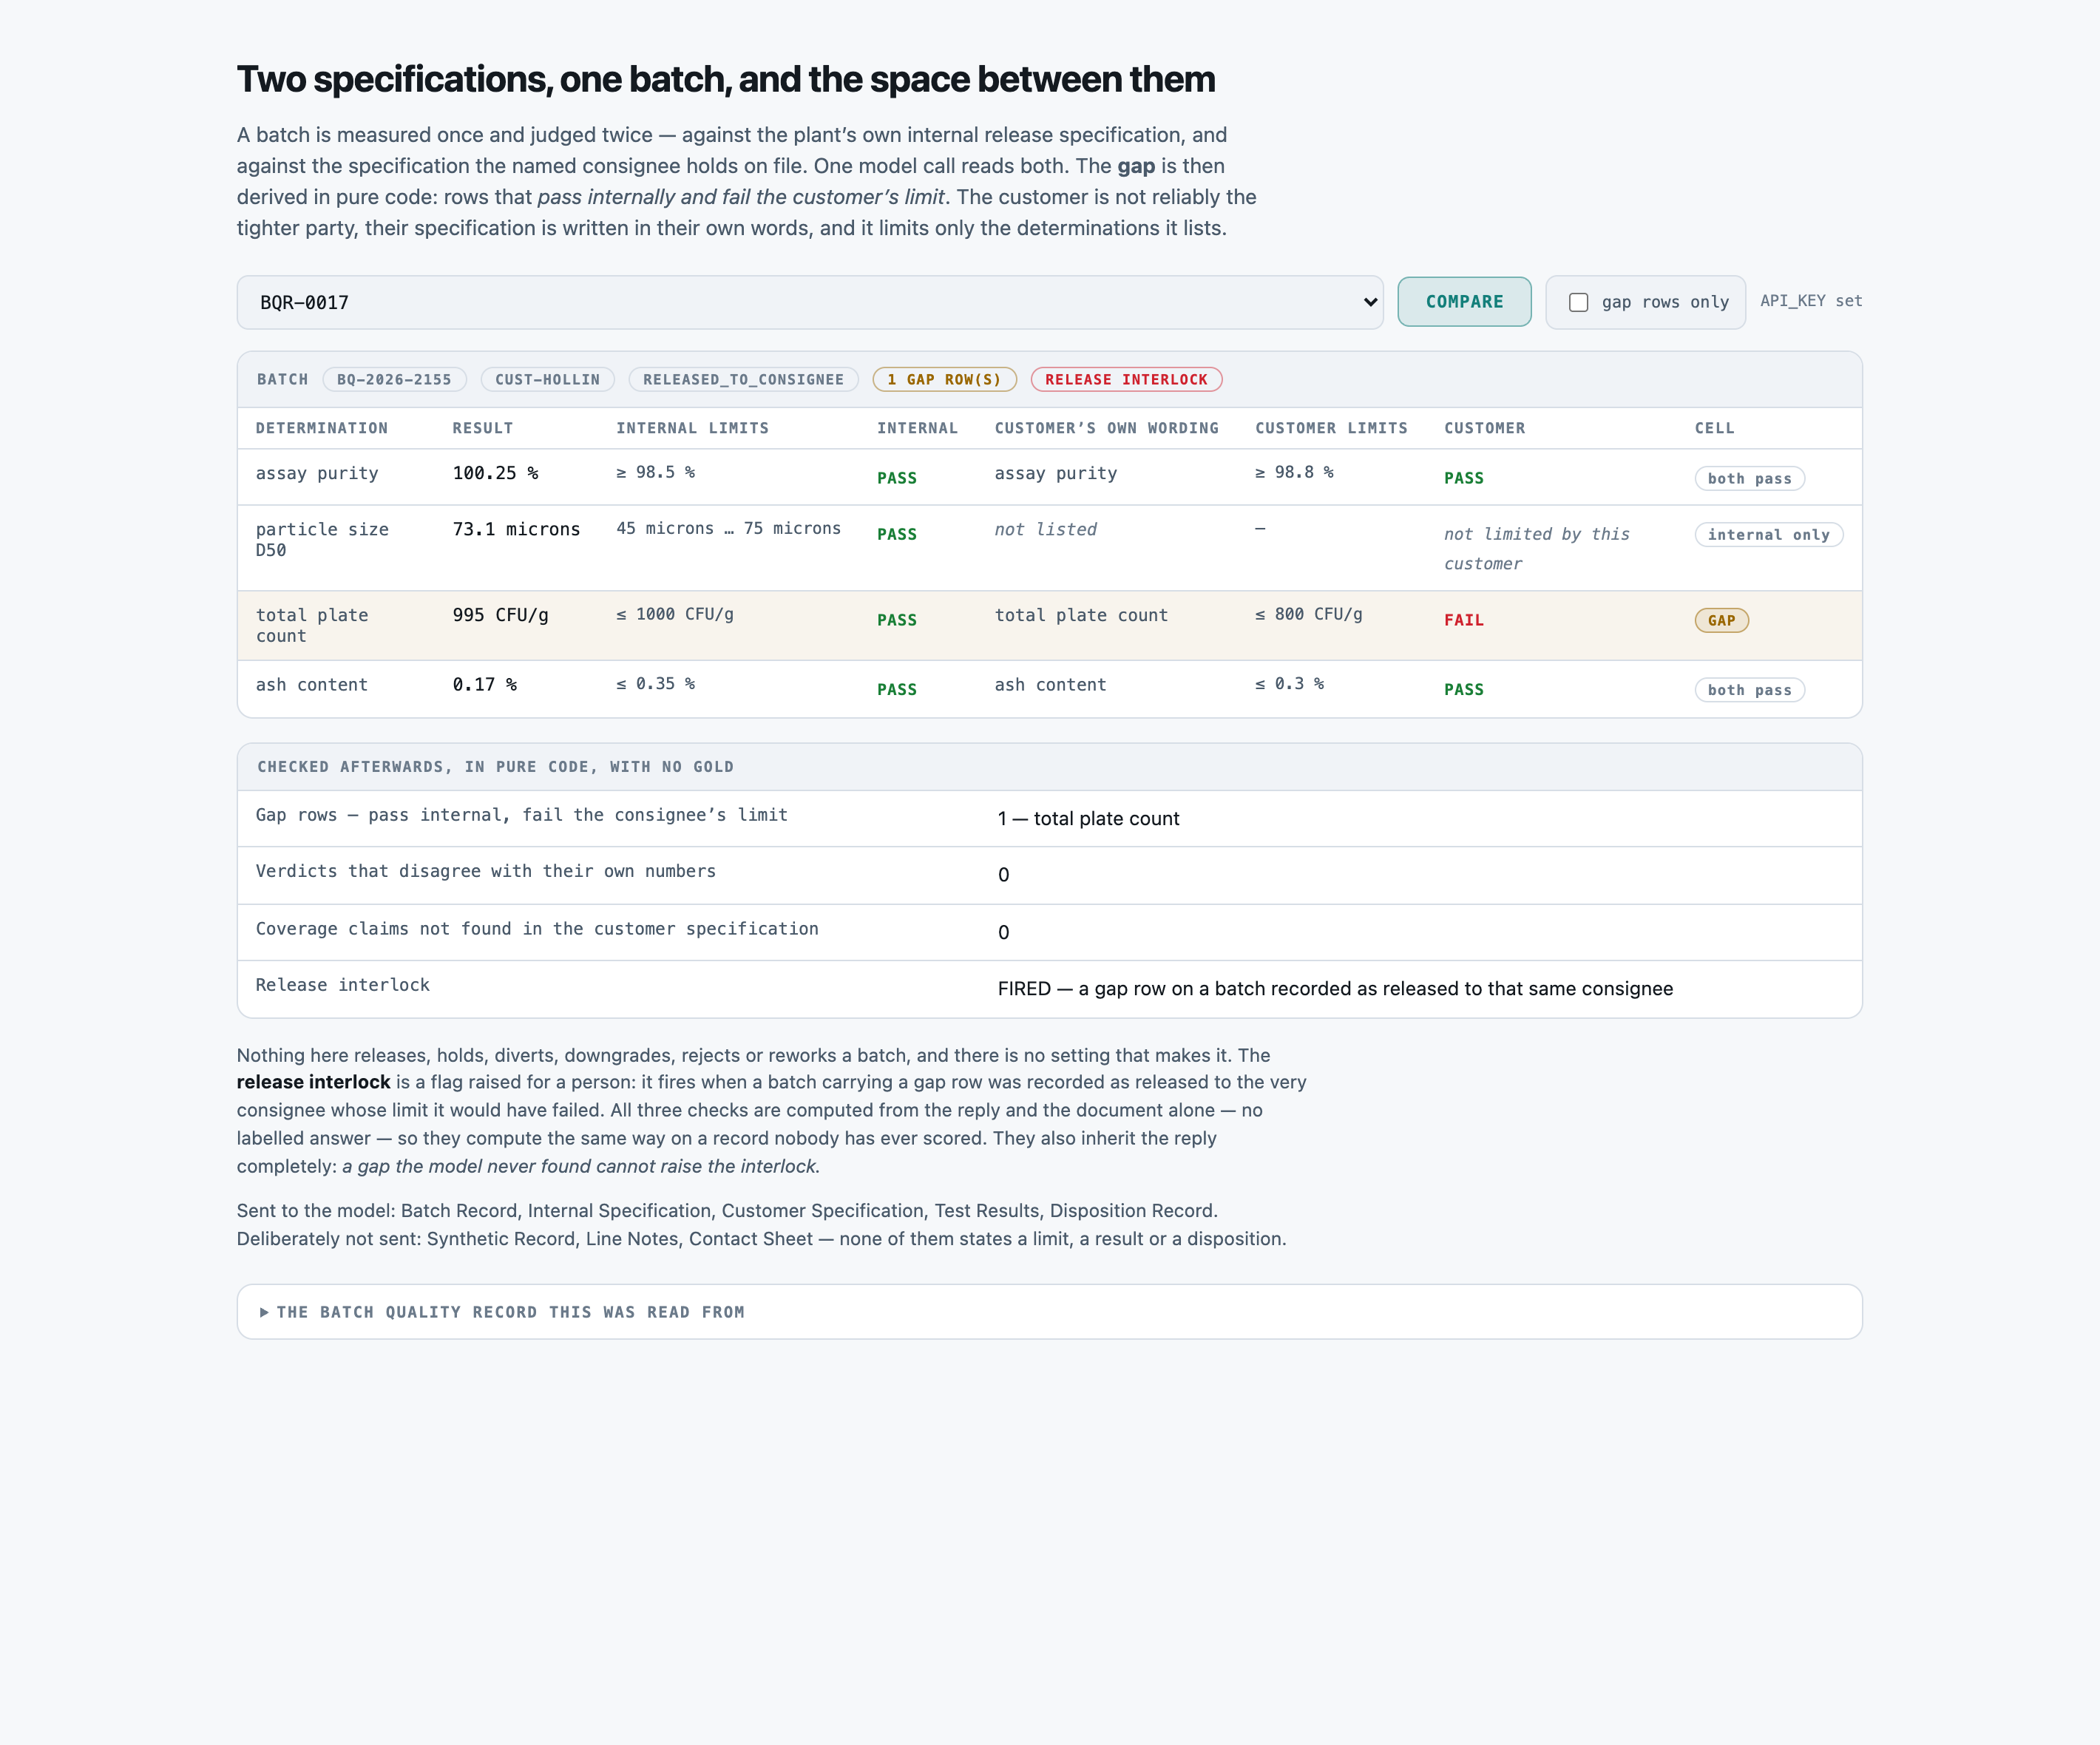
BQR-0017 clears the plant's total plate count limit of 1000 CFU/g but fails the customer's limit of 800.
Catch specification gaps before a batch shipsReference appBuilt to be shaped to your process
5
1One batch, two specifications BQR-0017 was released to CUST-HOLLIN, batch BQ-2026-2155.
2What the app found Total plate count passes internally but fails the customer's tighter limit.
3What doesn't count It isn't in the customer's specification, so it's marked not limited by this customer.
4Proof, not a guess The gap count is derived afterwards in code: 1, total plate count.
5A flag for a person The release interlock fires: a person checks it before the batch ships further.
For engineers
How it is built, and how we measured it
All fourteen steps of the build are written up, from the business case to running it in your own environment.
A small, forkable project that does one job end to end. Run once for real, and every figure on these pages captured from that run.
PresenterOpens the private repo. Visible to admins only.
The business caseThe problem this solves
A plant releases a batch against its OWN internal specification. The customer buys against theirs. The two are different documents, they use different words for the same determination, and neither is reliably the tighter — so a batch can clear every internal limit, ship, and be rejected on the customer's incoming check. A quality system that knows about one specification cannot see that coming, because it has only one verdict to give. Someone opening a batch quality record, finding the plant's own release limits for each determination, then finding the consignee's specification — a different document, in that customer's own wording, limiting only what it happens to list — and working out by hand which results clear the first and would not clear the second. Then reading the disposition record to see what was actually done with the batch.
Audience
Batch quality operations and quality assurance at a manufacturer that ships one product to several customers under several agreed specifications, and the people who build tooling for them. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual batch quality records
The corpus is 44 batch quality records, 0.12 MB (txt 44). Plain text, one format, invented rather than fetched. 216 determination rows across 44 records, and the composition is the whole design: 136 rows the consignee limits and 80 they do not, 81 of the limited ones written in the customer's OWN wording rather than the plant's, and 29 near-miss entries naming a DIFFERENT determination that reads like a tested one. The customer relations are deliberately mixed — 77 tighter, 25 looser, 22 identical and 12 reshaped between one bound and two — because a corpus where the customer is always stricter would reward a prior instead of a reading. That produces 38 gap rows across the set, 9 reverse-gap rows, and 7 batches recorded as released to the very consignee whose limit they would have failed.
The corpus
The 44 batch quality recordsgenerated from a fixed seed, so no real record, person or institution appears in it.
Where each came fromwritten for this kit rather than collected — the corpus is generated in the kit's own repository, so there is no third-party data in it.
Swap this folder for your own material and the kit is pointed at your batch quality records. That is the whole change — there is no database to migrate.
One batch quality record, as the model receives itBQR-0001.txt · 1 of 44
Synthetic Record
----------------
This is a SYNTHETIC batch quality record, generated for the AI Foundry `spec-conformance` kit.
No real manufacturer, customer, person, plant, product, grade, laboratory or release decision
appears in it. Every batch number, product code, consignee, specification reference, limit,
result and disposition is invented, and every email domain is `.invalid`, which is reserved and
cannot resolve. The internal and customer specifications shipped inside this record are this
kit's own construction: they reproduce no published standard, no pharmacopoeia, no monograph, no
regulation and no organisation's own release specification or supply contract.

Batch Record
------------
Record: BQR-0001
Batch: BQ-2026-3499
Product: Brindle Alkalised Cocoa Powder
Product code: PRD-4461
Manufactured on: 2026-06-19
Consignee: CUST-BRAYMOOR (Braymoor Nutrition)
Internal specification: INT-SPEC-4461 rev 9
Customer specification on file: CS-BRAYMOOR-4461 rev 6

Internal Specification
----------------------
Reference: INT-SPEC-4461 rev 9. Applies to every batch of this product regardless of consignee.
Lower and upper release limits. A limit shown as `not specified` places no constraint on that side.

  moisture content       %          lower not specified  upper 0.5 %
  bulk density           g/mL       lower 0.55 g/mL      upper 0.75 g/mL
  ash content            %          lower not specified  upper 0.35 %
  lead                   ppm        lower not specified  upper 1.0 ppm

Customer Specification
----------------------
Reference: CS-BRAYMOOR-4461 rev 6, held on file for consignee CUST-BRAYMOOR (Braymoor Nutrition).
This customer limits ONLY the determinations listed below, in their own wording.
Abridged — the file continues.
The outcomeWhat a good result looks like
One row per determination, carrying both verdicts and the consignee's own wording for the limit it was judged against, plus a batch-level disposition. The gap rows and the release interlock are derived from those in pure code. Informational only — nothing here releases, holds, diverts, downgrades, rejects or reworks a batch.
And when it cannot
This run found ONE wrong determination row of 216 (4 cells of 2292) — a dropped alias on BQR-0010/bulk density — and no gap, interlock or disposition error at all. What it did NOT test: a unit mismatch between a result and the limit it is compared against, a specification revised between the test and the review, a re-test superseding the first, a customer entry whose wording is ambiguous rather than merely different, or a plant with more than one specification library. See Business.not_good_enough and Eval.could_not_verify.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
Finding the batches that cleared your own release specification and would have failed the customer's — the fast tier — it found 38 of 38 gap rows with precision 1.00 The free exact-match floor finds 19 of 38 at the same precision and the free single-threshold floor finds none at all. The 19-row difference is exactly the set whose customer entry is written in the customer's own words.
Classifying what was done with a batch from its disposition record — either free floor — they tie with the model at 44 of 44 The disposition vocabulary in this corpus is two or three wordings a class, which is regex work. Nothing measured here says a model helps.
And where nothing here is good enough:
Running this where the consignee's specification lives in a contract register rather than inside the record — nothing yet — this kit does not do it Every figure on this page assumes both specifications are readable in the same document. The register lookup, and what to do when the register and the record disagree, is work this kit does not contain.
At a glanceHow the whole thing runs
100%gap recall
14,485 msp50, end to end
$7.65per 1,000 batch quality records · Gemini 3 Flash
Run once, for real, on 2026-08-23. Every figure on these pages was captured from that run — nothing is written from intent.
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Catch specification gaps before a batch ships14 steps · 4 questions · run once, for real · 2026-08-23
Every tile is a linkall 14 steps · no step without a page
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
What do I have to bring?
Replace data/corpus/*.txt and supply a gold row per record. The boundary is the SECOND specification.Corpus lens →
When is this the wrong choice?
Avoid: The single-threshold floor for this question specifically — it cannot produce a gap row at all, and its zero is a property of having one verdict rather than a measurement of anything. That is the case against the best-fitting scenario (“Finding the batches that cleared your own release specification and would have failed the customer's”). 3 scenarios scored in all, each with its own.Eval lens →
Where does it stop working?
A result and the limit it is judged against stated in different units — this kit does no conversion, and every row in this corpus states both in the same unit by construction. 5 recorded failure modes, each from a run rather than a guess.Corpus lens →
What was never verified?
Whether the gap matrix would still be clean on a larger or harder set. 38 gap rows on one seed is a small positive class, and the near misses are drawn from a fixed list of nine ordinary confusable determinations — a genuinely AMBIGUOUS customer entry, where two competent analysts would disagree, is not present anywhere in this corpus. 7 items this kit says it could not check.Eval lens →
Can I run this on a model I control?
Yes — any OpenAI-compatible endpoint, including one on your own hardware. The shipped adapter takes its host from BASE_URL and its model from MODEL, so nothing in src/ changes. The published figures come from 1 model on the fast tier, one provider, one key. Prompt lens →
And if it fits — what do I stand up?
4 artifacts with a stated home and a stated egress, and 3 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one.step 14 — Run it in your environment →
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-08-23 — r001-spec-conformance. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — Verified from a cold clone with no key configured: tools/build_corpus.py regenerates all 44 records and their gold rows byte-identically in 0.087 seconds (sha1 of the concatenated corpus and of gold.jsonl unchanged across two runs), evals/check_labels.py re-derives every verdict and passes, and the two free floors both score end to end with no key.
PresenterOpens the private repo. Visible to admins only.
Step 01 of 14Business case
Written for: product manager · Measured during the eval run. Never estimated, never quoted from a vendor page.
In brief
100.0%rows answered
14,485 msp50, end to end
26,815 msp95
2 minclone to first result
What the clock covers. model call only, one per batch quality record
Current processWhat it replaces
Someone opening a batch quality record, finding the plant's own release limits for each determination, then finding the consignee's specification — a different document, in that customer's own wording, limiting only what it happens to list — and working out by hand which results clear the first and would not clear the second. Then reading the disposition record to see what was actually done with the batch.
Where it is not good enough
ONE determination row of 216 was wrong, and it is the error that matters. On BQR-0010 the consignee's specification lists “Loose bulk density: NLT 0.57 g/mL, NMT 0.73 g/mL” and the run returned not_specified — it dropped the alias. That row's result fails BOTH specifications, so the miss cost no gap and no interlock (it moved 4 cells of 2292, which is why the field grade reads 99.83 pct). It is still exactly the failure mode that deletes a gap in silence: the same miss on a row that had passed internally is a batch nobody is told about. It happened once, where it cost nothing, and nothing in this run says how often it would land where it did. A clean 38-of-38 on the gap matrix is 38 rows of positive class, which is a small sample for a comparison this consequential, and the corpus is one seed. It also says nothing about the cases it does not build: a result and a limit stated in different units, a specification revised between test and review, a re-test that supersedes the first, or a customer entry whose wording is genuinely ambiguous rather than merely different. And the disposition classification is regex work here — the free floors score 44 of 44 too, so nothing on this page claims the model bought anything there.
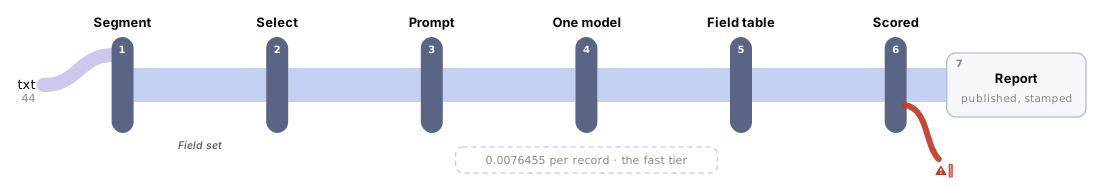
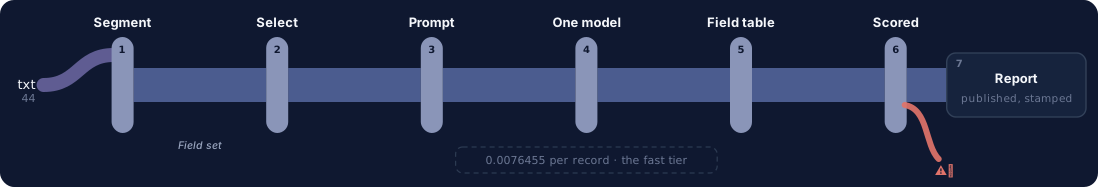
One question, end to end. Colour on the fan-in is the corpus format; a red hook marks every station with a recorded failure, and the words — every sub line, failure and report field — are in the ledger beneath. Every station is a link — click one to jump to its row, and each row links to the lens that explains it.
A batch is measured ONCE and judged TWICE — against the plant's own internal release specification and against the one the named consignee holds on file — and the GAP (pass internally, fail the customer's limit) is DERIVED afterwards in pure code from the two verdicts the reply gave. The model is never asked whether a row is a gap, so it cannot score without holding both verdicts at once. ⚑ TWO FREE FLOORS SHIP AND THEY MEASURE DIFFERENT THINGS. The single-threshold floor is the INCUMBENT — one specification, therefore one verdict — and its gap recall is 0 of 38 BY CONSTRUCTION, which is the measurement rather than a contest; it also asserts a customer limit on all 216 rows, including the 80 the consignee does not limit. The floor worth beating does the whole two-spec comparison in pure code and joins by EXACT NAME only: 19 of 38 gap rows, 5 of 7 interlocks, and wrong about every one of the 81 customer entries written in the customer's OWN wording. That alias set is the model's entire measured advantage — on the disposition classification all three score 44 of 44, and this page does not count that as a win.
⚠︎ The release interlock inherits the reply completely: a gap the model never found cannot raise it. Both specification libraries are INVENTED, applied to every product, and reproduce no standard, pharmacopoeia, monograph or supply contract. No red-team run exists for this kit; this footer names that absence rather than a resistance rate it does not have.
The swap seams
Seam
File
What changes
SEND
src/select.py
which sections of your own record layout reach the model; an unmatched set falls back to the whole document
MARGINAL_BAND
src/compare.py
the proximity-to-limit band that makes a result “marginal”. It is None and the kit publishes no marginal verdict, because the operator question behind it is open; margin() ships the signed distance so a band can be chosen from evidence
compare
src/compare.py
the comparison itself — the boundary convention, or a tolerance band if your programme allows one. It is stated once and used by the corpus generator, the prompt and the guardrail, so changing it here changes all three together
PROVIDERS
src/adapters/__init__.py
any OpenAI-compatible host, or Anthropic's Messages API
the record schema
data/fields.json
a different set of batch and row fields, with their own types and allowed values — the prompt is assembled from this declaration, so it cannot drift from what is scored
Components
Component
File
Role
segment
src/segment.py
cut the record into addressable sections, pure code — and hand the Customer Specification section out on its own, which is what lets a coverage claim be checked against the document rather than taken on trust
select
src/select.py
decide which sections are sent, pure code — five of eight; the synthetic-record banner, the shift's line notes and the contact sheet state no limit, no result and no disposition
compare
src/compare.py
THE comparison, the gap classification and the release interlock, stated once and imported by the corpus generator, the prompt and the guardrail so the three cannot drift. Also the deliberately-unset marginal band
prompt
src/prompt.py
assemble one call per record, with both specifications, the boundary convention, and the three collapse rules stated in full — judge separately, do not assume a direction, do not match a determination that merely looks similar
extract
src/extract.py
the AI layer, one provider one key — plus the three pure-code checks downstream: recompute both verdicts from the reply's own numbers, locate every coverage claim in the customer specification, and raise the interlock
judge
evals/judge.py
score four things separately — field cells, customer coverage, the gap matrix and the disposition — pure code, no model and no key
Where it breaks at scale
One call per record, no concurrency and nothing shared between calls: 44 records took 683 seconds wall clock, at a p50 of 14.5 seconds a record. A release queue of thousands needs batching and a rate-limit strategy this kit does not have. It also reads one record in isolation — no re-test supersedes a first result, no sister lot on the same production run is consulted, and no specification revision between test and review is noticed. And the consignee's specification here lives INSIDE the record; a real plant holds it in a contract register, so a production version needs a lookup this kit does not have and a story for what happens when the register and the record disagree.
PresenterOpens the private repo. Visible to admins only.
Step 03 of 14App UI
Written for: anyone, in 5 seconds · Screenshots of the running app taken during the run.
SuccessesWhen it works
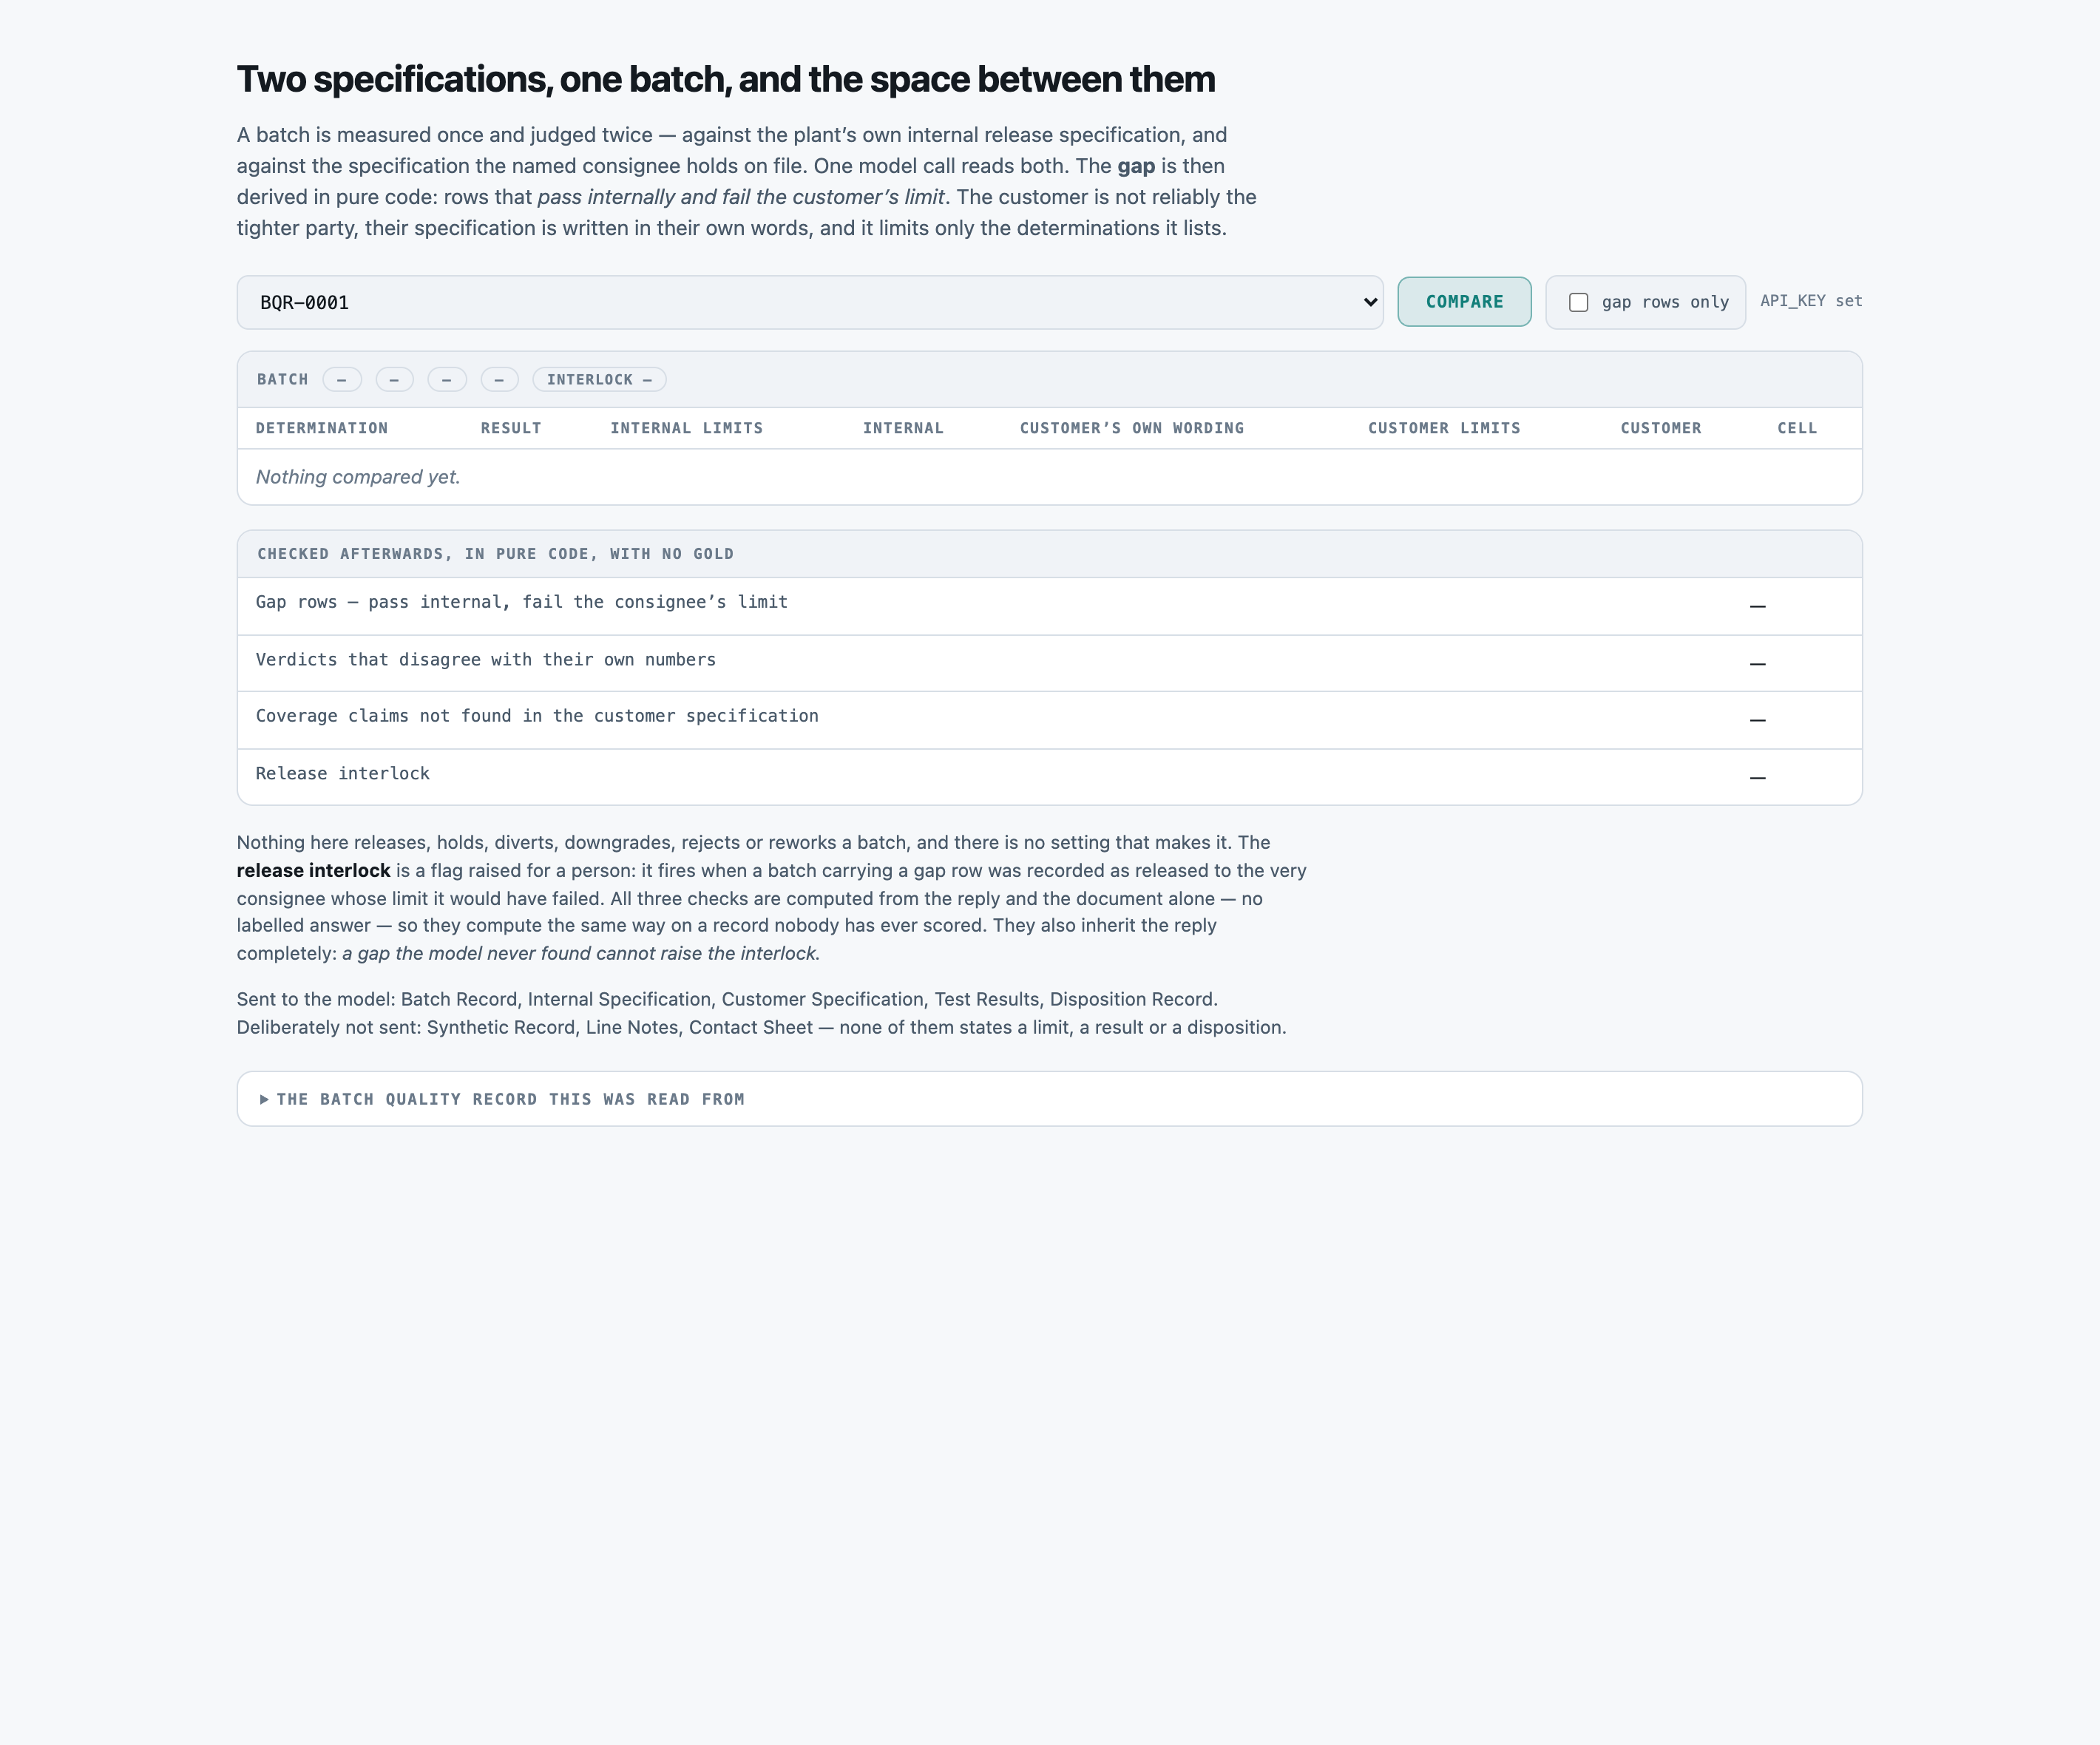
Before anything is asked of the model. Eight columns because the question has two halves — the plant's limits and verdict, then the consignee's own wording, their limits and their verdict — and a derived Cell chip for how the two stand. Under it, the three checks that run afterwards in pure code and need no labelled answer.successOpen full size →BQR-0017, compared live. Three of this kit's difficulties on one record: total plate count at 995 CFU/g clears the plant's 1000 and fails the consignee's 800 — the GAP, highlighted; particle size D50 at 73.1 microns is left “not listed” because the only thing resembling it in the customer's specification is “Particle size D90”, a different determination; and the disposition record says the batch was released and allocated to CUST-HOLLIN, so the RELEASE INTERLOCK fires.successOpen full size →
LimitsWhen it does not
A report showing only wins is an advert. This one is required, and the validator now refuses a kit that omits it.
The same button with no API_KEY configured. A calm 200 and a plain sentence, not a stack trace: nothing was called, nothing was spent, and the record stays browsable. Note the interlock chip reads “—” rather than the green “interlock clear” — an unknown is not a clean bill, and it rendered as one until the screenshot was opened.failureOpen full size →
PresenterOpens the private repo. Visible to admins only.
Step 04 of 14Corpus
Written for: "can I point this at mine?" · Measured off the corpus the run actually used.
In brief
44batch quality records
0.12 MiBtxt 44
352sections · p50 35 chars
$0.00setup · 0.005s
How it is cutWhat one section is
cut on underlined section headings; a record with none falls back to one whole-document segment so a span still resolves
SetupWhat the setup figure measured
There is no index. Preparation is segmentation only — 44 records cut into 352 sections by src/segment.py in 0.005 seconds, pure code, no model and no key.
LicenceLicence
MIT — this repository's own licence. Every plant, product, consignee, specification reference, limit, result and disposition is invented. A real batch quality record cannot be published either: it names a real customer, states that customer's contractually agreed limits, and carries a real release decision by a named person.
Bring your ownBring your own batch quality records
Replace data/corpus/*.txt and supply a gold row per record. Three things will need editing for a different layout: SEND in src/select.py (your section headings), the column slices in evals/baseline.py (your table layout), and the whole specification library in tools/build_corpus.py — the limits there are invented and resemble no real standard. If your records are unlabelled, the field grade and all four matrices go away and the three pure-code checks do not: they are computed from the reply and the document alone.
⚠︎ And what stops being true when you do: The boundary is the SECOND specification. This kit assumes the consignee's limits are readable in the same document as the results. Where they live in a contract register instead, everything above the model call still applies and the join to that register is work this kit does not contain and does not estimate.
What breaks it
A result and the limit it is judged against stated in different units — this kit does no conversion, and every row in this corpus states both in the same unit by construction.
A customer limit written into free text rather than the specification list — src/select.py deliberately does not send the shift's line notes, so “customer agreed 0.40 on the phone” is invisible to this kit.
A specification revised between the test and the review, or a re-test that supersedes the first — each record carries one revision of each specification and one result per determination.
A consignee's specification held in a contract register rather than inside the record — the real case, and the lookup does not exist here.
Scanned or image-only records — there is no OCR step.
PresenterOpens the private repo. Visible to admins only.
Step 05 of 14Prompt
Written for: engineer · Logged from the run, verbatim.
In brief
The assembled prompt in full, and its real decomposition. Every part below occurs in the prompt that was actually sent, and the token counts sum to the recorded input total — they were measured against the provider’s own counter, not apportioned by character share.
AssemblyHow the prompt is assembled
Part
Characters
Tokens
system
3,116
796
record schema
2,545
585
record sections
1,832
524
Total
1,905
This is the cost lesson as arithmetic: of the 1,905 tokens assembled, 796 are instructions — 42% of the prompt, the largest single part. A per-request bill follows whichever part is biggest, and on this kit that is the one named here.
Measured token-for-token via evals/prompt_tokens.py's nested-prefix subtraction against the provider's own tokenizer, not estimated from characters — see results/tokens-p001-spec-conformance.json.
Full promptThe prompt in full
The verbatim prompt, as sent
the prompt, as sent
You compare one manufactured batch's laboratory results against TWO separate specifications and report both verdicts. You return JSON and nothing else.

THE TWO SPECIFICATIONS ARE NOT THE SAME DOCUMENT AND ARE NEVER MERGED:
- The INTERNAL specification is the plant's own release specification. It applies to every batch of the product whatever the consignee is.
- The CUSTOMER specification is the one held on file for the consignee named on this batch. It is written in that customer's own wording and limits ONLY the determinations it lists.

RULES, in order of importance:
1. JUDGE EACH SPECIFICATION SEPARATELY. `internal_verdict` is decided against the internal limits alone and `customer_verdict` against the customer limits alone. NEVER copy one verdict into the other, and never combine the two sets of limits into a single window before comparing. The two answers are allowed to differ and often do -- that difference is the entire point of this task.
2. BOTH VERDICTS ARE ARITHMETIC. A result passes when it is greater than or equal to the lower limit AND less than or equal to the upper limit. BOTH LIMITS ARE INCLUSIVE -- a value exactly on a limit passes. A limit that is not stated places NO constraint on that side, so a one-sided limit is judged on the side it does state. Do the comparison yourself before answering.
3. THE CUSTOMER IS NOT NECESSARILY THE TIGHTER PARTY. Some customer limits are tighter than the internal ones, some are looser, some are identical, and some constrain a different number of sides. Read the numbers that are written; do not assume a direction.
4. A DETERMINATION THE CUSTOMER'S LIST DOES NOT LIMIT IS `not_specified`. Match a customer entry to a tested determination ONLY when it is the SAME measurement written in different words -- for example `Moisture (loss on drying, 105 C)` is `moisture content`, and `Total aerobic microbial count` is `total plate count`. A customer entry naming a DIFFERENT measurement is NOT a match even when it looks similar: `Particle size D90` is not `particle size D50`, `Tapped density` is not `bulk density`, and `Acid-insoluble ash` is not `ash content`. When in doubt, answer `not_specified` and null limits. Inventing a customer limit is worse than reporting that none exists.
5. `customer_parameter` MUST BE COPIED VERBATIM FROM THE CUSTOMER SPECIFICATION LIST when you match one, character for character, so the match can be checked. Use null when there is no match. Never write the internal name there unless the customer's list uses that exact wording.
6. The customer specification may also limit determinations this batch did not test. Ignore those entirely -- return one row per line of the Test Results table and no others, in the same order.
7. Report every limit and every result as a BARE NUMBER with the unit left out of it. A limit stated as `not specified` is null, not a number you supply.
8. `disposition` is read from the Disposition Record and from nothing else. Do not infer it from the verdicts. Use the exact allowed value.
9. Return every field named in the schema on every row, even when the answer is null.

---

Answer once for the batch:
- batch_id (string) -- the batch identifier from the Batch Record, verbatim
- consignee (string) -- the consignee CODE from the Batch Record (for example CUST-NORTHFELL), not the trading name
- disposition (enum) one of: released_to_consignee, diverted_other_customer, downgraded, held_pending_qa, rejected, reworked -- what the Disposition Record says actually happened to this batch. released_to_consignee ONLY when the batch was shipped to the consignee named in the Batch Record. A record that names that consignee while saying the batch went somewhere else, was regraded, or was held is NOT released_to_consignee.

Answer once for EVERY line of the Test Results table, in the same order:
- parameter (string) -- the determination as the Test Results table names it, verbatim
- unit (string) -- the unit the result is reported in, verbatim
- result (number) -- the numeric laboratory result, without its unit
- internal_lower (number) -- the INTERNAL specification's lower limit as a bare number, or null when it states `not specified` on that side
- internal_upper (number) -- the INTERNAL specification's upper limit as a bare number, or null when it states `not specified` on that side
- internal_verdict (enum) one of: pass, fail -- the result against the INTERNAL limits only. Arithmetic, both limits inclusive; a limit that is not specified places no constraint on that side
- customer_parameter (string) -- the wording the Customer Specification uses for THIS SAME determination, copied verbatim from that list -- or null when that customer's list does not limit this determination at all
- customer_lower (number) -- the CUSTOMER specification's lower limit as a bare number, or null when they state no lower limit or do not limit this determination
- customer_upper (number) -- the CUSTOMER specification's upper limit as a bare number, or null when they state no upper limit or do not limit this determination
- customer_verdict (enum) one of: pass, fail, not_specified -- the same result against the CUSTOMER limits only, decided independently of the internal verdict. not_specified when that customer's list does not limit this determination

Return a JSON object with exactly these keys: batch_id, consignee, disposition, rows
`rows` is a list, one object per Test Results line, each with exactly these keys: parameter, unit, result, internal_lower, internal_upper, internal_verdict, customer_parameter, customer_lower, customer_upper, customer_verdict
Use null for anything the record does not state.

BATCH QUALITY RECORD
--------------------
Batch Record
------------
Record: BQR-0017
Batch: BQ-2026-2155
Product: Kestrelin Xanthan Gum
Product code: PRD-4442
Manufactured on: 2026-03-12
Consignee: CUST-HOLLIN (Hollin Bakery Group)
Internal specification: INT-SPEC-4442 rev 4
Customer specification on file: CS-HOLLIN-4442 rev 4

Internal Specification
----------------------
Reference: INT-SPEC-4442 rev 4. Applies to every batch of this product regardless of consignee.
Lower and upper release limits. A limit shown as `not specified` places no constraint on that side.

  assay purity           %          lower 98.5 %         upper not specified
  particle size D50      microns    lower 45.0 microns   upper 75.0 microns
  total plate count      CFU/g      lower not specified  upper 1000 CFU/g
  ash content            %          lower not specified  upper 0.35 %

Customer Specification
----------------------
Reference: CS-HOLLIN-4442 rev 4, held on file for consignee CUST-HOLLIN (Hollin Bakery Group).
This customer limits ONLY the determinations listed below, in their own wording.
Any determination not listed here is not specified by this customer.

  assay purity: NLT 98.8 %
  ash content: not more than 0.3 %
  total plate count: not more than 800 CFU/g
  Moisture (loss on drying, 105 C): NMT 0.45 %
  Particle size D90: max 60.0 microns

Test Results
------------
Analysed by the works laboratory. One determination per line.

  assay purity           %          100.25   (analysed 2026-03-12)
  particle size D50      microns    73.1   (analysed 2026-03-13)
  total plate count      CFU/g      995   (analysed 2026-03-12)
  ash content            %          0.17   (analysed 2026-03-12)

Disposition Record
------------------
Batch released by quality assurance on 2026-03-17 and allocated to CUST-HOLLIN. Certificate of analysis issued with the shipment.
PresenterOpens the private repo. Visible to admins only.
Step 06 of 14Evals
Written for: the skeptic · The harness output, with as_of / model version / dataset version / verified_by.
In brief
Catch specification gaps before a batch ships — 216 batch quality records drawn from 44 real batch quality records. One model answered, and every answer was then graded Four different ways — because the grade is a measurement too, and most of what went wrong on this kit went wrong in the ruler rather than the model.
216batch quality records
44source documents
1model tier
4grading methods
MeasurementsWhat was measured
COUNTED38 / 38gap recall — gap rowsDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED2288 / 2292field accuracy — cellsDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED215 / 216customer coverage accuracy — determination rowsDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED7 / 7release interlock recall — batchesDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
NOT YET KNOWN—A person confirmed the gold is rightThe grader is == and needs no confirming. The gold does: it is machine-derived from the registry's structured modules, and every rate on this page rests on that derivation being faithful to what the prose actually says. Nobody has read a document against its gold record by hand.
Two words carry this page: Counted is deterministic and nobody's opinion and Not yet known is printed blank rather than filled with something plausible. There is no Judged row here and that is the point: nothing on this page is a model's opinion about another model. The row most worth having is currently the empty one.
How the method was validated
The scorer (evals/judge.py) is pure code, exact match with light normalisation — there is no judgement to validate, only comparison. What WAS validated: no verdict in gold is a typed label. Both verdicts, the gap classification and the release interlock are src/compare.py re-run over the numbers the document itself states, and evals/check_labels.py re-derives every one of them before any run is allowed to spend — failing if a single label disagrees with its own numbers, if a claimed customer wording is not readable off the Customer Specification section, or if any class would be degenerate. tools/build_corpus.py's own _verify() pass separately confirms every gold value is stated verbatim in the document it labels and every date is a real calendar date.
Grading costWhat it costs
Every dollar on these pages is a MEASURED token count multiplied by a named vendor's PUBLISHED rate — a projection onto a rate card, not a bill anyone paid.
Priced at
Per 1M in / out
One batch quality record
1,000 batch quality records
Share that is the prompt
Gemini 3 Flash the cheapest model Google publishes a rate for, and the card every kit in this series projects onto so the rows compare across use cases
$0.50 / $3.00
$0.007645
$7.65
13%
Same work, 1× the bill
The same batch quality records, the same tokens — only the rate card changed. And on that card about 13% of what you pay is the prompt this pipeline sends, not the answer it writes.
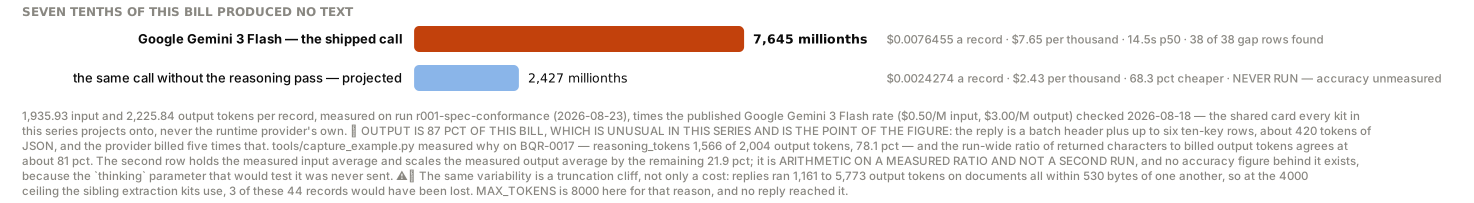
the provider's reasoning pass. It is about 81 pct of the output bill and the output bill is about 87 pct of the total, so it is roughly 71 pct of what this kit costs — and it is the one lever nobody has pulled. src/adapters/__init__.py accepts thinking and this kit's harness never sends one. Whether disabling it changes any published accuracy figure is UNMEASURED and is the obvious next run.
Rates checked 2026-08-18. The provider that actually ran r001-spec-conformance publishes no rate card this repo commits, so nothing here is what was actually paid. Nor does any card here model prompt caching, which the provider reported on the measured example (1792 of 1905 input tokens a cache hit) — the projection is a list price, and a list price is not what cached anything.
The gradersFour ways to grade
Grader
Cost / 1k
Data leaves
Same answer twice
Result
Row and batch field exact match Does every value the run returned match gold, after trimming whitespace and punctuation and treating numbers within half a thousandth as equal? Ten fields on each determination row plus three on the batch — including a correctly-returned null where the consignee does not limit a determination, which is a HIT and not an abstention.
$0.00
no
yes
the fast tier 99.8%
Customer coverage matrix For each tested determination, does the consignee's specification limit it AT ALL? Positive class is “limited”. A FALSE POSITIVE here is an INVENTED limit — the near-miss trap — and a FALSE NEGATIVE is a missed alias, which silently deletes any gap that row carried.
$0.00
no
yes
the fast tier 99.5%
The gap matrix Does this determination PASS the plant's internal specification and FAIL the consignee's? Positive class is the gap. It is DERIVED by src/compare.py::classify() from the two verdicts the run reported — the model is never asked whether a row is a gap — so a run cannot score here without holding both verdicts at once.
$0.00
no
yes
the fast tier 100.0%
Disposition classification Which of six things the disposition record says actually happened to the batch — released to the named consignee, diverted to another, downgraded, held, rejected or reworked. It is the second half of the eval intent (“and how it was dispositioned”) and it is what the release interlock is computed from.
$0.00
no
yes
the fast tier 100.0%
Every row opens its own page: how the test was run, the input on one real row, the prompt or formula with every iteration of it, and the analysis.
Why this set cannot separate them
Yes, sharply, and between the model and the two free floors rather than between model tiers — only one tier was run. On the gap matrix the model found 38 of 38, the exact-match floor 19 of 38, and the single-threshold floor 0 of 38. The separating variable is named and measurable: 81 of the 136 customer-limited rows are written in the customer's OWN wording, and the exact-match floor loses every one of them. On the two things that are NOT about the second specification — the structured fields a fixed layout makes regex work, and the disposition — the floors are level or close, and the disposition is a dead heat at 44 of 44 three ways. That is the honest shape of this result: the model bought the alias set and nothing else.
Choosing oneWhich one to use
The comparison is only useful if it ends in a choice. The answer is conditional — and it is not the grader with the best agreement score.
If your situation is
Use
Because
And avoid
Finding the batches that cleared your own release specification and would have failed the customer's
the fast tier — it found 38 of 38 gap rows with precision 1.00
The free exact-match floor finds 19 of 38 at the same precision and the free single-threshold floor finds none at all. The 19-row difference is exactly the set whose customer entry is written in the customer's own words.
the single-threshold floor for this question specifically — it cannot produce a gap row at all, and its zero is a property of having one verdict rather than a measurement of anything.
Classifying what was done with a batch from its disposition record
either free floor — they tie with the model at 44 of 44
The disposition vocabulary in this corpus is two or three wordings a class, which is regex work. Nothing measured here says a model helps.
reading this row as evidence about a REAL disposition record, which is one person's prose and is not what was tested.
Running this where the consignee's specification lives in a contract register rather than inside the record
nothing yet — this kit does not do it
Every figure on this page assumes both specifications are readable in the same document. The register lookup, and what to do when the register and the record disagree, is work this kit does not contain.
assuming the gap recall carries over. It is measured against a specification the model could read; a wrong specification fetched from elsewhere produces a confident verdict about the wrong contract.
This pipeline was also attacked, which is a different question from whether its answers are right: see Threat model for the injection experiment, its two gates and what it does not prove.
Failure causesHow it fails
Cause
What it means
Rows
A real example
dropped-alias
A customer entry written in the customer's own words, reported as no limit at all
1
BQR-0010 / bulk density: the Customer Specification lists “Loose bulk density: NLT 0.57 g/mL, NMT 0.73 g/mL” and the run returned customer_parameter null and customer_verdict not_specified. The result (0.763 g/mL) fails both specifications, so this row's cell…
exact-match-floor-alias-blindness
The free exact-match floor's own failure mode, measured on the same corpus
81
evals/baseline.py --floor exact joins a customer entry to a tested determination by exact name only. It is right about every entry the consignee happened to write in the plant's own words and reports “no limit” for every alias — 81 of 136 rows, which costs it…
single-threshold-phantom-coverage
The incumbent's own failure mode: a customer limit asserted on every row, including the ones the customer does not limit
80
evals/baseline.py --floor single has one specification and therefore one verdict, so it answers the customer question with the internal answer on all 216 rows — including the 80 the consignee does not limit at all. That is a claim about a contract on every…
unbilled-reasoning-pass
Output tokens that produced no text, on a kit whose bill is mostly output
5773
Not a wrong answer -- a cost and a truncation risk. The run billed 97937 output tokens for about 18533 tokens of returned JSON: 81 pct of the output bill produced no text the kit ever saw. tools/capture_example.py measured the cause directly on BQR-0017 --…
What we could NOT verify
Whether the gap matrix would still be clean on a larger or harder set. 38 gap rows on one seed is a small positive class, and the near misses are drawn from a fixed list of nine ordinary confusable determinations — a genuinely AMBIGUOUS customer entry, where two competent analysts would disagree, is not present anywhere in this corpus.
Whether a second model tier would separate. Only one tier was run, so every tier comparison other kits in this series publish is simply absent here.
Whether the three pure-code checks catch anything on a model that DOES make gap errors. They fired 0 inconsistencies and 0 unlocatable claims on this run because the run made no error they could catch, and all 7 interlock firings were true positives. The only firing evidence in this kit comes from the free floors — where the single-threshold floor's 139 unlocatable claims caught 16 of its 38 gap errors and MISSED the other 22, because a floor that copies the internal verdict is perfectly self-consistent while being wrong.
Whether the unlocatable_claim check can tell a WRONG match from a right one. By construction it cannot: it asks only whether the named wording appears in the Customer Specification section, and a near-miss entry is in that section. A run that matched “Particle size D90” to particle size D50 would locate cleanly and the check would stay quiet.
Whether a unit mismatch between a result and the limit it is judged against would be handled. Every row here states both in the same unit by construction and the kit does no conversion.
Whether disabling the provider's reasoning pass changes any published figure. src/adapters/__init__.py carries the thinking field and this kit's harness never sent one, so the 81 pct of the output bill that produced no text is measured and untested as a lever.
How the run performs where the consignee's specification is NOT in the record — the real case. Nothing here fetches a specification from a contract register, and no figure on this page covers that step.
PresenterOpens the private repo. Visible to admins only.
Step 07 of 14Unit cost
Written for: whoever signs off on the bill · Measured over the eval run, per model. Never quoted from a vendor page.
In brief
Tier
Input tokens
Output tokens
p50 latency
Gemini 3 Flash
the fast tier
1,935.93
2,225.84
14,485 ms
$0.007645
The token counts are measured on a real run and belong to this pipeline — which sections are selected, the field schema, the prompt — so they hold wherever you run it. The dollars are those counts multiplied by each vendor's published rate, checked 2026-08-18. Nobody paid these particular bills; they are what the same work would cost you on a card you can sign up to today.
Identical work in both rows — the same query, the same tokens. Only the price list changed. Which is why the token count is the measurement and the dollar is arithmetic you can redo on your own card.
Answering vs gradingAnswering and grading are two separate bills
Both free floors (evals/baseline.py) and the scorer (evals/judge.py) are pure code and cost $0.00 to run against any result set. The figure above is run r001-spec-conformance's own measured token counts (44 records) priced at Google Gemini 3 Flash's published rate — the same basis cost_per_query_usd uses, not a second, larger spend. It does not include the 5 additional calls this kit spent on measurement rather than on the eval: 3 at max_tokens=1 for the prompt split, 1 for the example capture, 1 for the live screenshot.
Cost driversWhat actually moves the bill
OUTPUT, not input, and it is not close: 0.9 of every projected dollar is output tokens on the card this page prices. About 81 pct of those output tokens produced no text this kit ever saw — measured directly on BQR-0017 as reasoning_tokens 1566 of 2004 (78 pct). Nothing was asked for it: src/adapters/__init__.py sends no thinking parameter.
The reply length scales with the number of determinations tested, not with the document: this corpus's records are all within 530 bytes of one another and their replies ranged 1161 to 5773 output tokens, a 5.0x spread.
The fixed system prompt and record schema are 1381 of 1905 input tokens (72 pct) on the measured example — the floor every call pays before a single number is read. The provider reported 1792 of those 1905 input tokens as a cache hit on that call; NOTHING on this page prices that, because the published projection is a list price and the list price is not what cached anything.
Your volumeWhat it costs at your volume
Linear in records: each call is independent and self-contained, with no shared context and no index to amortise. This run's 44 records project to $0.3364 on Gemini 3 Flash's rate, so ten times the set is about $3.36 on the same rate and the same prompt — arithmetic on the measured per-call figures, not a second run. ⚠︎ That linearity assumes the reasoning pass stays proportional, which is the one thing this run showed varying most (1161 to 5773 output tokens on documents of near-identical length).
Where pricing changes shape
MAX_TOKENS. Not a repricing — a loss. The ceiling is 8000 here and the longest reply billed 5773; at the 4000 the sibling extraction kits use, 3 of these 44 documents (BQR-0007, BQR-0010, BQR-0031) would have been truncated and produced no rows at all. A ceiling costs nothing until it is crossed, and then it costs the document.
Your return, with your numbers
Volume
What it replaces
Time saved per item
We publish the inputs, not a return: a return depends on your labour cost and your volume. The ROI dashboard takes it from here, and AI Costing explains the math.
Other modelsOn other models
This is arithmetic, not a run. No model below was executed against the labelled set, and no accuracy is claimed for any of them. What transfers is the input volume: retrieval is model-independent, so every model would receive the same passages.
85,181input tokens · this run
97,937output tokens
—not priced — no committed card for the provider that ran it
The exact work behind every number on these pages: 44 batch quality records compared against two specifications each, 216 determination rows, scored by pure code against a gold set whose verdicts are derived rather than typed. This run answered all 44 records with no truncation and no failures -- the row this table prices, the same one Cost.cost_by_model[0] uses.
Model
Provider
One eval pass
This whole run
Per 1,000 queries
Rates as of
gpt-5-6-luna
OpenAI
$0.135
$0.135
$3.06
2026-09-12
gemini-3-flash
Google
$0.336
$0.336
$7.65
2026-09-18
gemini-3-8-flash
Google
$0.431
$0.431
$9.80
2026-09-18
llama-5
Meta
$0.523
$0.523
$11.88
2026-09-18
claude-haiku-4-5
Anthropic
$0.575
$0.575
$13.07
2026-09-12
grok-4-5
xAI
$0.758
$0.758
$17.23
2026-09-18
grok-4-6
xAI
$0.758
$0.758
$17.23
2026-09-18
claude-sonnet-5
Anthropic
$1.150
$1.150
$26.13
2026-09-12
gemini-3-1-pro
Google
$1.346
$1.346
$30.58
2026-09-18
gpt-5-6-terra
OpenAI
$1.346
$1.346
$30.58
2026-09-12
gpt-5-6-sol
OpenAI
$2.299
$2.299
$52.26
2026-09-12
claude-opus-4-8
Anthropic
$2.874
$2.874
$65.33
2026-09-12
claude-opus-5
Anthropic
$2.874
$2.874
$65.33
2026-09-12
claude-fable-5
Anthropic
$5.749
$5.749
$130.65
2026-09-18
claude-fable-5-1
Anthropic
$5.749
$5.749
$130.65
2026-09-18
gpt-6-astra
OpenAI
$5.749
$5.749
$130.65
2026-09-17
Read this against the numbers above
Every row below prices ONE run (r001-spec-conformance) on ONE tier. No second tier was run for this kit, so unlike several sibling kits there is no tier comparison here to caveat -- and no evidence that a cheaper or dearer tier would score the same.
About 81 pct of the output tokens these rows price produced NO TEXT -- they are the provider's own reasoning pass, measured at reasoning_tokens 1566 of 2004 on BQR-0017. Since output is roughly 87 pct of the projected bill on every card below, every figure in this table is mostly pricing that pass. Whether it can be disabled without moving an accuracy figure is untested.
No card here models prompt caching. The provider reported 1792 of 1905 input tokens as a cache hit on the measured example, which would matter on a rate card that priced it; these are list prices.
PresenterOpens the private repo. Visible to admins only.
The codeEvery file, and what it is for
Six modules, no framework, and almost no dependencies. The pipeline is stdlib Python, because a kit is meant to be read and changed by someone who cloned it ten minutes ago — every dependency is a thing they have to understand before they can touch the part they came for.
Five of these are swap seams: the points you edit to make the kit yours. Each is marked, and each block below is the module’s real shape, read out of the file rather than written here.
The files on this page are not in the public GitHub catalog.
src/segment.pysegment
cut the record into addressable sections, pure code — and hand the Customer Specification section out on its own, which is what lets a coverage claim be checked against the document rather than taken on trust
src/segment.py
# Cut a batch quality record into addressable sections. Pure code -- no model, no network.

def sections(text):
def section_text(secs, name):
def locate(text, value):
def span_label(secs, start):
src/select.pyselect — a swap seam
decide which sections are sent, pure code — five of eight; the synthetic-record banner, the shift's line notes and the contact sheet state no limit, no result and no disposition
You change it to: which sections of your own record layout reach the model; an unmatched set falls back to the whole document
src/select.py
# Pick which sections go to the model. Pure code -- the last deterministic step before the call.

SEND = ["Batch Record", "Internal Specification", "Customer Specification",
DROP = ["Synthetic Record", "Line Notes", "Contact Sheet"]
SECTION_OF = {
def chosen(secs):
def dropped(secs):
src/compare.pycompare — a swap seam
THE comparison, the gap classification and the release interlock, stated once and imported by the corpus generator, the prompt and the guardrail so the three cannot drift. Also the deliberately-unset marginal band
You change it to: the comparison itself — the boundary convention, or a tolerance band if your programme allows one. It is stated once and used by the corpus generator, the prompt and the guardrail, so changing it here changes all three together
src/compare.py
# THE TWO-SPEC COMPARISON, stated once and imported by everything that needs it.

PASS = "pass"
FAIL = "fail"
NOT_SPECIFIED = "not_specified"
VERDICTS = (PASS, FAIL, NOT_SPECIFIED)
MARGINAL_BAND = None
def _numeric(v):
def compare(result, lower, upper):
GAP = "gap"
REVERSE_GAP = "reverse_gap"
src/prompt.pyprompt
assemble one call per record, with both specifications, the boundary convention, and the three collapse rules stated in full — judge separately, do not assume a direction, do not match a determination that merely looks similar
src/prompt.py
# Assemble the prompt. ONE call per batch quality record, every parameter row in it.

SYSTEM = (
def field_line(f):
def schema_text(fields):
def build(doc_text, secs, fields):
def parse(raw, fields):
RULE_SENTENCE = (
src/extract.pyextract
the AI layer, one provider one key — plus the three pure-code checks downstream: recompute both verdicts from the reply's own numbers, locate every coverage claim in the customer specification, and raise the interlock
src/extract.py
# Read one batch quality record: segment, select, prompt, ONE model call, then three pure-code

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
FIELDS = os.path.join(HERE, "data", "fields.json")
CORPUS = os.path.join(HERE, "data", "corpus")
MAX_TOKENS = 8000
CUSTOMER_SECTION = "Customer Specification"
def load_fields():
def load_doc(rec_id):
def documents():
def _num(v):
evals/judge.pyjudge
score four things separately — field cells, customer coverage, the gap matrix and the disposition — pure code, no model and no key
evals/judge.py
# Score a run. PURE CODE -- gold is exact and every answer is one value, so `==` (with light

BATCH_FIELDS = ("batch_id", "consignee", "disposition")
ROW_FIELDS = ("parameter", "unit", "result", "internal_lower", "internal_upper",
def norm(v):
def _numlike(v):
def equal(field, got, want):
def _align(got_rows, gold_rows):
def score(records, golds):
def _matrix(rows, positive_label):
def score_flags(records, golds, docs_text=None):
Start hereThe shortest path into it
src/segment.pycut the record into addressable sections, pure code — and hand the Customer Specification section out on its own, which is what lets a coverage claim be checked against the document rather than taken on trust
src/select.pydecide which sections are sent, pure code — five of eight; the synthetic-record banner, the shift's line notes and the contact sheet state no limit, no result and no disposition A swap seam.
src/compare.pyTHE comparison, the gap classification and the release interlock, stated once and imported by the corpus generator, the prompt and the guardrail so the three cannot drift. Also the deliberately-unset marginal band A swap seam.
src/prompt.pyassemble one call per record, with both specifications, the boundary convention, and the three collapse rules stated in full — judge separately, do not assume a direction, do not match a determination that merely looks similar
src/extract.pythe AI layer, one provider one key — plus the three pure-code checks downstream: recompute both verdicts from the reply's own numbers, locate every coverage claim in the customer specification, and raise the interlock
evals/judge.pyscore four things separately — field cells, customer coverage, the gap matrix and the disposition — pure code, no model and no key
Every entry above is a file in this kit, listed in the order the pipeline runs it.
PresenterOpens the private repo. Visible to admins only.
ScenariosWhat it costs at your volume
Everything below is computed from one measured base: 1935 input and 2225 output tokens per query, all of it fixed — this kit sends the document's own selected sections, so there is no retrieval depth to turn. Change the volume and the bill scales linearly, because nothing here batches.
Grading really is free here, and that is a property of the ruler rather than a discount
This kit is graded by pure code — the grader makes no model call, needs no key and sends nothing anywhere, so the grading line above is zero at every sampling rate and the leak count stays at nought. What that buys is a ruler you can run on every row, every time, for nothing. What it costs is reach: a code grader can only check what is mechanically checkable.
OperationsFour shapes of workload
The same arithmetic, at volumes worth naming. These are illustrations of scale, not measurements of anyone’s deployment.
Shape
Querys/day
Per day
Per month
Per year
Model follows the controls above.
What this ignoresWhere a real bill diverges
Read before quoting any of it
Output length is assumed constant.A terser or more verbose model moves it, and output is priced above input everywhere.
No volume, committed-use, batch or cache discount is modelled.Each moves real enterprise pricing and none are on a public rate card.
Longer documents cost more and nothing here caps them.This kit selects the document’s own sections in pure Python, so there is no vector store to price — but a corpus of longer records raises the input tokens per query directly, and that is the very number every figure above multiplies.
Grading adds nothing to this bill, and would if you changed the ruler.A code grader is free and local; swapping in an LLM judge would cost more per row than the extraction itself and send every row to a vendor. The instrument is a cost decision, not a footnote.
Rates age.Every one carries the date it was read on the cost page.
PresenterOpens the private repo. Visible to admins only.
In one lineWhat this kit exposes
This run's records are entirely synthetic (tools/build_corpus.py) -- no untrusted party wrote any of the text. In a real deployment two of the five sections this kit sends are authored OUTSIDE the plant: the customer specification is the consignee's own document, and in an incoming-goods review the whole record may arrive from a supplier. The disposition record is free text written by whoever worked the batch. All three reach the model verbatim with no verification step. No attack has been tried against this kit; see redteam.why.
Read from the shared .env or the real environment only, never written into the repo, never requested from a reader on any surface. src/app.py's /api/compare handler strips api_key and base_url out of any exception message before it reaches the browser, so a misconfigured key cannot leak into a UI error.
The experimentWe did not attack it — and three of four boundaries hold
An indirect prompt injection needs a field an outside party controls that reaches the prompt. This kit has three of them in a real deployment -- the consignee's specification, the disposition record, and the whole record on an incoming-goods review -- and in THIS corpus all three are generated by tools/build_corpus.py, so there is no live untrusted text in the run this report measures. The four gates below are boundaries confirmed by reading the code, not payloads run through it. Confirmed by reading the code, not by a run, on 2026-08-23 -- no attack run was fired; see redteam.why.
Boundary checked
What could go wrong
What the code guarantees
Does a comparison ever release, hold, divert, downgrade, reject or rework a batch?
A verdict this consequential could plausibly post a release, a hold or a rejection, or be configured to.
No code path does and no setting adds one. src/extract.py::extract() and src/app.py's /api/compare both return a record only; neither writes to any file or store -- confirmed by reading every call site. The cap is batch-release and the interlock is a returned field.
Could a misconfigured provider key leak into a UI-visible error?
An exception raised from a bad key or base URL could echo the secret back to the browser.
src/app.py's /api/compare handler replaces both values in any exception message before returning it -- confirmed by reading the handler (see key_handling).
Is the comparison something a prompt or a reply can move?
Text inside the customer specification or the disposition record could plausibly shift the boundary convention or talk the arithmetic into a different answer.
No. src/compare.py::compare() is pure code with no configuration and no model in it, and it runs AFTER the call over the reply's own values. Nothing in the reply text is consulted except the three numbers it names.
Could a crafted customer-specification entry manufacture or suppress a gap?
An entry written to be matched -- a near miss phrased to read like an alias -- would invent a limit and a gap with it; an alias phrased to read like a near miss would delete one. Both would pass the unlocatable_claim check, because the wording IS in the document.
Unmeasured -- no attack has been tried. This is the known blind spot of the coverage check (see guardrails.is_not): it verifies that a claimed wording EXISTS, never that matching it was right. The corpus's 29 near-miss entries test ordinary confusable vocabulary, not an adversary, and the run refused all of them (coverage precision 1.00). See could_not_verify.
The first three boundaries hold, confirmed by reading the code, not by an attack trial. The fourth is the one this run has not tested, and it is the same blind spot the coverage check names about itself: a wording that is present in the document looks identical to a correct match.
The result0 attack trials, and three of four boundaries checked here hold in code: no write path exists, the comparison is pure code the model cannot move, and a misconfigured key cannot leak into a UI error. The fourth -- whether a crafted customer entry could manufacture or suppress a gap -- is unmeasured, and is the coverage check's own known blind spot.
3externally-authored surfaces a live deployment would carry -- the consignee's own specification, the disposition record, and in an incoming-goods review the whole batch record. All synthetic on this run
0 of 0attack trials run
n/agap-flip resistance -- not measured
This run's corpus is entirely generated -- no section's text was authored by an outside party. A real customer specification is written by the customer, and a supplier-issued record is written entirely outside your control: exactly the kind of externally-supplied text this kit's architecture reads verbatim and trusts. Whether an entry crafted to be matched (or to be missed) could manufacture or suppress a gap is unmeasured for this kit.
Read this twice
The release interlock inherits the reply completely, and the coverage check verifies existence rather than correctness. A gap the model never found cannot raise the interlock, and a customer wording that IS in the document looks identical to a correct match. This run dropped exactly one alias -- BQR-0010 / bulk density -- and nothing flagged it, because a reply that claims no customer limit makes no claim to be checked. That row failed both specifications anyway, so it cost nothing; the identical miss on a row that had passed internally is a gap that disappears in silence. The fix is named in guardrails.add_first and it is free: the customer specification list is enumerable, so a check that flags any LISTED entry the reply matched to nothing would have caught this one. It is not built yet, and this page says so rather than reporting 99.83 pct and moving on.
HonestyWhat this does not prove
Whether a customer-specification entry crafted to be matched could manufacture a gap. The 29 near misses here are ordinary confusable determinations and the run refused every one (precision 1.00, 0 invented limits), but none of them was written to deceive.
Whether an alias phrased to read like a different determination could delete a gap. The run already dropped ONE ordinary alias (BQR-0010 / bulk density) with nothing flagged, so the failure mode exists without an attacker; how much easier it is to induce deliberately is unmeasured.
Whether a prompt-injection attempt inside the disposition record could move the disposition class, and with it the release interlock. Untested.
Whether the live app's own /api/compare behaves identically to the registered run under an adversarial record -- both use the same src/extract.py::extract(), but neither has been tested against one.
PresenterOpens the private repo. Visible to admins only.
In one lineThe guardrail is enforced in code
Not a prompt instruction the model can ignore — a comparison applied after the reply is parsed, before anything downstream sees it.
the guardrail, verbatim
THREE checks, all pure code, all computed from the reply and the document alone. (1) verdict_inconsistent: the comparison re-run over the model's OWN reported numbers lands on a different verdict from the model's own. (2) unlocatable_claim: the model says the consignee limits this determination and names a wording that does not appear in the Customer Specification section. (3) release_interlock: the batch carries a gap row AND its disposition says it was released to that same consignee. None of the three needs gold, a second call or a labelled set, so all three compute identically on a record nobody has ever scored.
src/extract.py::check_row() and ::compute(), which call src/compare.py::compare(), ::classify() and ::release_interlock() -- the same functions tools/build_corpus.py used to write gold and the same rule src/prompt.py asks the model to apply, stated once so the three cannot drift. Run after the model call, over the reply's own values; nothing in the reply text can talk them out of firing. What they CANNOT do is check whether the numbers or the match were RIGHT -- a different dependency, named in is_not and could_not_verify.
EvidenceDoes it hold?
What
Measured
The interlock fires exactly where a gap batch was released to that consignee
7 of 7 batches on run r001-spec-conformance, every one a true positive and 0 false alarms across the other 37 batches.
A coverage claim that is not in the document is caught without gold
Run over the free single-threshold floor's own output (results/eval-b000-single.json), unlocatable_claim fired 139 times -- and caught 16 of that floor's 38 gap errors with no gold consulted. On run r001-spec-conformance it fired 0 times: all 135 coverage claims located verbatim in the Customer Specification section.
The comparison is not something a prompt or a reply can move
src/compare.py::compare() is pure code with no configuration and no model in it -- confirmed by reading it; nothing in the reply text is consulted except the three values it names.
An unanswerable check is not a pass
check_row() returns None -- never False -- when a verdict is missing or a result is not a number, and release_interlock() returns None on an unrecognised disposition. Confirmed by reading both, and exercised by the stub run (t000-stub), where all 44 records returned no rows and were recorded as failures rather than as clean documents.
No code path releases, holds, diverts, downgrades, rejects or reworks a batch
src/extract.py::extract() and src/app.py's /api/compare both return a record only; neither writes to any file or store -- confirmed by reading every call site. The cap is batch-release and there is no setting that adds a write.
The limitWhat a guardrail is not
THE INTERLOCK INHERITS THE REPLY COMPLETELY. A gap the model never found cannot raise it -- so a dropped alias suppresses the flag as silently as it suppresses the gap. That is stated in the docstring of the function that computes it, and it is the reason the coverage matrix is graded separately rather than folded into the gap figure.
unlocatable_claim CANNOT TELL A WRONG MATCH FROM A RIGHT ONE. It asks only whether the named wording appears in the Customer Specification section -- and a near-miss entry IS in that section. A run that matched "Particle size D90" to particle size D50 would locate cleanly and this check would stay quiet.
verdict_inconsistent does not check whether the NUMBERS were read correctly. A reply that misreads a limit and then judges that misreading correctly is self-consistent and stays quiet. Measured proof of the shape: the free single-threshold floor's numbers are always right and its customer verdicts are always the internal one, so it is perfectly self-consistent while getting 38 gap rows wrong -- verdict_inconsistent fired 0 times on it.
None of the three has been attacked. Whether a crafted customer-specification entry or a prompt-injection attempt inside the disposition record could produce a wrong AND consistent answer is unmeasured; see Security.could_not_verify.
WatchedWhat is watched, and why that one
3runs recorded
0 / 0deterministic metrics exact
+0.0%largest move — latency
0band breaches
—model half · needs provider URL
The kit measures 14 watched figures plus 8 comparability guards and 5 reference constants — three duties, not one list. 0 of the watched are grader rates, each on its own grader page; this board watches the ones that decide when to look again. Each square is one watched figure; filled means the latest run measured it.
6 measured by the latest run8 need the model half
Metric
Owner
Role
Why this one
row-and-batch-field-exact-match
Row and batch field exact match
alarm
customer_parameter specifically — it is the field the whole kit turns on, and the only field this run got wrong; the two customer limit fields on rows the consignee does NOT limit, where a correctly-returned null is the answer and an invented bound is a manufactured limit; internal_verdict and customer_verdict together rather than separately: a run can score well on each and still be collapsing one into the other — alarm on Any drop in field accuracy below 99.83 pct — this run's figure is the baseline, and a regression means the prompt, the corpus or the provider changed.
customer-coverage-matrix
Customer coverage matrix
alarm
false_positive above all — an invented customer limit is a claim about a contract, and it can manufacture a gap that does not exist; false_negative on ALIAS rows specifically, since that is where the free exact-match floor loses 81 of 136 and where the model's whole advantage lives; the claim_located_rate diagnostic beside it: of every coverage claim made, how many name a wording actually present in the document — alarm on Any false positive. On this run there were none in 135 claims, and the pure-code unlocatable_claim check independently located all 135 of them in the customer specification section.
gap-matrix
The gap matrix
alarm
false_negative — a batch that would have failed the customer and was not flagged is the error this whole kit exists to prevent; false_positive, which on this corpus can only come from matching a near-miss entry and inventing a limit; it manufactures a gap out of a determination the contract never covers; the split between gap rows whose customer entry is an alias and those written in the plant's own words — the free exact-match floor gets the second group and not the first — alarm on Any false negative. There were none in this run's 38 gold gap rows; the free exact-match floor missed 19 of them and the free single-threshold floor missed all 38.
disposition-classification
Disposition classification
alarm
released_to_consignee specifically, since it is the only class that can raise the release interlock; the two classes that NAME the consignee while not shipping to them (diverted_other_customer, downgraded) — those are what a keyword floor grepping for the consignee beside “released” gets wrong; per-class accuracy rather than the total, because the classes are unbalanced (diverted_other_customer=3, downgraded=3, held_pending_qa=7, rejected=9, released_to_consignee=12, reworked=10) — alarm on Any released_to_consignee called something else, or something else called released_to_consignee — both change whether the interlock can fire.
GuardsBefore any comparison
Preconditions, not alarms. If one moves, the runs were not measuring the same system and nothing else on this board may be differenced.
Guard
Value
If it moves
corpus.doc_count
44
different corpus — nothing is comparable
corpus.bytes
126,194
batch quality records edited — the count held, the bytes did not
split.count
352
the sections count moved — a different set was scored
split.size_p50
35
the median size of one section moved
split.size_p95
92
the 95th-percentile size of one section moved
dataset.rows
216
the test set changed — every rate has a new denominator
tokens.context_limit
1,000,000
different model family
index.build_seconds
0.005
no index is built here — a change is in corpus preparation, not an index rebuild
all shared guards held between the recorded runs (documents 44, extraction_cells 2292, failures 0, refusal_cells 0) — which is why the history below is allowed to mean anything.
The reference constants — the null-grader baseline, the adjudication matrix, the negative count — are the third duty. They are never re-measured per run: a baseline that moves with the thing it measures is not a baseline.
BandsThe alarm bands
Derived from evidence, never picked: exact-match where two runs reproduced a metric to the digit, wider than the measured same-input drift for latency, one row of the negative class for any rate — denominator printed beside it.
Group
Band
Denominator
Where the band comes from
Gap rows found
exact match at 100 pct recall and 100 pct precision
38 gap rows of 216 determination rows
one run (r001-spec-conformance) against a gold set whose gap rows are derived, not typed. The free exact-match floor finds 19 of 38 and the free single-threshold floor 0.
216 determination rows: 136 limited by the consignee, 80 not
one run; the single miss is a dropped alias on BQR-0010. 0 invented limits against 29 planted near-miss entries.
Release interlock
exact match at 100 pct recall, 100 pct precision
44 batches: 7 carry the interlock in gold
one run; 7 positives is a very small class and the band says so.
Field cells
exact match at 99.83 pct
2292 cells
one run; the 4 misses are all one determination row (BQR-0010 / bulk density).
Gold-free checks
0 verdict inconsistencies, 0 unlocatable claims of 135 made
216 determination rows
measured directly on run r001-spec-conformance and on both free floors -- the single-threshold floor fired unlocatable_claim 139 times, which is where all the firing evidence in this kit comes from.
Invented limits (hallucinations)
exact match at 0 on the run; 201 on the free single-threshold floor, 0 on the free exact-match floor
485 cells of 2292 where gold states NO value -- the three customer fields on each of the 80 determinations the consignee does not limit, plus the unstated side of every one-sided internal limit. Those are the only cells an invention can land in; a wrong value where gold has one is an error, not an invention, and is counted as such.
measured directly. ⚠︎ evals/judge.py reported this as a HARD-CODED 0 until this lap -- copied from a sibling extraction kit where every field is stated on every document, so "gold has no value here" never happens and a zero is trivially right. It is not trivially right on this kit, where 485 of 2292 cells are exactly that case and an invented value there asserts a contractual limit that does not exist. Re-derived and re-scored over run r001-spec-conformance's own committed records in-process (pure code, no calls), which reproduces that run exactly and returns 0 -- the figure the literal happened to carry. The free single-threshold floor, scored by the same judge, invents 201: it asserts a customer limit on every row including the 80 the consignee does not limit.
Latency
14485ms / 26815ms p50/p95
44 calls
measured directly on one run; the provider was under concurrent load from other kits on the same key, so these are not a clean single-tenant measurement.
Token totals
85181 input, 97937 output -- and about 81 pct of the output produced no text
44 calls
measured directly; the cause is measured too, on BQR-0017 -- reasoning_tokens 1566 of 2004.
HistoryRun history
3 recorded runs. A dash is a metric that run did not measure, and a dash is never differenced: not measured is a third state, neither a value nor a zero, and reading it as zero is how a board reports an improvement on a run that never looked.
Metric
b000-single 2026-08-23
b001-exact 2026-08-23
r001-spec-conformance 2026-08-23
extraction accuracy
0.7579
0.8844
0.9983
invented values
201
0
0
input tokens, whole run
0
0
85181
model latency p50 ms
0.00
0.00
14485.00
model latency p95 ms
0.00
0.00
26815.00
output tokens, whole run
0
0
97937
not a time series No two of these 3 runs measured the same system — they differ on provider, thinking, the model — so nothing here may be differenced and the Verdict column is left off. Read this block DOWN a column, as a comparison between those runs, not along a row as a history.
DeviationsWhat deviated
0 breaches across 3 runs
The day a band breaks, a row renders here carrying the metric, the two runs, the band it crossed and what changed between them — model, prompt, chunker or top_k, read off the run records’ guards. A deviation with no diff beside it is an alarm nobody can act on.
RippleThe ripple map
Which figures move together, so one alarm reads as a system. Every edge carries its basis: measured names the run that showed it; reasoning admits nothing has varied it yet.
Lever
What moves
Basis
Evidence
joining the customer's specification by exact name instead of reading it
gap recall collapses from 1.00 to 0.50 and coverage recall from 0.9926 to 0.4044, while every structured field and the whole disposition grade stay level -- and NONE of the three gold-free checks fires, because a floor that reports "no limit" makes no claim to be unlocatable and no verdict to be inconsistent
measured
results/eval-b001-exact.json: 19 of 38 gap rows, 5 of 7 interlocks, 55 of 136 coverage, 44 of 44 disposition, 0 unlocatable claims and 0 verdict inconsistencies.
answering the customer question with the internal answer (one specification)
gap recall goes to 0.00 and interlock recall to 0.00 while coverage RECALL goes to 1.00 -- the floor claims a customer limit on every row, so it never misses one and invents 80. Field accuracy falls to 75.79 pct because the customer limit columns are then wrong wherever the two specifications differ
measured
results/eval-b000-single.json: 0 of 38 gap rows, 0 of 7 interlocks, coverage precision 0.6296, and unlocatable_claim firing 139 times to catch 16 of its 38 gap errors with no gold.
MAX_TOKENS
nothing at 8000, and 3 documents at 4000 -- not a degraded answer but no answer at all, since a truncated reply carries no usable rows and is recorded as a failure
measured
run r001-spec-conformance's output_tokens_by_doc: 1161 to 5773 tokens, BQR-0007, BQR-0010, BQR-0031 at or above 4000, 0 documents at or above 8000 and 0 failures.
a customer limit that is LOOSER than the plant's own
the row becomes a reverse gap -- it failed internally and would have passed for that customer -- and no interlock is possible, because a batch failing its own internal specification is never recorded as released in this corpus
reasoning
src/compare.py::classify() returns reverse_gap for (fail, pass) -- confirmed by reading it; 25 of this corpus's 136 customer-limited rows are looser and 9 rows land in the reverse gap.
FiresWhat fires when a band breaks
Where evals stop sitting beside the guardrail and start feeding it. Where the answer is nothing automatic, the row says so — hiding it would undo “What a guardrail is not” above.
Band
What fires
Release interlock
7 of 44 batches
NextThe three you would add first
Re-read the customer specification list by pure code and compare its entries against the ones the model claimed -- flag any listed entry the model matched to nothingthe blind spot named first in is_not. The list is enumerable (evals/baseline.py already parses it, 55 entries across the corpus), so a rule that says "this entry was never accounted for" is available free and would have caught this run's one error.
Set MARGINAL_BAND, once an operator has answered what proximity counts as marginalsrc/compare.py ships margin() on every row against both specifications precisely so the band can be chosen from a real distribution. Until it is set the kit publishes pass/fail and nothing else, which is the honest state of an open question rather than a gap in the code.
Look the consignee's specification up in a contract register instead of reading it out of the recordthe real case. Every figure here assumes both specifications sit in one document; a production version needs the lookup and a story for what happens when the register and the record disagree. See Data.bring_your_own_boundary.
None of these is built here. They are named against the seam they sit on so they can be argued with.
CadenceWhen to re-run, and what it costs
Re-check on any change to src/compare.py (all three checks are built from it) or to rules 1-5 of SYSTEM in src/prompt.py. Re-run evals/run.py (paid) on any change to MAX_TOKENS or the provider/model -- and note that MAX_TOKENS is not cosmetic here: 3 of 44 documents billed over 4000 output tokens.
What this cannot tell you
Whether the checks fire cleanly on a model that DOES make gap errors. This run made none, so the only firing evidence in the kit comes from the free floors -- and the single-threshold floor is the easy case for unlocatable_claim (its numbers are right and its claims are wholesale) while being the impossible case for verdict_inconsistent (it is self-consistent by construction).
Whether a crafted customer entry could produce a wrong AND locatable match, which unlocatable_claim would not catch -- no red-team run exists for this kit.
Whether the specification limits in this corpus resemble any real approved specification. They do not, by design, and one invented library is applied to every product; see README/SOURCES.md.
PresenterOpens the private repo. Visible to admins only.
In one lineNo framework, deliberately
No framework and no dependencies beyond the standard library -- requirements.txt is empty, with a comment explaining that the emptiness is load-bearing. The whole decision is four small files: src/segment.py, src/select.py, src/compare.py and src/adapters/__init__.py.
The mappingSeam by seam, who owns what
Seam
File here
Framework equivalent
Note
the corpus
tools/build_corpus.py
none -- a seeded generator
44 batch quality records with two specifications each, generated from a fixed seed, never fetched. It IMPORTS src/compare.py to write gold rather than restating the rule -- the sibling kit coa-conformance duplicated its rule into its generator under a comment asking the two to be kept in step, and importing costs one line.
segmentation and selection
src/segment.py, src/select.py
text splitters / retrievers
a heading-based cut and a fixed list of five sections to send -- no embeddings, no index, no ranking. segment.section_text() also hands out the Customer Specification section ALONE, which is what makes the phantom-coverage check possible at all.
the comparison
src/compare.py
rules engines
seven functions and no configuration. A rules engine would put the boundary convention, the third state (not_specified) and the interlock into a DSL that three other files then have to agree with; here they import it.
prompt assembly
src/prompt.py
prompt templates
the 13-field schema is one declaration in data/fields.json and SYSTEM is a literal beside it, so the prompt can be published verbatim -- which a template assembled two calls away cannot be.
the model
src/adapters/__init__.py
chat model wrappers / vendor SDKs
raw HTTP over urllib for every provider, so a forker runs this on whichever key they hold. MAX_TOKENS=8000 is a plain constant, not a client-library setting -- and on this kit it is load-bearing rather than cosmetic.
evaluation
evals/judge.py
eval harnesses
four matrices and a handful of counters. The only non-obvious part is pairing reply rows to gold rows by NAME rather than position, which is a dict comprehension.
spend control
src/budget.py
none
an append-only ledger written BEFORE each call, shared by every kit under one .env so the cap is on the KEY rather than per kit.
The seams are the ones this kit already publishes, so the mapping cannot drift from the code.
GraphsWhere LangGraph changes the answer
Nothing here is a graph. The pipeline has one path per record -- segment, select, prompt, call, parse, recompute, classify -- with no branching and no state carried between records. A framework would add an orchestrator to a for-loop.
The other sideWhat a framework costs you
A different record schema (data/fields.json) or a different comparison rule needs its own gold set and its own evals/check_labels.py pass -- a framework's own schema layer would not remove that work, only relocate it.
SEND in src/select.py is a five-minute edit for a new record layout because it is a list of headings, not a configured retriever -- a framework's chunking abstraction would need its own re-tuning pass instead, with its own failure modes to learn.
Swapping providers is one function and one entry in PROVIDERS -- a framework's model abstraction would add a dependency and a version to track for the same one-line change this file already gives away free.
What we could NOT verify
Whether a framework's retrieval or agent abstraction would resolve anything this kit does not already handle was not tested. The one measured weakness is a dropped alias on a single row, which is a reading problem rather than an orchestration one -- see Business.not_good_enough.
Whether a structured-output or function-calling layer would have removed the reasoning pass that is 81 pct of this kit's output bill. It was not tried, and the thinking parameter that would test it directly was never sent.
PresenterOpens the private repo. Visible to admins only.
In one lineWhat one run of this kit actually cost, in time and tokens
Measured on r001-spec-conformance on the fast tier, 2026-08-23. This kit records telemetry measured per run — 4 of the 6 readings on this axis, 4 of them with a band the guardrail board can judge against.
The readingWhat the last run measured
Reading
Last run
Band
What fires
Model, median
14,485 ms
14485ms / 26815ms p50/p95
—
Model, p95
26,815 ms
14485ms / 26815ms p50/p95
—
Input tokens
85,181
85181 input, 97937 output -- and about 81 pct of the output produced no text
—
Output tokens
97,937
85181 input, 97937 output -- and about 81 pct of the output produced no text
—
No movement column. Not one of the 2 earlier runs on record is comparable with this one — a different model tier, or a changed guard — and differencing across that measures two systems rather than one. Said once here rather than as a dash on every row.
Retrieval not shown. No run of this kit has ever recorded a retrieval timing, because the pipeline has no such stage. Those readings are left out rather than dashed: a dash says “this run did not measure it”, which promises a later run could.
DriftMedian call, run over run
No drift chart. Only one run has recorded a call latency; the other 2 runs on record made no model call at all — a rules-only floor stores 0, which is an absence, not a zero-millisecond answer. One timed run is a reading, not a trend, and it is in the table above. A chart appears the day a second run times itself.
The other sideWhat this does not tell you
What we could NOT verify
No stage-by-stage span tree. These are whole-call timings; which part of the pipeline spent the time is not recorded by this kit's harness.
Latency is a run-level median and p95. The spread between the fastest and slowest single call is not stored, so the distribution cannot be drawn.
No earlier run is comparable to this one (a different model tier or a changed guard), so nothing on this page is a trend yet.
One machine, one network, one region. Latency includes the provider round trip from a single location and will not transfer to yours.
The first of those is the one worth doing something about, and it is a solved problem: instrumenting a pipeline so each step reports its own duration is a couple of lines. Observability / tracing has the code, and what the result looks like once it is running.
PresenterOpens the private repo. Visible to admins only.
In one lineWhat you provision, honestly
Everything measured on this page says where it was measured; everything not measured says that — the same contract as the other thirteen pages. Where a retrieval index would be on other kits, this one has: no index — each document goes whole into one call.
The machineWhat this needs
Dependencies
nothing beyond the standard library — requirements.txt names no package
Configuration
7 environment variables — the full knob table is at the bottom of this page
Last verified run
2026-08-23, across 3 committed records
Enumerated from the kit’s own source by build/facts/envscan.py, committed, and drift-checked — never typed into this page.
Your dataWhere everything sits
Artifact
Where
Leaves your machine?
batch quality records
data/corpus/*.txt — 44 files, generated once from a fixed seed (SEED = 20260823) by tools/build_corpus.py
read whole by src/segment.py; five sections of each reach the model, three do not (src/select.py). Never modified after generation.
gold labels
data/gold.jsonl — 44 rows carrying 216 determination rows, whose verdicts are src/compare.py re-run over the numbers the document states, never a typed opinion
never — evals/judge.py is pure code, no model, no key
the record schema
data/fields.json — the 3 batch fields and 10 row fields src/prompt.py assembles the user message from
read by src/prompt.py and src/extract.py only
the key
.env — never committed (see .gitignore)
only inside the Authorization header, to the configured BASE_URL (src/adapters/__init__.py)
The wireWhat crosses it, and when
Runtime call site
Destination
src/adapters/__init__.py line 55
the configured BASE_URL
Build-time (corpus tooling, run once)
Destination
none — this kit’s corpus is generated locally
Zero-egress topology: point BASE_URL at a local OpenAI-compatible server and nothing leaves the machine — statically true of the shipped adapter, whose only credential travels in the Authorization header.
The third state
What the provider retains, trains on or logs once a request arrives is not measured here — it is provider-dependent, and this page does not assert what no run of ours can verify.
The shapeHow it ships, and what you add
The key
Read from the shared .env or the real environment only, never written into the repo, never requested from a reader on any surface. src/app.py's /api/compare handler strips api_key and base_url out of any exception message before it reaches the browser, so a misconfigured key cannot leak into a UI error.
You add
your reverse proxy and your identity in front of one process — the kit deliberately ships neither, because identity belongs to your estate, not to a kit
Never ships
Docker, Helm, a queue, a database. The product is a folder of readable Python; what to run it under is this page’s job to state, not the kit’s job to impose
The ladderEach decision, and what you provision past its ceiling
Decision
The kit ships
Measured here
Past the ceiling
What stops being valid
model
one call per RECORD, carrying five sections plus the 13-field schema, behind src/adapters/__init__.py — OpenAI-compatible wire format over raw HTTP, so a forker runs this on whichever key they hold. MAX_TOKENS is 8000 (src/extract.py), and unlike the sibling extraction kits that number is not inherited: this run's longest reply billed 5773 output tokens and 3 of 44 documents would have been truncated at 4000.
14485ms p50 / 26815ms p95 over 44 calls, 683s wall clock (run r001-spec-conformance, 2026-08-23 -- see Cost.cost_by_model)
one call per record, no concurrency and nothing shared between calls — see Architecture.breaks_at_scale. MAX_CALLS_PER_DAY in src/budget.py caps the shared key across every kit on this machine, not this kit's own throughput.
point src/adapters/__init__.py at a different provider or model and every published accuracy, cost and latency figure is void until re-run — and on this kit the output-token finding goes with them, since a reasoning pass is a property of the model rather than of the prompt.
corpus refresh
tools/build_corpus.py regenerates the whole corpus — 44 records over a fixed roster of invented grades, 9 determinations and six disposition outcomes — byte-identically from a fixed seed every time. There is no incremental refresh. Both verdicts, the gap classification and the interlock are derived by IMPORTING src/compare.py rather than restating the rule, so the corpus cannot disagree with the prompt or the guardrail about what any of them mean.
0.087s wall time to regenerate all 44 records and their gold rows; sha1 of the concatenated corpus and of gold.jsonl unchanged across two consecutive runs (measured directly, 2026-08-23 (python3 tools/build_corpus.py, timed and hashed twice) -- see Data.index for the separate segmentation figure, a different step)
a real plant's batch volume, product roster, specification library and customer vocabulary do not come from a fixed seed. This corpus applies ONE invented nine-determination library to every product, which no real plant would do, and its near misses are drawn from a fixed list of nine; see Data.breaks_on and Eval.could_not_verify.
point tools/build_corpus.py at your own records and specification library and every published accuracy figure is void — they are this corpus's own planted alias and near-miss sets, not a property of the model.
labels
evals/check_labels.py re-derives BOTH verdicts, the gap classification and the interlock on every row from that row's own numbers before evals/run.py is allowed to spend, re-locates every claimed customer wording in the Customer Specification section, and refuses any degenerate class. Scoring (evals/judge.py) is four separate graders — field cells, customer coverage, the gap matrix and the disposition — plus three gold-free diagnostics computed by pure code from the reply (src/extract.py::compute), never from a second model call.
2292 cells scored (132 batch fields plus 216 rows x 10) with the coverage, gap, interlock and disposition matrices on top (lenses.Eval.dataset, run r001-spec-conformance, 2026-08-23)
the gold set stops at 44 records and 38 gap rows, and its hardest planted case is a confusable determination NAME. A customer entry whose scope is genuinely arguable, a unit mismatch, and a superseding re-test are never presented; see Data.breaks_on.
a different record schema (data/fields.json) or a different comparison rule needs its own gold set and its own evals/check_labels.py pass before any published figure can be trusted again.
Every threshold is a measurement with its provenance beside it, or says is_measured:false. A ceiling with no seam says so — it is the point the kit is outgrown, never a forced join.
When it failsFailure signatures
What you see
What it is
First move
a row whose Cell chip reads GAP — internal pass, customer fail
this batch cleared the plant's own release specification and would not have cleared the consignee's. It is derived by src/compare.py::classify() from the two verdicts the reply gave; the model was never asked whether the row was a gap. 38 of the 216 rows in this corpus are gaps, spread over 28 batches
read the consignee's own wording in the same row before assuming the customer limit is the tighter one — 25 of the 136 customer-limited rows here are LOOSER than the plant's, and 9 rows are the reverse gap: they failed internally and would have passed for that customer (run r001-spec-conformance, 2026-08-23 -- see Eval.graders (the gap matrix) and Data.why_this_corpus)
RELEASE INTERLOCK on a batch
the batch carries at least one gap row AND its disposition record says it was released to the very consignee whose limit it would have failed. It fired on 7 of 44 batches on this run, every one a true positive, 0 false alarms. It needs no gold at all — both halves come out of the reply — so it computes identically on a record nobody has scored
open the gap row and the disposition record together. The flag says the two coexist; it does not say the release was wrong, and this kit dispositions nothing either way (src/compare.py::release_interlock over run r001-spec-conformance's result file, 2026-08-23)
a customer verdict of not_specified on a determination that LOOKS listed
the consignee's specification names something similar and different — “Particle size D90” where D50 was measured, “Tapped density” for bulk density, “Acid-insoluble ash” for total ash. 29 such entries are planted, and this run matched none of them: coverage precision 1.00, 0 invented limits
check the customer's list for the determination by name before treating not_specified as a miss — an unlimited determination is a real answer, and 80 of 216 rows here genuinely are unlimited (run r001-spec-conformance's coverage matrix, 2026-08-23 -- and the same corpus's exact-match floor, which refuses every near miss for the wrong reason (it cannot match anything inexact))
No machine symptom — this failure leaves no trace in any output.
no path in src/compare.py, src/extract.py or src/app.py releases, holds, diverts, downgrades, rejects or reworks a batch, and no setting adds one — the cap is batch-release and the interlock is a returned field, not a control. A wrong verdict on a real deployment would show up only in whatever quality system consumes this kit's output, which this kit does not have and does not simulate. There is deliberately no committed artifact naming that failure: it is outside this kit's boundary, not unmeasured.
Whether a clean gap matrix on 44 records and one seed generalises was not tested — see Eval.could_not_verify. A second model tier was not run, so every tier comparison the sibling kits publish is absent here. Concurrency (every call is sequential), unit conversion between a result and a limit stated differently, a specification revised between test and review, a superseding re-test, a customer specification held in a contract register rather than in the record, and whether disabling the provider's reasoning pass changes any figure are all unmeasured.
The corpus licence, from the Data lens: MIT — this repository's own licence. Every plant, product, consignee, specification reference, limit, result and disposition is invented. A real batch quality record cannot be published either: it names a real customer, states that customer's contractually agreed limits, and carries a real release decision by a named person. Your corpus’s licence is yours to verify, and the labels you write are about your documents.
PresenterOpens the private repo. Visible to admins only.
In one lineRow and batch field exact match
Does every value the run returned match gold, after trimming whitespace and punctuation and treating numbers within half a thousandth as equal? Ten fields on each determination row plus three on the batch — including a correctly-returned null where the consignee does not limit a determination, which is a HIT and not an abstention.
$0.00per 1,000 batch quality records
nodata leaves your network
yessame answer every time
MethodHow the test was run
evals/judge.py::score, in-process, no key and no model. Rows are paired to gold BY PARAMETER NAME rather than by position, so a reply that drops one row scores that one row wrong instead of shifting every later row and reporting six errors for one omission.
Every grader on these pages scored the same 216 already-recorded answers. Nothing was re-generated, so this compares rulers and not models.
The inputOne real row, seen by every grader
The batch quality record
BQR-0017
The determination this row is about
total plate count
What the laboratory measured
995
In
CFU/g
The plant's own release limits
no lower limit, upper limit 1000
Against the plant's limits
pass
The consignee's own wording, copied from their specification
total plate count
The consignee's limits
no lower limit, upper limit 800
Against the consignee's limits
fail
Where the two verdicts land
gap
What the disposition record says happened
released_to_consignee
Gap row on a batch released to that same consignee
yes
Grader
Verdict
Why
Row and batch field exact match
correct
All 43 cells on BQR-0017 matched gold exactly — 4 determination rows × 10 fields plus the 3 batch fields — including customer_parameter returned as null on particle size D50, where the consignee's list carries “Particle size D90” and nothing else resembling it.
Customer coverage matrix
correct
Three of the four determinations are limited by CUST-HOLLIN and one is not. The run matched all three and refused the near miss. The free exact-match floor also gets this record right, because CUST-HOLLIN happened to use the plant's own wording for all three — on the 81 alias rows elsewhere in the corpus it does not.
The gap matrix
correct
total plate count measured 995 CFU/g. The plant's limit is not more than 1000 — pass. CUST-HOLLIN's is not more than 800 — fail. src/compare.py::classify() derives GAP from those two verdicts; the model was never asked whether this row was a gap. The free single-threshold floor answers ‘pass’ for both and sees nothing.
Disposition classification
correct
The disposition record reads “Batch released by quality assurance on 2026-03-17 and allocated to CUST-HOLLIN. Certificate of analysis issued with the shipment.” — released_to_consignee. Combined with the gap row above, src/compare.py::release_interlock() fires: this batch was shipped to the very consignee whose limit it would have failed.
The formulaWhat it computes
The analysisWhat it actually did
Model
Result
the fast tier
scored 99.8%
In operationWhat to monitor
Reference standard: tools/build_corpus.py's gold, read back off the same numbers, wordings and dates the document states. evals/check_labels.py re-derives every verdict from its own numbers, asserts every claimed customer wording is readable off the Customer Specification section, and refuses any degenerate class, before any run is allowed to spend.
These rates are UNKNOWN, on purpose
This grader IS the reference standard for values, so it cannot be scored against itself. What can go wrong is the corpus's own generation logic, which tools/build_corpus.py's _verify() pass checks by confirming every stated value appears verbatim in the document and every date parses as a real calendar date.
Watch these
customer_parameter specifically — it is the field the whole kit turns on, and the only field this run got wrong
the two customer limit fields on rows the consignee does NOT limit, where a correctly-returned null is the answer and an invented bound is a manufactured limit
internal_verdict and customer_verdict together rather than separately: a run can score well on each and still be collapsing one into the other
Alarm on
Any drop in field accuracy below 99.83 pct — this run's figure is the baseline, and a regression means the prompt, the corpus or the provider changed.
How tight can the band be? No tolerance band on the grade itself: exact match after trimming whitespace and punctuation, with numeric fields equal within 0.0005. Never a continuous score to round.
Cadence: Re-score on any change to src/prompt.py, data/fields.json or tools/build_corpus.py — the first two change what is asked, the third changes what is asked about. Re-run evals/run.py (paid) on any change to MAX_TOKENS or the provider/model.
The decisionWhen to reach for it
Use it
Gold is read back off the same numbers and wordings the record states, never from a separate target — true of every kit corpus, never true of a real plant's own batch archive.
Do not use it
The true values are not known in advance — the normal state of a real quality review, and the reason this corpus is generated rather than captured.
PresenterOpens the private repo. Visible to admins only.
In one lineCustomer coverage matrix
For each tested determination, does the consignee's specification limit it AT ALL? Positive class is “limited”. A FALSE POSITIVE here is an INVENTED limit — the near-miss trap — and a FALSE NEGATIVE is a missed alias, which silently deletes any gap that row carried.
$0.00per 1,000 batch quality records
nodata leaves your network
yessame answer every time
MethodHow the test was run
evals/judge.py::score_flags, in-process, no key and no model. A row counts as “limited” when the run's customer_verdict is anything other than not_specified.
Every grader on these pages scored the same 216 already-recorded answers. Nothing was re-generated, so this compares rulers and not models.
The inputOne real row, seen by every grader
The batch quality record
BQR-0017
The determination this row is about
total plate count
What the laboratory measured
995
In
CFU/g
The plant's own release limits
no lower limit, upper limit 1000
Against the plant's limits
pass
The consignee's own wording, copied from their specification
total plate count
The consignee's limits
no lower limit, upper limit 800
Against the consignee's limits
fail
Where the two verdicts land
gap
What the disposition record says happened
released_to_consignee
Gap row on a batch released to that same consignee
yes
Grader
Verdict
Why
Row and batch field exact match
correct
All 43 cells on BQR-0017 matched gold exactly — 4 determination rows × 10 fields plus the 3 batch fields — including customer_parameter returned as null on particle size D50, where the consignee's list carries “Particle size D90” and nothing else resembling it.
Customer coverage matrix
correct
Three of the four determinations are limited by CUST-HOLLIN and one is not. The run matched all three and refused the near miss. The free exact-match floor also gets this record right, because CUST-HOLLIN happened to use the plant's own wording for all three — on the 81 alias rows elsewhere in the corpus it does not.
The gap matrix
correct
total plate count measured 995 CFU/g. The plant's limit is not more than 1000 — pass. CUST-HOLLIN's is not more than 800 — fail. src/compare.py::classify() derives GAP from those two verdicts; the model was never asked whether this row was a gap. The free single-threshold floor answers ‘pass’ for both and sees nothing.
Disposition classification
correct
The disposition record reads “Batch released by quality assurance on 2026-03-17 and allocated to CUST-HOLLIN. Certificate of analysis issued with the shipment.” — released_to_consignee. Combined with the gap row above, src/compare.py::release_interlock() fires: this batch was shipped to the very consignee whose limit it would have failed.
The formulaWhat it computes
The analysisWhat it actually did
Model
Result
the fast tier
scored 99.5%
In operationWhat to monitor
Reference standard: Gold's customer_parameter, which tools/build_corpus.py wrote as the exact wording it printed into the Customer Specification section, and which evals/check_labels.py re-locates in that section on every row before any run may spend.
These rates are UNKNOWN, on purpose
Whether the same discrimination holds against wordings this corpus did not build. The near misses here are ordinary confusable vocabulary drawn from a fixed list of nine (29 entries planted); a genuinely ambiguous entry — one where two competent analysts would disagree about whether it is the same determination — is not present, so this grader has never met the case where the right answer is arguable.
Watch these
false_positive above all — an invented customer limit is a claim about a contract, and it can manufacture a gap that does not exist
false_negative on ALIAS rows specifically, since that is where the free exact-match floor loses 81 of 136 and where the model's whole advantage lives
the claim_located_rate diagnostic beside it: of every coverage claim made, how many name a wording actually present in the document
Alarm on
Any false positive. On this run there were none in 135 claims, and the pure-code unlocatable_claim check independently located all 135 of them in the customer specification section.
How tight can the band be? Binary per row against a 136-row positive class, so one row moves recall by 0.74 points. No band finer than that is meaningful.
Cadence: Re-score on any change to the alias or near-miss lists in tools/build_corpus.py, or to rule 4 and 5 of SYSTEM in src/prompt.py — those are what this grader measures.
The decisionWhen to reach for it
Use it
The consignee's specification is present in the record and its entries are unambiguous — either the same determination in other words, or a clearly different one.
Do not use it
A customer entry whose scope is genuinely arguable, or a specification held outside the record entirely. Neither is in this corpus.
PresenterOpens the private repo. Visible to admins only.
In one lineThe gap matrix
Does this determination PASS the plant's internal specification and FAIL the consignee's? Positive class is the gap. It is DERIVED by src/compare.py::classify() from the two verdicts the run reported — the model is never asked whether a row is a gap — so a run cannot score here without holding both verdicts at once.
$0.00per 1,000 batch quality records
nodata leaves your network
yessame answer every time
MethodHow the test was run
evals/judge.py::score_flags, in-process, no key and no model. Derives gold's cell with src/compare.py::classify over gold's own verdicts, derives the run's cell the same way over the run's own two verdicts, and compares them per row.
Every grader on these pages scored the same 216 already-recorded answers. Nothing was re-generated, so this compares rulers and not models.
The inputOne real row, seen by every grader
The batch quality record
BQR-0017
The determination this row is about
total plate count
What the laboratory measured
995
In
CFU/g
The plant's own release limits
no lower limit, upper limit 1000
Against the plant's limits
pass
The consignee's own wording, copied from their specification
total plate count
The consignee's limits
no lower limit, upper limit 800
Against the consignee's limits
fail
Where the two verdicts land
gap
What the disposition record says happened
released_to_consignee
Gap row on a batch released to that same consignee
yes
Grader
Verdict
Why
Row and batch field exact match
correct
All 43 cells on BQR-0017 matched gold exactly — 4 determination rows × 10 fields plus the 3 batch fields — including customer_parameter returned as null on particle size D50, where the consignee's list carries “Particle size D90” and nothing else resembling it.
Customer coverage matrix
correct
Three of the four determinations are limited by CUST-HOLLIN and one is not. The run matched all three and refused the near miss. The free exact-match floor also gets this record right, because CUST-HOLLIN happened to use the plant's own wording for all three — on the 81 alias rows elsewhere in the corpus it does not.
The gap matrix
correct
total plate count measured 995 CFU/g. The plant's limit is not more than 1000 — pass. CUST-HOLLIN's is not more than 800 — fail. src/compare.py::classify() derives GAP from those two verdicts; the model was never asked whether this row was a gap. The free single-threshold floor answers ‘pass’ for both and sees nothing.
Disposition classification
correct
The disposition record reads “Batch released by quality assurance on 2026-03-17 and allocated to CUST-HOLLIN. Certificate of analysis issued with the shipment.” — released_to_consignee. Combined with the gap row above, src/compare.py::release_interlock() fires: this batch was shipped to the very consignee whose limit it would have failed.
The formulaWhat it computes
The analysisWhat it actually did
Model
Result
the fast tier
scored 100.0%
In operationWhat to monitor
Reference standard: src/compare.py::classify() run over GOLD's own two verdicts, which are themselves src/compare.py::compare() run over the numbers the document states. The true gap is never separately typed, only derived — so the truth this grades against cannot drift from the rule the kit applies.
These rates are UNKNOWN, on purpose
Whether the result holds where the two specifications differ in ways this corpus does not build: a unit mismatch, a limit expressed as a percentage of a target, a revision that changed between test and review. The matrix is exact against these 216 rows and says nothing beyond them. See Eval.could_not_verify.
Watch these
false_negative — a batch that would have failed the customer and was not flagged is the error this whole kit exists to prevent
false_positive, which on this corpus can only come from matching a near-miss entry and inventing a limit; it manufactures a gap out of a determination the contract never covers
the split between gap rows whose customer entry is an alias and those written in the plant's own words — the free exact-match floor gets the second group and not the first
Alarm on
Any false negative. There were none in this run's 38 gold gap rows; the free exact-match floor missed 19 of them and the free single-threshold floor missed all 38.
How tight can the band be? Binary per row against a 38-row positive class, so one row moves recall by 2.6 points. A clean sweep of 38 is a real result and a small one; no band finer than one row is supportable.
Cadence: Re-score on any change to src/compare.py::compare or ::classify, or to rules 1-3 of SYSTEM in src/prompt.py — all of those change what the gap means.
The decisionWhen to reach for it
Use it
Both specifications are readable in the record and state their limits in the same unit as the result.
Do not use it
A real release decision is not known until a qualified person signs against an approved specification — this corpus's gold is a construction, not an observed outcome, and no batch here was ever actually shipped or rejected.
PresenterOpens the private repo. Visible to admins only.
In one lineDisposition classification
Which of six things the disposition record says actually happened to the batch — released to the named consignee, diverted to another, downgraded, held, rejected or reworked. It is the second half of the eval intent (“and how it was dispositioned”) and it is what the release interlock is computed from.
$0.00per 1,000 batch quality records
nodata leaves your network
yessame answer every time
MethodHow the test was run
evals/judge.py::score_flags, in-process, no key and no model. Exact string match against the six allowed values, per batch.
Every grader on these pages scored the same 216 already-recorded answers. Nothing was re-generated, so this compares rulers and not models.
The inputOne real row, seen by every grader
The batch quality record
BQR-0017
The determination this row is about
total plate count
What the laboratory measured
995
In
CFU/g
The plant's own release limits
no lower limit, upper limit 1000
Against the plant's limits
pass
The consignee's own wording, copied from their specification
total plate count
The consignee's limits
no lower limit, upper limit 800
Against the consignee's limits
fail
Where the two verdicts land
gap
What the disposition record says happened
released_to_consignee
Gap row on a batch released to that same consignee
yes
Grader
Verdict
Why
Row and batch field exact match
correct
All 43 cells on BQR-0017 matched gold exactly — 4 determination rows × 10 fields plus the 3 batch fields — including customer_parameter returned as null on particle size D50, where the consignee's list carries “Particle size D90” and nothing else resembling it.
Customer coverage matrix
correct
Three of the four determinations are limited by CUST-HOLLIN and one is not. The run matched all three and refused the near miss. The free exact-match floor also gets this record right, because CUST-HOLLIN happened to use the plant's own wording for all three — on the 81 alias rows elsewhere in the corpus it does not.
The gap matrix
correct
total plate count measured 995 CFU/g. The plant's limit is not more than 1000 — pass. CUST-HOLLIN's is not more than 800 — fail. src/compare.py::classify() derives GAP from those two verdicts; the model was never asked whether this row was a gap. The free single-threshold floor answers ‘pass’ for both and sees nothing.
Disposition classification
correct
The disposition record reads “Batch released by quality assurance on 2026-03-17 and allocated to CUST-HOLLIN. Certificate of analysis issued with the shipment.” — released_to_consignee. Combined with the gap row above, src/compare.py::release_interlock() fires: this batch was shipped to the very consignee whose limit it would have failed.
The formulaWhat it computes
The analysisWhat it actually did
Model
Result
the fast tier
scored 100.0%
In operationWhat to monitor
Reference standard: Gold's disposition, which tools/build_corpus.py chose BEFORE it wrote the free text, so the text is a rendering of the label rather than the label being a reading of the text.
These rates are UNKNOWN, on purpose
How hard this actually is. Every disposition class here is rendered from two or three fixed wordings, and both free floors score 44 of 44 on it with a keyword regex — so this grader has separated nothing on this corpus and cannot say whether a model helps. A real disposition record is one person's prose.
Watch these
released_to_consignee specifically, since it is the only class that can raise the release interlock
the two classes that NAME the consignee while not shipping to them (diverted_other_customer, downgraded) — those are what a keyword floor grepping for the consignee beside “released” gets wrong
per-class accuracy rather than the total, because the classes are unbalanced (diverted_other_customer=3, downgraded=3, held_pending_qa=7, rejected=9, released_to_consignee=12, reworked=10)
Alarm on
Any released_to_consignee called something else, or something else called released_to_consignee — both change whether the interlock can fire.
How tight can the band be? Binary per batch over 44 batches, and the smallest class holds 3. One batch moves the total by 2.3 points and a small class by far more, so no per-class band is supportable here.
Cadence: Re-score on any change to DISPOSITION_TEXTS in tools/build_corpus.py or to the disposition hint in data/fields.json.
The decisionWhen to reach for it
Use it
The disposition record states one outcome plainly.
Do not use it
A record that describes several things happening to different parts of a batch, or one written before the outcome was decided. Neither is in this corpus.
A living map of modern AI — kept current every morning