The business caseThe problem this solves
A district bills Medicaid for a special-education service it delivered in school. Before the claim line goes anywhere, somebody has to open the folder behind it and ask six separate questions: is parental consent to bill on file and current on the date of service; does the provider hold the credential the state requires for THAT service; is the service on the student's IEP, in the setting the IEP mandates; does the session note carry every element the rules require; do the date and duration agree with the service log; and does the procedure code match the service that was actually delivered. Five of those six are comparisons a spreadsheet could do. The sixth question underneath all of them — what service was actually delivered — is written in a paragraph of prose and nowhere else. Opening five documents per claim and reading a date, a credential string, a grid row, a log line and a code against each other by hand — and then reading a paragraph of prose to find out which of them you were supposed to be comparing against in the first place.
Audience
A district's Medicaid billing clerk or special-education compliance reviewer, working a queue of assembled packets before a batch is submitted, and the person who has to answer an audit afterwards. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual school-Medicaid claim packets
The corpus is 62 school-Medicaid claim packets, 0.15 MB (json 3 · jsonl 1 · md 2 · txt 62). Because the shape of a school-Medicaid documentation failure is not the dates, it is WHICH service you are checking against. Ten of the sixty-two packets code a service the session note does not describe, and on those the credential matrix, the IEP grid and the code table are all being read against the wrong row — invisibly, because every comparison passes. Eight more carry a note short of a required element, which no panel in the packet lists. Between them that is 28 of the 372 requirement rows a column-reader cannot reach, and it is what the paid call is being asked to buy. The other 344 are a comparison and two date tests, and this kit does all of them for free on every arm rather than charging for them.
The corpus
- The 62 school-Medicaid claim packetsgenerated from a fixed seed, so no real record, person or institution appears in it.
- Where each came fromNowhere — all 62 packets, data/packets.json, data/reference.json and the whole answer key are generated in-process by the builder from one seed. SMDQ-2026 is invented and the PC-### procedure codes are not HCPCS, not CPT and not any real code set.
Swap this folder for your own material and the kit is pointed at your school-Medicaid claim packets. That is the whole change — there is no database to migrate.
SCHOOL MEDICAID CLAIM - DOCUMENTATION QUALITY CHECK

CLAIM HEADER
  Claim              SMC-0001
  District           Balfern Hollow Public Schools
  Student reference  STU-8743
  Date of service    2025-11-24
  Provider           M. Hallberg
  Service as coded   Speech-language therapy, individual
  Procedure code     PC-101
  Units billed       30 minutes
  Assembled by       K. Sowande, claims office
  Assembled on       2025-12-01

PARENTAL CONSENT TO BILL
  Consent record     signed 2025-05-28, expires 2026-05-28, form CONSENT-PB-1

IEP SERVICE GRID (the services this student's IEP mandates)
   Service                              Setting      Minutes/week  From         To
   Speech-language therapy, individual  individual   60            2025-09-02   2026-06-12

PROVIDER RECORD
  Provider record    M. Hallberg
  Credential held    SLP
  Credential expires 2027-05-21

CREDENTIAL MATRIX (the district's own matrix of the credential each service requires)
   Service                              Required credential
   Speech-language therapy, individual  SLP
   Speech-language therapy, group       SLP
   Occupational therapy                 OTR
   Physical therapy                     PT
   Counseling, individual               LCSW
   Counseling, group                    LCSW
   Nursing service                      RN

PROCEDURE CODE TABLE (this district's own codes; not HCPCS, not CPT)
   Code    Service                              Unit minutes
   PC-101  Speech-language therapy, individual  30
   PC-102  Speech-language therapy, group       30
   PC-201  Occupational therapy                 15
   PC-301  Physical therapy                     15
   PC-401  Counseling, individual               30
   PC-402  Counseling, group                    30
Abridged — the file continues.
The outcomeWhat a good result looks like
Every requirement carries MET, UNMET or UNEVIDENCED, the SMDQ-2026 rule it rests on, and one row copied verbatim out of the packet wherever it is not MET — so a reviewer sees the finding and the evidence for it in one glance, and the packet goes back with the requirement named rather than with 'something is wrong'.
And when it cannot
⚠︎ THE PACKET-LEVEL NUMBER IS 43 OF 62 AND THE KIT LOSES IT TO ITS OWN FREE FLOOR, which scores 54 of 62 for $0.00 (McNemar exact p = 0.027, 5 discordant one way against 16 the other). claim_all_correct requires all six statuses, both readings, the claim status and both requirement lists to be right at once, and one defect caps it: the arm quoted a row on 21 of the 372 requirement rows where the checklist says quote nothing. The number this kit wins is the one under it — 369 of 372 requirement statuses after the pure-code station against the same floor's 355, p = 0.0026.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
- Your billers code the service correctly and your documentation arguments are about consent dates, credentials, logs and codes. — the free panel floor alone — python3 -m evals.run --floor rules
Every one of those is a comparison and two date tests. The floor is 344 of 372 requirement statuses and 44 of 62 whole packets for $0.00, no key and no network. - Your session notes are written by therapists and your billers code from a schedule rather than from the note. — the paid call, rechecked
That is the only arm that reads the note: 9 of the 10 packets the claim coded differently, against the keyword floor's 3 and the panel floor's 0.
And where nothing here is good enough:
- You need a citation on every finding for an audit file. — neither, yet
The arm quotes a row on 21 requirements that are MET, where the contract says null. It never invents one — citations_unlocatable is 0 of 75 — but a queue where every satisfied requirement arrives carrying evidence is a queue where the rows that matter are invisible.
At a glanceHow the whole thing runs
Run once, for real, on 2026-09-09. Every figure on these pages was captured from that run — nothing is written from intent.
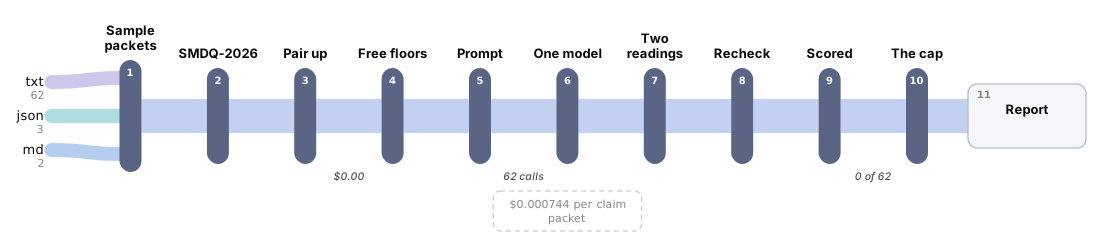
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
| What do I have to bring? | Point data/corpus/ at your own exported packets and data/packets.json at your own records, keep the nine panel headings, and every free floor, the parser, the engine, the station, the citation scorer and the board work unchanged with no key at all. The boundary is the ANSWER KEY, not the documents. Corpus lens → |
| When is this the wrong choice? | Avoid: Paying for a reading you do not need, once per claim line, every month. That is the case against the best-fitting scenario (“Your billers code the service correctly and your documentation arguments are about consent dates, credentials, logs and codes.”). 3 scenarios scored in all, each with its own. Eval lens → |
| Where does it stop working? | A packet whose panels are not the nine this parser knows. src/rules.py splits on the headings CLAIM HEADER, PARENTAL CONSENT TO BILL, IEP SERVICE GRID, PROVIDER RECORD, CREDENTIAL MATRIX, PROCEDURE CODE TABLE, SESSION NOTE, SERVICE LOG and SUBMISSION NOTES, and a packet that does not carry them parses to empty panels rather than raising. 6 recorded failure modes, each from a run rather than a guess. Corpus lens → |
| What was never verified? | Whether the citation defect is reproducible. One run, one tier, one temperature. 5 items this kit says it could not check. Eval lens → |
| Can I run this on a model I control? | The shipped adapter is one provider, one key, configured in .env; the Prompt lens states what swapping it costs. The published figures come from 1 model on the fast tier, reasoning disabled (THE PUBLISHED RUN). Prompt lens → |
| And if it fits — what do I stand up? | 4 artifacts with a stated home and a stated egress, and 4 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one. step 14 — Run it in your environment → |
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-09-09 — r001-medicaid-doc. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
- The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
- The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — Clone and run python3 -m evals.baseline with no key, no network and nothing installed: all four floors score in-process against the derived key. python3 -m evals.check_labels and python3 tools/build_corpus.py --check are the same — no key, no network, no install.