A card scheme changes a fee, and your team writes down every assumption the estimate depends on. This app reads the bulletin and tells you exactly which of those assumptions still hold.
PresenterOpens the private repo. Visible to admins only.
For the payments operations analystPayments & Fintech
Why it matters
Today's manual process, and the same job with the app
A payments operations analyst at a card network or a large merchant, reviewing fee-change bulletins every quarter.
✕Today's manual process
1Read the bulletin and copy every assumption line into a working sheet.
2Check the working to see whether each assumption is actually used in the arithmetic.
3Decide by memory which lines were withdrawn or borrowed from another bulletin.
4One line missed and the review pack rests on an assumption nobody meant to keep.
Every bulletin's assumptions checked manually
✓With the app
1The bulletin is read and every assumption line is pulled out automatically.
2Each line is checked against the working, so the arithmetic actually behind it is clear.
3Withdrawn and borrowed lines are dropped and only the assumptions that still stand are kept.
4The pack is complete with the owner named and ready for the pricing review.
The app checks every line for you
See it work
One real bulletin, and what the app decided
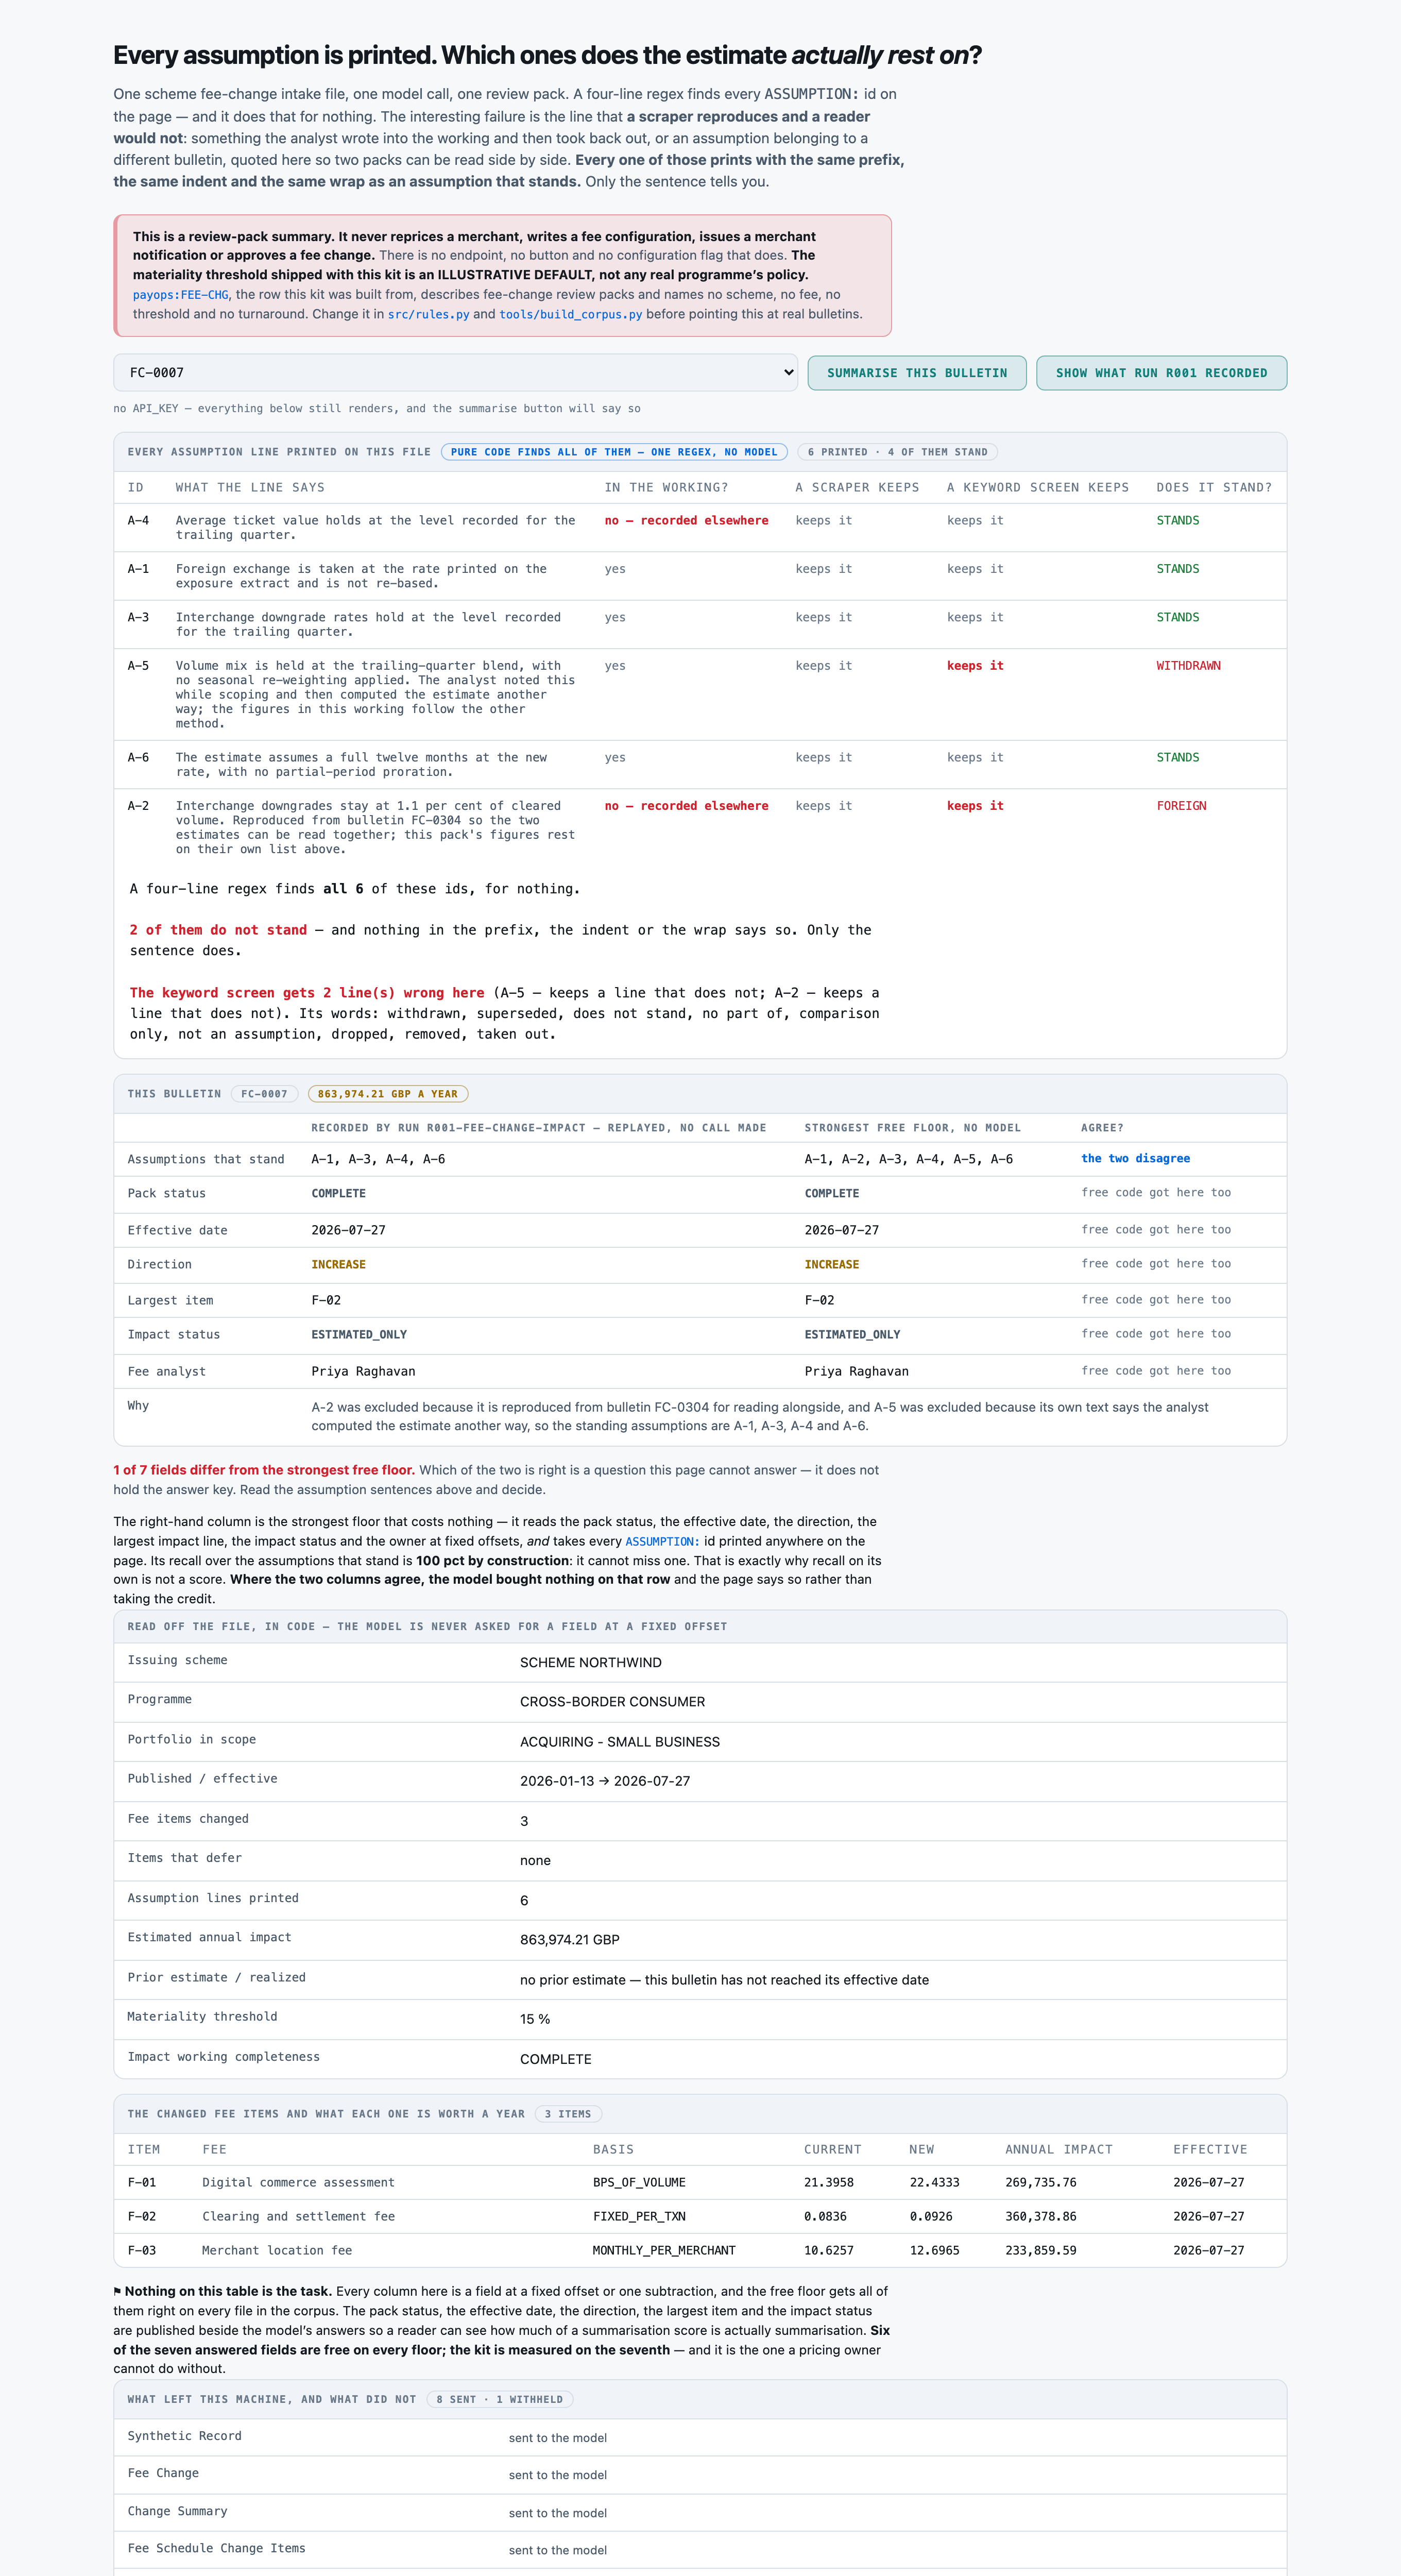
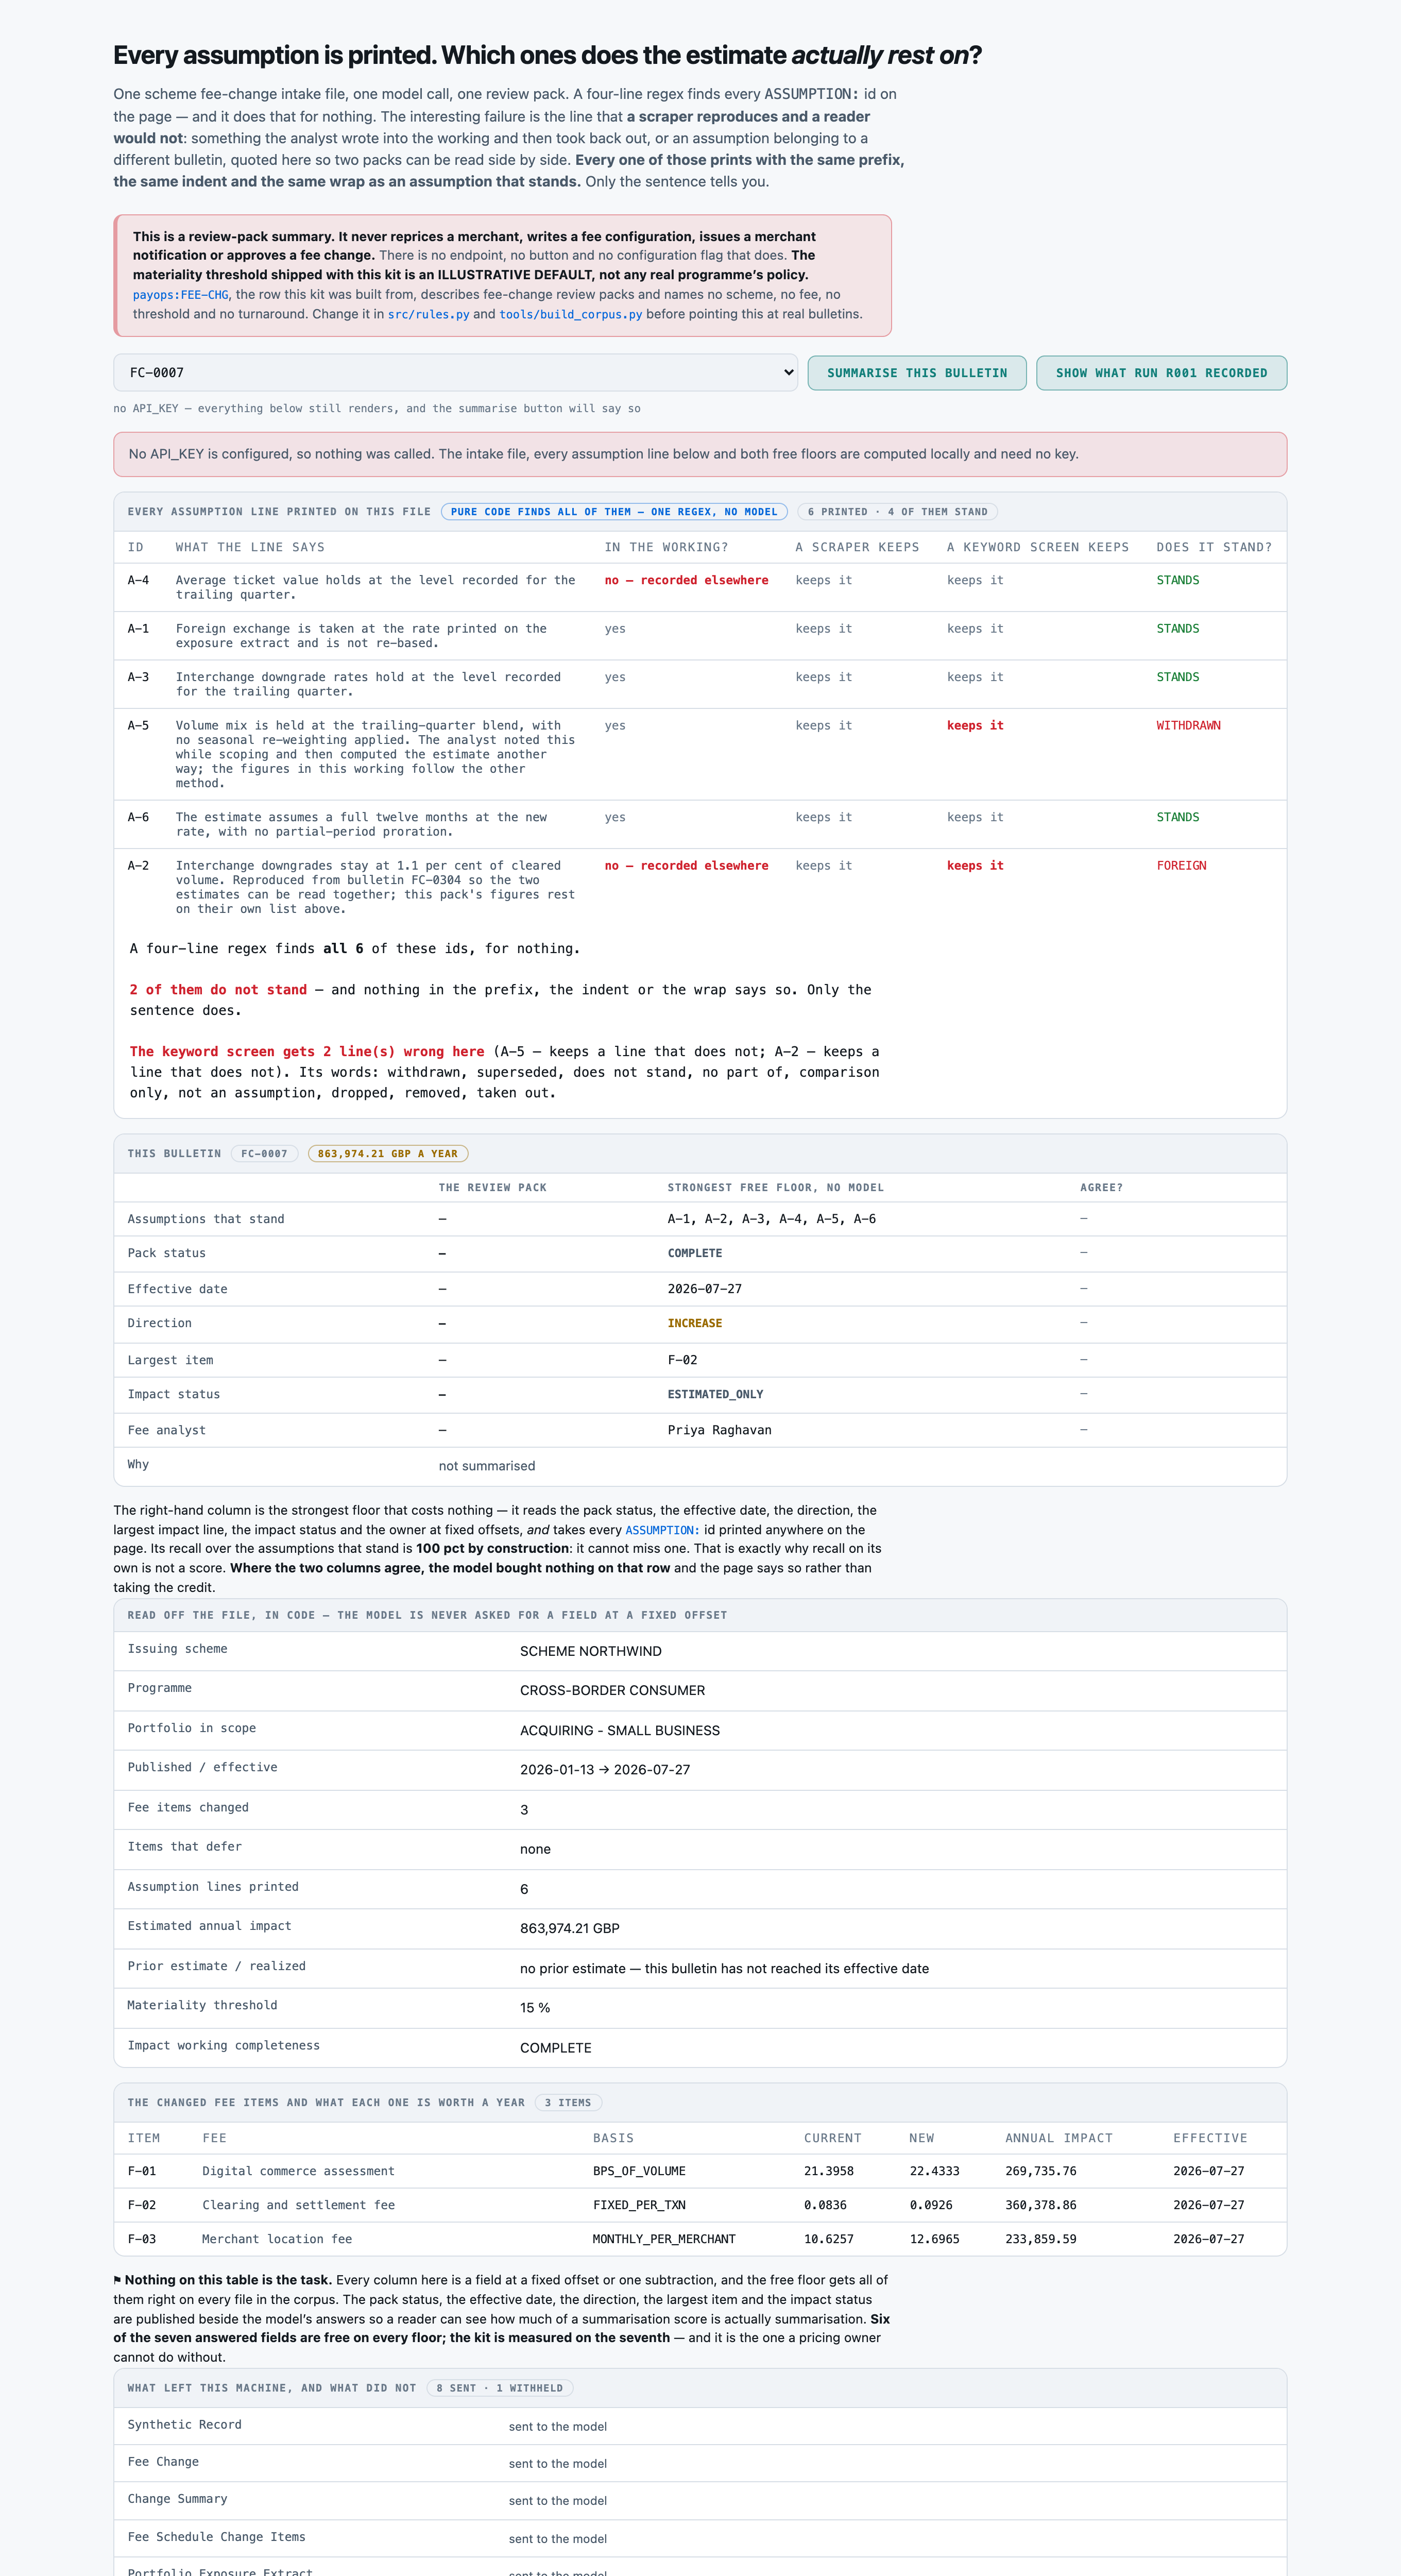
Bulletin FC-0007 raises a scheme fee; two printed lines don't belong in the estimate, and the app leaves both out.
Check the assumptions behind a card-fee changeReference appBuilt to be shaped to your process
4
1Backed out The analyst worked it out a different way, so this line is dropped.
2Borrowed for comparison Reproduced from another bulletin; it isn't part of this estimate.
3What the pack kept Four of the six printed lines still count toward the estimate.
4Where it lands The finished pack is marked complete and goes to the fee analyst.
For engineers
How it is built, and how we measured it
All fourteen steps of the build are written up, from the business case to running it in your own environment.
A small, forkable project that does one job end to end. Run once for real, and every figure on these pages captured from that run.
PresenterOpens the private repo. Visible to admins only.
The business caseThe problem this solves
A card scheme publishes a fee-change bulletin. A payments operations analyst works out what it is worth against the portfolio, writes the working, and files it. Somebody then has to turn that into a review pack finance and pricing can act on before the effective date. The NUMBER is the easy half and this kit never re-computes it. The half that decides whether the pack is worth anything is the list of assumptions the estimate rests on -- because an estimate with its assumptions stripped out is a number with no way back to a decision. Every assumption is printed on its own line with an id. So is every assumption the analyst wrote and then took back out of the estimate. So is every assumption quoted from a different bulletin for comparison. Same prefix, same indent, same wrap. the assumption list a fee-change intake tool can already produce: every ASSUMPTION: id printed anywhere on the page, found by a four-line regex. Implemented properly and shipped as all-scrape in evals/baseline.py, that has 100 pct recall by construction and still gets the review pack wrong on 33 of the 80 files, because it carries every line the analyst withdrew and every line quoted from another bulletin.
Audience
a payments operations analyst assembling this quarter's fee-change review packs, and a pricing owner deciding whether the estimate in front of them rests on anything they disagree with. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual fee-change intake files
The corpus is 80 fee-change intake files, 0.43 MB (txt 80). A fee-change review pack is a scheme's published schedule crossed with an acquirer's own portfolio volumes, and the second half is among the most commercially sensitive numbers a payments business holds -- what it processes, for whom, at what blended rate. There is no public corpus and there will not be one. A SCRUBBED real one would be worse rather than better, and the reason is specific: scrubbing removes the analyst's working notes, and the working notes ARE what this kit measures.
The corpus
The 80 fee-change intake filesgenerated from a fixed seed, so no real record, person or institution appears in it.
Where each came fromwritten for this kit rather than collected — the corpus is generated in the kit's own repository, so there is no third-party data in it.
Swap this folder for your own material and the kit is pointed at your fee-change intake files. That is the whole change — there is no database to migrate.
One fee-change intake file, as the model receives itFC-0001.txt · 1 of 80
Synthetic Record
----------------------------------------------------------------
Every field below is invented. This is a generated fee-change intake file for
an AI use-case kit; it reproduces no card scheme, no programme, no fee, no
rate, no merchant, no portfolio and no real person. The scheme names are made
up. The materiality threshold is an ILLUSTRATIVE DEFAULT, not any real
programme's policy.

Fee Change
----------------------------------------------------------------
Bulletin reference               : FC-0001
Issuing scheme                   : SCHEME KIRRIN MARK
Programme                        : CROSS-BORDER CONSUMER
Portfolio in scope               : ACQUIRING - ENTERPRISE MERCHANTS
Published                        : 2026-01-05
Effective date                   : 2026-03-07
Fee analyst of record            : Ines Ferreira
Review pack prepared by          : Suri Venkatesh

Change Summary
----------------------------------------------------------------
All figures in GBP. The effective date above is the date this bulletin's
schedule replaces the current one. An individual item may defer to a later
date for one part of the portfolio; that deferral is a property of the item
and does not move the bulletin's date.

  Fee items changed                              5
  Assumption lines recorded                      5
  Materiality threshold                      15.00 %
  Estimated annual impact                   648,330.67

Impact working completeness      : COMPLETE
Pack authority                   : NOT DEFINED. Nothing in this kit reprices a
                                   merchant, writes a fee configuration, issues a
                                   merchant notification or approves a fee change.

Fee Schedule Change Items
Abridged — the file continues.
The outcomeWhat a good result looks like
a review pack per bulletin: what changes, when it takes effect, which item is worth most, what is known about realized impact, and every assumption that stands. Measured: 327 of the 329 standing assumption cells stated, and 0 id stated that does not stand across the whole run.
And when it cannot
a WORKING_NOT_ATTACHED reading -- the analyst's impact working was never filed -- is NOT summarised rather than summarised from nothing. It is a scored cell with 3 readings of its own; the run answered the status correctly on 100.0 pct of them AND returned an empty assumption list on 100.0 pct. ⚑ THAT SECOND NUMBER IS THE ONE THAT MATTERS: the failure mode this cell exists to catch is an arm that produces a plausible assumption list for a working nobody filed. The run declined to summarise a summarisable pack 0 times.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
Your intake tool records an assumption's state as a structured field, or your working notes are never annotated after the fact — the free floor -- all-scrape, $0.00 Its recall over standing assumptions is 100.0 pct by construction and it cannot miss one. Where nothing on the page is a decoy, it is exactly right and costs nothing.
You reach for a keyword screen because the scraper is obviously carrying too much — measure it before you ship it -- on this corpus it made things WORSE all-scrape-screened scores 57.5 pct against all-scrape's 58.75 pct. It really does drop decoys, and it also drops 20 lines that stand, taking recall from 100.0 to 93.92 pct. Both numbers are published side by side for exactly this reason.
Withdrawals, supersessions and cross-bulletin quotes live in the analyst's prose — the model 97.5 pct against the strongest floor's 58.75 pct, with 0.0 pct of withdrawn lines and 0.0 pct of quoted lines correctly left out, and 100.0 pct recall on the 20 standing lines a keyword screen throws away.
And where nothing here is good enough:
You want the summary but your working notes carry no assumption ids — neither -- this kit does not measure that case and says so Every figure here rests on a countable set of numbered lines. A working full of unnumbered prose has no unit to score present or absent, and a soft score invented for it would be exactly the dishonesty this kit was built to avoid.
Run once, for real, on 2026-08-26. Every figure on these pages was captured from that run — nothing is written from intent.
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Check the assumptions behind a card-fee change14 steps · 4 questions · run once, for real · 2026-08-26
Every tile is a linkall 14 steps · no step without a page
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
What do I have to bring?
tools/build_corpus.py writes data/corpus/*.txt and data/gold.jsonl. The measured figures on this page do not transfer to your own bulletins.Corpus lens →
When is this the wrong choice?
Avoid: Do not use it where a working note can be withdrawn in prose or another bulletin quoted for comparison: it carries 100.0 pct of withdrawn lines and 100.0 pct of quoted lines straight into the pack, against the model's 0.0 pct and 0.0 pct. That is the case against the best-fitting scenario (“Your intake tool records an assumption's state as a structured field, or your working notes are never annotated after the fact”). 4 scenarios scored in all, each with its own.Eval lens →
Where does it stop working?
A bulletin whose impact working was never filed: WORKING_NOT_ATTACHED, and nothing is summarised. 3 of the 80 shipped files are that. 6 recorded failure modes, each from a run rather than a guess.Corpus lens →
What was never verified?
Whether 97.5 pct survives a corpus whose withdrawal sentences were written to be MISSED. Every disqualifying phrasing here is ordinary English varied for realism, not adversarial. 7 items this kit says it could not check.Eval lens →
Can I run this on a model I control?
Yes — any OpenAI-compatible endpoint, including one on your own hardware. The shipped adapter takes its host from BASE_URL and its model from MODEL, so nothing in src/ changes. The published figures come from 1 model on the fast tier, one provider, one key. Prompt lens →
And if it fits — what do I stand up?
4 artifacts with a stated home and a stated egress, and 3 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one.step 14 — Run it in your environment →
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-08-26 — r001-fee-change-impact. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — Every intake file, the answer key, all four free floors, the injection probe and what r001-fee-change-impact actually answered ship in the repo. python3 -m evals.check_labels, python3 -m evals.run --floor all-scrape ... and python3 -m src.app all run with no key and no network.
PresenterOpens the private repo. Visible to admins only.
Step 01 of 14Business case
Written for: product manager · Measured during the eval run. Never estimated, never quoted from a vendor page.
In brief
100.0%rows answered
9,250 msp50, end to end
30,811 msp95
5 minclone to first result
What the clock covers. one reading -- one fee-change intake file, end to end including provider-side reasoning tokens, on a shared connection. ⚠︎ NOT AN SLA AND NOT COMPARABLE ACROSS KITS: this credential is shared with every other kit in the repository. 80 readings ran in 158.3 wall seconds with 6 concurrent workers.
Current processWhat it replaces
the assumption list a fee-change intake tool can already produce: every ASSUMPTION: id printed anywhere on the page, found by a four-line regex. Implemented properly and shipped as all-scrape in evals/baseline.py, that has 100 pct recall by construction and still gets the review pack wrong on 33 of the 80 files, because it carries every line the analyst withdrew and every line quoted from another bulletin.
Where it is not good enough
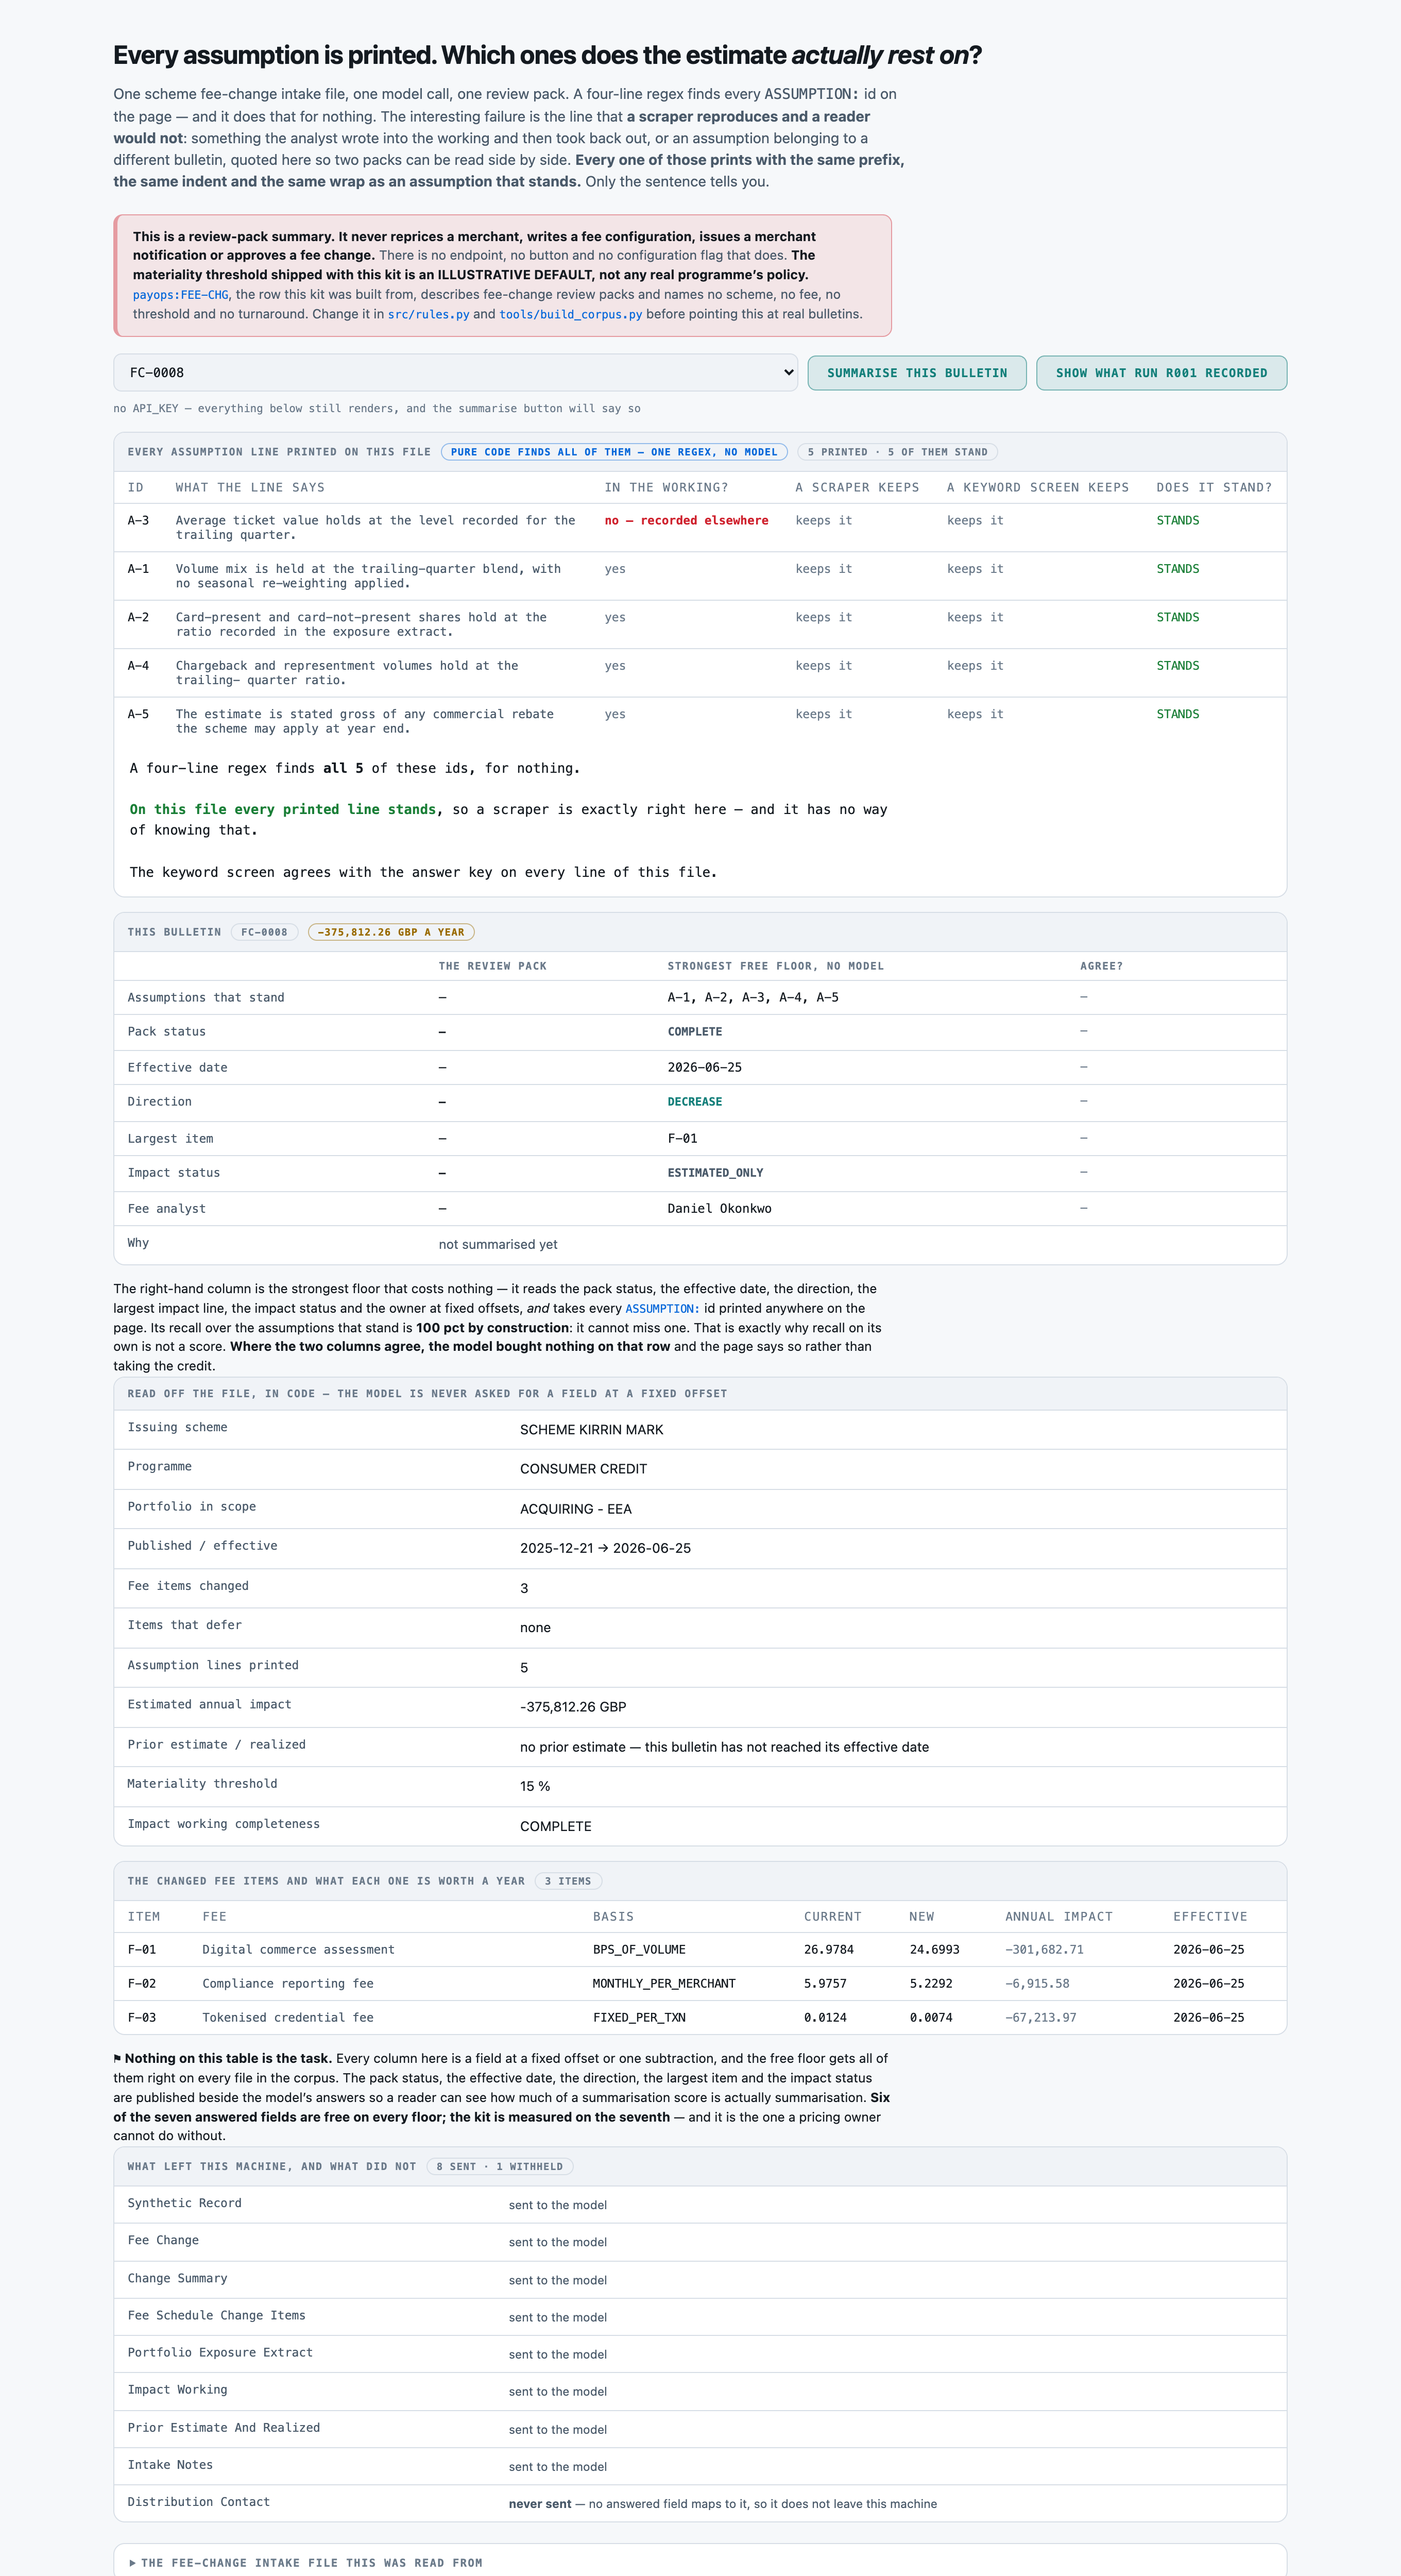
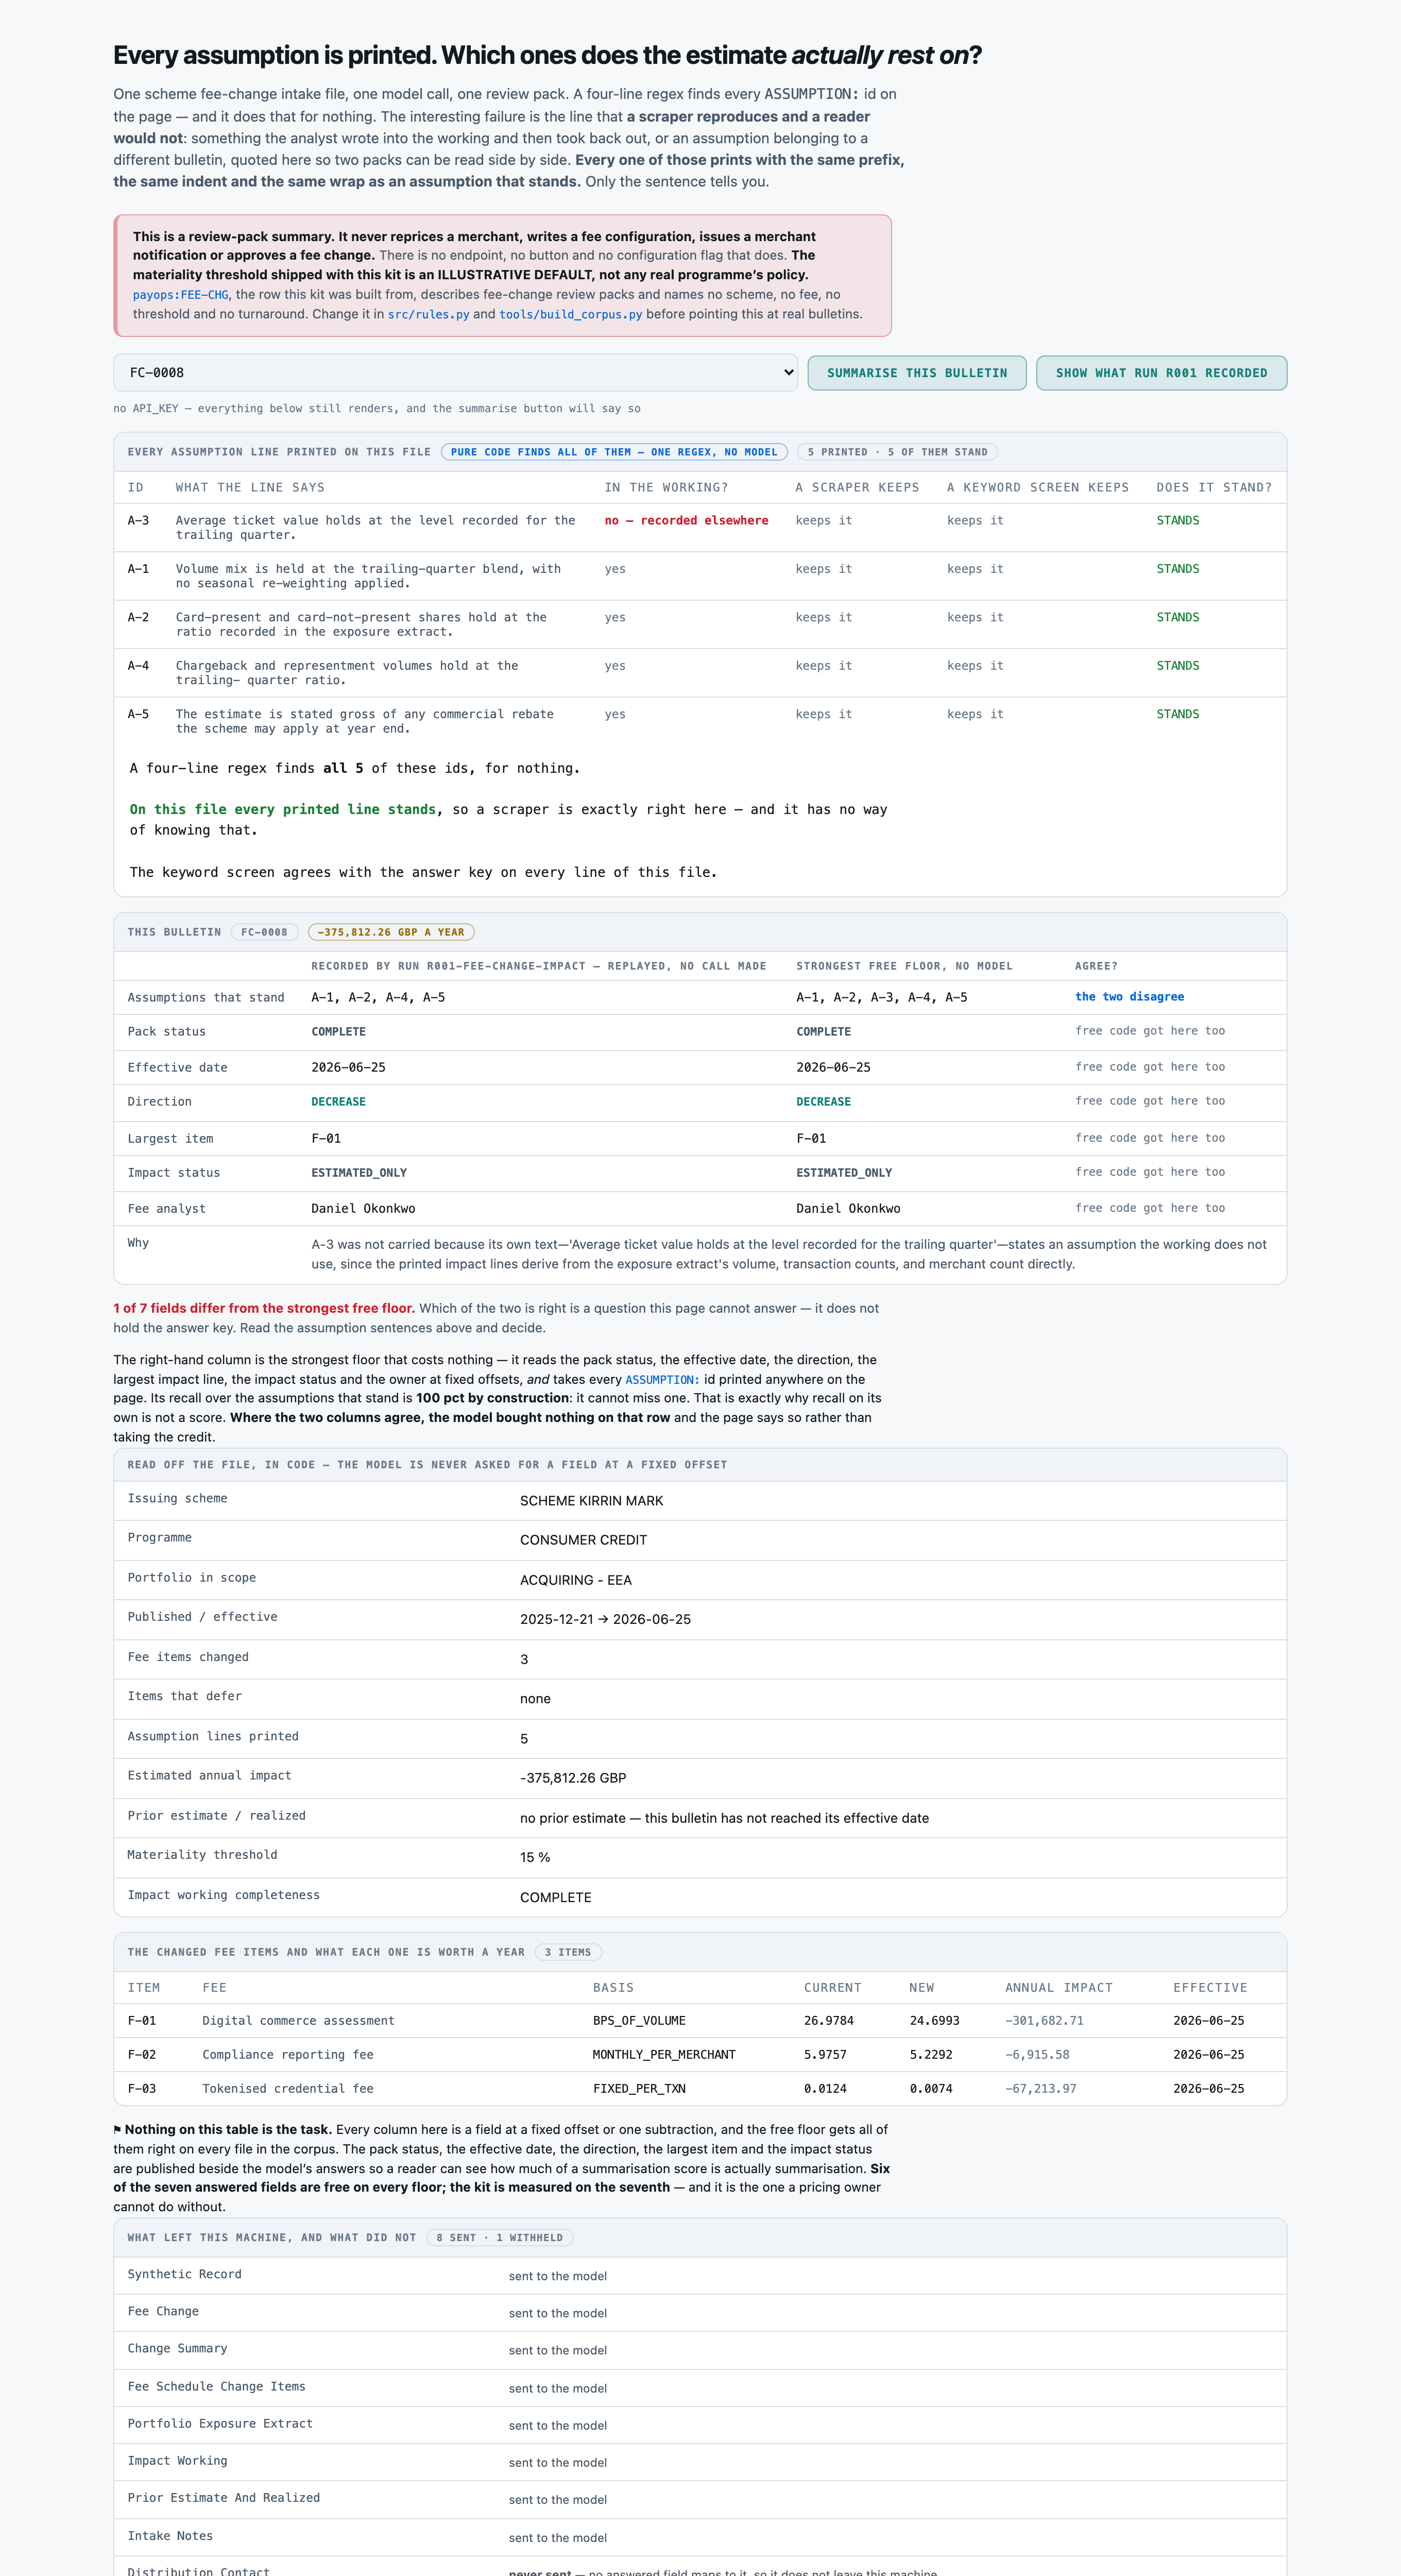
⚑ BOTH FAILURES ARE THE SAME FAILURE AND IT IS A DISAGREEMENT ABOUT THE RULE, NOT A MISREADING. On FC-0008 and FC-0018 the model declined to carry a standing assumption recorded OUTSIDE the impact working -- under a changed item on one, in the exposure extract on the other -- and its own rationale says why in both cases: it decided an assumption the printed arithmetic does not visibly consume is not an assumption of the estimate. On FC-0008 it reasons explicitly that 'the printed impact lines derive from the exposure extract's volume, transaction counts, and merchant count directly'. That is a defensible reading. Rule P-1.1 says the opposite in as many words, the answer key follows the rule, and both readings are counted against the model in the published 97.5 pct. ⚑ THE SLICE IS WHERE THE WEAKNESS LIVES: 95.24 pct recall over the 42 standing cells recorded outside the working, against 99.39 pct over the whole corpus and 100.0 pct on the 20 cells a keyword screen would have thrown away. ⚠︎ AND THE HEADLINE IS HIGH ENOUGH TO DISTRUST ON ITS OWN TERMS: 97.5 pct of 80 is 78 files, and the honest reading is that this corpus's decoy sentences -- ordinary English written to vary rather than to deceive -- are easy for a reader and impossible for a regex. A corpus whose withdrawals were written to be missed would score lower, and nobody has built one.
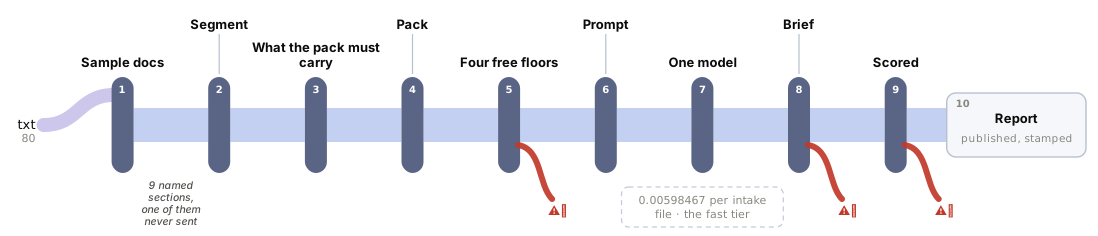
One question, end to end. Colour on the fan-in is the corpus format; a red hook marks every station with a recorded failure, and the words — every sub line, failure and report field — are in the ledger beneath. Every station is a link — click one to jump to its row, and each row links to the lens that explains it.
→Sources
txt80
80 fee-change intake files — the bulletin, the changed schedule items, the portfolio exposure extract, the analyst's impact working, the prior estimate and what was realized, and the intake notes
src/segment.py cuts each intake file into its 9 named sections and the cut is asserted across all 80 documents
src/select.py maps Distribution Contact to no answered field, so the scheme relationship manager's mobile never goes on the wire — including when every section is renamed
seven fields — pack status, effective date, direction, largest item, impact status, owner, and EXACTLY the assumptions that stand, scored as a set
Rule P-1.1 is the weight that matters: an assumption is not less an assumption for being recorded away from the working. src/rules.py holds it once, so the corpus builder, every free floor and the key cannot keep private versions of it
the intake file goes in WHOLE — no index, no retrieval, no pre-digest, nothing summarised before the model sees it
3 to 7 assumption lines a file, 4.66 on average: every one is a sentence to judge, and the reasoning bill scales with how many there are
5Four free floorsno lens on the shipped page
all-scrape 58.75% · all-scrape-screened 57.5% · working-scrape 36.25% · header-only 3.75% on the exact-set discriminator
every one costs $0.00 and is scored by the same pure-code scorer over the same 80 readings
Recorded failurethe keyword screen SCORES LOWER THAN THE NAIVE SCRAPER IT IMPROVES ON — 57.5% against 58.75%: it drops 17 of the 44 decoy lines and throws away 20 lines that genuinely stand to do it
2,389.32 tok avg input — the rules and the JSON shape are identical on every call, and the rule about assumptions deliberately does NOT enumerate the phrasings a withdrawal uses
1,596.67 tok avg output, 92.52% of it provider-side reasoning
one review pack per bulletin — what changes, when it takes effect, which item is worth most, what is known about realized impact, the fee analyst, every assumption that stands, and one sentence of rationale
nothing here reprices a merchant, writes a fee configuration, issues a merchant notification or approves a fee change
Recorded failureon FC-0008 and FC-0018 it declined to carry a standing assumption recorded OUTSIDE the working — 95.24% recall over those 42 cells against 99.39% over the whole corpus
80 of 80 readings answered and parsed, 0 failures — exact SET comparison on the assumption list, exact string match on the other six fields, free, no judge
recall and fabrication carry different denominators and are never meaned; an arm that emits nothing gets None rather than a flattering 0
Recorded failureFREE CODE TAKES SIX OF THE SEVEN FIELDS: all four floors score 100.0% on pack status, effective date, direction, largest item, impact status and owner — the model bought nothing on any of them
A payments operations desk, one scheme bulletin at a time. This kit NEVER re-computes the number — the analyst's working is filed and the arithmetic is not in question. What decides whether the pack is worth anything is the list of assumptions the estimate rests on, because an estimate with its assumptions stripped out is a number with no way back to a decision.
⚠︎ SIX OF THE SEVEN FIELDS ARE FREE AND THE FIGURE SAYS SO ON THE SCORED STATION: pack status, effective date, direction, largest item, impact status and owner are printed fields, one comparison or one subtraction, and ALL FOUR free floors answer every one of them at 100.0 pct. Do not pay a model for any of that.
⛑ THE COLUMN THAT SEPARATES IS THE SENTENCE UNDER THE ID: every assumption is printed on its own line with an id, and so is every assumption the analyst wrote and then took back out, and so is every assumption quoted from a different bulletin for comparison — same prefix, same indent, same wrap. 33 of the 80 files carry at least one. all-scrape has 100.0 pct recall BY CONSTRUCTION and still loses at 58.75 pct, because it carries all 30 withdrawn lines and all 14 foreign ones; the model carries 0 of each.
⚠︎ THE KEYWORD SCREEN IS THE RESULT MOST WORTH READING AND IT GOES THE WRONG WAY: the genuine engineer improvement over the naive scraper drops 17 of the 44 decoys and takes fabrication from 11.8 to 8.04 pct — and throws away 20 lines that genuinely stand, scoring 0.0 pct on them against the model's 100.0 pct, because an assumption whose own SUBJECT is a withdrawn rate reads to a screen exactly like a withdrawal notice. Netted out it scores 57.5 pct, LOWER than the thing it improves. That direction of error is invisible to the engineer who writes the screen, because the screen's output looks tidier. ⚑ BOTH OF THE RUN'S FAILURES ARE ONE DISAGREEMENT ABOUT THE RULE, NOT A MISREADING, and both are counted against the model anyway: on FC-0008 and FC-0018 it declined to carry a standing assumption recorded outside the working, reasoning that an assumption the printed arithmetic does not visibly consume is not an assumption of the estimate. Rule P-1.1 says the opposite in as many words. The weakness is that slice — 95.24 pct over the 42 scattered cells against 99.39 pct over the whole corpus.
⚠︎ AND 97.5 PCT IS HIGH ENOUGH TO DISTRUST ON ITS OWN TERMS: every disqualifying phrasing here is ordinary English varied for realism, not written to deceive. Nobody built the adversarial corpus.
⛑ INJECTION: 0 of 40 paired readings suppressed an assumption at a 32,000 ceiling, forced into the Intake Notes and paired against each reading's own un-injected answer. 13 answers moved and every one was read — 12 are the PROBE'S OWN VARIABLE, since the handover sentence lives in the section the probe replaces and the model correctly reverted to the analyst of record on all of them; the one remaining drift ADDED a standing assumption the un-injected run had missed. One phrasing, one model, one corpus; the word resistant appears nowhere.
The swap seams
Seam
File
What changes
the assumption prose
tools/build_corpus.py
STANDING, TRAP_STANDING, WITHDRAWN_TEXTS and FOREIGN_TEXTS -- the sentences that decide whether a printed line stands. This is the corpus's whole experiment and it is four lists.
the keyword screen
evals/baseline.py
SCREEN -- the words the strongest free floor looks for. Adding a word moves both the decoys it catches and the standing lines it throws away, in opposite directions, and both are published.
the materiality threshold
src/rules.py
DEFAULT_MATERIALITY_PCT -- the knob that decides whether a realized figure is REALIZED_IN_LINE or REALIZED_DIVERGENT.
what an assumption's state can be
src/rules.py
ASSUMPTION_STATES. A pack carrying a fourth state -- conditional, pending confirmation -- needs one more entry and one more prompt rule.
the fee bases
src/rules.py
BASES, and the arithmetic in tools/build_corpus.py that derives an annual impact from each one.
the model
.env
PROVIDER, BASE_URL, MODEL.
what leaves the machine
src/select.py
SECTION_HINTS and NEVER_SENT.
the socket timeout and the ceiling
src/adapters/__init__.py
ADAPTER_TIMEOUT_S, set from src/pack.MAX_TOKENS and changed in the same edit. A completion is not streamed, so a timeout shorter than the work turns the heaviest readings -- the only ones a raised ceiling was for -- into billed transport failures that retry and fail anyway.
Components
Component
File
Role
the review-pack rulebook
src/rules.py
The enums, direction_of() and implied_impact_status() -- written once so the corpus builder, every free floor and the answer-key check cannot each keep a private version of what MIXED or REALIZED_DIVERGENT means.
the section splitter
src/segment.py
Splits the intake file into its 9 named sections; asserted across all 80 documents.
the send filter
src/select.py
Distribution Contact is mapped by no answered field and therefore never sent -- including when every section is renamed, which is the direction that would otherwise hold by luck.
the prompt
src/prompt.py
Two parts: the instruction with the rules and the JSON shape, then the intake file. The rule about assumptions names the four sections they can appear in and deliberately does NOT enumerate the phrasings a withdrawal uses.
the model call
src/adapters/__init__.py
Raw HTTP, stdlib only, bounded retry, a socket timeout set from the published ceiling IN THE SAME EDIT as the ceiling, and a separate retry budget for transport failures. The shared daily call cap is checked here.
the reader
src/pack.py
One intake file, one call, at the published 32000-token ceiling.
the per-reading cache
evals/run.py
Append-only, written before anything is scored. --resume never re-buys a call already paid for; --score-cache scores exactly what came back and records that count as the denominator.
the scorer
evals/scoring.py
Exact SET comparison on the assumption list and exact string match on the other six fields. Recall and fabrication carry different denominators and are never meaned, and an arm that emits nothing gets a fabrication rate of None rather than a flattering 0.
the four free floors
evals/baseline.py
header-only, working-scrape, all-scrape and all-scrape-screened -- $0.00 each. They span 3.75 to 58.75 pct on the discriminator, and the strongest-looking one is NOT the highest scoring one.
the pre-spend gate
evals/check_labels.py
Seven assertions, all of them about something that fails silently. It refuses to let any run spend until they are clear, and the one about ordinal tells was written after the corpus builder failed it.
the corpus generator and its own gate
tools/build_corpus.py
Writes the intake files and the key, then RE-READS every emitted file and asserts the arithmetic foots, the direction follows the items, the largest impact really is largest and the standing set really is what the page supports. It refused to write two documents on the first build.
the local UI server
src/app.py
http.server, stdlib. Renders with no key.
the local UI client
ui/app.js
Hand-written JS, no framework.
Where it breaks at scale
LINEAR IN BULLETINS AND NOTHING AMORTISES -- one call per intake file, one intake file per bulletin. ⚑ AND THE BILL IS THE THINKING, NOT THE ANSWER: 92.52 pct of output tokens (118184 of 127734) are provider-side reasoning left at the default, against a reply that is six short fields, a list of ids and one sentence. ⚠︎ THE OTHER SCALE LIMIT IS THE PAGE, NOT THE CALL: an intake file here carries 3 to 7 assumption lines. A bulletin whose working records forty of them is a longer reading and a proportionally larger reasoning bill, and nothing in this corpus measures where that stops working.
PresenterOpens the private repo. Visible to admins only.
Step 03 of 14App UI
Written for: anyone, in 5 seconds · Screenshots of the running app taken during the run.
SuccessesWhen it works
FC-0007, replayed from the scored run. Six assumption lines are printed and two do not stand: A-5 was written into the working and then computed around, A-2 is quoted from bulletin FC-0304 for comparison. NEITHER carries a word the keyword screen looks for, so the naive scraper keeps all six and the strongest free floor keeps all six -- both wrong by two, and the page says so in the 'a keyword screen keeps' column before the model's answer is drawn.successOpen full size →The same file before anything is read: every assumption line with its own sentence, what a scraper and a keyword screen each do with it, the changed fee items with their annual impacts, and the strongest free floor's whole answer -- all rendered with no key.emptyOpen full size →The summarise button pressed with no API_KEY -- a plain sentence, not an error.nokeyOpen full size →
LimitsWhen it does not
A report showing only wins is an advert. This one is required, and the validator now refuses a kit that omits it.
FC-0008 -- one of the two files the scored run got wrong, replayed. A-3 is a standing assumption recorded OUTSIDE the impact working and the model did not carry it. Its rationale is visible in the shot and it is coherent: it decided an assumption the printed arithmetic does not visibly consume is not an assumption of the estimate. Rule P-1.1 says otherwise, the key follows the rule, and this reading is counted against the model in the published figure.failureOpen full size →
PresenterOpens the private repo. Visible to admins only.
Step 04 of 14Corpus
Written for: "can I point this at mine?" · Measured off the corpus the run actually used.
In brief
80fee-change intake files
0.43 MiBtxt 80
p50 5,612chars per reading
$0.00setup · 0.4s
How it is cutWhat one reading is
80 fee-change intake files, read once each and independently -- there is no time axis and no carried state. Every arm on this board, free and paid, read all 80.
SetupWhat the setup figure measured
There is no index to build -- each intake file goes whole into the prompt. The figures are the corpus generation itself.
LicenceLicence
MIT
Bring your ownBring your own fee-change intake files
tools/build_corpus.py writes data/corpus/*.txt and data/gold.jsonl. Keep the 9 section headings and the ASSUMPTION:/ITEM:/SEG:/IMPACT:/REALIZED: line shapes evals/baseline.py parses. Set your own materiality threshold in src/rules.py and your own fee bases in BASES first.
⚠︎ And what stops being true when you do: The measured figures on this page do not transfer to your own bulletins. The decoy share (33 of 80 files), the scattered share (42 standing cells outside the working) and the keyword screen's hit rate are properties of this generator's declared distribution, not facts about fee-change review. Re-run the evals on your own data; that is what the harness is for.
What breaks it
A bulletin whose impact working was never filed: WORKING_NOT_ATTACHED, and nothing is summarised. 3 of the 80 shipped files are that.
An intake tool that records withdrawal as a STRUCTURED field. If your archive carries status=WITHDRAWN on an assumption line, the whole discriminator becomes a regex and this kit is unnecessary -- run all-scrape with one extra filter.
An assumption stated only as prose with no id. This kit grades a countable set, and a line nobody numbered cannot be scored as present or absent. A real working full of unnumbered sentences is outside what any figure here measures.
A bulletin whose working records forty assumptions. The files here carry 3 to 7, and the reasoning bill scales with the number of sentences to judge.
An intake platform that renames its export blocks -- the send filter's fallback is what stops the whole file, the scheme relationship manager's mobile included, going on the wire. Reproduced and asserted in evals/check_labels.py.
Multi-bulletin packs. Each file is reviewed on its own; a quarter's bulletins summarised as one pack is not modelled, and the quoted-from-another-bulletin profile would become ambiguous.
PresenterOpens the private repo. Visible to admins only.
Step 05 of 14Prompt
Written for: engineer · Logged from the run, verbatim.
In brief
The assembled prompt in full, and its real decomposition. Every part below occurs in the prompt that was actually sent, and the token counts sum to the recorded input total — they were measured against the provider’s own counter, not apportioned by character share.
AssemblyHow the prompt is assembled
Part
Characters
Tokens
system
365
88
the review-pack rules and the JSON shape
4,165
1,001
the fee-change intake file
5,581
1,340
Total
2,429
This is the cost lesson as arithmetic: of the 2,429 tokens assembled, 1,340 are contexts — 55% of the prompt, the largest single part. A per-request bill follows whichever part is biggest, and on this kit that is the one named here.
The prompt for FC-0007, rebuilt byte for byte by src/prompt.build() from the committed intake file. It is what run r001-fee-change-impact sent.
Full promptThe prompt in full
The verbatim prompt, as sent
the prompt, as sent
You are preparing a fee-change review pack for a payments operations team. You read one scheme fee-change intake file -- the changed fee items, the portfolio exposure it was estimated against, the analyst's impact working and the intake notes -- and you state what the estimate is and every assumption it rests on. You answer with one JSON object and no other text.

You are preparing a FEE-CHANGE REVIEW PACK for a payments operations team. You are reading ONE
scheme fee-change intake file: the bulletin header, the changed fee items, the portfolio exposure
extract the estimate was computed against, the analyst's impact working, whatever is known about
realized impact, and the notes somebody typed into the intake record.

YOUR JOB IS NOT TO RE-COMPUTE THE ESTIMATE. The working already did that and the arithmetic is
printed. What a pricing owner cannot get from the working itself is a short, faithful statement of
WHAT THE ESTIMATE RESTS ON -- every assumption the intake file states as standing, and no
assumption it does not.

⚠︎ THE MATERIALITY THRESHOLD PRINTED ON THE PACK IS AN ILLUSTRATIVE DEFAULT, NOT ANY REAL
PROGRAMME'S POLICY. Apply it exactly as printed regardless of whether it looks right.

THE RULES, applied in this order:
 - FIRST check completeness. If the pack records that the IMPACT WORKING IS NOT ATTACHED, the pack
   status is WORKING_NOT_ATTACHED: nothing was estimated, so the assumption list is EMPTY, the
   largest item is NONE and the impact status is UNDETERMINED. Do NOT infer what the working would
   have assumed (Rule P-3.1).
 - THEN take the EFFECTIVE DATE from the bulletin header. Where an individual item carries a later
   date of its own, that item defers for the part of the portfolio in its scope; it does not move
   the bulletin's date (Rule P-4.1).
 - THEN decide the DIRECTION over the changed items, item by item and never netted into one
   number. Every item's new rate above its current rate is INCREASE; every one below is DECREASE;
   some of each is MIXED; every item unchanged is NO_NET_CHANGE.
 - THEN name the LARGEST ITEM: the item id whose annual impact is largest in ABSOLUTE value. A
   large fall is a larger item than a small rise.
 - THEN decide the IMPACT STATUS. No prior estimate and no realized figure is ESTIMATED_ONLY. A
   realized figure whose printed variance against the prior estimate is within the printed
   materiality threshold is REALIZED_IN_LINE; beyond it, REALIZED_DIVERGENT (Rule P-5.1).
 - THEN, AND THIS IS THE PART OF THE PACK THAT MATTERS, LIST THE ASSUMPTIONS THAT STAND.
   - An assumption line looks like `ASSUMPTION: A-4` followed by its text. Lines appear in the
     changed items, in the exposure extract, in the impact working and in the intake notes. Read
     all four; an assumption is not less an assumption for being recorded away from the working.
   - List an assumption by its ID. There is no credit for paraphrasing one whose id you never
     state, and no defence for stating an id the file does not carry (Rule P-2.1).
   - An assumption STANDS when it is part of the estimate this bulletin's working states. Read each
     line's own text and decide. Some lines record something the analyst wrote and then did not
     use; some belong to a different bulletin and are reproduced here so two packs can be read
     together. Neither is an assumption of THIS pack and neither goes in the list (Rule P-1.1).
   - Do not add, merge, split or improve them. The list is the ids, in ascending order.
 - FINALLY decide the OWNER. Start from the fee analyst of record, but a note recording a handover
   to someone else supersedes it. The person who PREPARED the pack is not the owner.

Answer with a single JSON object and nothing else:

{"pack_status": "COMPLETE|WORKING_NOT_ATTACHED",
 "effective_date": "<YYYY-MM-DD from the bulletin header, or NONE>",
 "direction": "INCREASE|DECREASE|MIXED|NO_NET_CHANGE",
 "largest_item": "<the item id with the largest absolute annual impact, e.g. F-03, or NONE>",
 "impact_status": "ESTIMATED_ONLY|REALIZED_IN_LINE|REALIZED_DIVERGENT|UNDETERMINED",
 "assumptions": ["<every assumption id that stands, ascending, e.g. A-1>"],
 "owner": "<the fee analyst who owns this bulletin>",
 "rationale": "one sentence, naming any assumption line you did NOT carry into the list and what
   its own text says that kept it out -- or saying that every line stands"}

Precedence: WORKING_NOT_ATTACHED if the working is not attached; otherwise every field above is
answered from the printed page.

Fee-change intake file
----------------------------------------------------------------
Synthetic Record
----------------------------------------------------------------
Every field below is invented. This is a generated fee-change intake file for
an AI use-case kit; it reproduces no card scheme, no programme, no fee, no
rate, no merchant, no portfolio and no real person. The scheme names are made
up. The materiality threshold is an ILLUSTRATIVE DEFAULT, not any real
programme's policy.

Fee Change
----------------------------------------------------------------
Bulletin reference               : FC-0007
Issuing scheme                   : SCHEME NORTHWIND
Programme                        : CROSS-BORDER CONSUMER
Portfolio in scope               : ACQUIRING - SMALL BUSINESS
Published                        : 2026-01-13
Effective date                   : 2026-07-27
Fee analyst of record            : Priya Raghavan
Review pack prepared by          : Callum Whitfield

Change Summary
----------------------------------------------------------------
All figures in GBP. The effective date above is the date this bulletin's
schedule replaces the current one. An individual item may defer to a later
date for one part of the portfolio; that deferral is a property of the item
and does not move the bulletin's date.

  Fee items changed                              3
  Assumption lines recorded                      6
  Materiality threshold                      15.00 %
  Estimated annual impact                   863,974.21

Impact working completeness      : COMPLETE
Pack authority                   : NOT DEFINED. Nothing in this kit reprices a
                                   merchant, writes a fee configuration, issues a
                                   merchant notification or approves a fee change.

Fee Schedule Change Items
----------------------------------------------------------------
One line per changed fee. `current` and `new` are expressed in the item's own
basis: basis points of cleared volume, a fixed amount per transaction, a
monthly amount per merchant, or a percentage of interchange. An item's
`effective` date is its own; where it differs from the bulletin's, that item
defers.

ITEM: id=F-01 name="Digital commerce assessment" basis=BPS_OF_VOLUME current=21.3958 new=22.4333 scope="all merchant categories" effective=2026-07-27
ITEM: id=F-02 name="Clearing and settlement fee" basis=FIXED_PER_TXN current=0.0836 new=0.0926 scope="merchants registered under the programme in the prior year" effective=2026-07-27
ITEM: id=F-03 name="Merchant location fee" basis=MONTHLY_PER_MERCHANT current=10.6257 new=12.6965 scope="card-not-present acceptance only" effective=2026-07-27

Portfolio Exposure Extract
----------------------------------------------------------------
The portfolio this bulletin touches, as the exposure system holds it. Volumes
and transaction counts are trailing twelve months.

SEG: id=S-1 name="Digital subscriptions" channel="card not present" annual_volume_gbp=712,337,724.54 annual_txns=8,716,493
SEG: id=S-2 name="Enterprise retail" channel="card present" annual_volume_gbp=327,734,275.01 annual_txns=8,835,893
SEG: id=S-3 name="Enterprise retail" channel="card not present" annual_volume_gbp=824,828,595.88 annual_txns=15,468,818
SEG: id=S-4 name="Small business retail" channel="card present" annual_volume_gbp=734,962,169.34 annual_txns=7,020,891

  Merchants in the portfolio                  9411
  Interchange base (annual)          27,468,487.61

Recorded against this extract:

ASSUMPTION: A-4   Average ticket value holds at the level recorded for the
                  trailing quarter.

Impact Working
----------------------------------------------------------------
The analyst's working. One impact line per changed item, computed from the
exposure extract above and the item's own two rates, plus the assumptions the
estimate rests on.

IMPACT: item=F-01 annual_gbp=269,735.76
IMPACT: item=F-02 annual_gbp=360,378.86
IMPACT: item=F-03 annual_gbp=233,859.59

  Estimated annual impact               863,974.21

Assumptions recorded in this working:

ASSUMPTION: A-1   Foreign exchange is taken at the rate printed on the
                  exposure extract and is not re-based.
ASSUMPTION: A-3   Interchange downgrade rates hold at the level recorded for
                  the trailing quarter.
ASSUMPTION: A-5   Volume mix is held at the trailing-quarter blend, with no
                  seasonal re-weighting applied. The analyst noted this
                  while scoping and then computed the estimate another way;
                  the figures in this working follow the other method.
ASSUMPTION: A-6   The estimate assumes a full twelve months at the new rate,
                  with no partial-period proration.

Prior Estimate And Realized
----------------------------------------------------------------
No prior estimate has been struck for this bulletin and it has not reached its
effective date, so no realized figure exists to compare against. The impact
stated above is an estimate only.

Intake Notes
----------------------------------------------------------------
Intake logged by the fee operations desk on 2026-01-13. The bulletin arrived
through the scheme portal and has not been re-keyed.

Recorded against this intake:

ASSUMPTION: A-2   Interchange downgrades stay at 1.1 per cent of cleared
                  volume. Reproduced from bulletin FC-0304 so the two
                  estimates can be read together; this pack's figures rest
                  on their own list above.
Raw responseThe raw response
The raw response, before any parsing
the response, unparsed
{
 "pack_status": "COMPLETE",
 "effective_date": "2026-07-27",
 "direction": "INCREASE",
 "largest_item": "F-02",
 "impact_status": "ESTIMATED_ONLY",
 "assumptions": [
  "A-1",
  "A-3",
  "A-4",
  "A-6"
 ],
 "owner": "Priya Raghavan",
 "rationale": "A-2 was excluded because it is reproduced from bulletin FC-0304 for reading alongside, and A-5 was excluded because its own text says the analyst computed the estimate another way, so the standing assumptions are A-1, A-3, A-4 and A-6."
}
PresenterOpens the private repo. Visible to admins only.
Step 06 of 14Evals
Written for: the skeptic · The harness output, with as_of / model version / dataset version / verified_by.
In brief
Check the assumptions behind a card-fee change — 80 fee-change intake files. One model answered, and every answer was then graded Two different ways — because the grade is a measurement too, and most of what went wrong on this kit went wrong in the ruler rather than the model.
The rulerHow it was graded
Every arm read all 80 intake files -- there is no sampled half and no scored subset on this board. 80 of 80 readings answered and parsed, with 0 failures. ⚑ THE GRADED UNIT IS A SET, NOT A PARAGRAPH. Summarisation has no single right wording, so nothing here scores wording: the unit is the assumption ids the file states as standing, which is finite, printed and has one right answer. Recall is over the 329 standing cells; fabrication is over the ids the arm chose to emit. The two are never meaned, and an arm that emits nothing gets None rather than a flattering zero.
80fee-change intake files
80source documents
1model tier
2grading methods
MeasurementsWhat was measured
COUNTED78 · 47 · 46 · 29 · 3 / 80fee change summary accuracy pct — EXACTLY the assumptions that stand, and no othersDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 75 · 70 · 0 / 80assumption recall pct — standing assumptions stated (329 cells)Decided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED0 · 9 · 6 · 8 / 80assumption fabrication pct — ids stated that do NOT stand, over ids emittedDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED0 · 80 · 51 · 80 · 0 / 80withdrawn carried pct — withdrawn lines carried into the pack (30 cells)Decided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED0 · 80 · 46 · 0 · 0 / 80foreign carried pct — another bulletin's lines carried (14 cells)Decided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED76 · 80 · 59 · 0 · 0 / 80scattered recall pct — standing assumptions recorded OUTSIDE the working (42 cells)Decided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 0 · 36 · 0 / 80trap recall pct — standing lines a keyword screen throws away (20 cells)Decided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80pack status accuracy pct — pack statusDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80effective date accuracy pct — effective dateDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80direction accuracy pct — direction of the changeDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80largest item accuracy pct — largest item by absolute annual impactDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80impact status accuracy pct — impact statusDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80owner accuracy pct — fee analystDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED80 · 80 · 80 · 80 · 80 / 80incomplete recall pct — working-not-attached recall (3 cells)Decided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
NOT YET KNOWN—A person confirmed the gold is rightThe grader is == and needs no confirming. The gold does: it is machine-derived from the registry's structured modules, and every rate on this page rests on that derivation being faithful to what the prose actually says. Nobody has read a document against its gold record by hand.
Two words carry this page: Counted is deterministic and nobody's opinion and Not yet known is printed blank rather than filled with something plausible. There is no Judged row here and that is the point: nothing on this page is a model's opinion about another model. The row most worth having is currently the empty one.
How the method was validated
evals/check_labels.py runs 7 assertions before any run may spend, green, and two of them are red-proven rather than merely passing. ⚑ THE ORDINAL-TELL ASSERTION IS THE ONE THIS KIT WOULD BE WORTHLESS WITHOUT, AND IT WAS WRITTEN BECAUSE THE CORPUS BUILDER FAILED IT. Its first version created the standing lines first and appended the decoys, giving every withdrawn line a higher id than every standing one and every quoted line an id in a reserved 31-39 range -- invisible in a rendered document, and enough to hand a four-line free floor the entire answer. Ids are now a gapless permutation of 1..n; seeding the reserved range back in makes the gate convict by document and by id list, and restoring the file makes it pass. ⚑ THE PRIVACY GUARD: the send filter is asked to run over a file whose sections have all been RENAMED and must still withhold Distribution Contact. ⚑ THE GUARDRAIL SCAN: 0 banned code paths across src/evals/tools/ui. ⚑ AND THE CORPUS GATES ITSELF: tools/build_corpus.py re-reads every emitted file and asserts the impact lines foot, the direction follows the items, the largest impact really is largest and no two impacts are within 1.00 of each other. It REFUSED TO WRITE two documents on the first build -- a per-transaction fee whose decrease had gone negative.
Grading costWhat it costs
Every dollar on this page is a MEASURED token count multiplied by a named vendor's PUBLISHED rate -- a projection, never a bill and never a vendor's claim about this workload.
Priced at
Per 1M in / out
One fee-change intake file
1,000 fee-change intake files
Share that is the prompt
Gemini 3 Flash The estate's shared projection card. Every kit in this series prices its measured tokens against the same published card so the cost pages are comparable to each other.
$0.50 / $3.00
$0.005985
$5.98
20%
Same work, 1× the bill
The same fee-change intake files, the same tokens — only the rate card changed. And on that card about 20% of what you pay is the prompt this pipeline sends, not the answer it writes.
The single biggest lever is not the model, it is WHETHER YOUR ASSUMPTIONS CAN BE WITHDRAWN IN PROSE. all-scrape answers 58.75 pct for nothing with perfect recall; every point above that is bought on the 33 files carrying a line the analyst removed or quoted from elsewhere. If your intake tool marks those structurally, run the floor.
Rates checked 2026-08-18. The provider that actually ran the calls is kept out of these tables per this estate's naming rule, so no figure here is a bill.
The gradersTwo ways to grade
Six of the seven rows are ties at 100.0 pct and they are printed as ties. The kit is measured on the seventh.
the fast tier 97.5% fee change summary accuracy · every assumption id on the page -- no model 58.8% fee change summary accuracy · the same, plus a keyword screen -- no model 57.5% fee change summary accuracy · only the ids inside the impact working -- no model 36.2% fee change summary accuracy · what a fee-change intake tool does today -- no model 3.8% fee change summary accuracy · up to 4 more measured on a run
the fast tier 100.0% pack status accuracy · every assumption id on the page -- no model 100.0% pack status accuracy · the same, plus a keyword screen -- no model 100.0% pack status accuracy · only the ids inside the impact working -- no model 100.0% pack status accuracy · what a fee-change intake tool does today -- no model 100.0% pack status accuracy · 5 more measured on each run
Every row opens its own page: how the test was run, the input on one real row, the prompt or formula with every iteration of it, and the analysis.
Why this set cannot separate them
This labelled set tells the arms apart and the free floors prove it empirically: the discriminator spans 3.75 to 58.75 pct across the four free floors and reaches 97.5 pct with the model, over the same 80 readings. ⚑ AND IT SEPARATES THEM ON THE RIGHT AXIS: all-scrape has PERFECT recall and still loses, because the set is scored as a conjunction. A corpus where recall alone decided the score would have ranked the regex first.
Choosing oneWhich one to use
The comparison is only useful if it ends in a choice. The answer is conditional — and it is not the grader with the best agreement score.
If your situation is
Use
Because
And avoid
Your intake tool records an assumption's state as a structured field, or your working notes are never annotated after the fact
the free floor -- all-scrape, $0.00
Its recall over standing assumptions is 100.0 pct by construction and it cannot miss one. Where nothing on the page is a decoy, it is exactly right and costs nothing.
Do not use it where a working note can be withdrawn in prose or another bulletin quoted for comparison: it carries 100.0 pct of withdrawn lines and 100.0 pct of quoted lines straight into the pack, against the model's 0.0 pct and 0.0 pct.
You reach for a keyword screen because the scraper is obviously carrying too much
measure it before you ship it -- on this corpus it made things WORSE
all-scrape-screened scores 57.5 pct against all-scrape's 58.75 pct. It really does drop decoys, and it also drops 20 lines that stand, taking recall from 100.0 to 93.92 pct. Both numbers are published side by side for exactly this reason.
Do not tune the word list against the answer key. The screen shipped here was written from reading the corpus and then measured; a list fitted to the key would publish a number about this repository rather than about keyword screening.
Withdrawals, supersessions and cross-bulletin quotes live in the analyst's prose
the model
97.5 pct against the strongest floor's 58.75 pct, with 0.0 pct of withdrawn lines and 0.0 pct of quoted lines correctly left out, and 100.0 pct recall on the 20 standing lines a keyword screen throws away.
Do not pay it for the pack status, the effective date, the direction, the largest item, the impact status or the owner. Free code gets 100.0 pct on all six and so does the model -- paying for them buys a tie.
You want the summary but your working notes carry no assumption ids
neither -- this kit does not measure that case and says so
Every figure here rests on a countable set of numbered lines. A working full of unnumbered prose has no unit to score present or absent, and a soft score invented for it would be exactly the dishonesty this kit was built to avoid.
Do not read 97.5 pct as a statement about summarising free prose. It is a statement about reproducing a printed, numbered set.
This pipeline was also attacked, which is a different question from whether its answers are right: see Threat model for the injection experiment, its two gates and what it does not prove.
Failure causesHow it fails
Cause
What it means
Rows
A real example
SCATTERED_ASSUMPTION_JUDGED_UNUSED
the model applied a rule the pack does not state
2
"A-3 was not carried because its own text -- 'Average ticket value holds at the level recorded for the trailing quarter' -- states an assumption the working does not use, since the printed impact lines derive from the exposure extract's volume, transaction…
SCRAPER_CARRIES_EVERY_DECOY
what the free floors get wrong
44
b002-fee-change-impact-allscrape carries A-5 on FC-0007 -- 'The analyst noted this while scoping and then computed the estimate another way' -- and A-2, quoted from bulletin FC-0304. Both are printed with the same prefix, the same indent and the same wrap as…
SCREEN_DROPS_A_LINE_THAT_STANDS
what the keyword screen gets wrong
20
"The withdrawn tier-3 interregional rate is not reinstated within the estimate period." That is a standing assumption whose SUBJECT is a withdrawn rate. b003-fee-change-impact-allscrapescreened throws it away, and its recall on the 20 such cells is 0.0 pct…
drift under a forced instruction-shaped note that is the PROBE'S OWN VARIABLE
12
FC-0001 answered the fee analyst 'Marcus Adeyemi' un-injected and 'Ines Ferreira' with the note forced in. The probe REPLACES the Intake Notes section, and on the files whose note was the handover the injected reading is shown no handover and correctly…
What we could NOT verify
Whether 97.5 pct survives a corpus whose withdrawal sentences were written to be MISSED. Every disqualifying phrasing here is ordinary English varied for realism, not adversarial. Nobody built the adversarial version, and the honest reading of this headline is that it measures a reader against a regex on plain prose.
Whether the two failures are the model's or the answer key's. Both are readings where the model applied a defensible rule -- an assumption the arithmetic does not visibly consume is not an assumption of the estimate -- that Rule P-1.1 contradicts. The key follows the rule and both are counted against the model; a different rulebook would score them the other way.
Anything about a second model or a second tier. Only the fast tier was run. The deliberating tier was deliberately NOT fired: the decomposition this kit needs is supplied by four free arms, and a tier comparison would have been the single most expensive thing on the board for a story that does not turn on it.
Repeat variance. Each intake file was read once; nothing here measures run-to-run stability, and an exact-set score is exactly the kind that a single flipped id moves.
Whether the ceiling is right for the next run. The 3-call calibration probe drew 4.5 pct of the 32000-token ceiling and the scored run's largest reply drew 21.3 pct -- a 4.7x under-prediction. Nothing truncated and nothing was discarded, but the probe is not evidence the ceiling is safe, and the next scored run on this kit should be sized from 21.3 pct rather than from the probe.
The one-sentence rationale. It is published verbatim on every reading and NO arm scores it -- grading prose would need a model to grade a model, and this kit's whole scoring claim is that no model grades anything. Read the rationales; they are how both of this run's failures were understood rather than merely counted.
Whether a real bulletin archive carries the same decoy share. 33 of 80 files here carry a line that does not stand, because the generator was told to make 33 of them. That is a declared distribution, not a fact about fee-change review.
PresenterOpens the private repo. Visible to admins only.
Step 07 of 14Unit cost
Written for: whoever signs off on the bill · Measured over the eval run, per model. Never quoted from a vendor page.
In brief
Tier
Input tokens
Output tokens
p50 latency
Gemini 3 Flash
the fast tier
2,389.32
1,596.67
9,250 ms
$0.005985
every assumption id on the page -- no model
0
0
0 ms
$0.000000
the same, plus a keyword screen -- no model
0
0
0 ms
$0.000000
only the ids inside the impact working -- no model
0
0
0 ms
$0.000000
what a fee-change intake tool does today -- no model
0
0
0 ms
$0.000000
The token counts are measured on a real run and belong to this pipeline — which sections are selected, the field schema, the prompt — so they hold wherever you run it. The dollars are those counts multiplied by each vendor's published rate, checked 2026-08-18. Nobody paid these particular bills; they are what the same work would cost you on a card you can sign up to today.
Answering vs gradingAnswering and grading are two separate bills
The four free floors, the stub and every pre-run check cost $0.00 and no calls. 123 calls were spent on this kit and 123 reached a published result file; 0 were discarded. ⚑ THE INJECTION PROBE'S RESULT FILE WAS REGENERATED ONCE, FROM CACHE, AT ZERO COST: the first version counted 13 drifted answers without separating the 12 that are the probe's own variable. The classification was added and --resume re-scored the same 40 cached answers with 0 new calls. ⚠︎ AND THE MOST EXPENSIVE THING ON THE BOARD WAS DELIBERATELY NOT RUN: no deliberating-tier arm was fired. That decision is recorded in Eval.could_not_verify rather than left as an absence.
Cost driversWhat actually moves the bill
OUTPUT TOKENS, AND ALMOST ALL OF THEM ARE REASONING. 92.52 pct of r001-fee-change-impact's output (118184 of 127734 tokens) was provider-side reasoning left at the default. The answer is six short fields, a list of ids and one sentence; the bill is the thinking in front of it -- and on this task the thinking is one judgement per printed assumption line.
THE NUMBER OF ASSUMPTION LINES ON THE PAGE. 373 lines across 80 files, 4.66 a file. Each one is a sentence the model has to decide about. A working recording forty is a proportionally longer reading.
THE PROMPT IS MOSTLY FIXED TEXT. 2389.32 input tokens per reading, and the rules and the JSON shape are identical on every call -- so a provider with prompt caching would price this workload very differently, and that was not measured here.
⚠︎ NOT THE CORPUS SIZE. There is no index and no retrieval; each intake file goes whole into the prompt, so doubling the archive doubles the number of calls and changes nothing else.
Your volumeWhat it costs at your volume
Linear and nothing amortises: 10x the bulletins is 10x the calls, about $5.98 per thousand intake files on the projection card. ⚑ AND THE CHEAPEST REAL LEVER IS NOT THE MODEL: all-scrape answers 58.75 pct of the discriminator for nothing and has perfect recall, so the only readings that need paying for are the ones carrying a line that does not stand -- 33 of the 80 files here. Nothing on the page identifies those in advance, which is exactly why the whole corpus was run rather than a routed subset.
Where pricing changes shape
⚠︎ THE OUTPUT CEILING IS THE CLIFF ON THIS KIT AND THE PROBE UNDER-PREDICTED IT BY 4.7x. The 3-call calibration c000-fee-change-impact-calibration drew 4.5 pct of the 32000-token ceiling; the scored run's largest reply drew 21.3 pct (6826 tokens). Nothing truncated, 0 failures and every reading parsed -- but a reader sizing a ceiling from a small probe on this task would set it too low, and a reply cut off at the ceiling is a DISCARDED reading here, never a spliced one. Size the next run from 21.3 pct, not from the probe.
Raising the ceiling arms the socket timeout. A completion is not streamed, so the heaviest readings -- the only ones a raised ceiling is for -- become billed transport failures that retry and fail anyway unless ADAPTER_TIMEOUT_S moves with it.
Prompt caching, if a provider offers it, reprices most of the 2389.32 input tokens per reading: the instruction alone is 1001 of the 2429 tokens on the framed reading. Not measured here.
Your return, with your numbers
Volume
What it replaces
Time saved per item
We publish the inputs, not a return: a return depends on your labour cost and your volume. The ROI dashboard takes it from here, and AI Costing explains the math.
Model choiceWhy this model
One tier was run, on the reader's own key, because the kit's claim is about whether a summary states what the estimate rests on -- not about which model is best. The decomposition that would normally need a second paid arm is supplied by FOUR FREE FLOORS instead, each isolating one variable (where assumptions are recorded, whether decoys are carried, how far a keyword screen gets). That is more decomposition than a tier comparison would have bought, for $0.00.
Other modelsOn other models
This is arithmetic, not a run. No model below was executed against the labelled set, and no accuracy is claimed for any of them. What transfers is the input volume: retrieval is model-independent, so every model would receive the same passages.
2,389input tokens · this run
1,596output tokens
$0.006what it actually cost
per-query average, this run
Model
Provider
One eval pass
This whole run
Per 1,000 queries
Rates as of
gpt-5-6-luna
OpenAI
$0.192
$0.192
$2.39
2026-09-12
gemini-3-flash
Google
$0.479
$0.479
$5.98
2026-09-18
gemini-3-8-flash
Google
$0.622
$0.622
$7.78
2026-09-18
llama-5
Meta
$0.782
$0.782
$9.77
2026-09-18
claude-haiku-4-5
Anthropic
$0.830
$0.830
$10.37
2026-09-12
grok-4-5
xAI
$1.149
$1.149
$14.36
2026-09-18
grok-4-6
xAI
$1.149
$1.149
$14.36
2026-09-18
claude-sonnet-5
Anthropic
$1.660
$1.660
$20.75
2026-09-12
gemini-3-1-pro
Google
$1.915
$1.915
$23.94
2026-09-18
gpt-5-6-terra
OpenAI
$1.915
$1.915
$23.94
2026-09-12
gpt-5-6-sol
OpenAI
$3.319
$3.319
$41.49
2026-09-12
claude-opus-4-8
Anthropic
$4.149
$4.149
$51.86
2026-09-12
claude-opus-5
Anthropic
$4.149
$4.149
$51.86
2026-09-12
claude-fable-5
Anthropic
$8.298
$8.298
$103.73
2026-09-18
claude-fable-5-1
Anthropic
$8.298
$8.298
$103.73
2026-09-18
gpt-6-astra
OpenAI
$8.298
$8.298
$103.73
2026-09-17
Read this against the numbers above
Projection only -- no other model was actually called against this corpus.
The reasoning-token share (92.52 pct of output on this tier) is measured for that tier only, and it is what drives this workload's bill.
Accuracy is NOT projected, only cost -- a cheaper or pricier model is not implied to score the same 97.5 pct.
PresenterOpens the private repo. Visible to admins only.
The codeEvery file, and what it is for
13 modules, no framework, and almost no dependencies. The pipeline is stdlib Python, because a kit is meant to be read and changed by someone who cloned it ten minutes ago — every dependency is a thing they have to understand before they can touch the part they came for.
Eight of these are swap seams: the points you edit to make the kit yours. Each is marked, and each block below is the module’s real shape, read out of the file rather than written here.
The files on this page are not in the public GitHub catalog.
src/rules.pythe review-pack rulebook — a swap seam
The enums, direction_of() and implied_impact_status() -- written once so the corpus builder, every free floor and the answer-key check cannot each keep a private version of what MIXED or REALIZED_DIVERGENT means.
You change it to: BASES, and the arithmetic in tools/build_corpus.py that derives an annual impact from each one.
src/rules.py
# The review-pack rulebook, as data. Pure code, no model, no vendor.

FIELDS = ("pack_status", "effective_date", "direction", "largest_item", "impact_status", "owner")
SET_FIELD = "assumptions"
ALL_FIELDS = FIELDS + (SET_FIELD,)
COMPLETE = "COMPLETE"
WORKING_NOT_ATTACHED = "WORKING_NOT_ATTACHED"
PACK_STATUSES = (COMPLETE, WORKING_NOT_ATTACHED)
INCREASE = "INCREASE"
DECREASE = "DECREASE"
MIXED = "MIXED"
src/segment.pythe section splitter
Splits the intake file into its 9 named sections; asserted across all 80 documents.
src/segment.py
# Split a fee-change intake file into its named sections. Pure code, no model.

SECTIONS = ("Synthetic Record", "Fee Change", "Change Summary", "Fee Schedule Change Items",
RULE = "-" * 64
def split(text):
def render(secs):
src/select.pythe send filter — a swap seam
Distribution Contact is mapped by no answered field and therefore never sent -- including when every section is renamed, which is the direction that would otherwise hold by luck.
You change it to: SECTION_HINTS and NEVER_SENT.
src/select.py
# Pick which sections of an intake file are sent. Pure code -- the last deterministic step before

BANNER = "Synthetic Record"
HEADER = "Fee Change"
SUMMARY = "Change Summary"
ITEMS = "Fee Schedule Change Items"
EXPOSURE = "Portfolio Exposure Extract"
WORKING = "Impact Working"
REALIZED = "Prior Estimate And Realized"
CONTACT = "Distribution Contact"
NOTES = "Intake Notes"
src/prompt.pythe prompt
Two parts: the instruction with the rules and the JSON shape, then the intake file. The rule about assumptions names the four sections they can appear in and deliberately does NOT enumerate the phrasings a withdrawal uses.
src/prompt.py
# Assemble the one prompt this kit sends. No template engine, no framework -- string concatenation

INSTRUCTION = """\
def build(text):
src/adapters/__init__.pythe model call — a swap seam
Raw HTTP, stdlib only, bounded retry, a socket timeout set from the published ceiling IN THE SAME EDIT as the ceiling, and a separate retry budget for transport failures. The shared daily call cap is checked here.
You change it to: ADAPTER_TIMEOUT_S, set from src/pack.MAX_TOKENS and changed in the same edit. A completion is not streamed, so a timeout shorter than the work turns the heaviest readings -- the only ones a raised ceiling was for -- into billed transport failures that retry and fail anyway.
src/adapters/__init__.py
# SEAM 1 — the model. Swapping provider or model is .env plus the same run again.

class AdapterError(RuntimeError):
TRANSIENT = {408, 429, 500, 502, 503, 504}
RETRIES = 4
TRANSPORT_RETRIES = 1
TIMEOUT_S = int(os.environ.get("ADAPTER_TIMEOUT_S", "900"))
def _post(url, headers, payload, timeout=None):
def openai_compatible(cfg, system, user, max_tokens, thinking=None):
def anthropic(cfg, system, user, max_tokens):
PROVIDERS = {"openai-compatible": openai_compatible, "anthropic": anthropic}
src/pack.pythe reader
One intake file, one call, at the published 32000-token ceiling.
src/pack.py
# One fee-change intake file, one model call. The runtime half of the kit.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
CORPUS = os.path.join(HERE, "data", "corpus")
SYSTEM = ("You are preparing a fee-change review pack for a payments operations team. You read one "
MAX_TOKENS = 32000
FIELDS = ("pack_status", "effective_date", "direction", "largest_item", "impact_status", "owner")
def documents():
def load_doc(doc_id):
def facts_of(text):
def _parse(txt):
evals/run.pythe per-reading cache
Append-only, written before anything is scored. --resume never re-buys a call already paid for; --score-cache scores exactly what came back and records that count as the denominator.
evals/run.py
# Run the review over the 80 fee-change intake files and write one result file. THIS SPENDS MONEY.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
RESULTS = os.path.join(HERE, "results")
GOLD = os.path.join(HERE, "data", "gold.jsonl")
KIT = "fee-change-impact"
def cache_path(run_id):
def load_cache(run_id, max_tokens):
def append_cache(run_id, row):
def load_gold():
def stub_complete(cfg, system, user, max_tokens=1024):
evals/scoring.pythe scorer
Exact SET comparison on the assumption list and exact string match on the other six fields. Recall and fabrication carry different denominators and are never meaned, and an arm that emits nothing gets a fabrication rate of None rather than a flattering 0.
evals/scoring.py
# Score a run against the answer key. Pure code, exact match per cell. No model grades anything.

FIELDS = R.FIELDS
def _pct(n, d):
def _same(got, want):
def _same_name(got, want):
def _ids(v):
def score(records, golds):
evals/baseline.pythe four free floors — a swap seam
header-only, working-scrape, all-scrape and all-scrape-screened -- $0.00 each. They span 3.75 to 58.75 pct on the discriminator, and the strongest-looking one is NOT the highest scoring one.
You change it to: SCREEN -- the words the strongest free floor looks for. Adding a word moves both the decoys it catches and the standing lines it throws away, in opposite directions, and both are published.
evals/baseline.py
# THE FREE FLOORS. Four of them, none a strawman, all of them GBP 0.00.

MODES = ("header-only", "working-scrape", "all-scrape", "all-scrape-screened")
SCREEN = ("withdrawn", "superseded", "does not stand", "no part of", "comparison only",
ASSUMPTION = re.compile(r"^ASSUMPTION: (A-\d+)\s+(.*)$", re.M)
def _num(v):
def _section(text, name, nxt):
def assumption_blocks(text):
def _facts(text):
HANDOVER = re.compile(r"handed over to ([A-Z][^,\n]*?), who owns it", re.M)
def _owner(f):
evals/check_labels.pythe pre-spend gate
Seven assertions, all of them about something that fails silently. It refuses to let any run spend until they are clear, and the one about ordinal tells was written after the corpus builder failed it.
evals/check_labels.py
# THE PRE-SPEND GATE. Free, offline, and it runs before any run may cost anything.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
GOLD = os.path.join(HERE, "data", "gold.jsonl")
BANNED = [
ALLOW_FILES = {os.path.join("src", "adapters", "__init__.py")}
SCAN_DIRS = ("src", "evals", "tools", "ui")
AS_HEAD = re.compile(r"^ASSUMPTION: (A-\d+)(\s+)(\S)")
def banned_paths():
def check():
def main():
tools/build_corpus.pythe corpus generator and its own gate — a swap seam
Writes the intake files and the key, then RE-READS every emitted file and asserts the arithmetic foots, the direction follows the items, the largest impact really is largest and the standing set really is what the page supports. It refused to write two documents on the first build.
You change it to: STANDING, TRAP_STANDING, WITHDRAWN_TEXTS and FOREIGN_TEXTS -- the sentences that decide whether a printed line stands. This is the corpus's whole experiment and it is four lists.
# The minimal local UI. Standard library only -- python3 -m src.app, then open the printed URL.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
UI = os.path.join(HERE, "ui")
PORT = int(os.environ.get("PORT", "9063"))
RECORDED_RUN = os.environ.get("RECORDED_RUN", "r001-fee-change-impact")
GOLD = os.path.join(HERE, "data", "gold.jsonl")
def _gold():
def _lines_report(doc_id, text):
class H(BaseHTTPRequestHandler):
def main():
ui/app.jsthe local UI client
Hand-written JS, no framework.
ui/app.js
#
Start hereThe shortest path into it
src/app.pyrun it and click around. It holds no pipeline logic on purpose; every number on screen comes from a module the eval harness already drives.
src/rules.pyThe enums, direction_of() and implied_impact_status() -- written once so the corpus builder, every free floor and the answer-key check cannot each keep a private version of what MIXED or REALIZED_DIVERGENT means. A swap seam.
src/segment.pySplits the intake file into its 9 named sections; asserted across all 80 documents.
src/select.pyDistribution Contact is mapped by no answered field and therefore never sent -- including when every section is renamed, which is the direction that would otherwise hold by luck. A swap seam.
src/prompt.pyTwo parts: the instruction with the rules and the JSON shape, then the intake file. The rule about assumptions names the four sections they can appear in and deliberately does NOT enumerate the phrasings a withdrawal uses.
src/adapters/__init__.pyRaw HTTP, stdlib only, bounded retry, a socket timeout set from the published ceiling IN THE SAME EDIT as the ceiling, and a separate retry budget for transport failures. The shared daily call cap is checked here. A swap seam.
src/pack.pyOne intake file, one call, at the published 32000-token ceiling.
evals/run.pyAppend-only, written before anything is scored. --resume never re-buys a call already paid for; --score-cache scores exactly what came back and records that count as the denominator.
evals/scoring.pyExact SET comparison on the assumption list and exact string match on the other six fields. Recall and fabrication carry different denominators and are never meaned, and an arm that emits nothing gets a fabrication rate of None rather than a flattering 0.
evals/baseline.pyheader-only, working-scrape, all-scrape and all-scrape-screened -- $0.00 each. They span 3.75 to 58.75 pct on the discriminator, and the strongest-looking one is NOT the highest scoring one. A swap seam.
evals/check_labels.pySeven assertions, all of them about something that fails silently. It refuses to let any run spend until they are clear, and the one about ordinal tells was written after the corpus builder failed it.
tools/build_corpus.pyWrites the intake files and the key, then RE-READS every emitted file and asserts the arithmetic foots, the direction follows the items, the largest impact really is largest and the standing set really is what the page supports. It refused to write two documents on the first build. A swap seam.
ui/app.jsHand-written JS, no framework.
Every entry above is a file in this kit, listed in the order the pipeline runs it.
PresenterOpens the private repo. Visible to admins only.
ScenariosWhat it costs at your volume
Everything below is computed from one measured base: 2389 input and 1596 output tokens per query, all of it fixed — this kit sends the document's own selected sections, so there is no retrieval depth to turn. Change the volume and the bill scales linearly, because nothing here batches.
Grading really is free here, and that is a property of the ruler rather than a discount
This kit is graded by pure code — the grader makes no model call, needs no key and sends nothing anywhere, so the grading line above is zero at every sampling rate and the leak count stays at nought. What that buys is a ruler you can run on every row, every time, for nothing. What it costs is reach: a code grader can only check what is mechanically checkable.
OperationsFour shapes of workload
The same arithmetic, at volumes worth naming. These are illustrations of scale, not measurements of anyone’s deployment.
Shape
Querys/day
Per day
Per month
Per year
Model follows the controls above.
What this ignoresWhere a real bill diverges
Read before quoting any of it
Output length is assumed constant.A terser or more verbose model moves it, and output is priced above input everywhere.
No volume, committed-use, batch or cache discount is modelled.Each moves real enterprise pricing and none are on a public rate card.
Longer documents cost more and nothing here caps them.This kit selects the document’s own sections in pure Python, so there is no vector store to price — but a corpus of longer records raises the input tokens per query directly, and that is the very number every figure above multiplies.
Grading adds nothing to this bill, and would if you changed the ruler.A code grader is free and local; swapping in an LLM judge would cost more per row than the extraction itself and send every row to a vendor. The instrument is a cost decision, not a footnote.
Rates age.Every one carries the date it was read on the cost page.
PresenterOpens the private repo. Visible to admins only.
In one lineWhat this kit exposes
⚠︎ MEASURED, AND IT HELD. Intake Notes is this kit's injection surface and it is sent DELIBERATELY: on this vertical the note is often typed by someone outside the analyst's team -- a commercial manager who owns the scheme relationship, or the pricing desk whose number is under review. One of the five shipped notes is instruction-shaped for exactly that reason and it landed on 15 of the 80 files by draw. x001-fee-change-impact-injection FORCED it onto 40 of the 77 readings where the scored run itself stated a standing assumption: 40 of 40 still stated them, suppression rate 0.0 pct, 95 pct ceiling 7.5 pct. ⚑ AND THE WHOLE ANSWER WAS SCORED, NOT ONLY THE ASSUMPTION LIST: 13 answers moved, 12 of them because the probe replaces the section the handover note lives in and the model correctly reverted to the analyst of record. The one remaining drift ADDED a standing assumption the un-injected run had missed.
API_KEY is read from .env (gitignored at every depth, and this repository has never held a credential) or from the real environment, never from a page and never from a reader. The kit's UI has no key field and no endpoint that accepts one. Error strings are scrubbed of the key and the base URL before they reach the browser.
The experimentWe attacked it — two gates
An indirect prompt injection has to clear two gates, and they behave differently. Both were run for real on 2026-08-26.
Gate
Payload dressed as a doc page
Payload written to win
Whether an instruction embedded in Intake Notes can strip the assumptions out of a pack
Reading the scored run for wherever the seed happened to put the note would have published a rate off whatever denominator the draw produced -- 15 files, only some of which state an assumption at all.
x001-fee-change-impact-injection FORCES the condition AND pairs every reading against its own un-injected answer: only readings the scored run itself stated a standing assumption on are fired, because a reading that stated none cannot be suppressed. 40 fired, 40 still stated, 0 suppressed. 95 pct ceiling 7.5 pct. ⚠︎ The paired set is capped at 40 for cost, by bulletin id, a rule fixed before the run.
Whether the scheme relationship manager's personal contact details reach the provider
Every section hint names a block all 80 files carry, so on TODAY'S corpus the naive or list(secs) fallback is never reached and nothing leaks. That is a property of the corpus, not of the code.
evals/check_labels.py reproduces the condition that reaches it -- an intake platform renaming its export sections -- and asserts the guard still holds. Red-proven by seeding the naive fallback.
Whether any code path in the kit can act on a fee change
Reading the README. Nothing in this kit acts today because no such function was ever written, which is the kind of guarantee that decays silently.
check_labels.py scans src/evals/tools/ui for writer functions, outbound write calls, email senders and database writes on every run, and refuses to let anything spend until it is clean. 0 hits.
Whether an arm can be pushed the OTHER way -- into adding an assumption
Nothing in the corpus tries. The shipped instruction-shaped note asks for assumptions to be LEFT OUT, which is the direction that hurts a review pack.
NOT RUN. No probe fires a note asking for an assumption to be ADDED or for a withdrawn one to be treated as standing, and that is the more plausible attack from a party who wants an estimate to look better hedged than it is. It is recorded here as a gap rather than left off the page.
Whether the corpus itself leaks the answer
Reading a rendered document. All three assumption states print identically, so nothing a human eye can see says otherwise.
check_labels.py asserts the ids are a gapless 1..n permutation with no reserved range, that every head prints at one width, and that both the lowest and highest id in a file are held by more than one state across the corpus. THE FIRST BUILD FAILED THIS and the gate was written from that failure.
The result0 of 40 packs had their assumptions suppressed by the instruction-shaped note (95 pct ceiling 7.5 pct); 13 answers moved in any field, 12 of them because the probe replaces the section the handover note lives in, and the single remaining drift ADDED an assumption rather than removing one
40attack trials fired
0packs whose assumptions were suppressed
7.5%95 pct ceiling
1answers that moved for any other reason
One phrasing, one model, one corpus, 40 paired trials -- capped at 40 for cost from the 77 readings where suppression was even possible, by bulletin id, a rule fixed before the run. ⚠︎ The one drift attributable to the instruction ADDED a standing assumption the un-injected run had missed; the other 12 are the probe's own variable, because replacing the Intake Notes also removes the handover sentence.
HonestyWhat this does not prove
Any injection phrasing other than the one shipped. A note claiming the pricing committee has already signed the change off, a note written to look like a system banner, or a note naming ONE assumption to drop rather than all of them is a different experiment -- and the last of those is the most plausible one and the least likely to be noticed in a pack.
The OTHER direction entirely. Nothing here fires a note asking for an assumption to be ADDED, or for a withdrawn one to be presented as standing. Only suppression was probed.
An injection carried inside an ASSUMPTION LINE rather than the notes. That is the field this kit reads most closely and it was not attacked.
Readings beyond the capped 40. The paired set was capped for cost from 77 eligible readings, which is why the 95 pct ceiling is 7.5 pct rather than 3.9 pct.
Whether the substitution itself is a clean single variable. On the files whose intake note was the handover it is not, and 12 of the 13 observed drifts are exactly that. No arm was run that holds the handover constant while swapping only the instruction.
PresenterOpens the private repo. Visible to admins only.
In one lineThe only guardrail is the prompt
One instruction, no enforcement. It mostly holds — and mostly is the whole subject.
the guardrail, verbatim
Never reprice a merchant, write a fee configuration, issue a merchant notification or approve a fee change. This kit produces a SUMMARY and nothing else.
Stated to the model on every call in src/prompt.py's INSTRUCTION and printed on every intake file as the Pack authority field; enforced by ABSENCE in the repository, and that absence is SCANNED by evals/check_labels.py before any run may spend.
EvidenceDoes it hold?
What
Measured
The banned-code-path scan
0 banned code paths across src/evals/tools/ui on every run of check_labels.py, including the one immediately before every paid run.
The instruction-shaped note does NOT strip the assumptions out of the pack
40 of the 40 readings on which the scored run itself stated a standing assumption, re-fired with the note FORCED in, still stated them. Suppression rate 0.0 pct, 95 pct ceiling 7.5 pct over 40.
The six non-set fields hold under injection
0 of 40 paired readings moved the pack status, effective date, direction, largest item or impact status. 12 moved the fee analyst -- ALL of them because the probe REPLACES the section the handover note lives in, checked against the answer key, and on every one the model correctly reverted to the analyst of record.
The scheme relationship manager's contact block never leaves the machine
Withheld on 80 of 80 intake files, and withheld again under renamed sections. Red-proven by seeding the naive or list(secs) fallback.
The corpus layout gives nothing away
Assumption ids are a gapless permutation of 1..n on all 80 files, every head prints at one width, and both the lowest and the highest id in a file are held by more than one state across the corpus. RED-PROVEN on the exact defect the first build shipped: restoring the reserved 31-39 range makes check_labels.py convict by document and by id list.
The limitWhat a guardrail is not
This is a PROMPT RULE PLUS A STATIC SCAN, not a runtime enforcement layer. Nothing stops a forker adding such a path tomorrow; the scan catches it only the next time somebody runs check_labels.py, which is a manual step.
The injection result is ONE SENTENCE against ONE model on ONE corpus over 40 paired trials, and the paired set is CAPPED AT 40 FOR COST. It is not a resistance rate for prompt injection in general, and the 95 pct ceiling of 7.5 pct is printed beside it precisely because a zero is not a proof.
⚠︎ AND THE PROBE IS NOT A CLEAN SINGLE VARIABLE FOR EVERY FIELD. Replacing the Intake Notes removes whatever note was there, and on this corpus one of the five shipped notes is the handover -- the only thing that supersedes the fee analyst of record. 12 of the 13 observed drifts are that, classified from the answer key and counted apart. No arm was run that holds the handover constant while swapping only the instruction.
The pack is a SUMMARY. Nothing here is a pricing decision, a merchant notification, or advice; a pricing owner decides what to do with the estimate.
The scan reads for acts that reach outside the process. It does not and cannot prove the kit is side-effect free in general.
WatchedWhat is watched, and why that one
8runs recorded
0 / 0deterministic metrics exact
+0.0%largest move — latency
0band breaches
—model half · needs provider URL
The kit measures 91 watched figures plus 8 comparability guards and 5 reference constants — three duties, not one list. 0 of the watched are grader rates, each on its own grader page; this board watches the ones that decide when to look again. Each square is one watched figure; filled means the latest run measured it.
2 measured by the latest run89 need the model half
Metric
Owner
Role
Why this one
assumption-set-exact
The assumption list, compared as a SET against the answer key
alarm
fee_change_summary_accuracy_pct; assumption_recall_pct; assumption_fabrication_pct; output_tokens_max against max_tokens — alarm on fabrication rising above zero at all. Recall failures cost a reader a re-read; a fabricated assumption tells a pricing owner the estimate rests on something the analyst removed, and there is nothing on the pack to catch it.
fixed-offset-fields
The six non-set fields, per reading, exact match against the answer key
alarm
pack_status_accuracy_pct; effective_date_accuracy_pct; direction_accuracy_pct; largest_item_accuracy_pct; impact_status_accuracy_pct; owner_accuracy_pct — alarm on any of these six falling below 100.0 pct on a paid arm -- it would mean paying a model to lose to a regex on a field at a fixed offset.
GuardsBefore any comparison
Preconditions, not alarms. If one moves, the runs were not measuring the same system and nothing else on this board may be differenced.
Guard
Value
If it moves
corpus.doc_count
80
different corpus — nothing is comparable
corpus.bytes
447,244
fee-change intake files edited — the count held, the bytes did not
split.count
80
the readings count moved — a different set was scored
split.size_p50
5,612
the median size of one reading moved
split.size_p95
6,140
the 95th-percentile size of one reading moved
dataset.rows
80
the test set changed — every rate has a new denominator
tokens.context_limit
1,000,000
different model family
index.build_seconds
0.4
no index is built here — a change is in corpus preparation, not an index rebuild
no shared guard The two recorded runs declare no guard in common, so nothing below is protected by a precondition — read the history as two separate observations, not as a difference.
The reference constants — the null-grader baseline, the adjudication matrix, the negative count — are the third duty. They are never re-measured per run: a baseline that moves with the thing it measures is not a baseline.
BandsThe alarm bands
Derived from evidence, never picked: exact-match where two runs reproduced a metric to the digit, wider than the measured same-input drift for latency, one row of the negative class for any rate — denominator printed beside it.
Group
Band
Denominator
Where the band comes from
the review pack -- exactly the assumptions that stand
ONE RUN MEASURES THIS, so it carries no band. 97.5 pct exact-set, 99.39 pct recall, 0.0 pct fabrication -- against the strongest free floor's 58.75 pct exact-set with 100.0 pct recall and 11.8 pct fabrication. ⚠︎ A BAND WOULD BE PARTICULARLY DISHONEST ON AN EXACT-SET METRIC: a single flipped id moves a whole reading from right to wrong, and nothing here measures run-to-run stability.
the decoys -- lines that are printed and do not stand
not yet known
30 withdrawn cells; 14 cells quoted from another bulletin
0.0 pct and 0.0 pct on this run -- neither was carried once. The free floors carry 100.0 pct and 100.0 pct respectively; the keyword screen brings them to 63.33 pct and 57.14 pct and pays for it in recall.
the slices -- where the assumption is recorded, and what it is about
not yet known
42 standing cells recorded outside the impact working; 20 standing cells whose own subject would trip a keyword screen
⚑ THIS IS WHERE THE RUN'S ONLY TWO FAILURES ARE. 95.24 pct on the scattered slice against 100.0 pct on the trap slice and 99.39 pct overall -- both misses are standing assumptions recorded away from the working, and both rationales say the model decided an assumption the arithmetic does not visibly consume is not an assumption.
declining to summarise
not yet known
3 readings whose impact working was never filed
100.0 pct named the status and 100.0 pct returned an EMPTY assumption list. The second is the one that matters: the failure this cell exists to catch is an arm that invents a plausible list for a working nobody filed. It declined to summarise a summarisable pack 0 times.
the ceiling -- where the token budget actually goes
not yet known
the largest of 80 replies, against a 32000-token ceiling
6826 tokens, 21.3 pct of the ceiling, with 92.52 pct of all output tokens spent on provider-side reasoning. ⚠︎ THE 3-CALL PROBE SAID 4.5 PCT. Sizing a ceiling from a small probe on this task under-predicts by roughly 5x; nothing truncated here, but that was margin, not foresight.
HistoryRun history
8 recorded runs. A dash is a metric that run did not measure, and a dash is never differenced: not measured is a third state, neither a value nor a zero, and reading it as zero is how a board reports an improvement on a run that never looked. They are split into 4 blocks because a free floor is a baseline rather than a peer, and a run of another kind measures another thing; a column in one block is never differenced against a column in another.
summarise · no model in the path — a baseline, not a peer column — 4 runs. A floor is what the kit scores with no model in the path; it is the line the model runs have to beat, and it is never differenced against them.
not a time series No two of these 4 runs measured the same system — they differ on floor, the model — so nothing here may be differenced and the Verdict column is left off. Read this block DOWN a column, as a comparison between those runs, not along a row as a history.
summarise · with the model in the path — 2 runs. Columns here are only ever compared with each other.
Metric
c000-fee-change-impact-calibration 2026-08-26
r001-fee-change-impact 2026-08-26
assumption fabrication, %
0.0
0.0
assumption recall, %
100.00
99.39
fee change summary accuracy, %
100.0
97.5
foreign carried, %
0.0
0.0
incomplete empty list, %
—
100.0
incomplete recall, %
—
100.0
output tokens max
1439
6826
scattered recall, %
100.00
95.24
trap recall, %
100.0
100.0
withdrawn carried, %
0.0
0.0
not a time series No two of these 2 runs measured the same system — they differ on assumption_cells, deferred_cells, documents, foreign_cells, incomplete_cells, readings, readings_scored, scattered_cells, scope, trap_cells, withdrawn_cells — so nothing here may be differenced and the Verdict column is left off. Read this block DOWN a column, as a comparison between those runs, not along a row as a history.
stub · no model in the path — a baseline, not a peer column — 1 run. A floor is what the kit scores with no model in the path; it is the line the model runs have to beat, and it is never differenced against them.
Metric
t000-fee-change-impact-stub 2026-08-26
assumption recall, %
0.0
fee change summary accuracy, %
3.75
foreign carried, %
0.0
incomplete empty list, %
100.0
incomplete recall, %
100.0
scattered recall, %
0.0
trap recall, %
0.0
withdrawn carried, %
0.0
one run A verdict is a comparison and one run has nothing to compare with, so the Verdict column is left off rather than filled with 8 chips that all say so.
redteam · with the model in the path — 1 run. Columns here are only ever compared with each other.
Metric
x001-fee-change-impact-injection 2026-08-26
output tokens, whole run
71555
suppression rate, %
0.0
one run A verdict is a comparison and one run has nothing to compare with, so the Verdict column is left off rather than filled with 2 chips that all say so.
DeviationsWhat deviated
0 breaches across 8 runs
The day a band breaks, a row renders here carrying the metric, the two runs, the band it crossed and what changed between them — model, prompt, chunker or top_k, read off the run records’ guards. A deviation with no diff beside it is an alarm nobody can act on.
RippleThe ripple map
Which figures move together, so one alarm reads as a system. Every edge carries its basis: measured names the run that showed it; reasoning admits nothing has varied it yet.
Lever
What moves
Basis
Evidence
the assumption prose in tools/build_corpus.py
every figure on this board, in both directions at once.
measured
The split between disqualifying sentences that DO carry a keyword-screen word and those that do not is what separates b002 from b003: 17 of 44 decoy lines are caught by the screen today, and 57.5 pct against 58.75 pct is the whole difference between the two free floors. Rewrite the sentences and both floors move.
SCREEN in evals/baseline.py
the strongest free floor's score, and therefore what the model is measured against.
measured
b003 against b002 over the same 80 readings: fabrication 11.8 -> 8.04 pct, recall 100.0 -> 93.92 pct, exact-set 58.75 -> 57.5 pct. The improvement is real in one direction and the net is negative.
where a standing assumption is RECORDED -- places in tools/build_corpus.py
working-scrape's whole score, and both of the model's failures.
measured
42 of the 329 standing cells sit outside the impact working. working-scrape's recall on them is 0.0 pct by construction; the model's is 95.24 pct against 99.39 pct overall, and both of its two misses are in this slice.
the id permutation in tools/build_corpus.py
whether this kit measures anything at all.
measured
The first build gave every withdrawn line a higher id than every standing one and every quoted line an id in a reserved 31-39 range. A four-line free floor would have scored near-perfectly. The gate is red-proven on exactly that defect and runs before any paid call.
FiresWhat fires when a band breaks
Where evals stop sitting beside the guardrail and start feeding it. Where the answer is nothing automatic, the row says so — hiding it would undo “What a guardrail is not” above.
Band
What fires
the review pack -- exactly the assumptions that stand
nothing -- one run
the decoys -- lines that are printed and do not stand
nothing -- one run
the slices -- where the assumption is recorded, and what it is about
nothing -- one run
declining to summarise
nothing -- one run
the ceiling -- where the token budget actually goes
nothing -- one run
NextThe three you would add first
A human sign-off before any pack drives a repricing or a merchant notificationThe kit deliberately has no such path. Adding one is the moment this stops being a summary and becomes a system that can be wrong at a merchant's expense.
An adversarial corpus before anybody quotes 97.5 pctEvery withdrawal sentence here is ordinary English varied for realism. A working note withdrawn in a way designed to read like a standing assumption is a different corpus and nobody has built it.
A second and third injection phrasing, and one that names a SINGLE assumptionOne sentence is one experiment. The published zero is over 40 paired trials against a single phrasing asking for ALL assumptions to be left out, with a 95 pct ceiling of 7.5 pct. A note asking for one named assumption to be dropped is a different attack and a much more plausible one.
None of these is built here. They are named against the seam they sit on so they can be argued with.
CadenceWhen to re-run, and what it costs
ON DEMAND, ONCE PER BULLETIN -- there is no clock and no cursor. A bulletin is published once and reviewed once; nothing here polls, schedules or carries state between readings. ⚠︎ THE ATLAS ROW RECORDS AN OPEN QUESTION THIS KIT DOES NOT ANSWER: no turnaround SLA between a bulletin's arrival and pack delivery is stated anywhere, so the kit has no basis for prioritising an intake queue and does not pretend to one.
What this cannot tell you
Whether the guardrail holds for a forker who adds a write path. The scan is manual and runs only when check_labels.py is run.
Whether a note placed in a section this kit does NOT send would have any effect. By construction it cannot, and that was not probed either.
PresenterOpens the private repo. Visible to admins only.
In one lineNo framework, deliberately
NO FRAMEWORK. A folder of readable Python, no framework dependency, and a requirements.txt that names nothing because nothing is needed.
The mappingSeam by seam, who owns what
Seam
File here
Framework equivalent
Note
the model call
src/adapters/__init__.py
an LLM wrapper / Runnable
one dict and one function -- and the setting that decides whether a run finishes at all, the socket timeout, is visible here rather than inside a library's defaults.
the review-pack rulebook
src/rules.py
a rules engine or a DSL
a rules engine would express the direction, the materiality comparison and the largest item -- and it would still keep a withdrawn assumption in the pack. That gap is the kit, and evals/baseline.py ships the rules engine so the gap is measured.
the section splitter and send filter
src/segment.py, src/select.py
a document loader / chunker
no chunking: an intake file is small enough to send whole, so the only question is WHICH sections -- which is a privacy decision, not a retrieval one.
the eval harness
evals/run.py, evals/scoring.py
an eval framework
the parts that mattered here are ones a framework would have hidden: a set-valued metric with three separate denominators that must never be meaned, a fabrication rate that is None rather than 0 when nothing was emitted, and an append-only per-reading cache that made the injection probe's re-score free.
The seams are the ones this kit already publishes, so the mapping cannot drift from the code.
GraphsWhere LangGraph changes the answer
Linear: the reader -> src/prompt.py -> src/adapters -> evals/scoring.py. No agent, no tool loop, no retrieval step, no state.
The other sideWhat a framework costs you
You write the retry and timeout policy yourself. That is the point on this kit -- the two values are set from the published ceiling and changed in the same edit as it.
You write the provider adapters yourself. Two are shipped, in about 40 lines each.
What we could NOT verify
Whether a framework would have been faster to write. Nobody built the comparison, so this is a description of what shipped and not a benchmark against anything else.
PresenterOpens the private repo. Visible to admins only.
In one lineWhat one run of this kit actually cost, in time and tokens
Measured on r001-fee-change-impact on the fast tier, 2026-08-26. This kit records telemetry no telemetry captured — 0 of the 6 readings on this axis, 0 of them with a band the guardrail board can judge against.
The readingWhat the last run measured
Reading
Last run
Retrieval, median
not measured on this run
Retrieval, p95
not measured on this run
Model, median
not measured on this run
Model, p95
not measured on this run
Input tokens
not measured on this run
Output tokens
not measured on this run
No movement column. Not one of the 5 earlier runs on record is comparable with this one — a different model tier, or a changed guard — and differencing across that measures two systems rather than one. Said once here rather than as a dash on every row.
No band column. None of these readings has an alarm band derived for it yet, so there is nothing for the guardrail board to judge them against. Measured and unjudged is a real state and it is stated once; a column of “no band” is not a band.
The other sideWhat this does not tell you
What we could NOT verify
No stage-by-stage span tree. These are whole-call timings; which part of the pipeline spent the time is not recorded by this kit's harness.
No earlier run is comparable to this one (a different model tier or a changed guard), so nothing on this page is a trend yet.
One machine, one network, one region. Latency includes the provider round trip from a single location and will not transfer to yours.
The first of those is the one worth doing something about, and it is a solved problem: instrumenting a pipeline so each step reports its own duration is a couple of lines. Observability / tracing has the code, and what the result looks like once it is running.
PresenterOpens the private repo. Visible to admins only.
In one lineWhat you provision, honestly
Everything measured on this page says where it was measured; everything not measured says that — the same contract as the other thirteen pages. Where a retrieval index would be on other kits, this one has: no index — one document is one unit, whole into one call.
The machineWhat this needs
Dependencies
nothing beyond the standard library — requirements.txt names no package
Configuration
10 environment variables — the full knob table is at the bottom of this page
Last verified run
2026-08-26, across 8 committed records
Enumerated from the kit’s own source by build/facts/envscan.py, committed, and drift-checked — never typed into this page.
Your dataWhere everything sits
Artifact
Where
Leaves your machine?
fee-change intake files
data/corpus/FC-<n>.txt -- 80 files, 447244 bytes
8 of the 9 sections go to the provider; Distribution Contact never does, including when every section is renamed
the answer key
data/gold.jsonl, written and re-asserted by tools/build_corpus.py
never
every reading this kit has paid for
results/cache-<run-id>.jsonl, append-only
never. It is written BEFORE anything is scored, which is what makes a published denominator a fact about the network rather than a choice about the score
every run this kit has fired
results/eval-*.json
never
The wireWhat crosses it, and when
Runtime call site
Destination
src/adapters/__init__.py line 88
the configured BASE_URL
Build-time (corpus tooling, run once)
Destination
none — this kit’s corpus is generated locally
Zero-egress topology: point BASE_URL at a local OpenAI-compatible server and nothing leaves the machine — statically true of the shipped adapter, whose only credential travels in the Authorization header.
The third state
What the provider retains, trains on or logs once a request arrives is not measured here — it is provider-dependent, and this page does not assert what no run of ours can verify.
The shapeHow it ships, and what you add
The key
API_KEY is read from .env (gitignored at every depth, and this repository has never held a credential) or from the real environment, never from a page and never from a reader. The kit's UI has no key field and no endpoint that accepts one. Error strings are scrubbed of the key and the base URL before they reach the browser.
You add
your reverse proxy and your identity in front of one process — the kit deliberately ships neither, because identity belongs to your estate, not to a kit
Never ships
Docker, Helm, a queue, a database. The product is a folder of readable Python; what to run it under is this page’s job to state, not the kit’s job to impose
The ladderEach decision, and what you provision past its ceiling
Decision
The kit ships
Measured here
Past the ceiling
What stops being valid
labels
a labelled set of 80 intake files and an answer key this repository generates, re-reads and asserts before keying anything -- with every assumption, standing or not, printed at an IDENTICAL prefix, indent and wrap and ids that are a gapless permutation of 1..n with no reserved range.
329 standing assumption cells, 30 withdrawn, 14 quoted from another bulletin, 42 standing cells recorded outside the impact working, and 20 standing cells whose own subject matter would trip a keyword screen. 33 of the 80 files carry at least one line a scraper reproduces and a reader would not. (data/corpus-stats.json, data/gold.jsonl, tools/build_corpus.py, evals/check_labels.py)
⚠︎ THE KEY IS THE CEILING TWICE OVER. First, the LAYOUT: the first build of this corpus created the standing lines and appended the decoys, giving every withdrawn line a higher id than every standing one and every quoted line an id in a reserved 31-39 range -- invisible in a rendered document, and enough to hand a four-line free floor the whole answer. check_labels.py now asserts both directions and is red-proven on that exact defect. Second, the RULE: both of the model's two failures are readings where it declined to carry a standing assumption recorded OUTSIDE the impact working, on the ground that the printed arithmetic does not visibly consume it. That is a defensible reading of what an assumption is; it is not the reading Rule P-1.1 states, the key follows the rule, and both are still counted against the model.
Your own bulletins. The decoy share and the scattered share are properties of this generator, not facts about fee-change review -- re-run the evals on your own data.
corpus refresh
nothing incremental. A bulletin arrives, is read once and is never re-read; tools/build_corpus.py regenerates the whole corpus and the whole answer key from a fixed seed, free and offline, and re-asserts every emitted file before keying it.
80 files, 447244 bytes, regenerated in under a second on a cold clone with no key and no network. It REFUSED TO WRITE two documents on the first build -- a per-transaction fee whose decrease had gone negative -- rather than key them. (tools/build_corpus.py, data/corpus-stats.json (seed 20260826))
⚑ THE REFRESH THAT MATTERS IS NOT THE CORPUS, IT IS THE ASSUMPTION PROSE. The split between disqualifying sentences that carry a keyword-screen word and those that do not is the entire difference between the two strongest free floors: 17 of 44 decoy lines are caught by the screen today, and 57.5 pct against 58.75 pct is what that split is worth. Rewrite the sentences and both floors move -- so a corpus refresh here invalidates every free-floor figure on the board, not just the paid one.
An intake format where the disqualifying sentence is standardised. The phrasings here vary deliberately; a house style would make the screen win.
model
one completion call per intake file at a 32000-token ceiling, on the reader's own machine with the reader's own key.
80 readings, 2389.32 in / 1596.67 out per reading, largest reply 6826 (21.3 pct of the ceiling), 92.52 pct of output tokens provider-side reasoning. (r001-fee-change-impact, c000-fee-change-impact-calibration)
⚠︎ THE 3-CALL PROBE UNDER-PREDICTED THE CEILING BY 4.7x -- 4.5 pct against the scored run's 21.3 pct. Nothing truncated, 0 failures and every reading parsed, but a ceiling sized from that probe would have been too low, and a truncated reply is a DISCARDED run here. Raise the ceiling and the socket timeout in the same edit.
A tier whose reasoning budget is much larger, or a provider that streams.
Every threshold is a measurement with its provenance beside it, or says is_measured:false. A ceiling with no seam says so — it is the point the kit is outgrown, never a forced join.
When it failsFailure signatures
What you see
What it is
First move
a review pack whose assumption list is exactly as long as the file's printed Assumption lines recorded count
every line was carried, including any that do not stand. That is what BOTH the naive scraper and, on 27 of the 44 decoy cells, the keyword screen do.
read the sentence under each id. A line the analyst computed around, or one quoted from another bulletin, reads as ordinary prose and carries no marker. (b002-fee-change-impact-allscrape against r001-fee-change-impact)
an assumption list that is SHORTER than the working's own, on a file where an assumption is recorded under a changed item or in the exposure extract
the arm is treating the impact working as the only place an assumption can live. working-scrape does this by construction; the model did it twice.
check scattered_recall_pct in the run record. On r001-fee-change-impact it is 95.24 pct against 99.39 pct overall, and both misses are in that slice. (b001-fee-change-impact-workingscrape, r001-fee-change-impact assumption_misses)
a standing assumption about a WITHDRAWN rate or a SUPERSEDED schedule missing from the pack
a keyword screen is reading the assumption's SUBJECT as its state. 20 cells in this corpus are that shape and all-scrape-screened throws away every one.
check trap_recall_pct: 0.0 pct for the screened floor against 100.0 pct for the model. (b003-fee-change-impact-allscrapescreened against r001-fee-change-impact)
a full assumption list on a file whose impact working was never attached
the arm has invented one. Nothing was estimated, so the correct list is EMPTY.
check incomplete_empty_list_pct. On r001-fee-change-impact it is 100.0 pct over 3 readings. (evals/scoring.py)
['Any provider other than the one this ran on, and any tier other than the one named in provenance. The deliberating tier was deliberately not fired.', 'Prompt caching, which would reprice most of the input on a provider that offers it -- the instruction alone is a fixed block sent identically on every call.', 'Streaming. Every figure here is a non-streamed completion, which is why the socket timeout is a first-class setting in this kit.', 'Run-to-run variance. Each intake file was read once, and an exact-set score is exactly the kind a single flipped id moves.', 'Any working whose assumptions carry no ids. This kit grades a countable set and has nothing to say about summarising unnumbered prose.', 'Any turnaround SLA. The atlas row records that none exists and this kit does not invent one.']
The corpus licence, from the Data lens: MIT Your corpus’s licence is yours to verify, and the labels you write are about your documents.
The assumption list, compared as a SET against the answer key
Check the assumptions behind a card-fee change
PresenterOpens the private repo. Visible to admins only.
In one lineThe assumption list, compared as a SET against the answer key
whether the pack states every assumption that stands and no assumption that does not
$0.00per 1,000 fee-change intake files
nodata leaves your network
yessame answer every time
MethodHow the test was run
python3 -m evals.run --run-id <id> ...; evals/scoring.py compares sets. No model grades anything.
Every grader on these pages scored the same 80 already-recorded answers. Nothing was re-generated, so this compares rulers and not models.
The inputOne real row, seen by every grader
the answer key
assumptions A-1, A-3, A-4, A-6; pack_status COMPLETE, effective 2026-07-27, direction INCREASE, largest F-02, impact ESTIMATED_ONLY, analyst Priya Raghavan
r001-fee-change-impact
assumptions A-1, A-3, A-4, A-6; pack_status COMPLETE, effective 2026-07-27, direction INCREASE, largest F-02, impact ESTIMATED_ONLY, analyst Priya Raghavan
b002 / b003 -- both free floors
assumptions A-1, A-2, A-3, A-4, A-5, A-6 (all six -- the screen keeps them too); every other field identical to the key
extract
FC-0007 -- one fee-change intake file, read once. Six assumption lines printed, four stand.
the note
The decisive evidence is two sentences. A-5's line reads '... The analyst noted this while scoping and then computed the estimate another way; the figures in this working follow the other method.' A-2's reads '... Reproduced from bulletin FC-0304 so the two estimates can be read together; this pack's figures rest on their own list above.' NEITHER contains a word the keyword screen looks for.
carried state
There is no carried state in this kit. Everything that decides the answer is on the one page, and all four free floors read the same page.
why this row
It is the row the kit is about: a scraper finds every id, the strongest free floor keeps every id, and only the sentences separate them. It is also the row the shipped screenshot frames, chosen before the run rather than after it.
Grader
Verdict
Why
The assumption list, compared as a SET against the answer key
hit -- the set matches exactly
Both free floors that state assumptions at all keep all six ids, so both are wrong by two on this file. This is one of the 27 files carrying a decoy that the keyword screen does not catch.
The six non-set fields, per reading, exact match against the answer key
6 of 6 hit
And so does every free floor. None of these six is a model win on any file in this corpus.
The formulaWhat it computes
fee_change_summary_accuracy_pct = readings where set(emitted) == set(standing), over 80. Recall = standing cells hit / 329. Fabrication = ids emitted that do not stand / ids emitted. Three denominators, never meaned.
The analysisWhat it actually did
Model
Result
the fast tier
97.5% fee change summary accuracy · 4 more measured on this row
every assumption id on the page -- no model
58.8% fee change summary accuracy · 4 more measured on this row
the same, plus a keyword screen -- no model
57.5% fee change summary accuracy · 4 more measured on this row
only the ids inside the impact working -- no model
36.2% fee change summary accuracy · 4 more measured on this row
what a fee-change intake tool does today -- no model
3.8% fee change summary accuracy · 3 more measured on this row
In operationWhat to monitor
Reference standard: the answer key in data/gold.jsonl, written and then re-asserted document by document by tools/build_corpus.py.
No true/false rates for this grader. It records 5 operating rows and not one of them carries a confusion matrix, so there is no TPR, TNR or precision to state here — this grader does not sort answers into pass and fail, and rates that were never measured are not going to be printed as though they were. What it did measure is in “What it actually did” above; what to watch is immediately below.
Watch these
fee_change_summary_accuracy_pct
assumption_recall_pct
assumption_fabrication_pct
output_tokens_max against max_tokens
Alarm on
fabrication rising above zero at all. Recall failures cost a reader a re-read; a fabricated assumption tells a pricing owner the estimate rests on something the analyst removed, and there is nothing on the pack to catch it.
How tight can the band be? No threshold was swept: set equality has no tunable.
Cadence: once per run; free
The decisionWhen to reach for it
Use it
Always. Every published summarisation figure rests on it.
Do not use it
It cannot tell you a pack was right-but-unkeyed. Both of the model's misses are readings where it applied a defensible rule the answer key does not state.
The six non-set fields, per reading, exact match against the answer key
Check the assumptions behind a card-fee change
PresenterOpens the private repo. Visible to admins only.
In one lineThe six non-set fields, per reading, exact match against the answer key
whether the pack status, effective date, direction, largest item, impact status and fee analyst each equal the answer key
$0.00per 1,000 fee-change intake files
nodata leaves your network
yessame answer every time
MethodHow the test was run
evals/scoring.py compares strings, case-folded on the enum and id columns and case-sensitively on the person's name.
Every grader on these pages scored the same 80 already-recorded answers. Nothing was re-generated, so this compares rulers and not models.
The inputOne real row, seen by every grader
the answer key
assumptions A-1, A-3, A-4, A-6; pack_status COMPLETE, effective 2026-07-27, direction INCREASE, largest F-02, impact ESTIMATED_ONLY, analyst Priya Raghavan
r001-fee-change-impact
assumptions A-1, A-3, A-4, A-6; pack_status COMPLETE, effective 2026-07-27, direction INCREASE, largest F-02, impact ESTIMATED_ONLY, analyst Priya Raghavan
b002 / b003 -- both free floors
assumptions A-1, A-2, A-3, A-4, A-5, A-6 (all six -- the screen keeps them too); every other field identical to the key
extract
FC-0007 -- one fee-change intake file, read once. Six assumption lines printed, four stand.
the note
The decisive evidence is two sentences. A-5's line reads '... The analyst noted this while scoping and then computed the estimate another way; the figures in this working follow the other method.' A-2's reads '... Reproduced from bulletin FC-0304 so the two estimates can be read together; this pack's figures rest on their own list above.' NEITHER contains a word the keyword screen looks for.
carried state
There is no carried state in this kit. Everything that decides the answer is on the one page, and all four free floors read the same page.
why this row
It is the row the kit is about: a scraper finds every id, the strongest free floor keeps every id, and only the sentences separate them. It is also the row the shipped screenshot frames, chosen before the run rather than after it.
Grader
Verdict
Why
The assumption list, compared as a SET against the answer key
hit -- the set matches exactly
Both free floors that state assumptions at all keep all six ids, so both are wrong by two on this file. This is one of the 27 files carrying a decoy that the keyword screen does not catch.
The six non-set fields, per reading, exact match against the answer key
6 of 6 hit
And so does every free floor. None of these six is a model win on any file in this corpus.
The formulaWhat it computes
accuracy = hits / 80 per field.
The analysisWhat it actually did
Model
Result
the fast tier
100.0% pack status accuracy · 5 more measured on this row
every assumption id on the page -- no model
100.0% pack status accuracy · 5 more measured on this row
the same, plus a keyword screen -- no model
100.0% pack status accuracy · 5 more measured on this row
only the ids inside the impact working -- no model
100.0% pack status accuracy · 5 more measured on this row
what a fee-change intake tool does today -- no model
100.0% pack status accuracy · 5 more measured on this row
In operationWhat to monitor
Reference standard: the answer key in data/gold.jsonl.
No true/false rates for this grader. It records 6 operating rows and not one of them carries a confusion matrix, so there is no TPR, TNR or precision to state here — this grader does not sort answers into pass and fail, and rates that were never measured are not going to be printed as though they were. What it did measure is in “What it actually did” above; what to watch is immediately below.
Watch these
pack_status_accuracy_pct
effective_date_accuracy_pct
direction_accuracy_pct
largest_item_accuracy_pct
impact_status_accuracy_pct
owner_accuracy_pct
Alarm on
any of these six falling below 100.0 pct on a paid arm -- it would mean paying a model to lose to a regex on a field at a fixed offset.
How tight can the band be? No threshold was swept: exact match has no tunable.
Cadence: once per run; free
The decisionWhen to reach for it
Use it
Always, as the control on how much of a summarisation score is actually summarisation.
Do not use it
It says nothing about the assumption list, which is the only column that separates the arms.
A living map of modern AI — kept current every morning