Read scanned supplier invoices and know which fields to trust
Supplier invoices and orders arrive as scans, and a scan quietly turns 2026 into 20Z6. This app reads six key fields from the page as written and as scanned, and marks which ones survived.
PresenterOpens the private repo. Visible to admins only.
For accounts payableCross-domain
Why it matters
Today's manual process, and the same job with the app
An accounts payable team whose supplier invoices and purchase orders arrive as scans from the post room.
✕Today's manual process
1Key in every scan: document number, date, supplier, total, currency and order reference.
2Check every field against the scanned image, because a scan blurs letters and digits.
3Or trust a reader that did well on clean test files, and hope it holds on scans.
4One misread digit in a document number looks exactly like a real one, and goes into the ledger.
Every scanned field checked manually
✓With the app
1Six fields are read from every page: number, date, supplier, total, currency and reference.
2Each field is marked ok, wrong or missed, against the same page as written.
3You see which fields hold: currency and totals survive the scan, document numbers are the weak spot.
4Your team decides what goes straight in, and document numbers get a person's check first.
People check only the weak fields
See it work
One real document, as written and as scanned, step by step
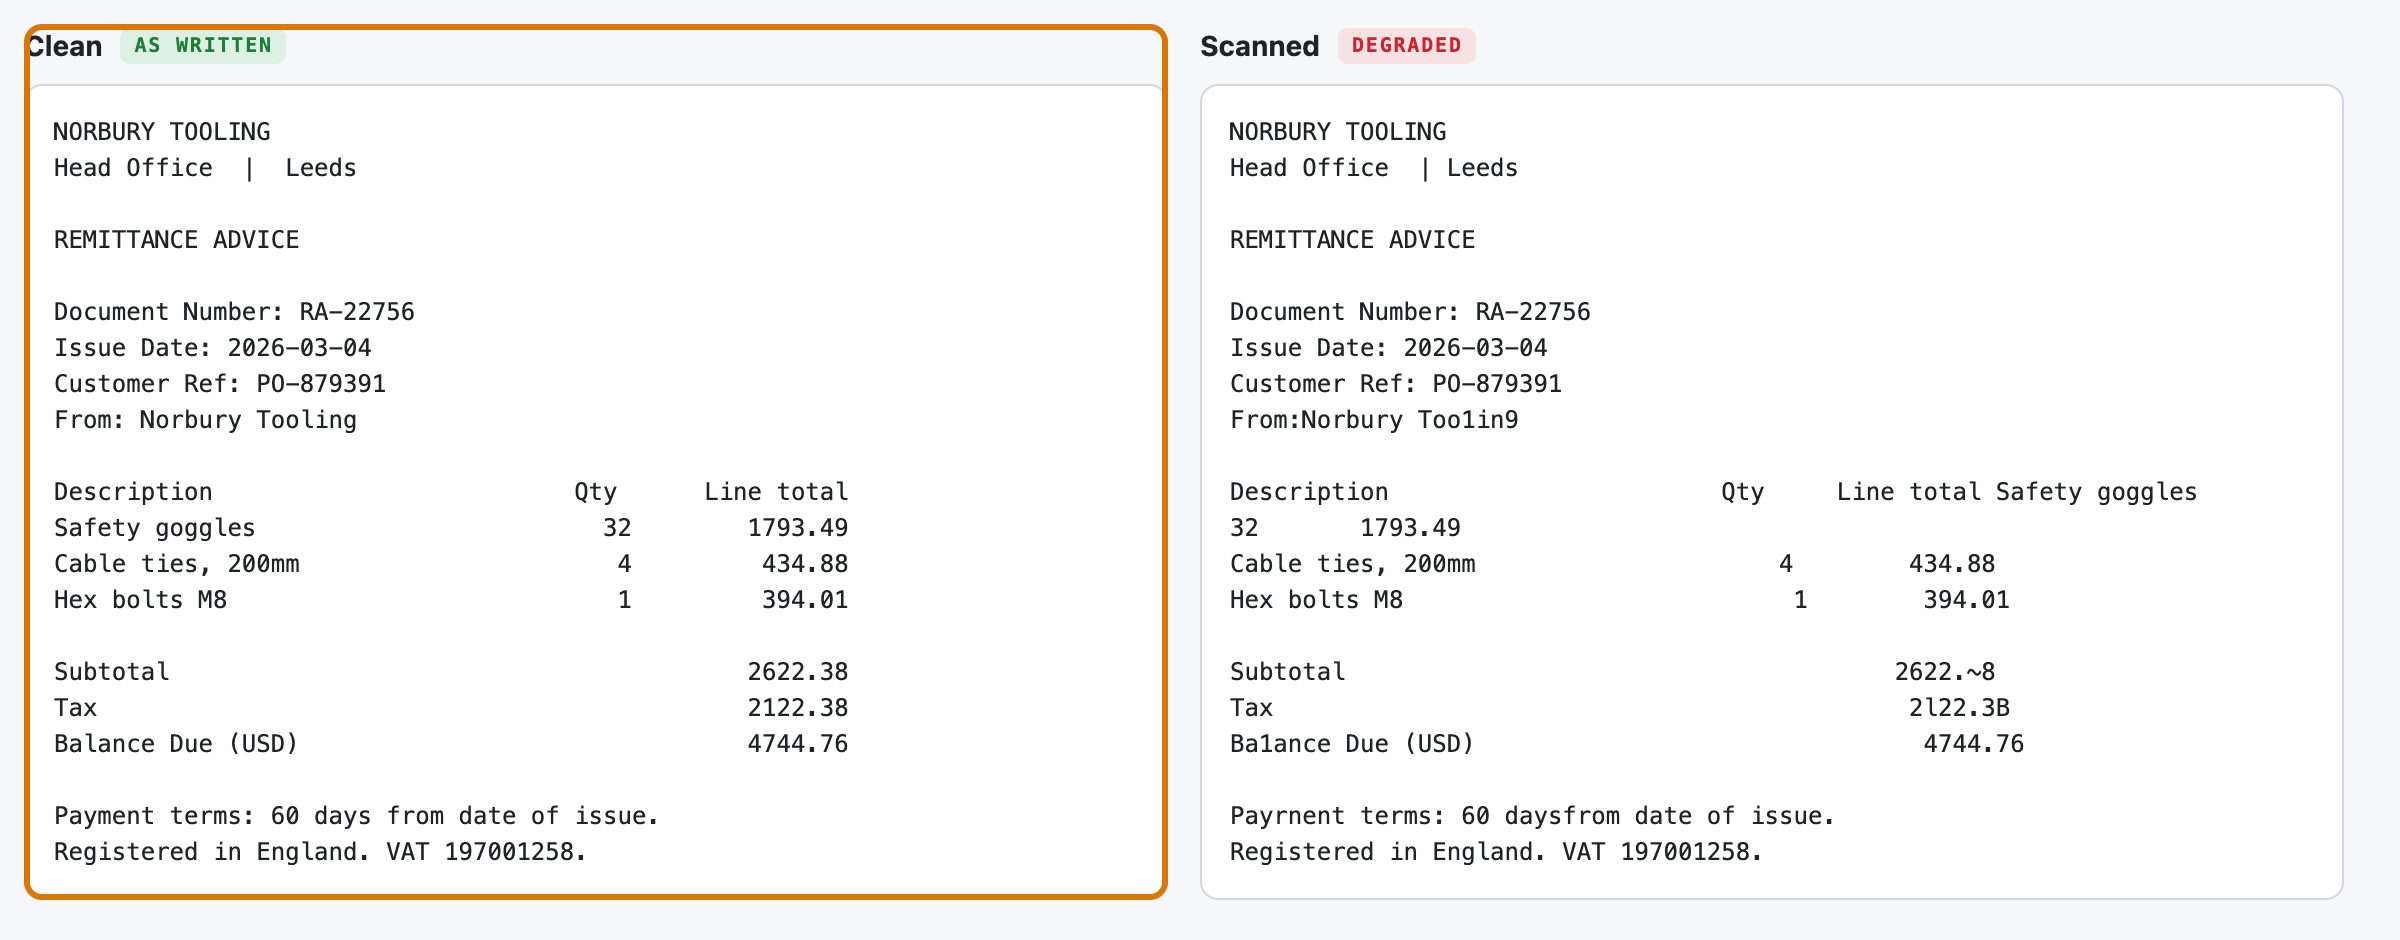
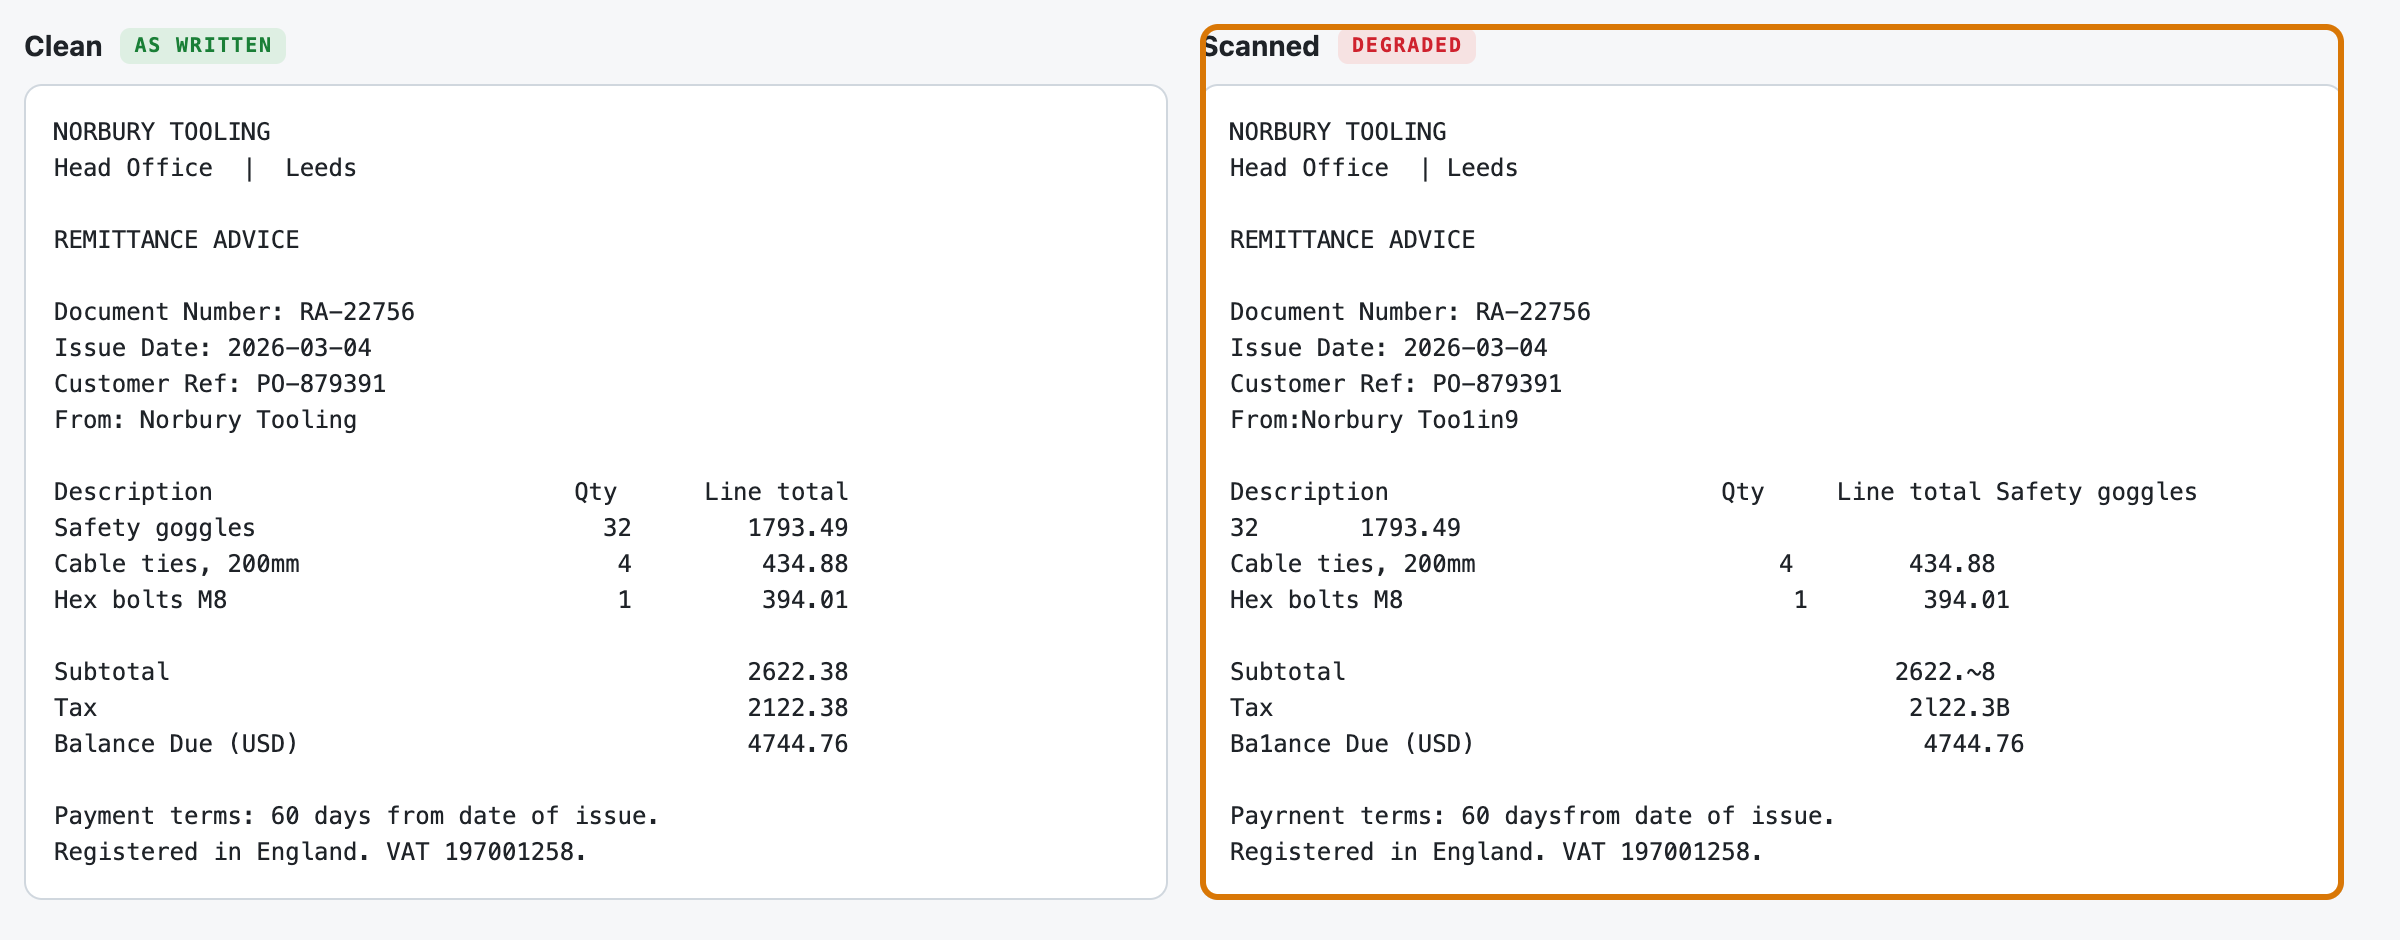
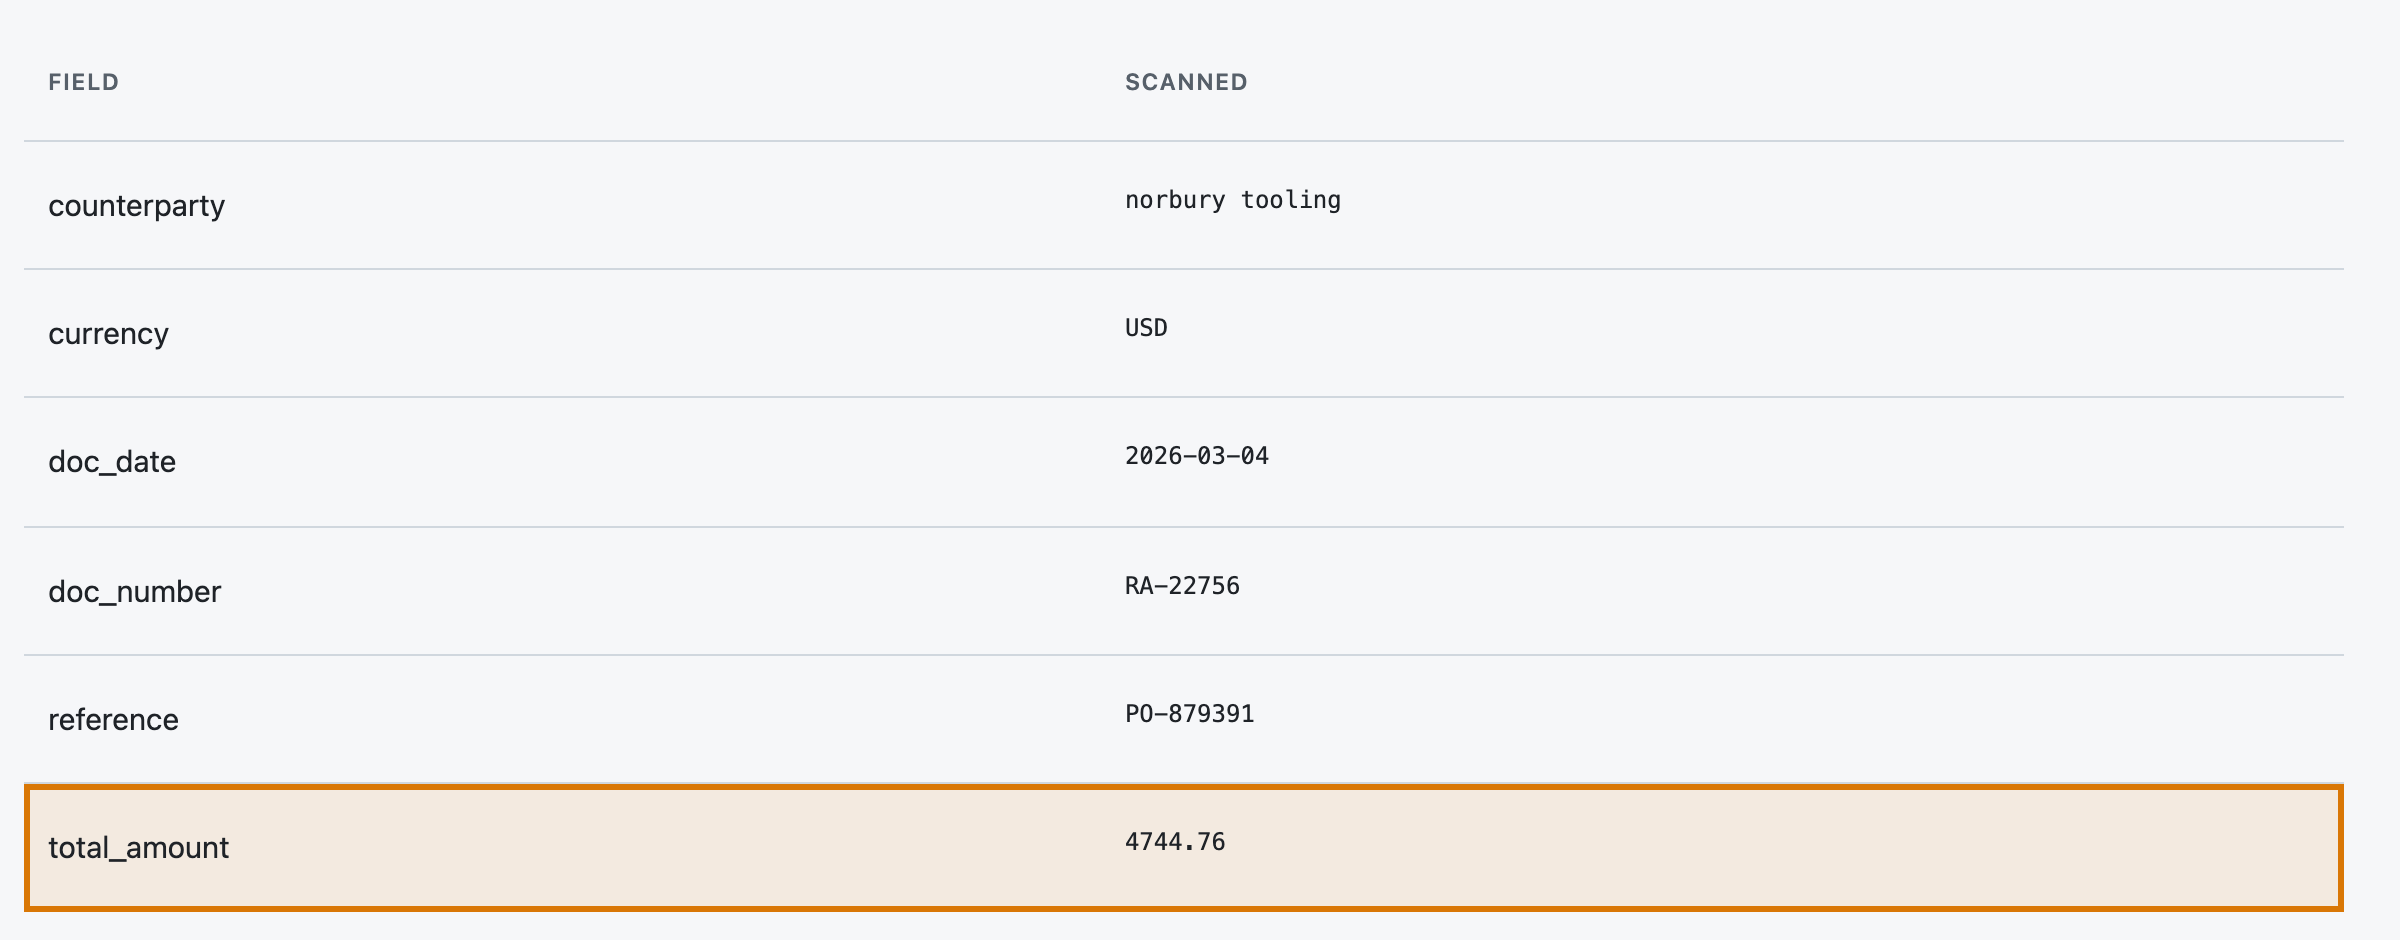
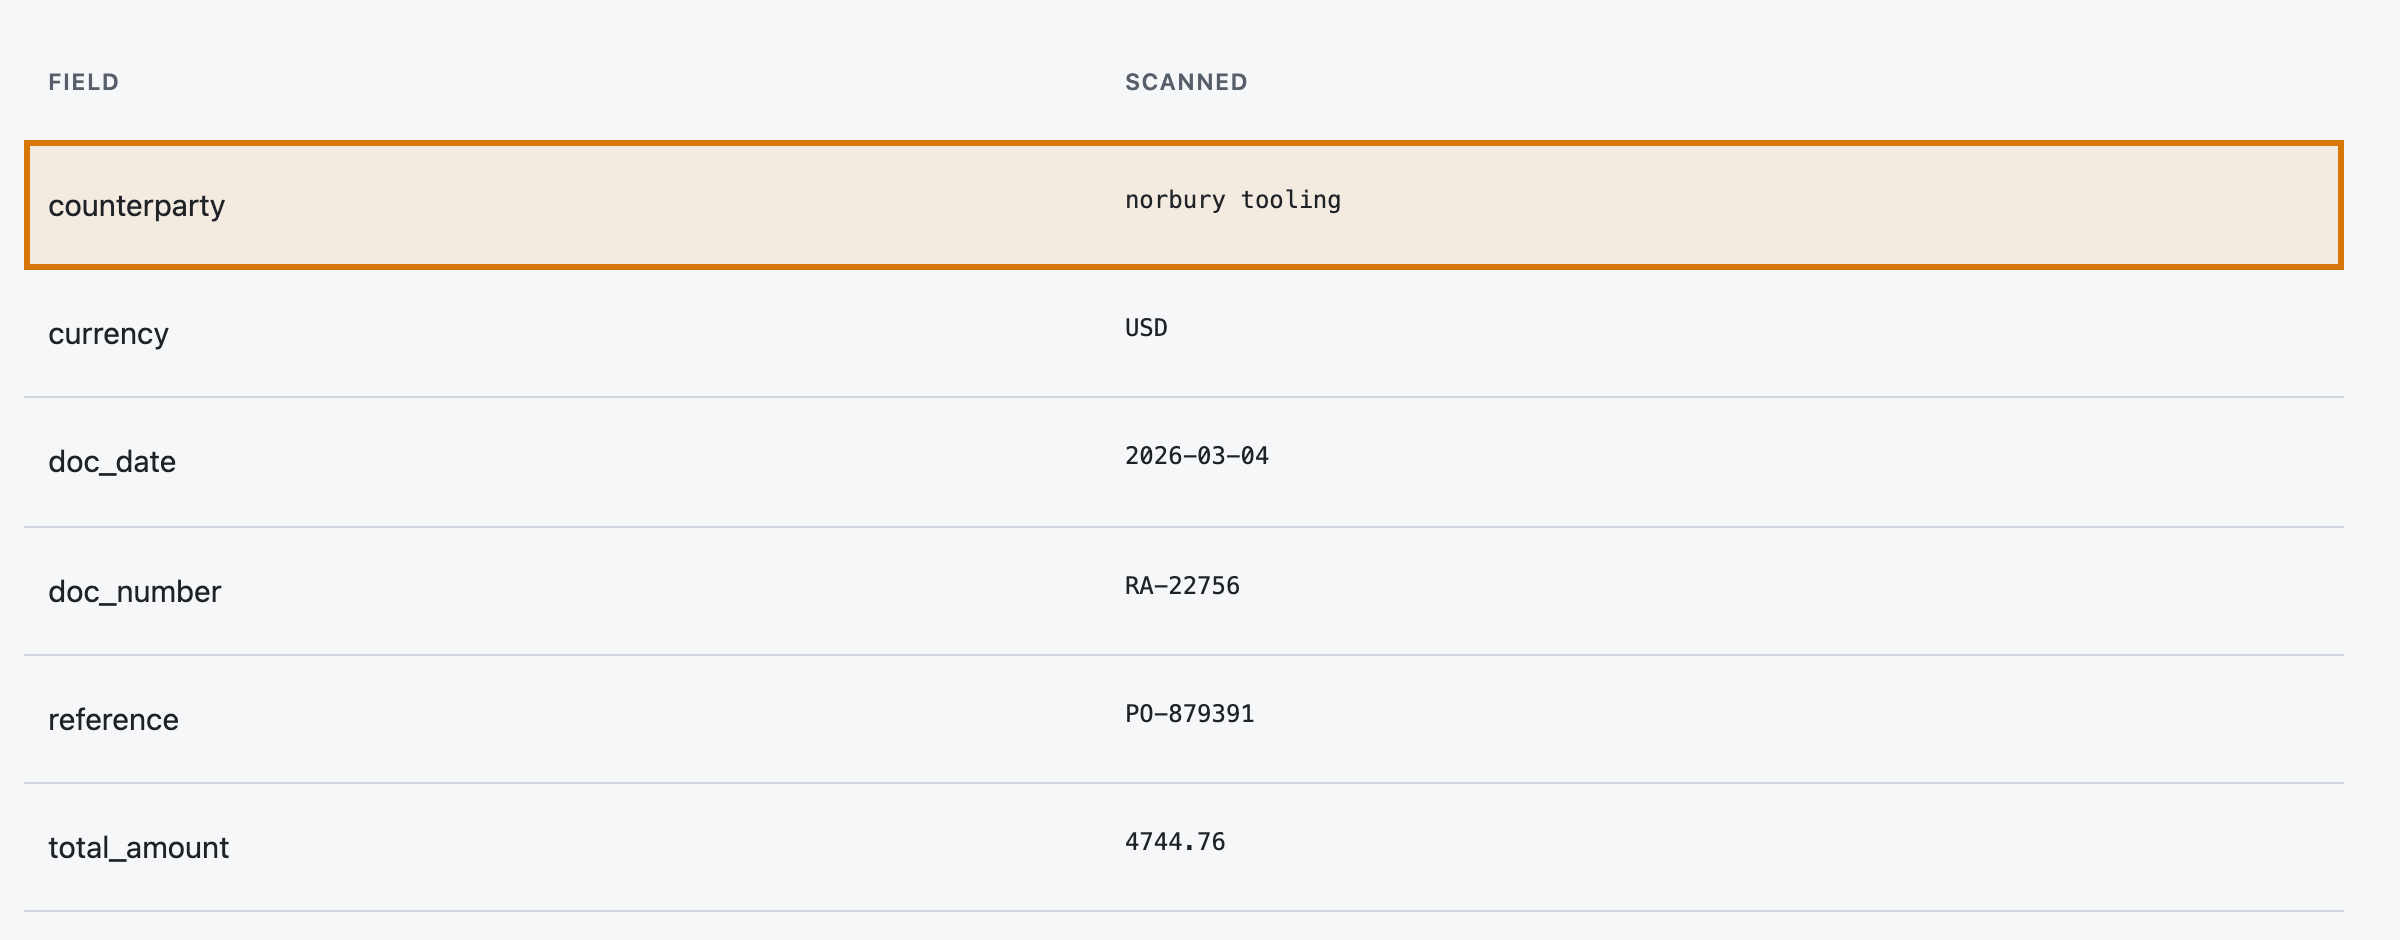
Norbury Tooling's remittance advice RA-22756, as written and as a scan that turns 'Tooling' into 'Too1in9' and 'Balance' into 'Ba1ance'.
Read scanned supplier invoices and know which fields to trustReference appBuilt to be shaped to your process
6
1The document as written Norbury Tooling's remittance advice RA-22756, dated 2026-03-04.
2The same document, scanned 'Tooling' became 'Too1in9', and 'Balance' became 'Ba1ance'.
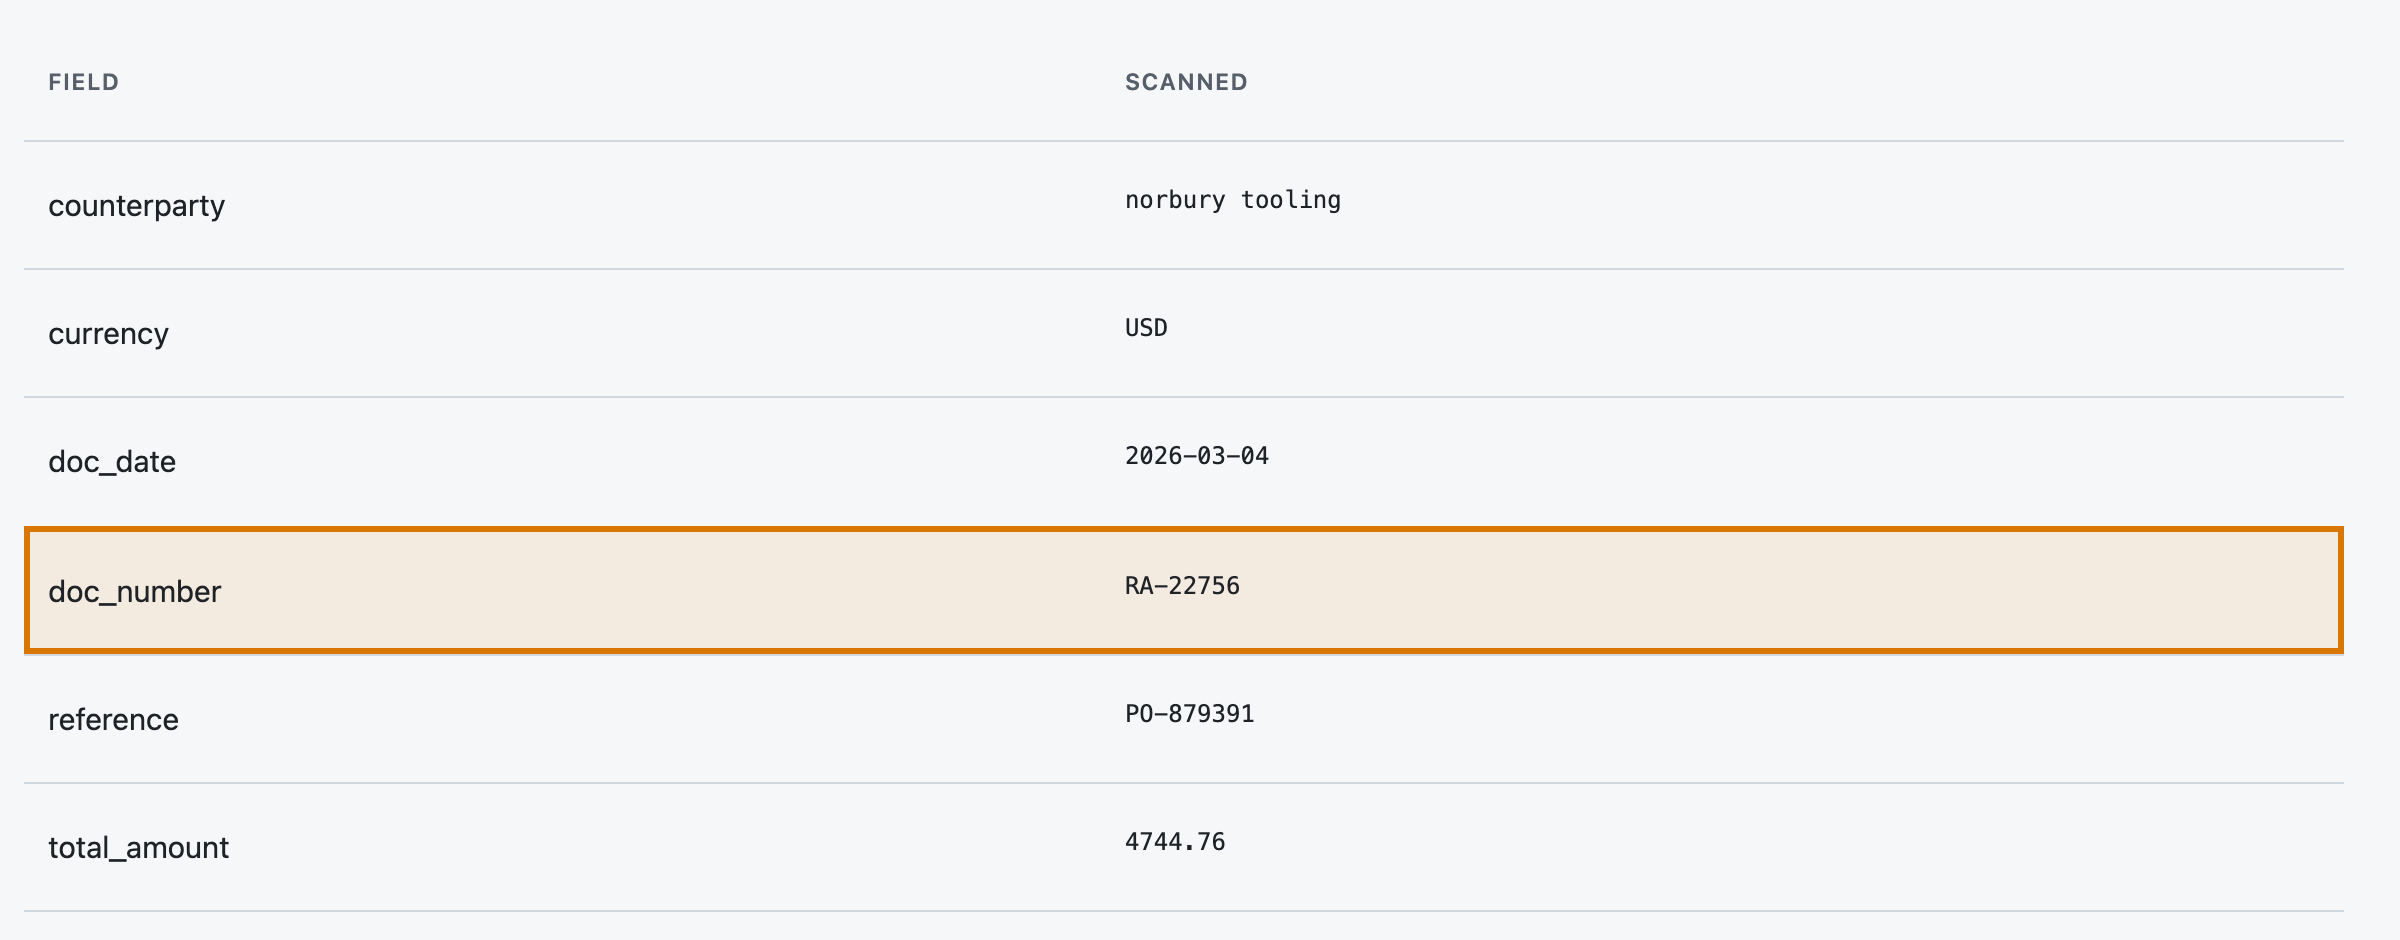
3The document number RA-22756, read correctly from the scan.
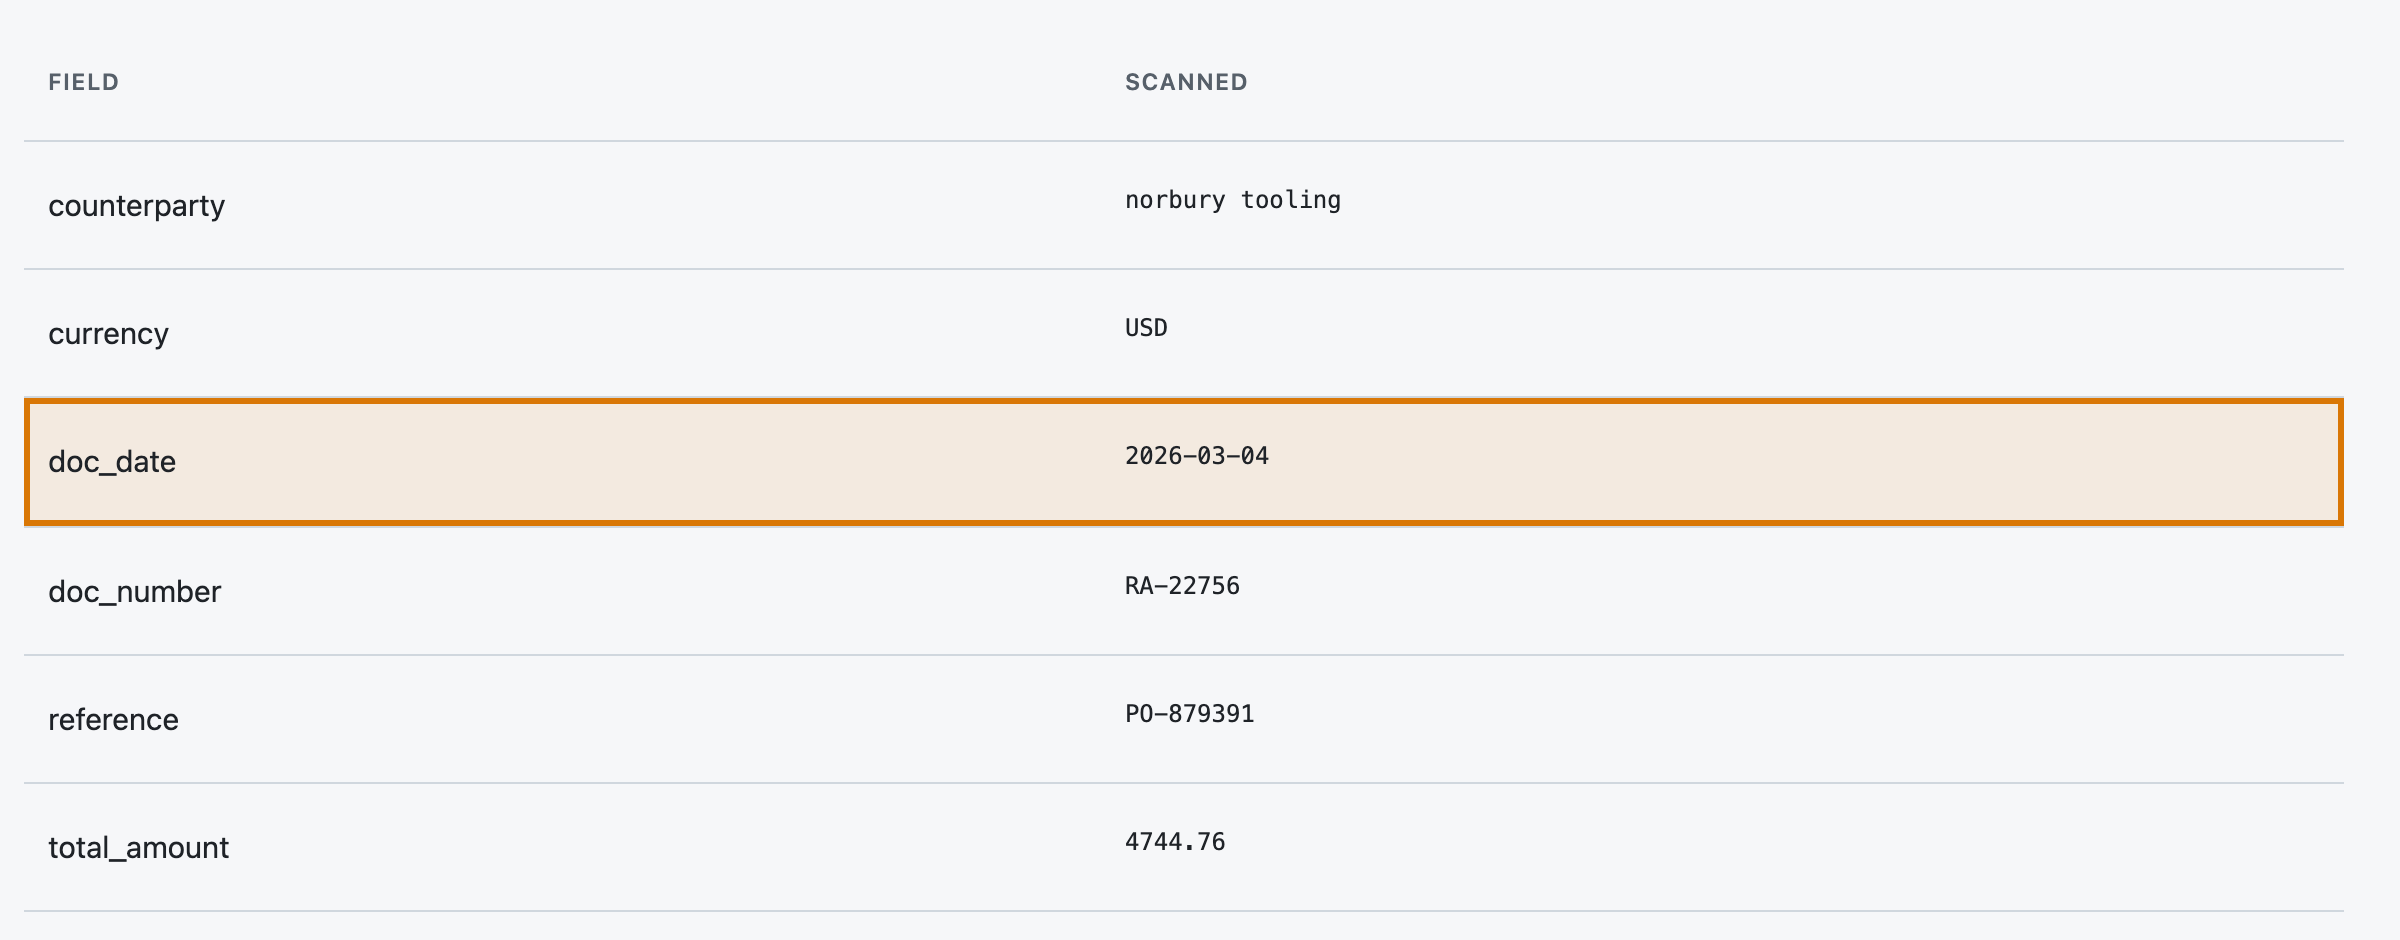
4The date 2026-03-04, unaffected by the scan's damage.
5The total $4,744.76, unchanged despite the scan's typos.
6The supplier name Norbury Tooling, correct even though the scan wrote 'Too1in9'.
For engineers
How it is built, and how we measured it
All fourteen steps of the build are written up, from the business case to running it in your own environment.
Read scanned supplier invoices and know which fields to trust
A small, forkable project that does one job end to end. Run twice for real over the same set, and every figure on these pages captured from those runs.
PresenterOpens the private repo. Visible to admins only.
The business caseThe problem this solves
Every extraction benchmark runs on clean text. Production runs on scans and on documents where two suppliers label the same field three different ways. Nobody publishes what that costs you. A hand-check of every scanned document, or the unexamined assumption that the extractor which scored well in the demo will hold up on the post room's output.
Audience
Anyone about to put a document pipeline in front of real inbound paperwork. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual business documents
The corpus is 120 business documents, 0.08 MB (txt 120). Measuring this gap needs the SAME page in two conditions with one ground truth attached to both, and no public corpus ships that pair. Real scanned enterprise documents cannot be published at all — third-party, usually confidential, licences that do not permit redistribution. Self-authoring removes the argument and is the only way the degraded half can be held to a known answer: we know what the page said before it was damaged, because we wrote it.
The corpus
The 120 business documentsgenerated from a fixed seed, so no real record, person or institution appears in it.
Where each came fromnowhere — we wrote all 120 from a fixed seed, and tools/build_corpus.py --verify rebuilds them byte for byte.
Swap this folder for your own material and the kit is pointed at your business documents. That is the whole change — there is no database to migrate.
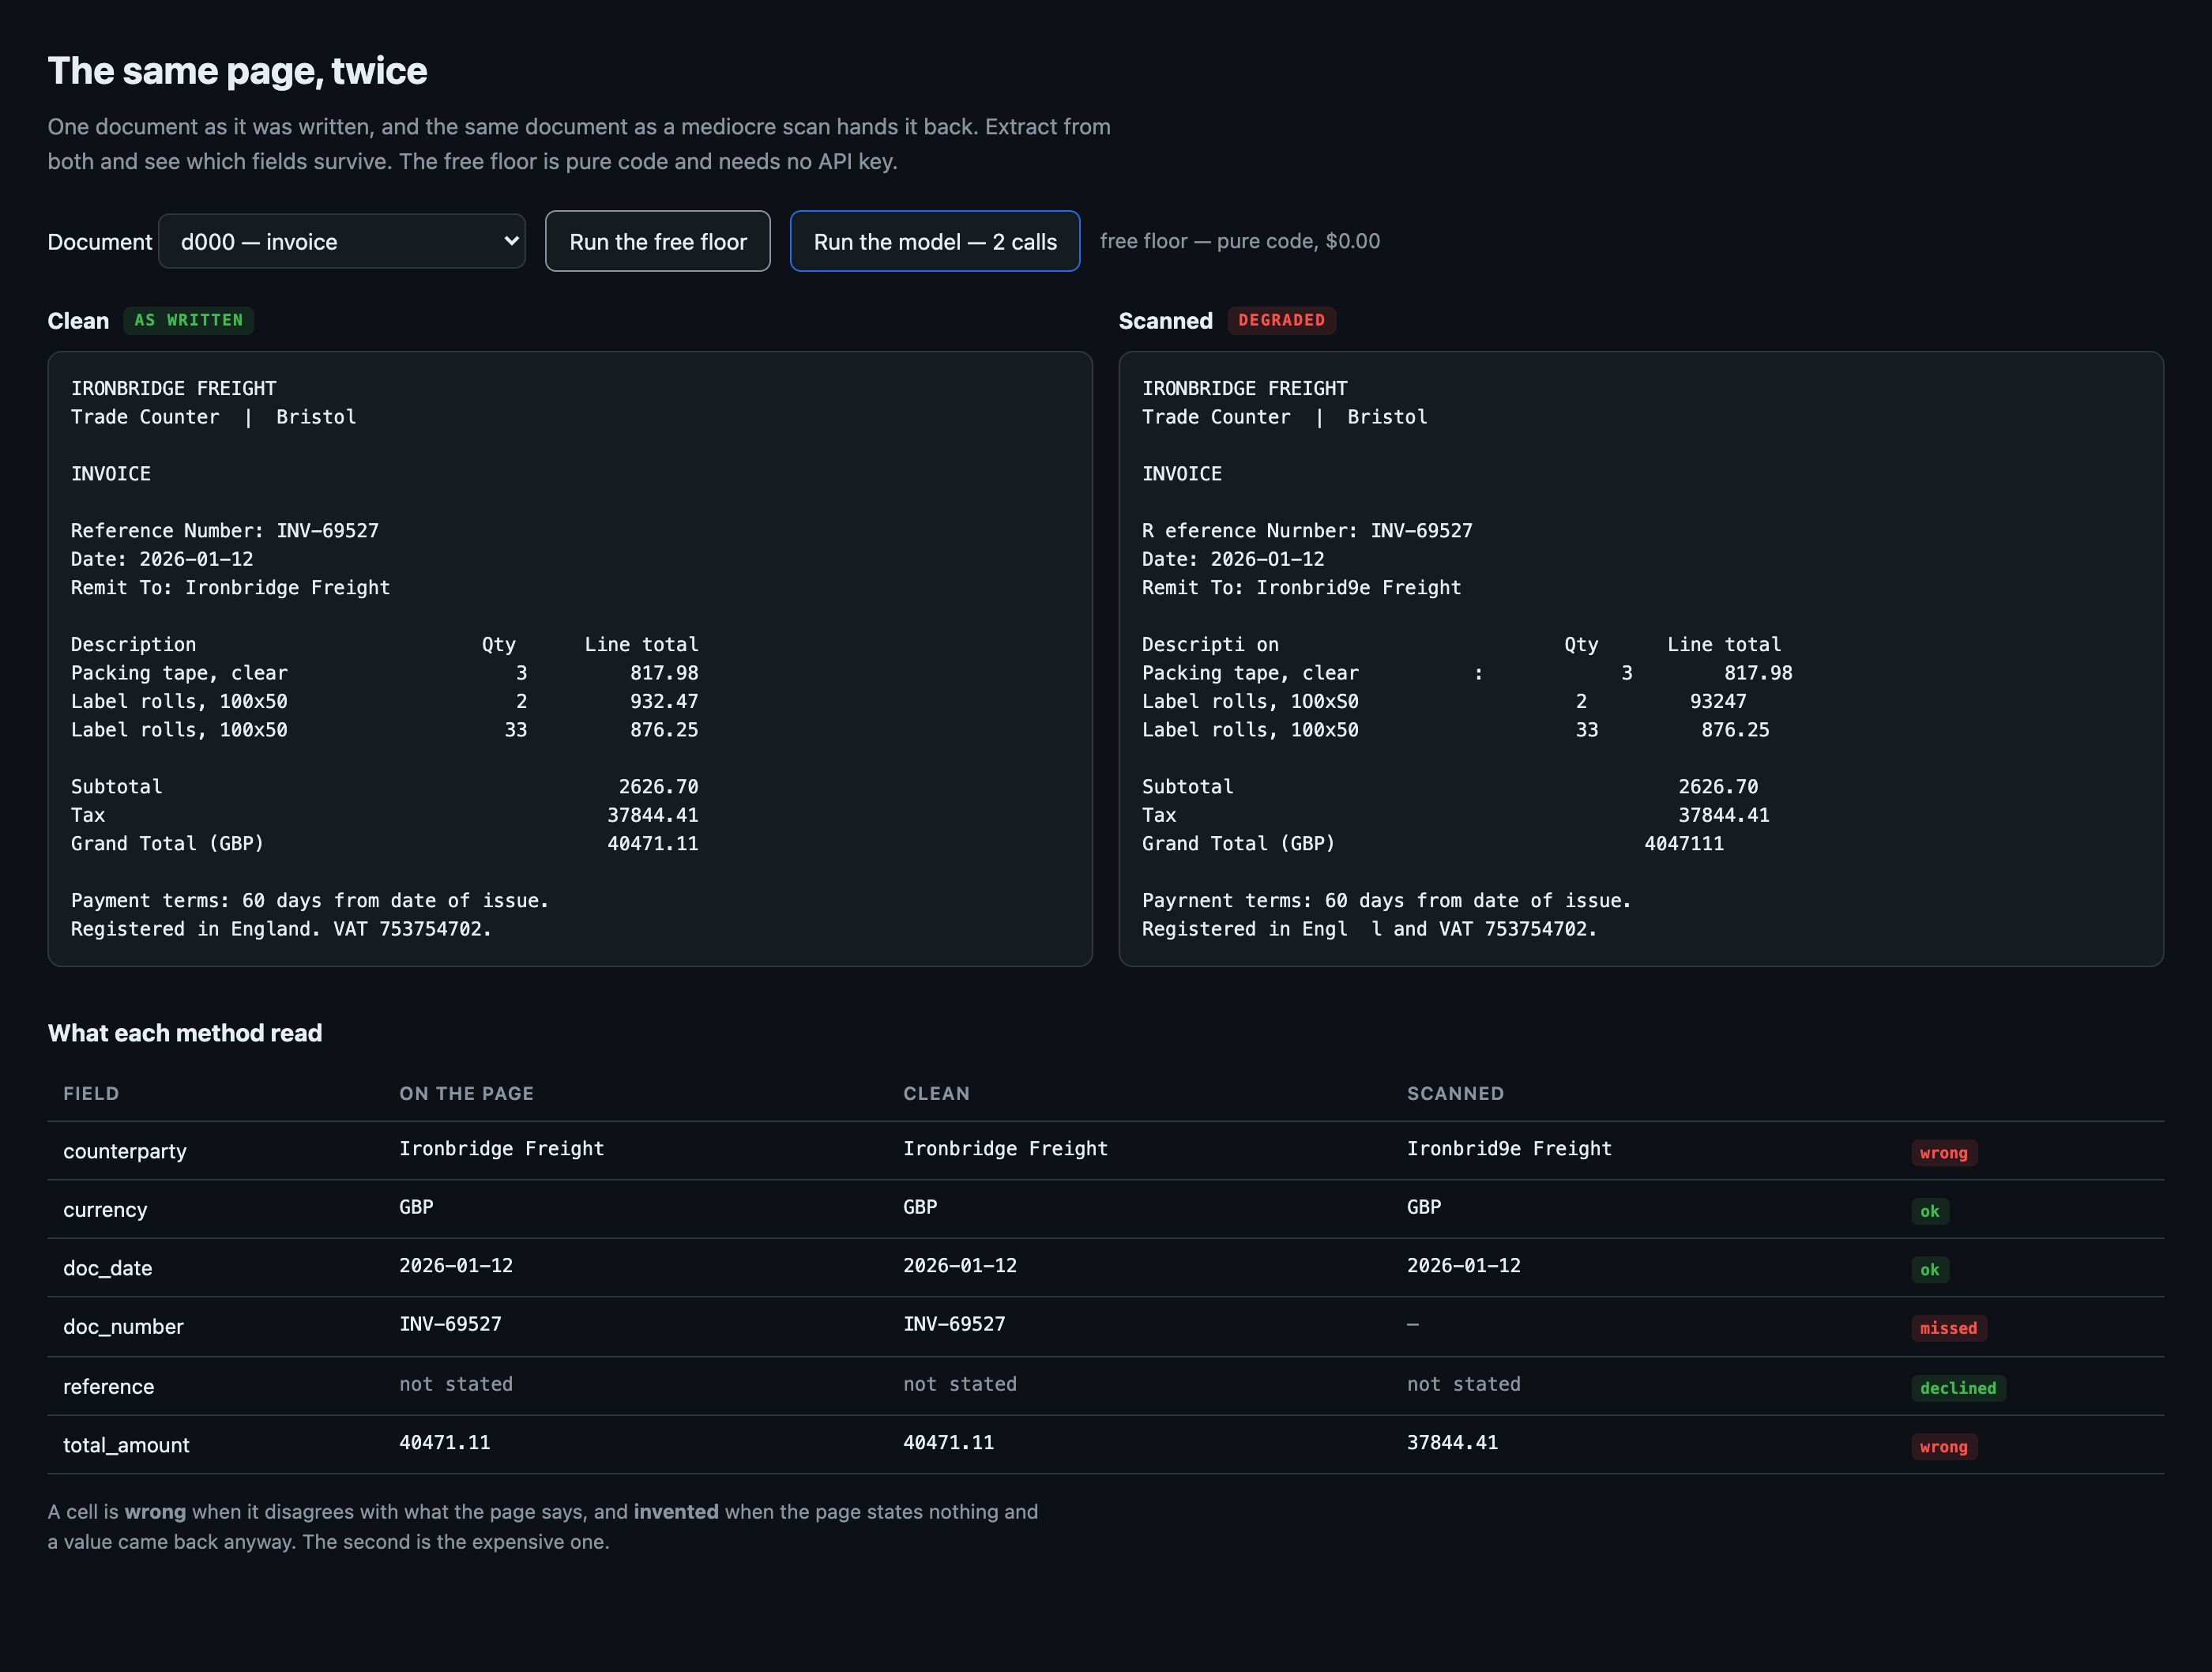
One business document, as the model receives itclean/d000.txt · 1 of 120
IRONBRIDGE FREIGHT
Trade Counter  |  Bristol

INVOICE

Reference Number: INV-69527
Date: 2026-01-12
Remit To: Ironbridge Freight

Description                         Qty      Line total
Packing tape, clear                    3         817.98
Label rolls, 100x50                    2         932.47
Label rolls, 100x50                   33         876.25

Subtotal                                        2626.70
Tax                                            37844.41
Grand Total (GBP)                              40471.11

Payment terms: 60 days from date of issue.
Registered in England. VAT 753754702.
The outcomeWhat a good result looks like
One number per method: how many accuracy points you lose when the input stops being clean. The model loses 11.8. Label-anchored rules lose 26.4.
And when it cannot
Identifiers are where it lands. Document number falls to 73.3% and the reference field to 72.5% — codes have no linguistic redundancy to recover from, so a single confused glyph is a wrong answer.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
Your documents arrive clean and digitally generated — The free rules baseline Rules score 88.2% on clean input for $0.00. The model's 100.0% is better, but that is an 11.8-point gap you are paying for on text that was never damaged.
Your documents arrive scanned, and identifiers matter — The model, plus a check digit or cross-reference on the identifiers The model holds 88.2% on scanned input against the floor's 61.8%, but its document-number field is the weakest at 73.3% — the field you most need to trust degrades most.
You cannot tolerate an invented value — Either — both scored zero inventions Neither method invented a value in either condition. ⚠︎ That rests on 20 not-stated cells, which is the thinnest denominator on this page.
At a glanceHow the whole thing runs
88–100%across runs · 2 runs, no ordering
1,639 msp50, end to end
$0.08per 1,000 field cells · the fast tier
Run twice over the same set, for real, the last on 2026-08-14. Every figure on these pages was captured from those runs — nothing is written from intent.
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Read scanned supplier invoices and know which fields to trust14 steps · 4 questions · run once, for real · 2026-08-14
Every tile is a linkall 14 steps · no step without a page
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
What do I have to bring?
Drop your own text files into data/corpus/clean/ and data/corpus/messy/ with matching names, add their answers to data/gold.jsonl, and both methods run unchanged. Corpus lens →
When is this the wrong choice?
Avoid: Paying per document before you have measured what it buys you. That is the case against the best-fitting scenario (“Your documents arrive clean and digitally generated”). 3 scenarios scored in all, each with its own.Eval lens →
Where does it stop working?
Handwriting. Nothing in the corpus is handwritten and the degradation model does not simulate it. 4 recorded failure modes, each from a run rather than a guess.Corpus lens →
What was never verified?
The refusal rates rest on 20 not-stated cells per condition. 100% there means 20 of 20, which is not a strong claim. 5 items this kit says it could not check.Eval lens →
Can I run this on a model I control?
Yes — any OpenAI-compatible endpoint, including one on your own hardware. The shipped adapter takes its host from BASE_URL and its model from MODEL, so nothing in src/ changes. The published figures come from 1 model on the fast tier, one provider, one key. Prompt lens →
And if it fits — what do I stand up?
5 artifacts with a stated home and a stated egress, and 3 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one.step 14 — Run it in your environment →
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-08-14 — r001-clean + r002-messy. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — git clone, then python3 tools/build_corpus.py && python3 evals/baseline.py clean && python3 evals/baseline.py messy. No dependencies, no key, ~3 seconds, and you have the free floor's half of the result.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
Step 01 of 14Business case
Written for: product manager · Measured during the eval run. Never estimated, never quoted from a vendor page.
In brief
100.0%rows answered
1,639 msp50, end to end
2,079 msp95
5 minclone to first result
What the clock covers. model call only, one per document, scanned condition
Current processWhat it replaces
A hand-check of every scanned document, or the unexamined assumption that the extractor which scored well in the demo will hold up on the post room's output.
Where it is not good enough
88.2% on scanned input is not good enough to post entries unattended. It is good enough to triage: the fields that survive (currency 100.0%, total 91.7%) can flow, and the identifiers cannot.
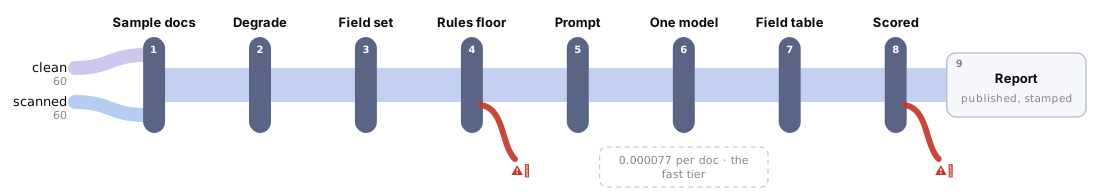
One question, end to end. Colour on the fan-in is the corpus format; a red hook marks every station with a recorded failure, and the words — every sub line, failure and report field — are in the ledger beneath. Every station is a link — click one to jump to its row, and each row links to the lens that explains it.
⚑ THE MODEL READING A SCAN (88.2 pct) IS AS ACCURATE AS THE RULES READING A PERFECT PAGE (88.2 pct). Neither method invented a value — 0 across all four cells, over 20 not-stated cells each. The model half also lost 9 of 60 calls with the provider's reasoning pass ON, billed in full for an empty body; that run is kept as r000 and the published pair has it off.
⚠︎ The scanned condition is a SIMULATION of scanner damage, not output from a real scanner.
The swap seams
Seam
File
What changes
The degradation model
src/corpus.py
How badly the scan damages the page, and in which ways.
The free floor
evals/baseline.py
What the model is being compared against.
The prompt
src/prompt.py
Which fields are extracted.
The provider
src/adapters/
Any OpenAI-compatible endpoint, or Anthropic.
The scorer
evals/score.py
What counts as correct.
Components
Component
File
Role
Corpus generator
src/corpus.py
Writes 60 documents and their ground truth from a fixed seed, then emits each one twice — clean, and degraded by a documented set of OCR error classes.
Free floor
evals/baseline.py
Label-anchored rules with glyph un-confusion. Pure code, no key, and the honest half of the comparison.
Extractor
evals/run.py
One model call per document, the same prompt in both conditions.
Scorer
evals/score.py
One scorer for both methods, splitting stated cells from not-stated cells so a misread is never averaged with an invention.
Where it breaks at scale
One call per document with no batching. At 60 documents that is under two minutes; at 60,000 it is a queue, and the per-call latency of ~1639ms p50 becomes the whole design problem.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
Step 03 of 14App UI
Written for: anyone, in 5 seconds · Screenshots of the running app taken during the run.
SuccessesWhen it works
The same document in both conditions, with what the free floor read from each.successOpen full size →
LimitsWhen it does not
A report showing only wins is an advert. This one is required, and the validator now refuses a kit that omits it.
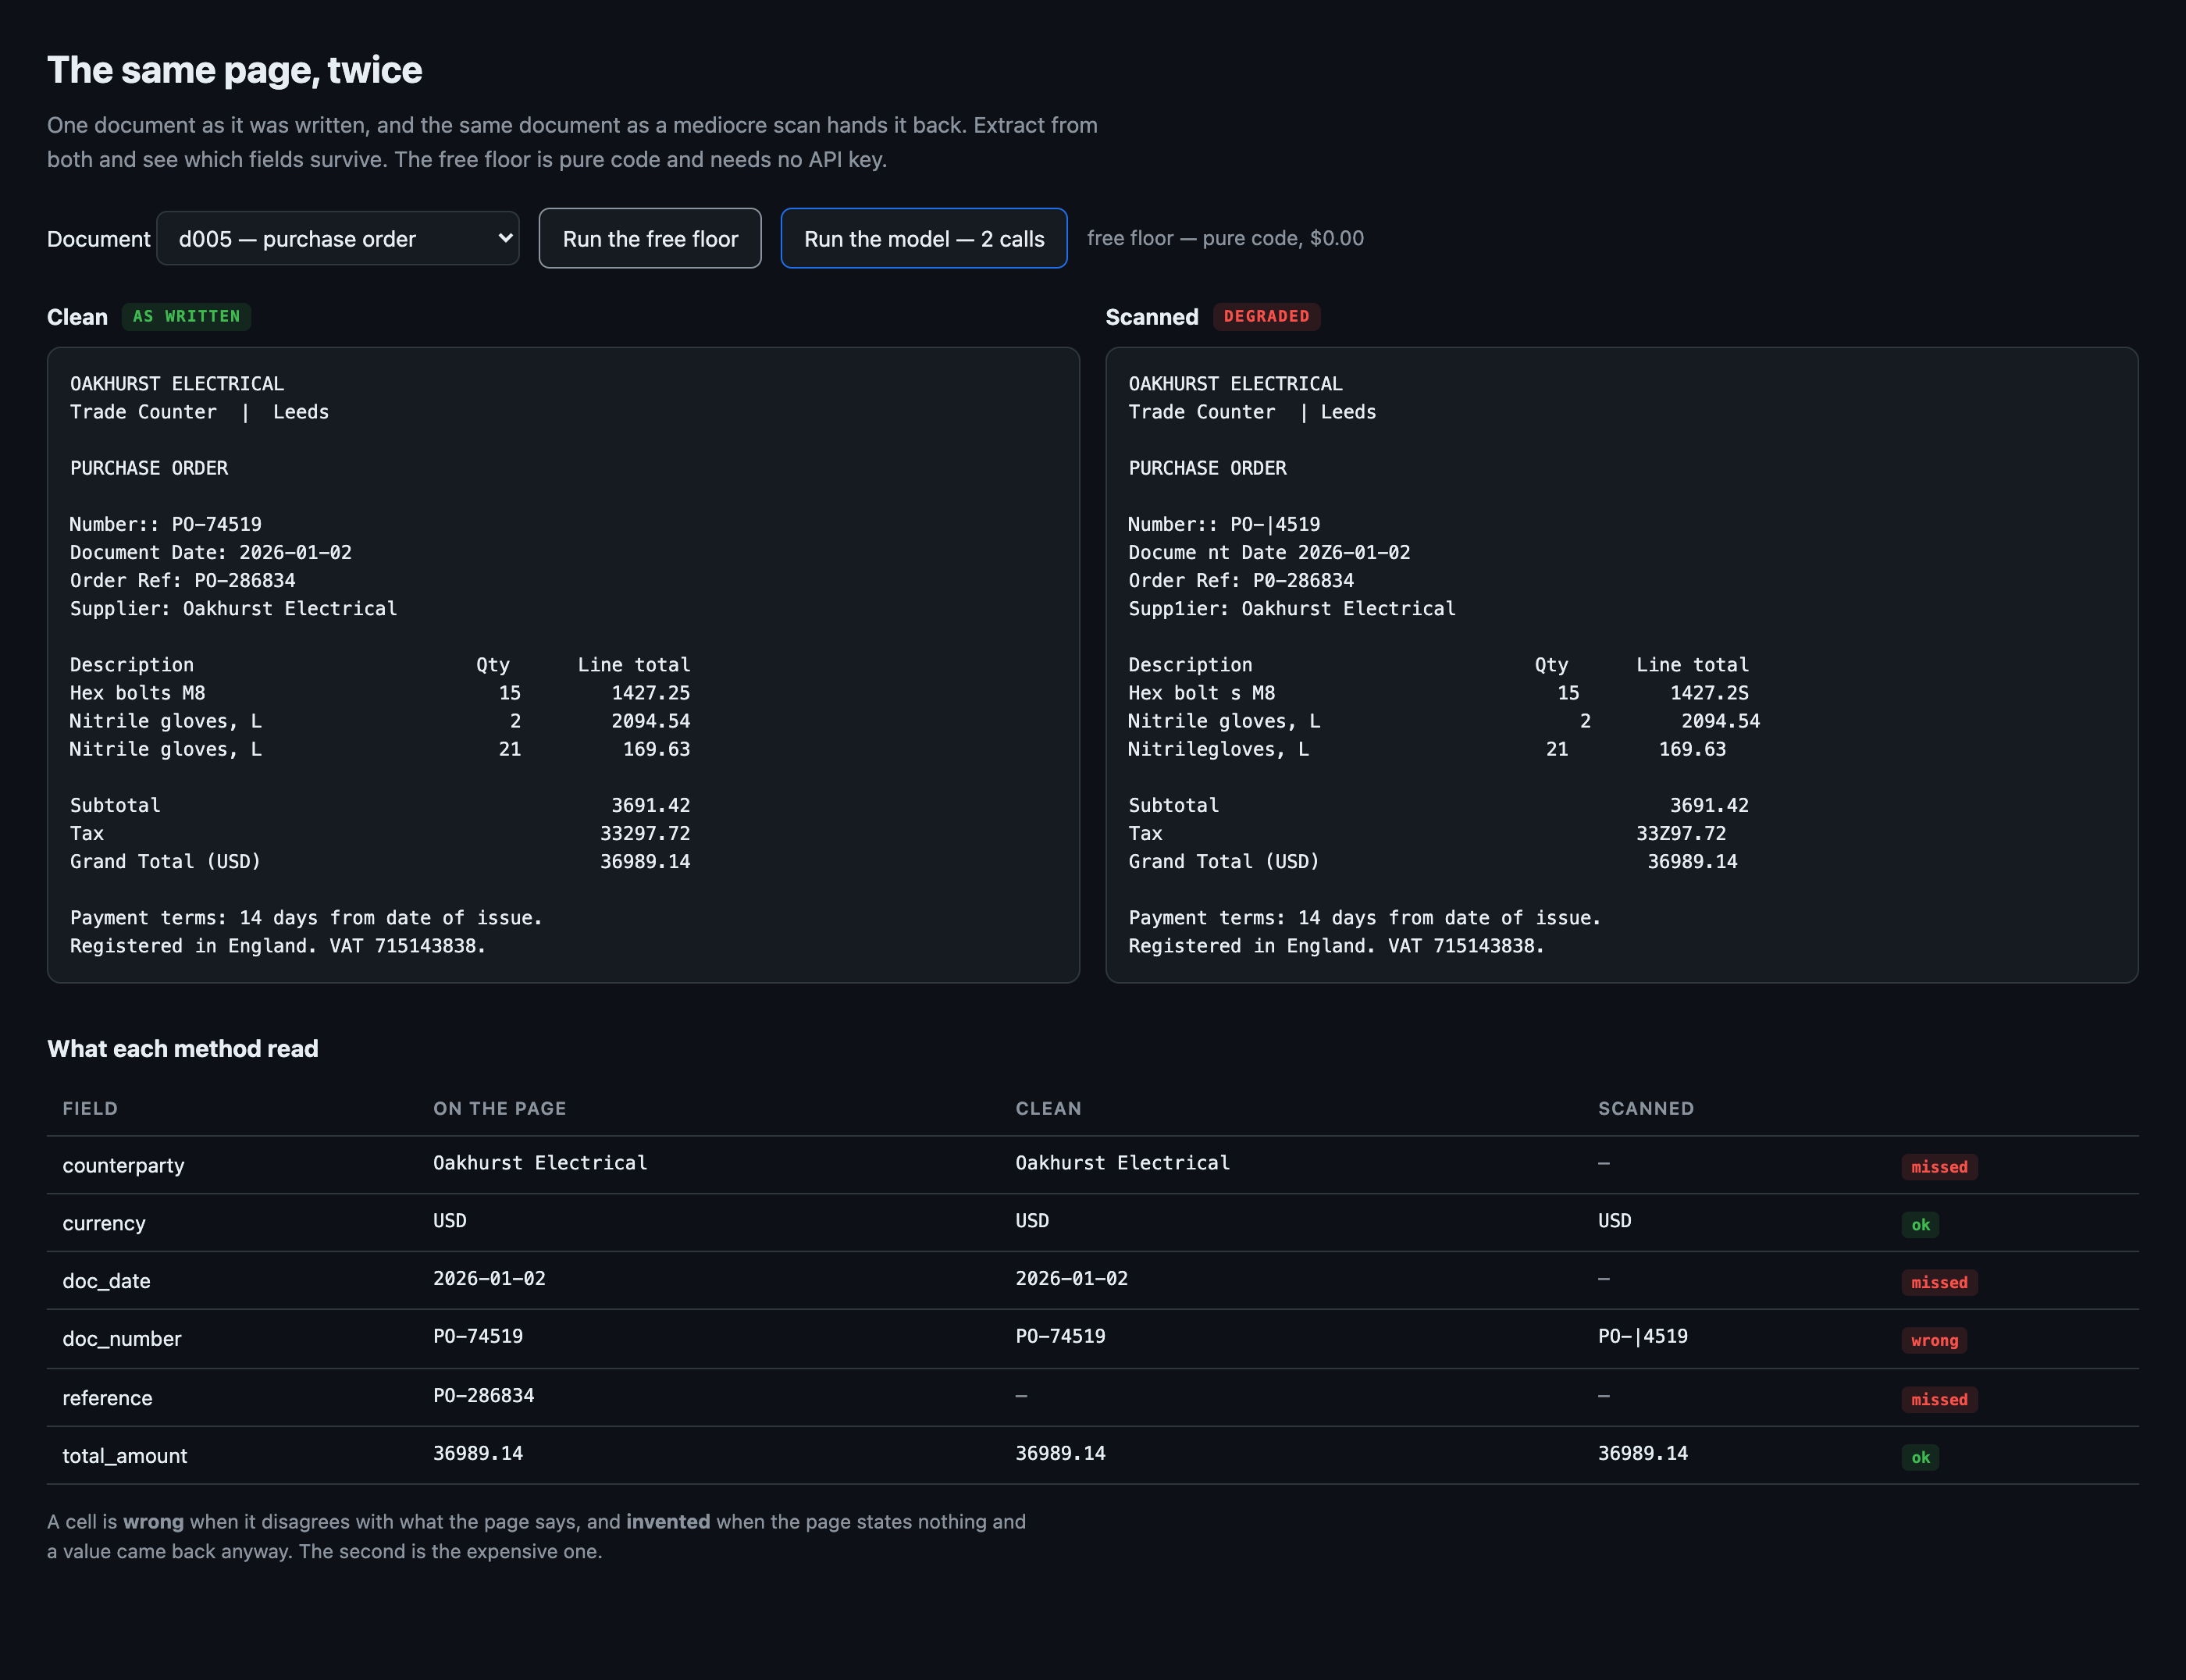
d005 as a scan: PO-74519 became PO-|4519, 'Document Date' became 'Docume nt Date', 2026 became 20Z6 and 'Supplier' became 'Supp1ier'. The free floor misses the counterparty, the date and the reference, and gets the number wrong — while the currency and the total survive intact.failureOpen full size →
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
Step 04 of 14Corpus
Written for: "can I point this at mine?" · Measured off the corpus the run actually used.
In brief
120business documents
0.08 MiBtxt 120
60documents · p50 0 chars
$0.00setup · 0.0s
How it is cutWhat one document is
No split — nothing is fitted. Every document is scored in both conditions.
size_p50/p95 are 0 because there is no segmentation: each document is passed whole. Recorded as an explicit zero rather than omitted, so the absence is a decision and not a missing key.
SetupWhat the setup figure measured
There is no index. The kit does not retrieve — each document is passed whole to one call. Corpus preparation is generation, not indexing: tools/build_corpus.py writes 120 files from a fixed seed in under a second, with no model and no key.
LicenceLicence
MIT. Granted by us because we wrote every byte of it — the generator is in the kit and its output is a pure function of seed 20260814. Nothing is derived from a third-party corpus, so there is no upstream licence to honour and no attribution owed. Verified 2026-08-14 by rebuilding from a clean tree and diffing byte for byte (tools/build_corpus.py --verify).
Bring your ownBring your own business documents
Drop your own text files into data/corpus/clean/ and data/corpus/messy/ with matching names, add their answers to data/gold.jsonl, and both methods run unchanged. If you have real scanned documents with ground truth, that is the single most valuable thing you can contribute here — it replaces the simulation this kit is honest about being.
What breaks it
Handwriting. Nothing in the corpus is handwritten and the degradation model does not simulate it.
Multi-column layouts and tables that wrap across pages. The column-bleed class simulates a fragment of a neighbouring line, not a genuine two-column read order.
Photographs rather than scans. A page shot at an angle has geometric distortion this corpus contains none of.
Any language the label list does not cover — ANCHORS in evals/baseline.py is English only, so the free floor collapses entirely on a non-English page while the model may not.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
Step 05 of 14Prompt
Written for: engineer · Logged from the run, verbatim.
In brief
The assembled prompt in full, and its real decomposition. Every part below occurs in the prompt that was actually sent, and the token counts sum to the recorded input total — they were measured against the provider’s own counter, not apportioned by character share.
AssemblyHow the prompt is assembled
Part
Characters
Tokens
The task, the field shape and the not-stated rule
957
257
The document, whole
604
142
Total
399
This is the cost lesson as arithmetic: of the 399 tokens assembled, 257 are instructions — 64% of the prompt, the largest single part. A per-request bill follows whichever part is biggest, and on this kit that is the one named here.
Measured by prefix subtraction against the provider's own tokenizer (evals/prompt_tokens.py, 2 calls at max_tokens=1) on document d000, not estimated from characters.
Full promptThe prompt in full
The verbatim prompt, as sent
the prompt, as sent
Read the document below and return this JSON object:

{
  "doc_number": null,   // Document number The document's own identifier, not any other reference on the page.,
  "doc_date": null,   // Document date ISO format, YYYY-MM-DD.,
  "total_amount": null,   // Total amount due The final total, not the subtotal and not a line total. Digits only, two decimals.,
  "currency": null,   // Currency Three-letter ISO code.,
  "counterparty": null,   // Counterparty The organisation that issued the document.,
  "reference": null,   // Purchase-order or customer reference Often absent. If the page does not state one, say so rather than guessing.
}

Rules:
- Copy values as the document states them. Do not reformat except where a field says to.
- If the document does not state a field, return null for it. Do not guess, and do not
  substitute a similar-looking value from elsewhere on the page.
- Return the JSON object and nothing else.

DOCUMENT
--------
IRONBRIDGE FREIGHT
Trade Counter  |  Bristol

INVOICE

Reference Number: INV-69527
Date: 2026-01-12
Remit To: Ironbridge Freight

Description                         Qty      Line total
Packing tape, clear                    3         817.98
Label rolls, 100x50                    2         932.47
Label rolls, 100x50                   33         876.25

Subtotal                                        2626.70
Tax                                            37844.41
Grand Total (GBP)                              40471.11

Payment terms: 60 days from date of issue.
Registered in England. VAT 753754702.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
Step 06 of 14Evals
Written for: the skeptic · The harness output, with as_of / model version / dataset version / verified_by.
In brief
Read scanned supplier invoices and know which fields to trust — 720 field cells drawn from 120 real business documents. One model answered, and every answer was then graded one way — by == against a fixed gold value, which is a measurement too and only as good as the gold behind it.
The rulerHow it was graded
Exact match after a normalisation applied identically to gold and prediction (whitespace, trailing punctuation, case; money to two decimals; codes uppercased and de-spaced). The same scorer runs both methods — a comparison whose two sides are scored by two pieces of code is not a comparison.
720field cells
120source documents
1model tier
1grading method
MeasurementsWhat was measured
COUNTED300 · 210 · 340 · 300 / 340extraction accuracy — cells the document states — clean inputDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED20 · 20 · 20 · 20 / 20refusal accuracy — cells the document does not state — clean inputDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
NOT YET KNOWN—A person confirmed the gold is rightThe grader is == and needs no confirming. The gold does: it is machine-derived from the registry's structured modules, and every rate on this page rests on that derivation being faithful to what the prose actually says. Nobody has read a document against its gold record by hand.
Two words carry this page: Counted is deterministic and nobody's opinion and Not yet known is printed blank rather than filled with something plausible. There is no Judged row here and that is the point: nothing on this page is a model's opinion about another model. The row most worth having is currently the empty one.
How the method was validated
The scorer was validated against the free floor on clean input before any model call was made: the rules extractor scores 88.2% there, and every one of its misses was read by hand and confirmed to be a genuine label-wording miss rather than a normalisation artifact. The refusal half was validated the same way — the 20 not-stated cells were checked to contain no value anywhere on the page.
Run it twiceThe same set, run again
Run date
the fast tier
2026-08-14 r001-clean
100.0% r001-clean
2026-08-14 r002-messy
88.2% r002-messy
—
Grading costWhat it costs
Every dollar here is a MEASURED token count multiplied by a named vendor's PUBLISHED rate, read from build/facts/models.json.
Priced at
Per 1M in / out
One field cell
1,000 field cells
Share that is the prompt
the fast tier the tier this kit was actually run on — one model, one key
$0.14 / $0.28
$0.000076
$0.08
77%
Same work, 1× the bill
The same field cells, the same tokens — only the rate card changed. And on that card about 77% of what you pay is the prompt this pipeline sends, not the answer it writes.
Turning the provider's reasoning pass OFF cut output from 279 tokens per call to 63 — a 4.4x reduction — and took the failure rate from 9 in 60 to 0. See r000-clean-thinking-on, kept as the evidence.
Rates checked 2026-07-17.
Grading unitWhat the grading figure prices
freegrading cost, as measured
The GRADER is free: exact match after a shared normalisation, pure code, no model in the scoring loop. Re-scoring the committed run records costs $0.00 and a fresh clone can do it with no key at all. The model calls that produced the answers are the system under test, not the evaluation of it — those are priced per document in the Cost lens.
The gradersOne way to grade, and why it is the only one
It scores 88.2% clean and 61.8% messy. The model reading a SCAN (88.2%) is as accurate as the rules reading a PERFECT page (88.2%).
Grader
Cost / 1k
Data leaves
Same answer twice
Result
Per-field exact match, both conditions Is this cell's value the one the page states — or, where it states nothing, did the method correctly return nothing?
$0.00
no
yes
no headline metric on any of its 4 runs — they record condition · extraction accuracy · refusal accuracy · hallucinations
The row opens its own page: how the test was run, one real row, the formula with every iteration of it, and the analysis.
Why this set cannot separate them
The four cells separate cleanly: 88.2 / 61.8 for the rules and 100.0 / 88.2 for the model. The gap between methods on messy input is 26.4 points, well outside anything 60 documents could produce by chance.
Choosing oneWhen to reach for the model at all
The comparison is only useful if it ends in a choice, and on this kit the choice is not which grader — there is one, and it is ==. It is whether to call a model for this field at all, and the answer is conditional.
If your situation is
Use
Because
And avoid
Your documents arrive clean and digitally generated
The free rules baseline
Rules score 88.2% on clean input for $0.00. The model's 100.0% is better, but that is an 11.8-point gap you are paying for on text that was never damaged.
Paying per document before you have measured what it buys you
Your documents arrive scanned, and identifiers matter
The model, plus a check digit or cross-reference on the identifiers
The model holds 88.2% on scanned input against the floor's 61.8%, but its document-number field is the weakest at 73.3% — the field you most need to trust degrades most.
Trusting an extracted document number straight into a ledger
You cannot tolerate an invented value
Either — both scored zero inventions
Neither method invented a value in either condition. ⚠︎ That rests on 20 not-stated cells, which is the thinnest denominator on this page.
Reading the 100% refusal rate as a strong claim
This pipeline was also attacked, which is a different question from whether its answers are right: see Threat model for the injection experiment, its two gates and what it does not prove.
Failure causesHow it fails
Cause
What it means
Rows
A real example
glyph-confused-identifier
a confused glyph inside an identifier
16
d005 — the page says PO-74519 and the scan reads PO-|4519, the 7 read as a speckle. Identifiers carry no linguistic redundancy, so one confused character is a wrong answer with nothing to recover from. Document number is the model's worst field at 73.3%.
label-damaged-value-orphaned
the label broke, so the rules lost the value
40
'Order Ref: : PO-171741' — the free floor returns nothing for the reference field on 40 of 40 scanned documents, scoring 0.0%. It does not invent one: it only emits a value when a well-formed code matches.
survives-the-scan
fields the damage does not reach
60
Currency is read correctly on 60 of 60 scanned documents by the model and the total on 55 of 60. Three letters with heavy context redundancy, and a number that appears several times on the page, are the easiest things on a damaged document.
What we could NOT verify
⚠︎ THE SCANNED HALF IS A SIMULATION. Every error class in src/corpus.py is one OCR demonstrably makes, and the rates land the corpus at a 2.6% character error rate — but no real scanner or OCR engine was involved. Nothing here is measured against real scans, and that is the single largest caveat on this kit.
The refusal rates rest on 20 not-stated cells per condition. 100% there means 20 of 20, which is not a strong claim.
Neither run was repeated, so run-to-run variance is unmeasured.
Only one model tier was run. Nothing here argues a larger model would not close the scanned gap — it was not tried.
No prompt-injection resistance was measured; the self-authored corpus contains no attack.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
Step 07 of 14Unit cost
Written for: whoever signs off on the bill · Measured over the eval run, per model. Never quoted from a vendor page.
In brief
Tier
Input tokens
Output tokens
p50 latency
the fast tier
the fast tier
416.5
62.9
1,794 ms
$0.000076
the fast tier
426.1
63.4
1,639 ms
$0.000077
the free floor
0
0
0 ms
$0.000000
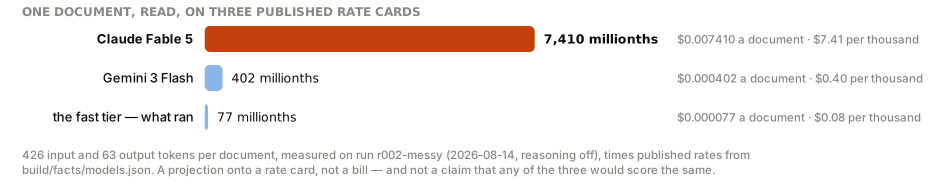
The token counts are measured on a real run and belong to this pipeline — which sections are selected, the field schema, the prompt — so they hold wherever you run it. The dollars are those counts multiplied by each vendor's published rate, checked 2026-07-17. Nobody paid these particular bills; they are what the same work would cost you on a card you can sign up to today.
Identical work in both rows — the same query, the same tokens. Only the price list changed. Which is why the token count is the measurement and the dollar is arithmetic you can redo on your own card.
Answering vs gradingGrading is free here, and it is a measured zero
ZERO, AND A MEASURED ZERO RATHER THAN AN UNPRICED ONE. evals/score.py makes no call and needs no key: grading all 720 cells costs a forker nothing, and the free floor that supplies half the comparison costs nothing either. A fresh clone reproduces the rules half of this page — both conditions — with no API key at all.
Cost driversWhat actually moves the bill
Input is the INSTRUCTION, not the document — 257 of 399 tokens on a typical page. That is the opposite of the retrieval kits, where context dominates: cut the field hints and you cut most of the input bill.
One call per document, so cost scales linearly with corpus size. No batching, no caching.
Output is small and stable at ~63 tokens because the reply is a six-field JSON record — but only with the provider's reasoning pass disabled. With it on the same reply cost 279.
A scanned page costs marginally MORE than a clean one: the damage adds tokens, it does not remove them.
Your volumeWhat it costs at your volume
600 documents in both conditions is 1,200 calls at $0.000077 — about $0.09. The cost is linear; there is no batching and no caching.
Where pricing changes shape
max_tokens=700 is a cliff, not a ceiling. With reasoning enabled, 9 of 60 calls reached it, were billed in full and parsed to nothing — the most expensive outcome a call has. Disabling reasoning took that to 0 of 60 and cut output 4.4x.
No context-length cliff is anywhere near: ~400 input tokens against a 1M context.
Your return, with your numbers
Volume
What it replaces
Time saved per item
We publish the inputs, not a return: a return depends on your labour cost and your volume. The ROI dashboard takes it from here, and AI Costing explains the math.
Model choiceWhy this model
One model, one key — the kit standard. The fast tier was chosen because the task is short-form extraction with a fixed schema, and it reached 100.0% on clean input. Nothing here argues a bigger model would not do better on the scan; it was not run.
Other modelsThe same 120 calls, on other models
This is arithmetic, not a run. No model below was executed against the labelled set, and no accuracy is claimed for any of them. What transfers is the input volume: retrieval is model-independent, so every model would receive the same passages.
50,553input tokens · this run
7,581output tokens
$0.009what it actually cost
Both scored runs — 60 clean and 60 scanned. It excludes the 3-call probe, the 2-call token measurement, and the abandoned reasoning-on run, all of which are on the ledger but not in the published pair.
Model
Provider
One eval pass
This whole run
Per 1,000 queries
Rates as of
gpt-5-6-luna
OpenAI
$0.019
$0.019
$0.16
2026-09-12
gemini-3-flash
Google
$0.048
$0.048
$0.40
2026-09-18
gemini-3-8-flash
Google
$0.066
$0.066
$0.56
2026-09-18
claude-haiku-4-5
Anthropic
$0.088
$0.088
$0.74
2026-09-12
llama-5
Meta
$0.095
$0.095
$0.80
2026-09-18
grok-4-5
xAI
$0.146
$0.146
$1.23
2026-09-18
grok-4-6
xAI
$0.146
$0.146
$1.23
2026-09-18
claude-sonnet-5
Anthropic
$0.176
$0.176
$1.48
2026-09-12
gemini-3-1-pro
Google
$0.191
$0.191
$1.61
2026-09-18
gpt-5-6-terra
OpenAI
$0.191
$0.191
$1.61
2026-09-12
gpt-5-6-sol
OpenAI
$0.353
$0.353
$2.96
2026-09-12
claude-opus-4-8
Anthropic
$0.441
$0.441
$3.71
2026-09-12
claude-opus-5
Anthropic
$0.441
$0.441
$3.71
2026-09-12
claude-fable-5
Anthropic
$0.882
$0.882
$7.41
2026-09-18
claude-fable-5-1
Anthropic
$0.882
$0.882
$7.41
2026-09-18
gpt-6-astra
OpenAI
$0.882
$0.882
$7.41
2026-09-17
Read this against the numbers above
A projection, not a bill. Nothing here was run on any model but the fast tier, and a cheaper model scoring the same is an assumption, not a finding.
Output is small and stable on this task (~63 tokens), so models are separated here almost entirely by their INPUT rate — which is unusual and will not hold for a task with longer replies.
Rates are as of the dates in each row and go stale the moment a vendor reprices.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
The codeEvery file, and what it is for
Four modules, no framework, and almost no dependencies. The pipeline is stdlib Python, because a kit is meant to be read and changed by someone who cloned it ten minutes ago — every dependency is a thing they have to understand before they can touch the part they came for.
Five of these are swap seams: the points you edit to make the kit yours. Each is marked, and each block below is the module’s real shape, read out of the file rather than written here.
The files on this page are not in the public GitHub catalog.
src/corpus.pyCorpus generator — a swap seam
Writes 60 documents and their ground truth from a fixed seed, then emits each one twice — clean, and degraded by a documented set of OCR error classes.
You change it to: How badly the scan damages the page, and in which ways.
src/corpus.py
# The corpus: sixty one-page business documents, each emitted twice — clean, and degraded.

SEED = 20260814
N_DOCS = 60
CURRENCIES = ["USD", "EUR", "GBP"]
KINDS = ["INVOICE", "PURCHASE ORDER", "REMITTANCE ADVICE", "STATEMENT OF ACCOUNT"]
VENDORS = [
LABELS = {
ITEMS = [
def _money(rng):
def _date(rng):
evals/baseline.pyFree floor — a swap seam
Label-anchored rules with glyph un-confusion. Pure code, no key, and the honest half of the comparison.
You change it to: What the model is being compared against.
evals/baseline.py
# The free floor: label-anchored rules over whatever text layer you were handed. No model, $0.00.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
ANCHORS = {
UNCONFUSE = str.maketrans({"O": "0", "o": "0", "l": "1", "I": "1", "S": "5", "B": "8", "|": "1"})
MONEY = re.compile(r"(\d[\d,]*\.\d{2})")
DATE = re.compile(r"(\d{4})[-/ ](\d{1,2})[-/ ](\d{1,2})")
CODE = re.compile(r"\b([A-Z]{2,4})[-\s]?(\d{4,6})\b")
CCY = re.compile(r"\b(USD|EUR|GBP)\b")
def _label_value(text, names):
def extract(text):
evals/run.pyExtractor
One model call per document, the same prompt in both conditions.
evals/run.py
# The model run. One call per document, one condition per invocation.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
MAX_TOKENS = 700
def parse(text):
def main(argv):
evals/score.pyScorer — a swap seam
One scorer for both methods, splitting stated cells from not-stated cells so a misread is never averaged with an invention.
You change it to: What counts as correct.
evals/score.py
# One scorer, used by the free floor and the model alike.

def load_gold(root):
def load_fields(root):
def norm(key, v):
def score_all(gold_rows, preds, fields):
Start hereThe shortest path into it
src/corpus.pyWrites 60 documents and their ground truth from a fixed seed, then emits each one twice — clean, and degraded by a documented set of OCR error classes. A swap seam.
evals/baseline.pyLabel-anchored rules with glyph un-confusion. Pure code, no key, and the honest half of the comparison. A swap seam.
evals/run.pyOne model call per document, the same prompt in both conditions.
evals/score.pyOne scorer for both methods, splitting stated cells from not-stated cells so a misread is never averaged with an invention. A swap seam.
Every entry above is a file in this kit, listed in the order the pipeline runs it.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
ScenariosWhat it costs at your volume
Everything below is computed from one measured base: 426 input and 63 output tokens per query, all of it fixed — this kit sends the document's own selected sections, so there is no retrieval depth to turn. Change the volume and the bill scales linearly, because nothing here batches.
Grading really is free here, and that is a property of the ruler rather than a discount
This kit is graded by pure code — the grader makes no model call, needs no key and sends nothing anywhere, so the grading line above is zero at every sampling rate and the leak count stays at nought. What that buys is a ruler you can run on every row, every time, for nothing. What it costs is reach: a code grader can only check what is mechanically checkable.
OperationsFour shapes of workload
The same arithmetic, at volumes worth naming. These are illustrations of scale, not measurements of anyone’s deployment.
Shape
Querys/day
Per day
Per month
Per year
Model follows the controls above.
What this ignoresWhere a real bill diverges
Read before quoting any of it
Output length is assumed constant.A terser or more verbose model moves it, and output is priced above input everywhere.
No volume, committed-use, batch or cache discount is modelled.Each moves real enterprise pricing and none are on a public rate card.
Longer documents cost more and nothing here caps them.This kit selects the document’s own sections in pure Python, so there is no vector store to price — but a corpus of longer records raises the input tokens per query directly, and that is the very number every figure above multiplies.
Grading adds nothing to this bill, and would if you changed the ruler.A code grader is free and local; swapping in an LLM judge would cost more per row than the extraction itself and send every row to a vendor. The instrument is a cost decision, not a footnote.
Rates age.Every one carries the date it was read on the cost page.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
In one lineWhat this kit exposes
A document is untrusted input. It is inserted into the prompt as data, and nothing the model returns is executed, evaluated, or used to build a path or a query. The reply is parsed as JSON and every value is a string that gets compared to a ground-truth string. There is no tool call, no shell, no database and no network egress beyond the single provider request.
The key is read from .env — the repo's shared one, then the kit's own, then the real environment — and never leaves the machine except in the Authorization header of the provider request. .env is gitignored from the first commit. ⚠︎ THE SHARED .env MEANS A BRAND-NEW KIT WITH NO .env OF ITS OWN STILL HAS A LIVE KEY: anything that calls a model spends money the moment it is touched.
The experimentWhat was actually run
Both conditions, both methods, one pass each. 120 model calls, 120 free-floor extractions, one scorer. Measured on 2026-08-14, runs r001-clean and r002-messy: 60 documents in two conditions, 120 live calls on one model. The structural gates below are code-checked; no injection rate is claimed, because none was measured.
What you would do
What it does to the input
What it holds, measured
Treat the document as data, never as instruction
The page is interpolated into the prompt below a fixed instruction block. Nothing in it is parsed as a directive by the kit.
Unmeasured here. This corpus is self-authored and contains no injection attempt, so the kit has never been asked to resist one — see could_not_verify.
Never execute or evaluate a returned value
Values are compared as strings. There is no eval, no shell, no SQL and no file path built from model output.
Holds by construction — there is no execution path to reach.
Refuse rather than invent
The prompt tells the model to return null for a field the page does not state. Measured: 20 of 20 not-stated cells correctly left empty on scanned input, 0 inventions.
Held at 100%% on both conditions and both methods. ⚠︎ Over 20 cells, which is a thin denominator.
Record a broken reply as a failure, not as an empty answer
An unparseable reply is recorded in failures with its finish_reason and body. It is not scored as 'returned nothing', which would land in the refusal column and REWARD the run for breaking.
Exercised for real: r000-clean-thinking-on lost 9 of 60 calls and every one is on the record with its finish_reason.
Three of the four hold by construction rather than by a check that could fail. That is a weaker claim than a measurement and it is stated as such.
The resultThe kit reads documents and returns six fields. It never executes anything it reads, and the only thing it sends anywhere is the page you point it at.
120documents, in two conditions
360cells scored per condition
120model calls, scored runs
0inventions, all four cells
Every cell scored in both conditions by both methods.
The one thing worth reading twice
The expensive failure on a damaged page is not a misread — it is an invention. A wrong total is visible to anyone who looks; a purchase-order number that was never on the page looks exactly like a real one. Both methods scored 0 inventions here, and the rules baseline scored 0 for a reason worth knowing: it only emits a value when a well-formed code matches, so on a damaged page it returns nothing rather than the noise that followed the label.
HonestyWhat this does not prove
No prompt-injection resistance was measured — the corpus contains no attack.
The refusal gate rests on 20 not-stated cells per condition. 100%% there means 20 of 20, which is not a strong claim.
Neither run was repeated, so run-to-run variance is unmeasured.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
In one lineThe only guardrail is the prompt
One instruction, no enforcement. It mostly holds — and mostly is the whole subject.
the guardrail, verbatim
Do not accept an extracted identifier from a scanned page without a check digit, a cross-reference, or a human eye. Everything else on the page survives the scan well enough to flow.
At the point the extracted record is written to whatever system consumes it.
EvidenceDoes it hold?
What
Measured
Currency survives the scan
yes — 60 of 60 scanned documents read correctly by the model
The total survives well enough to triage
yes — 55 of 60, 91.7%
The document number does NOT
yes — 44 of 60, 73.3%. This is the field that needs the gate.
Neither method invents a value
yes — 0 inventions across all four cells, over 20 not-stated cells each
The limitWhat a guardrail is not
Not an OCR engine, and not a replacement for one.
Not a check that the document is genuine, or that the numbers on it are right.
Not a gate — it produces the evidence you would set a gate from.
WatchedWhat is watched, and why that one
4runs recorded
0 / 0deterministic metrics exact
+0.0%largest move — latency
0band breaches
—model half · needs provider URL
The kit measures 23 watched figures plus 8 comparability guards and 5 reference constants — three duties, not one list. 0 of the watched are grader rates, each on its own grader page; this board watches the ones that decide when to look again. Each square is one watched figure; filled means the latest run measured it.
7 measured by the latest run16 need the model half
Metric
Owner
Role
Why this one
invented values
per-field exact match
alarm
a count, not a rate — one more is one claim nobody on the receiving end can check
extraction accuracy, scanned
per-field exact match
alarm
the number this kit exists to report; it moves when the scan quality moves
document number accuracy
per-field exact match
alarm
the weakest field at 73.3%, and the one a ledger cannot tolerate being wrong
call yield
the run harness
watch
an empty body at the output ceiling is billed in full and yields nothing
extraction accuracy, clean
per-field exact match
watch
the control — if this moves, something other than legibility changed
GuardsBefore any comparison
Preconditions, not alarms. If one moves, the runs were not measuring the same system and nothing else on this board may be differenced.
Guard
Value
If it moves
corpus.doc_count
120
different corpus — nothing is comparable
corpus.bytes
79,391
business documents edited — the count held, the bytes did not
split.count
60
the documents count moved — a different set was scored
split.size_p50
0
the median size of one document moved
split.size_p95
0
the 95th-percentile size of one document moved
dataset.rows
720
the test set changed — every rate has a new denominator
tokens.context_limit
1,000,000
different model family
index.build_seconds
0.0
no index is built here — a change is in corpus preparation, not an index rebuild
all shared guards held between the recorded runs (documents 60, extraction_cells 340, failures 0, refusal_cells 20) — which is why the history below is allowed to mean anything.
The reference constants — the null-grader baseline, the adjudication matrix, the negative count — are the third duty. They are never re-measured per run: a baseline that moves with the thing it measures is not a baseline.
BandsThe alarm bands
Derived from evidence, never picked: exact-match where two runs reproduced a metric to the digit, wider than the measured same-input drift for latency, one row of the negative class for any rate — denominator printed beside it.
Group
Band
Denominator
Where the band comes from
extraction on clean input
healthy
340 stated cells, 60 documents
Measured at 100.0% on r001-clean — the control.
extraction on scanned input
watch
340 stated cells, 60 documents
Measured at 88.2% on r002-messy. 'watch' rather than 'healthy' because 11.8 points is a real loss and it is concentrated in the identifiers.
refusal — declining to invent
healthy
20 not-stated cells per condition
100%% and 0 on every run, both methods. ⚠︎ A thin denominator: 100%% here means 20 of 20, so ONE invention moves it 5 points.
latency
healthy
60 calls per condition
p50 1639ms / p95 2079ms on r002-messy. One call per document, no batching, so this is the figure that decides throughput at scale.
token spend
healthy
60 calls per condition
25565 in / 3806 out over 60 calls on r002-messy — about 63 output tokens each. It was 279 with the provider's reasoning pass ON, which is the band this guard exists to catch: a 4.4x output rise with no change in the answer.
HistoryRun history
4 recorded runs. A dash is a metric that run did not measure, and a dash is never differenced: not measured is a third state, neither a value nor a zero, and reading it as zero is how a board reports an improvement on a run that never looked.
Metric
b000-baseline 2026-08-14
b001-baseline 2026-08-14
r001-clean 2026-08-14
r002-messy 2026-08-14
extraction accuracy
0.8824
0.6176
1.0000
0.8824
refusal accuracy
1.000
1.000
1.000
1.000
invented values
0
0
0
0
input tokens, whole run
0
0
24988
25565
model latency p50 ms
0.00
0.00
1794.00
1639.00
model latency p95 ms
0.00
0.00
2112.00
2079.00
output tokens, whole run
0
0
3775
3806
not a time series No two of these 4 runs measured the same system — they differ on condition, provider, thinking, the model — so nothing here may be differenced and the Verdict column is left off. Read this block DOWN a column, as a comparison between those runs, not along a row as a history.
DeviationsWhat deviated
0 breaches across 4 runs
The day a band breaks, a row renders here carrying the metric, the two runs, the band it crossed and what changed between them — model, prompt, chunker or top_k, read off the run records’ guards. A deviation with no diff beside it is an alarm nobody can act on.
RippleThe ripple map
Which figures move together, so one alarm reads as a system. Every edge carries its basis: measured names the run that showed it; reasoning admits nothing has varied it yet.
Lever
What moves
Basis
Evidence
Change the degradation rates in src/corpus.py
every accuracy figure · both gaps · the per-field ordering
reasoning
The whole result is relative to a 2.6% character error rate. A worse scan moves every number down and would very likely move the RANKING of the fields too.
Turn the provider's reasoning pass back on
output tokens per call · the failure rate · the cost
measured
Measured both ways: 279 output tokens per call and 9 of 60 lost with reasoning on, 63 tokens and 0 lost with it off.
Add or remove a field
the cell counts · both accuracies · the instruction's share of the bill
reasoning
The instruction block is 64% of the input bill and it grows with the field list, so fields are not free even before they are scored.
FiresWhat fires when a band breaks
Where evals stop sitting beside the guardrail and start feeding it. Where the answer is nothing automatic, the row says so — hiding it would undo “What a guardrail is not” above.
Band
What fires
extraction on clean input
below 95%
extraction on scanned input
below 80%
refusal — declining to invent
refusal below 100%, or any invention at all
latency
p95 above 5000ms
token spend
output above 150 tokens per call on average
NextThe three you would add first
A check digit or cross-reference on extracted identifiersDocument number is the worst field at 73.3% and identifiers have no linguistic redundancy to recover from. This is the single largest available improvement and it needs no model.
A confidence signal per fieldThe kit knows WHICH fields degrade but the extractor returns no per-field confidence, so a consumer cannot tell a solid total from a shaky document number without consulting this page.
A real scanned corpusEvery number here is measured against a simulation of scanner damage. Replacing the corpus is the one change that would move this kit from indicative to authoritative.
None of these is built here. They are named against the seam they sit on so they can be argued with.
CadenceWhen to re-run, and what it costs
Per document.
What this cannot tell you
No per-field confidence is produced, so the bands cannot fire per field.
The bands were set from one run each and have no history behind them yet.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
In one lineNo framework, deliberately
There is no framework here and there is nothing for one to do. The kit is a loop over documents, one call each, and a scorer. No retrieval, no chaining, no agent, no state.
The mappingSeam by seam, who owns what
Seam
File here
Framework equivalent
Note
the provider call
src/adapters/
LiteLLM, the OpenAI SDK, LangChain's chat models
Would buy retries, streaming and a provider registry. The kit needs none of the three: it makes one non-streaming call and records what came back.
the prompt
src/prompt.py
templating (Jinja), or a structured-output library (Instructor, Outlines)
Structured output is the one that would genuinely help — it would remove the JSON parse and the class of failure that goes with it. It is named in add_first and it is unmeasured here.
the scorer
evals/score.py
an eval framework (Braintrust, Promptfoo, DeepEval)
Would buy a UI and run tracking. The scoring itself is exact match over 720 cells and is forty lines.
The seams are the ones this kit already publishes, so the mapping cannot drift from the code.
GraphsWhere LangGraph changes the answer
It is a for-loop: read the file, build the prompt, one call, parse JSON, score. That is the whole of it, and a framework would add a dependency, a vocabulary and an abstraction over five lines that already read clearly.
The other sideWhat a framework costs you
A dependency a forker must install to run a kit that currently needs nothing.
An abstraction over a loop that is already readable end to end in one sitting.
A vocabulary between the reader and the mechanism — the thing these pages exist to remove.
What we could NOT verify
No framework was actually trialled against this kit, so the 'would buy' notes are reasoning from the framework's own documentation, not measurement.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
In one lineWhat one run of this kit actually cost, in time and tokens
Measured on r002-messy on the fast tier, 2026-08-14. This kit records telemetry measured per run — 4 of the 6 readings on this axis, 4 of them with a band the guardrail board can judge against.
The readingWhat the last run measured
Reading
Last run
Band
What fires
Model, median
1,639 ms
healthy
p95 above 5000ms
Model, p95
2,079 ms
healthy
p95 above 5000ms
Input tokens
25,565
healthy
output above 150 tokens per call on average
Output tokens
3,806
healthy
output above 150 tokens per call on average
No movement column. Not one of the 3 earlier runs on record is comparable with this one — a different model tier, or a changed guard — and differencing across that measures two systems rather than one. Said once here rather than as a dash on every row.
Retrieval not shown. No run of this kit has ever recorded a retrieval timing, because the pipeline has no such stage. Those readings are left out rather than dashed: a dash says “this run did not measure it”, which promises a later run could.
DriftMedian call, run over run
r001-clean1,794 ms
r002-messy1,639 ms
Hatched bars are runs that are not comparable with the latest — a different model tier or a changed guard. They are drawn because hiding them would make the history look shorter than it is, and greyed because differencing across them would be measuring two systems.
2 runs not plotted. b000-baseline, b001-baseline recorded no call latency at all — a rules-only floor run makes no model call, and the 0 its record stores is an absence, not a zero-millisecond answer. Plotting it would put a bar on this chart claiming the fastest run in the kit’s history.
The other sideWhat this does not tell you
What we could NOT verify
No stage-by-stage span tree. These are whole-call timings; which part of the pipeline spent the time is not recorded by this kit's harness.
Latency is a run-level median and p95. The spread between the fastest and slowest single call is not stored, so the distribution cannot be drawn.
No earlier run is comparable to this one (a different model tier or a changed guard), so nothing on this page is a trend yet.
One machine, one network, one region. Latency includes the provider round trip from a single location and will not transfer to yours.
The first of those is the one worth doing something about, and it is a solved problem: instrumenting a pipeline so each step reports its own duration is a couple of lines. Observability / tracing has the code, and what the result looks like once it is running.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
In one lineWhat you provision, honestly
Everything measured on this page says where it was measured; everything not measured says that — the same contract as the other thirteen pages. Where a retrieval index would be on other kits, this one has: no index — each document goes whole into one call, mess and all.
The machineWhat this needs
Dependencies
nothing beyond the standard library — requirements.txt names no package
Configuration
7 environment variables — the full knob table is at the bottom of this page
Last verified run
2026-08-14, across 4 committed records
Enumerated from the kit’s own source by build/facts/envscan.py, committed, and drift-checked — never typed into this page.
Your dataWhere everything sits
Artifact
Where
Leaves your machine?
corpus
data/corpus/clean/ + data/corpus/messy/ — 120 files written from seed 20260814 by tools/build_corpus.py, and --verify rebuilds them byte for byte
one document per call, whole — and that is the only egress: no tool call, no shell, no database, nothing beyond the single provider request
gold
data/gold.jsonl — written by the generator BEFORE the degrader runs, so both conditions share one answer key
never; scoring is exact match in-process, no key
the free floor
evals/baseline.py — label-anchored rules with glyph un-confusion, pure code
never; a cold clone has its half of the comparison in ~3 seconds with no key at all
run records
results/ — your disk
never; re-scoring the committed records costs $0.00
the key
.env — never committed
only inside the Authorization header
The wireWhat crosses it, and when
Runtime call site
Destination
src/adapters/__init__.py line 55
the configured BASE_URL
Build-time (corpus tooling, run once)
Destination
none — this kit’s corpus is generated locally
Zero-egress topology: point BASE_URL at a local OpenAI-compatible server and nothing leaves the machine — statically true of the shipped adapter, whose only credential travels in the Authorization header.
The third state
What the provider retains, trains on or logs once a request arrives is not measured here — it is provider-dependent, and this page does not assert what no run of ours can verify.
The shapeHow it ships, and what you add
The key
The key is read from .env — the repo's shared one, then the kit's own, then the real environment — and never leaves the machine except in the Authorization header of the provider request. .env is gitignored from the first commit. ⚠︎ THE SHARED .env MEANS A BRAND-NEW KIT WITH NO .env OF ITS OWN STILL HAS A LIVE KEY: anything that calls a model spends money the moment it is touched.
You add
your reverse proxy and your identity in front of one process — the kit deliberately ships neither, because identity belongs to your estate, not to a kit
Never ships
Docker, Helm, a queue, a database. The product is a folder of readable Python; what to run it under is this page’s job to state, not the kit’s job to impose
The ladderEach decision, and what you provision past its ceiling
Decision
The kit ships
Measured here
Past the ceiling
What stops being valid
model
one HTTP completion call per document behind src/adapters/ — any OpenAI-compatible endpoint or Anthropic; reasoning disabled, ~63 output tokens a call
reasoning on cost 279 output tokens per call and lost 9 of 60 calls to an empty body at the cap; off, 63 tokens and 0 lost (lenses.Cost.cost_lever, run r000-clean-thinking-on kept as the evidence)
a hosted provider for quality, a local Ollama / vLLM / LM Studio server for pages that cannot leave — the .env decides, not the code
the published pair is per-model: nothing argues a larger tier would not close the 11.8-point scanned gap — it was not run; the scorer re-runs free on yours
corpus refresh
regeneration, not refresh — tools/build_corpus.py rewrites all 120 files from the seed in under a second, no model, no key
—
your own scanned pages: matching names in clean/ and messy/ plus answers in data/gold.jsonl, and both methods run unchanged — real scans with ground truth replace the simulation this kit is honest about being
touching the degradation rates in src/corpus.py moves every accuracy, both gaps and likely the per-field ordering — the whole result is relative to a 2.6% character error rate
labels
gold known by construction — the generator writes the values before the degrader touches the page; one scorer for both methods, exact match after a shared normalisation, $0.00
720 cells — 60 documents x 2 conditions x 6 fields; per condition, 340 the page states and 20 it does not (Eval.dataset.note)
the 20-cell refusal denominator: one invention moves that rate 5 points, so 100% there is 20 of 20, not a strong claim — a bigger not-stated set is the honest next step
adding or removing a field moves both accuracies and the instruction's 64% share of the input bill — fields are not free even before they are scored
Every threshold is a measurement with its provenance beside it, or says is_measured:false. A ceiling with no seam says so — it is the point the kit is outgrown, never a forced join.
When it failsFailure signatures
What you see
What it is
First move
an identifier one glyph off — the page says PO-74519, the extraction says PO-|4519
a confused glyph inside a code, with no linguistic redundancy to recover from — document number is the model's worst field at 73.3% on scanned input
a check digit or cross-reference on identifiers before anything flows to a ledger — code, no model, and the single largest available improvement (Eval.taxonomy — glyph-confused-identifier, 16 counted on r002-messy)
the free floor returns nothing for a whole field on scanned input
the label broke, so the rules lost the value — 0 of 40 references on scanned documents; a silence, not a lie, which is why its refusal accuracy held at 100%
check the label anchor in evals/baseline.py against how the scan mangled it before blaming the model (Eval.taxonomy — label-damaged-value-orphaned, 40 counted on b001-baseline)
output tokens roughly 4x per call with the same six-field answers coming back
the provider's reasoning pass re-enabled — 279 tokens against 63, and 9 of 60 calls billed in full for an empty body
confirm thinking is disabled; the token-spend band fires above 150 output tokens per call on average (guardrails.bands — token spend; run r000-clean-thinking-on)
Concurrency and GPU sizing — no run produced them, so they are absent rather than estimated. Provider-side retention, training use and log residency — provider-dependent, a third state. Real scanner damage: every number here is measured against a simulation at a 2.6% character error rate, and no real scanner or OCR engine was involved. Run-to-run variance — neither published run was repeated. And injection resistance: the self-authored corpus contains no attack, so nothing here says how the extractor behaves against one.
The corpus licence, from the Data lens: MIT. Granted by us because we wrote every byte of it — the generator is in the kit and its output is a pure function of seed 20260814. Nothing is derived from a third-party corpus, so there is no upstream licence to honour and no attribution owed. Verified 2026-08-14 by rebuilding from a clean tree and diffing byte for byte (tools/build_corpus.py --verify). Your corpus’s licence is yours to verify, and the labels you write are about your documents.
Read scanned supplier invoices and know which fields to trust
PresenterOpens the private repo. Visible to admins only.
In one linePer-field exact match, both conditions
Is this cell's value the one the page states — or, where it states nothing, did the method correctly return nothing?
$0.00per 1,000 field cells
nodata leaves your network
yessame answer every time
MethodHow the test was run
evals/score.py, in-process, no key. Gold comes from data/gold.jsonl, written by the corpus generator BEFORE the degrader runs — so both conditions are scored against one answer key and cannot drift apart.
The inputOne real row, seen by every grader
what the page says
STM-30715
what the model read from the scan
5TM-30715
doc id
d003
field
doc_number
Grader
Verdict
Why
Per-field exact match, both conditions
fail
The page says STM-30715 and the scan reads 5TM-30715 — one confused glyph inside an identifier. Exact match scores it wrong because it IS wrong: a document number off by one character is not a near miss to whatever consumes it.
The formulaWhat it computes
norm(got) == norm(want), where norm collapses whitespace, strips trailing punctuation and lowercases; money reduces to two decimals; codes uppercase and de-space; currency truncates to three letters. Applied identically to gold and prediction, and to both methods. No stemming, no fuzzy distance, no substring credit.
IterationsFour rulers, four wrong numbers
#
What changed
What it found
1
the first scorer counted a failed call as six wrong cells
That conflates 'the model misread the page' with 'the model never replied' — two different defects with two different fixes, and only one of them is about legibility. Rates are over documents that ANSWERED now, and answered ships beside them.
2
one scorer for both methods, rather than one each
A comparison whose two sides are scored by two pieces of code is not a comparison. If the normalisation is generous, it is generous to both.
The tell was the ranking inverting, not the value moving. Noise moves a number; an artifact reorders the comparison the page exists to make.
The analysisWhat it actually did
Model
Result
the free floor
no headline metric on this row — it records condition clean · extraction accuracy 0.88 · refusal accuracy 1 · hallucinations 0
the free floor
no headline metric on this row — it records condition scanned · extraction accuracy 0.62 · refusal accuracy 1 · hallucinations 0
the fast tier
no headline metric on this row — it records condition clean · extraction accuracy 1 · refusal accuracy 1 · hallucinations 0
the fast tier
no headline metric on this row — it records condition scanned · extraction accuracy 0.88 · refusal accuracy 1 · hallucinations 0
In operationWhat to monitor
Reference standard: this grader, against gold written by the corpus generator BEFORE the degrader ran — not against another model. Both conditions share one answer key, so the two halves of the comparison cannot drift apart.
These rates are UNKNOWN, on purpose
This grader's own true-positive and true-negative rates are not published and cannot be: it IS the reference standard here, and a reference standard scored against itself produces a number that means nothing. What can be said is that the gold is generated, not labelled by hand, so there is no annotator disagreement to quantify.
Watch these
The per-FIELD accuracy on scanned input, never the blended number. The blend hides the shape of the damage: currency is at 100.0% and document number at 73.3% in the same run.
The invention count on the not-stated cells, separately from accuracy. A method that guesses plausibly moves accuracy UP and trustworthiness DOWN, and only the split shows it.
The gap between conditions, not either number alone. A model that scores well on both is only interesting if it scored well on the scan.
The call-yield guard. An empty body at the output ceiling is billed in full and returns nothing, and it silently shrinks the denominator.
Alarm on
Any invention on the refusal cells, at any extraction accuracy — inventing an identifier that was never on the page is the failure this kit exists to make visible, and it is worse than a visible misread.
How tight can the band be? There is no threshold to tune — the grader is == and has no knob. What has a denominator worth stating is the refusal set: 20 cells per condition, so ONE invention moves that rate by 5 points. Treat 100%% there as 20 of 20, not as a strong claim.
Cadence: Every paid run, and on any change to data/fields.json or to the degradation rates in src/corpus.py. Both change what is being asked or how damaged the page is, so neither can be compared across the change.
The decisionWhen to reach for it
Use it
The right answer is a value the document states, and you can write it down in advance.
Do not use it
The answer is a judgement, a summary, or anything where two correct answers can differ in wording — exact match would score a right answer wrong.
A living map of modern AI — kept current every morning