Catch the store that's quietly short in cash every night
Your daily cash report only catches a big miss on one night. This app finds the store that is quietly short every night and adds up how much it has cost so far.
PresenterOpens the private repo. Visible to admins only.
For the regional cash managerRetail · Cross-domain
Why it matters
Today's manual process, and the same job with the app
A regional cash manager overseeing forty convenience and supermarket stores.
✕Today's manual process
1Run the daily report, which only lists a till that broke its limit that night.
2Check each flagged store, often the same rounding a supervisor already explained yesterday.
3Miss the quiet ones: a store that's a little short every night never gets listed.
4The pattern goes unnoticed for months, until the loss adds up to real money.
Only big misses ever get noticed
✓With the app
1The report reads every close, not only the ones that break a limit.
2It carries each store's recent history, so an old explanation is not re-raised.
3A store that's quietly short every night is named, even though no single night stands out.
4The total is added up by store, so a quiet pattern is not missed for months.
Quiet, steady losses are named by store
See it work
One real case: what the app reads, step by step
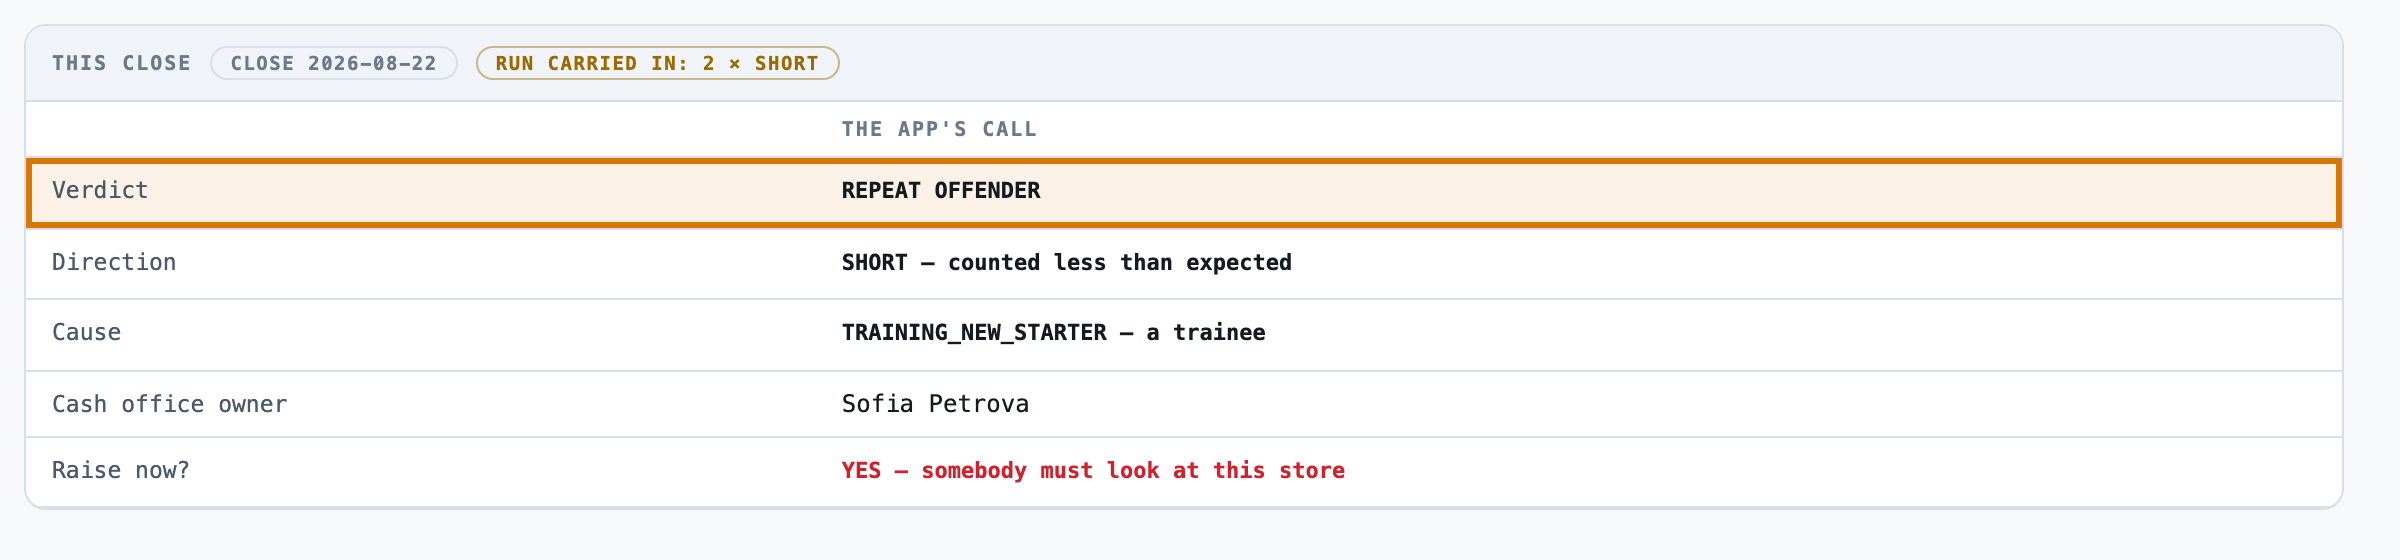
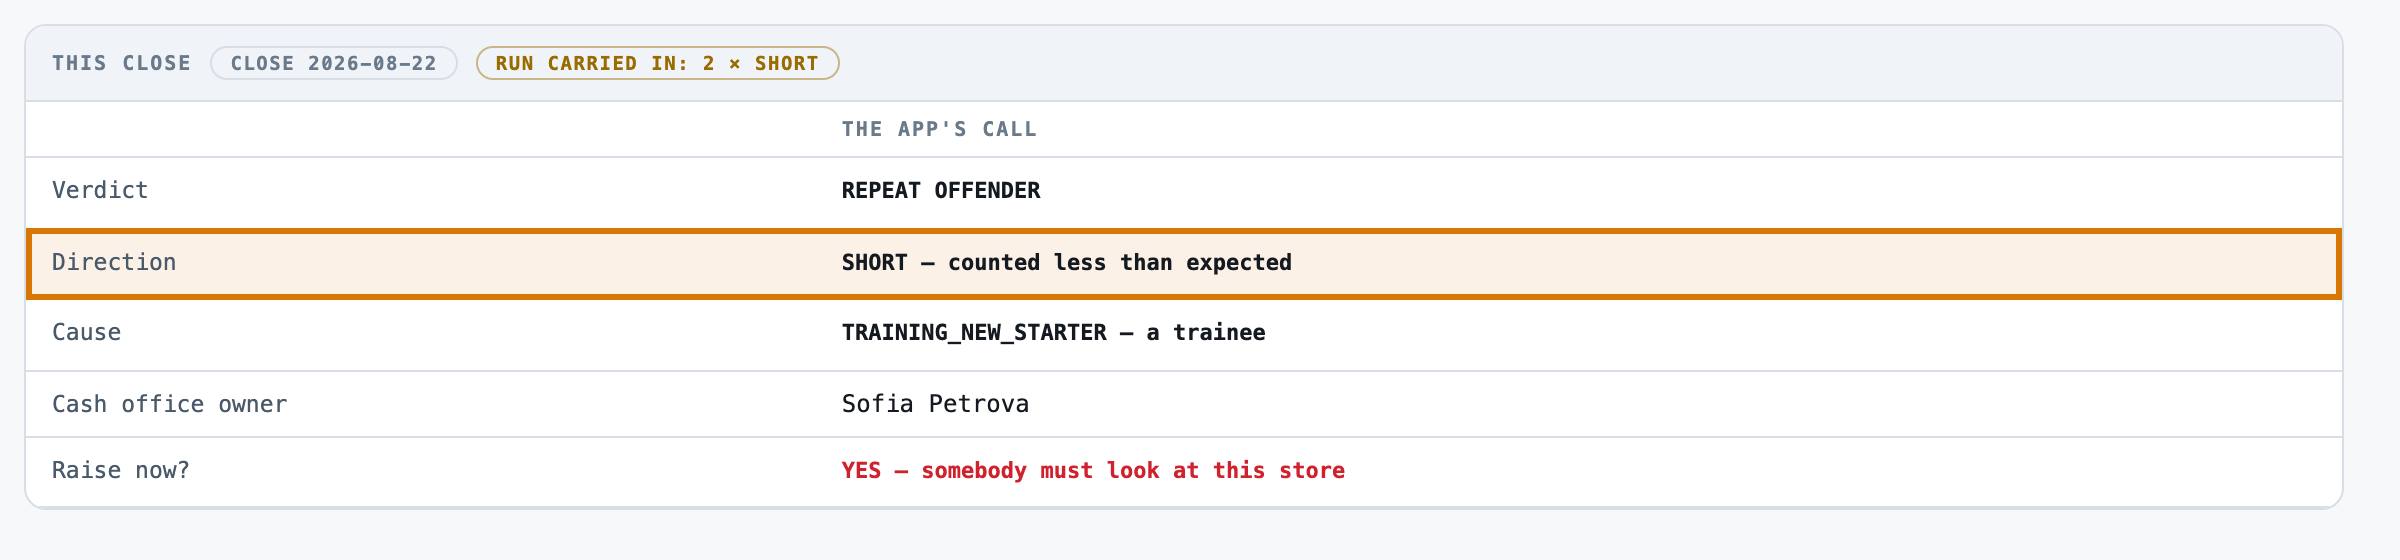
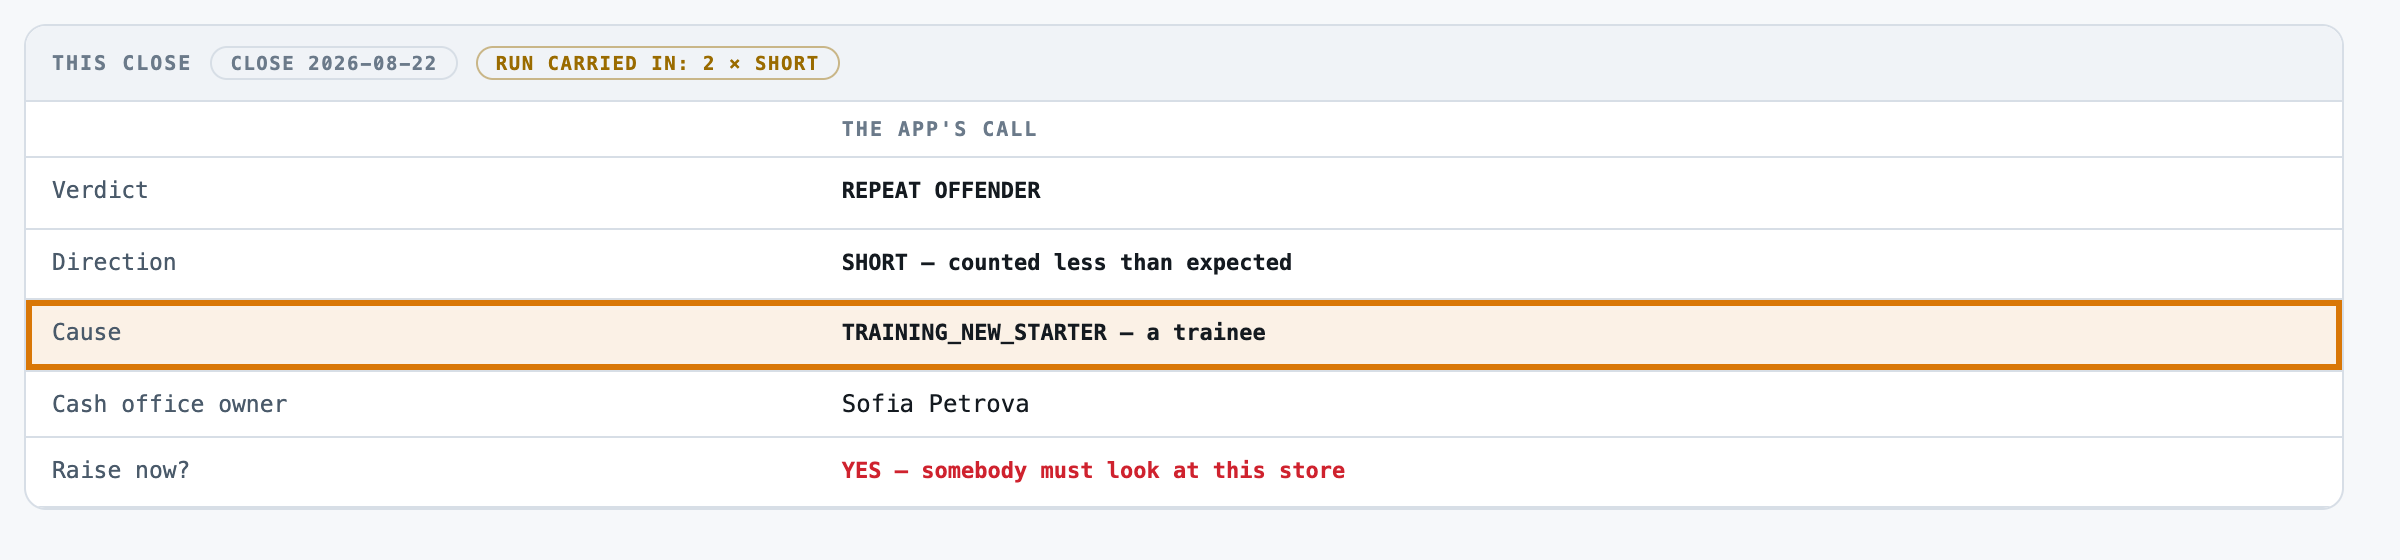
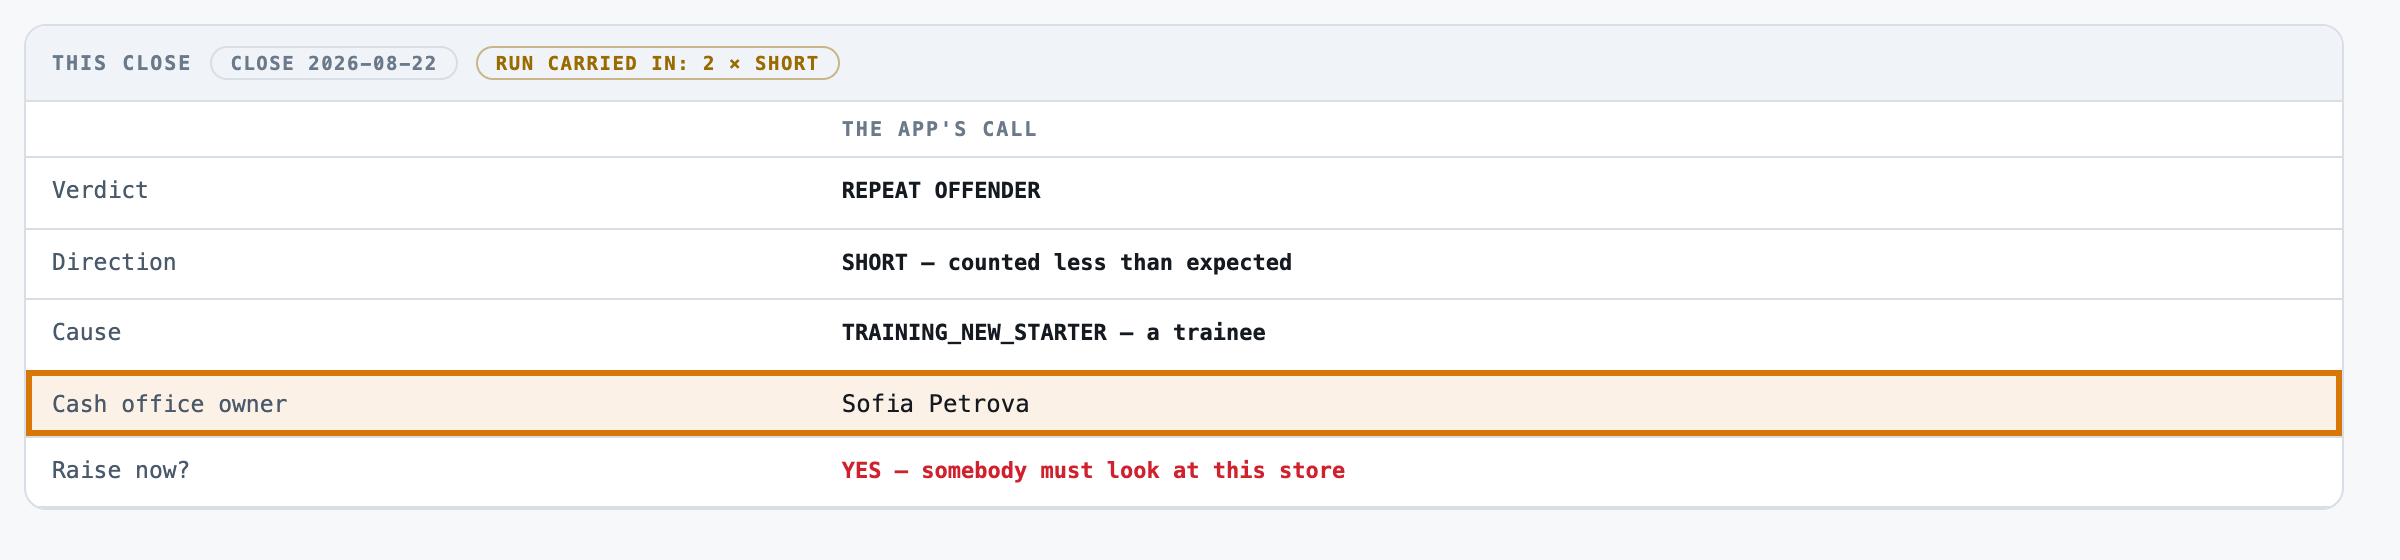
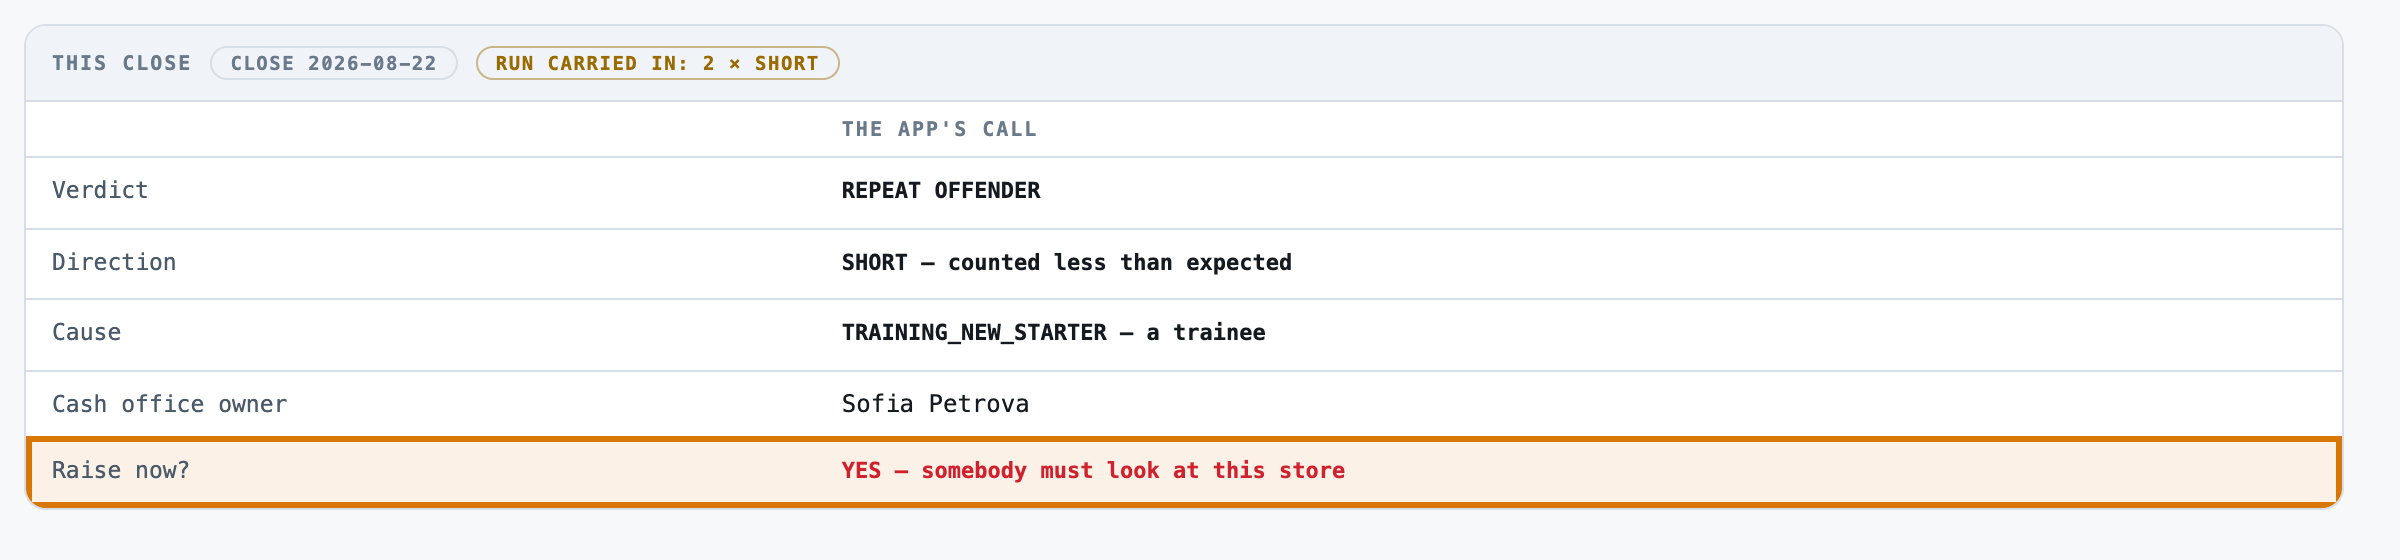
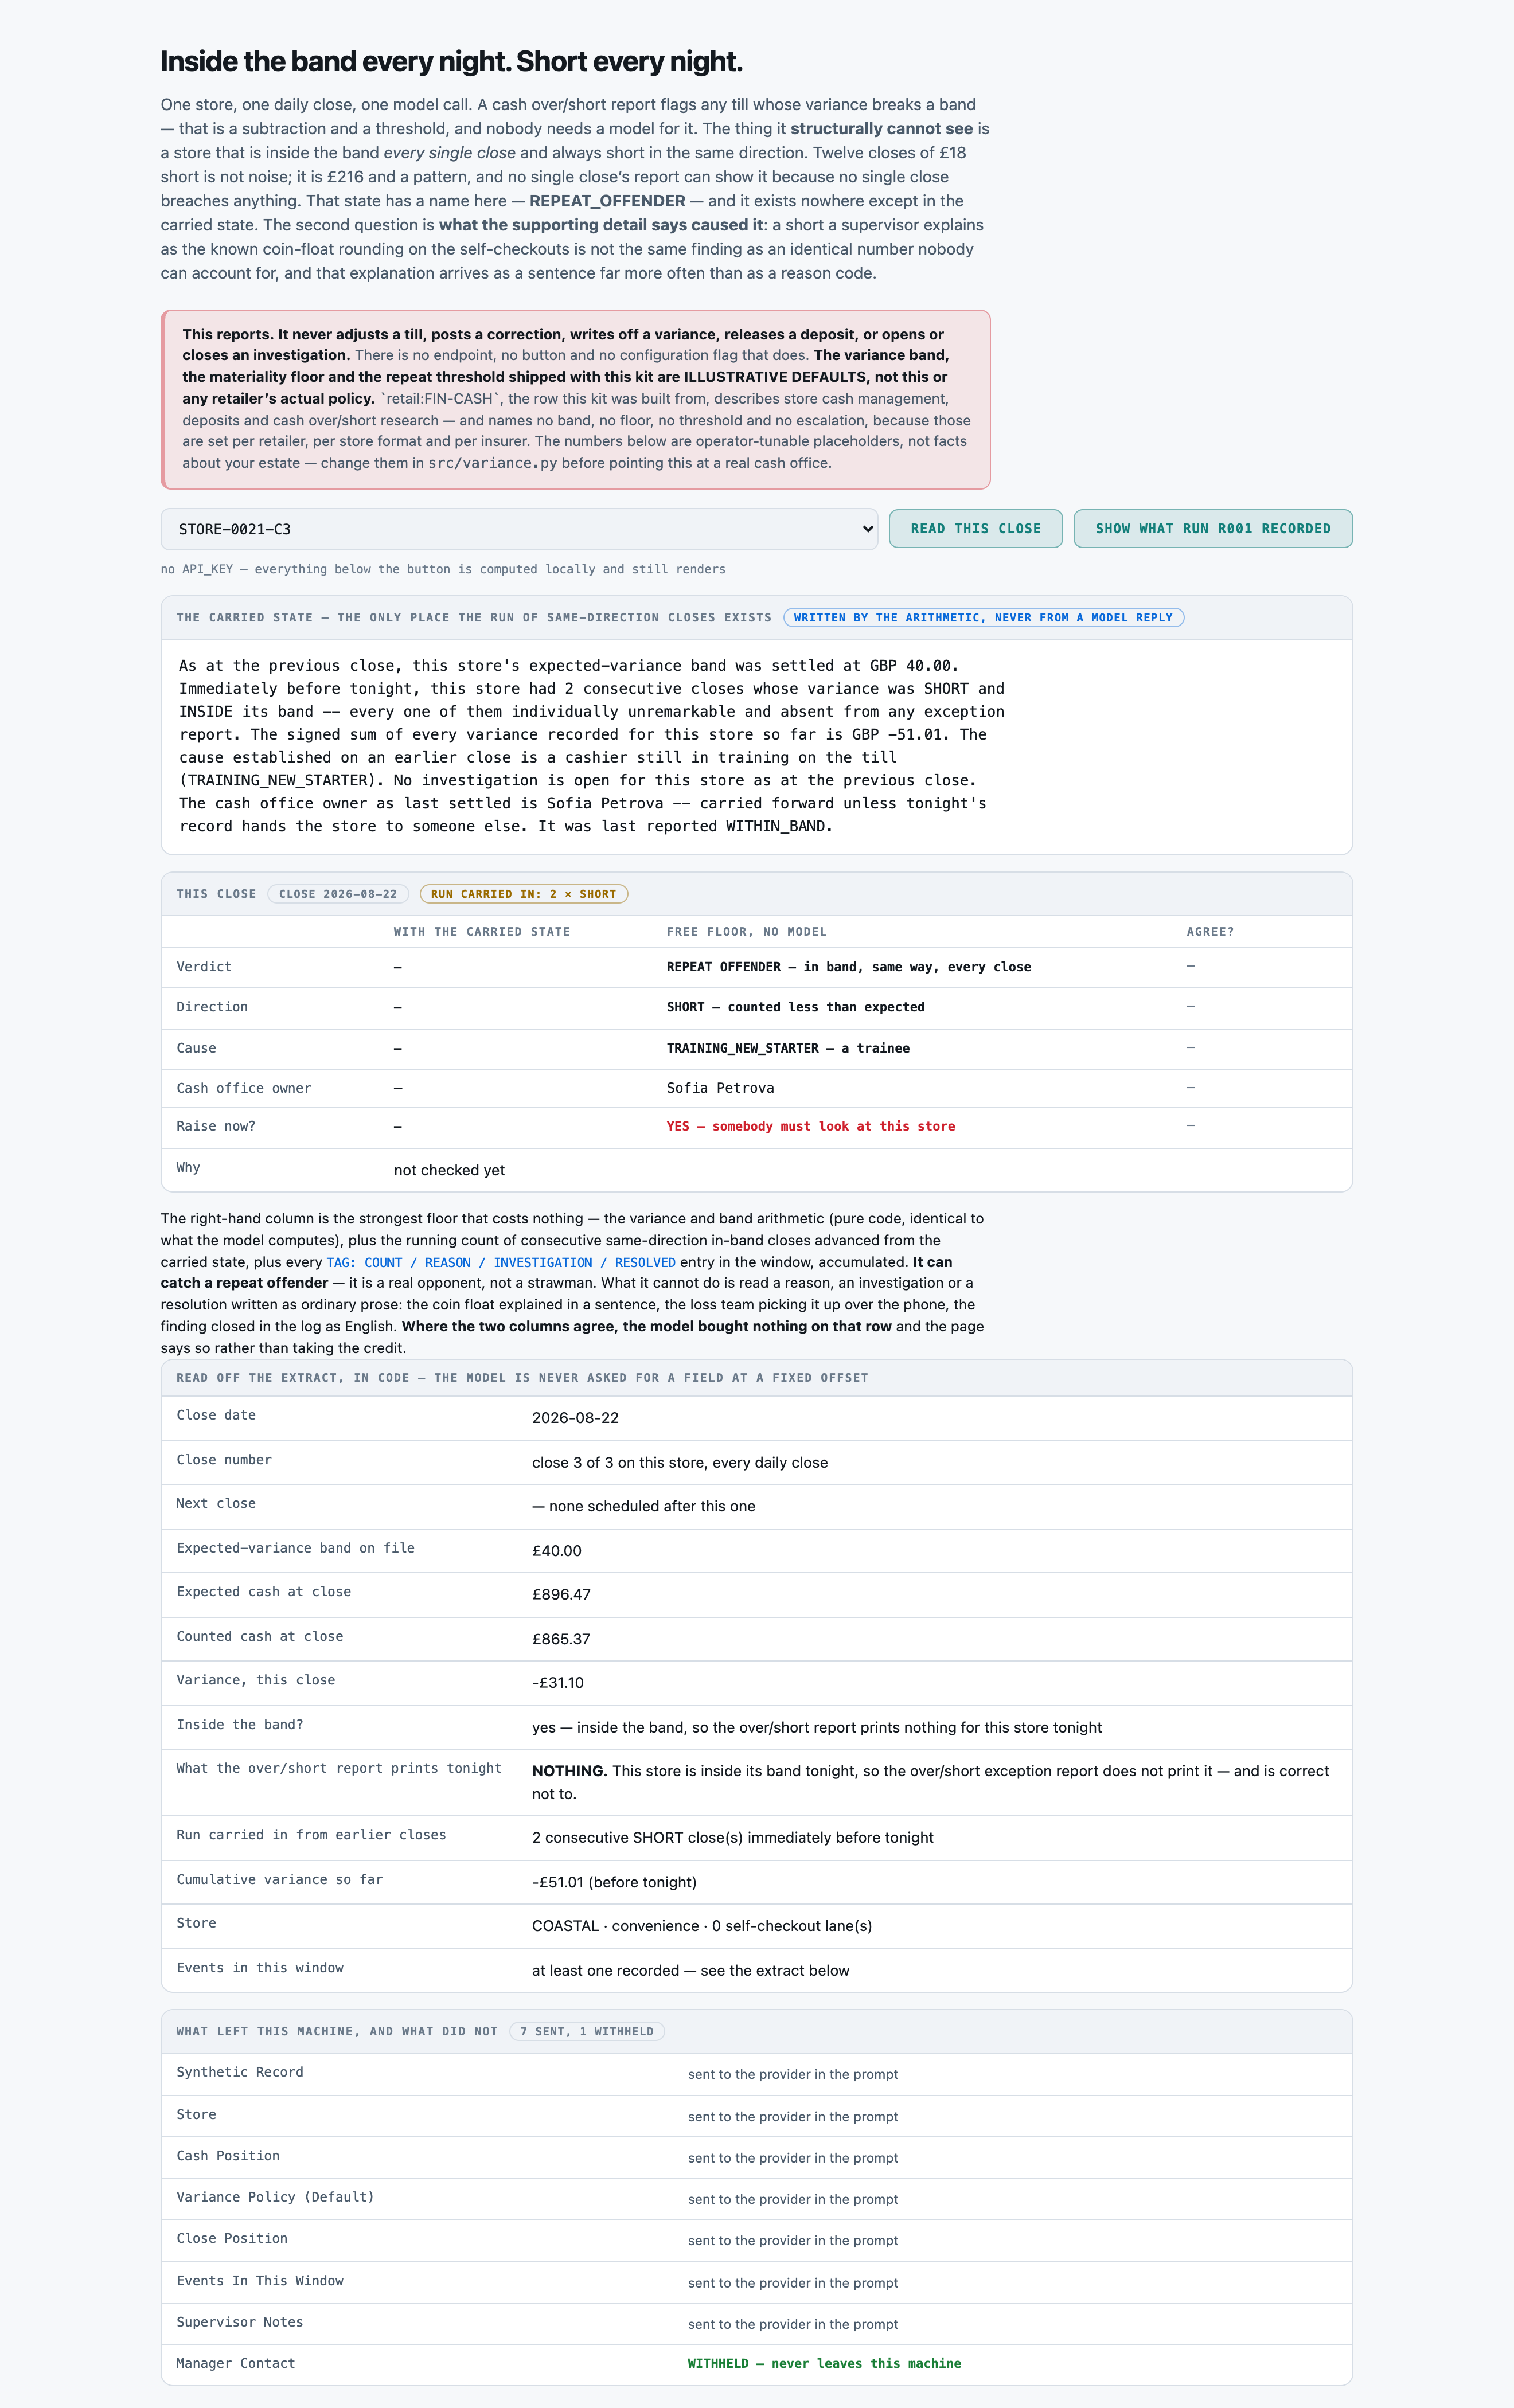
A convenience store's close comes in a little short for the third night running, and the app finally puts a name to the pattern.
Catch the store that's quietly short in cash every nightReference appBuilt to be shaped to your process
5
1The verdict Named a repeat offender, not treated as a one-off miss.
2Which way it moved Marked short, meaning less was counted than expected.
3The likely cause A trainee still learning the till, already on file.
4Who's responsible The cash office owner named, carried from the rota.
5Raise it now? A clear yes, so somebody looks at this store tonight.
For engineers
How it is built, and how we measured it
All fourteen steps of the build are written up, from the business case to running it in your own environment.
Catch the store that's quietly short in cash every night
A small, forkable project that does one job end to end. Run once for real, and every figure on these pages captured from that run.
PresenterOpens the private repo. Visible to admins only.
The business caseThe problem this solves
A cash over/short report is a subtraction and a threshold. What it structurally cannot show is a store whose variance is inside the band on every close and always in the same direction. On this corpus that is 12 readings, the largest single close among them £31.10 inside a £50 band, accumulating £648.59 the existing control prints nothing about. an over/short report that flags any till breaching a band — which by construction cannot see a store that never breaches one, re-raises variances a supervisor explained yesterday, and treats a coin-float rounding the same as an unexplained shortfall.
Audience
a regional cash manager deciding which stores to send someone to, and a loss-prevention lead deciding whether the over/short report is finding anything a threshold cannot. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual store close extracts
The corpus is 120 store close extracts, 0.80 MB (txt 120). A retailer's cash position by store and shift is a shrink map. There is no public one. A scrubbed export is worse rather than better: scrubbing removes the supervisor's typed explanation, which is exactly the layer this kit measures.
The corpus
The 120 store close extractsgenerated from a fixed seed, so no real record, person or institution appears in it.
Where each came fromwritten for this kit rather than collected — the corpus is generated in the kit's own repository, so there is no third-party data in it.
Swap this folder for your own material and the kit is pointed at your store close extracts. That is the whole change — there is no database to migrate.
One store close extract, as the model receives itSTORE-0001-C1.txt · 1 of 120
Synthetic Record
----------------------------------------------------------------
Every field below is invented. This is a generated store cash-close extract for an AI
use-case kit; it reproduces no retailer, no store, no banking arrangement and no real
person. The variance band, materiality floor and repeat threshold are ILLUSTRATIVE
DEFAULTS, not any real retailer's policy.

Store
----------------------------------------------------------------
Store reference                    : STORE-0001
Region                             : METRO
Format                             : superstore
Staffed tills in use               : 14
Self-checkout lanes                : 6
Cash office owner (rota of record) : Ingrid Solberg

Cash Position
----------------------------------------------------------------
Opening float                      : 500.00 GBP
Takings recorded at the POS        : 18,932.72 GBP
Paid-outs                          : 154.64 GBP
Deposit prepared for banking       : 18,874.46 GBP
Expected cash at close             : 403.62 GBP
Counted cash at close              : 381.97 GBP
Variance, this close               : -21.65 GBP

Till breakdown, this close -- these lines sum to the variance above:
  Till 01                                        -1.83 GBP
  Till 02                                        -1.83 GBP
  Till 03                                        -1.62 GBP
  Till 04                                        -1.78 GBP
  Till 05                                        -0.56 GBP
  Till 06                                        -1.17 GBP
  Till 07                                        -1.35 GBP
  Till 08                                        -1.77 GBP
  Till 09                                        -0.79 GBP
Abridged — the file continues.
The outcomeWhat a good result looks like
every store's verdict with the direction and the explained cause named, and the persistently one-directional stores surfaced by name — 0 false raises across 100 quiet readings.
And when it cannot
a CONTEXT_INCOMPLETE reading (no expected-variance band on file — 9 of 120) is not judged rather than judged against a guessed band. There is no default band.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
Every explanation is a structured reason code and your bands are correct — the free floor — structured-log-strong, $0.00 It counts same-direction closes from the carried state and BEATS the model on cause (91.67 against 80.83) and owner (95.0 against 92.5).
Supervisors explain variances in prose and handovers are noted, not keyed — the model, with the carried state Verdict 99.17 against 93.33, and 100.0 pct of explained variances left alone against 75.0 pct.
And where nothing here is good enough:
You want the reading but cannot carry state between closes — neither, as configured here The stateless control misses 12 of 12 repeat offenders.
At a glanceHow the whole thing runs
99%verdict accuracy pct
12,183 msp50, end to end
$6.51per 1,000 store close extracts · Google Gemini 3 Flash
Run once, for real, on 2026-08-25. Every figure on these pages was captured from that run — nothing is written from intent.
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Catch the store that's quietly short in cash every night14 steps · 4 questions · run once, for real · 2026-08-25
Every tile is a linkall 14 steps · no step without a page
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
What do I have to bring?
tools/build_corpus.py writes data/corpus/*.txt and data/gold.jsonl. The measured figures on this kit's page do not transfer to your own corpus.Corpus lens →
When is this the wrong choice?
Avoid: Do not use it where supervisors type explanations in a sentence — it leaves 75.0 pct of explained variances alone against the model's 100.0 pct. That is the case against the best-fitting scenario (“Every explanation is a structured reason code and your bands are correct”). 3 scenarios scored in all, each with its own.Eval lens →
Where does it stop working?
A store with no expected-variance band on file (9 of 120 readings): CONTEXT_INCOMPLETE. 5 recorded failure modes, each from a run rather than a guess.Corpus lens →
What was never verified?
Whether the 7 note-confusion cause misses are model error or the corpus defect named above. The defect is real, diagnosed and NOT fixed; no corrected figure is published. 5 items this kit says it could not check.Eval lens →
Can I run this on a model I control?
Yes — any OpenAI-compatible endpoint, including one on your own hardware. The shipped adapter takes its host from BASE_URL and its model from MODEL, so nothing in src/ changes. The published figures come from 1 model on the fast tier, with the carried state, one provider, one key. Prompt lens →
And if it fits — what do I stand up?
4 artifacts with a stated home and a stated egress, and 4 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one.step 14 — Run it in your environment →
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-08-25 — r001-cash-variance. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — Every corpus extract, the answer key, all three free floors, the injection probe and what r001-cash-variance actually answered ship in the repo. python3 -m evals.check_labels and python3 -m src.app both run with no key and no network.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
Step 01 of 14Business case
Written for: product manager · Measured during the eval run. Never estimated, never quoted from a vendor page.
In brief
99.17%rows answered
12,183 msp50, end to end
53,390 msp95
5 minclone to first result
What the clock covers. one reading — one store, at one scheduled run, end to end including provider-side reasoning tokens, on the shared connection. Not a cold-start figure and not a per-store SLA: 120 readings ran in 623.5 wall seconds because different stores run concurrently while a single store's runs are strictly serial.
Current processWhat it replaces
an over/short report that flags any till breaching a band — which by construction cannot see a store that never breaches one, re-raises variances a supervisor explained yesterday, and treats a coin-float rounding the same as an unexplained shortfall.
Where it is not good enough
The model LOSES three columns to free code. cause, 80.83 against 91.67 — 22 misses, 13 of them the enum's two empty values on readings the prompt never specified and 7 the model reading an ambient supervisor note as a deposit-timing explanation. owner, 92.5 against 95.0 — all 8 are handovers the carried state already named in English, where the model answered the rota printed on tonight's page. direction, 99.17 against 100.0 — the single unanswered reading. ⚠︎ AND ONE READING IS SCORED WRONG ON EVERY FIELD AND SITS INSIDE EVERY PERCENTAGE HERE: STORE-0014-C3 was cut off at the 16,000-token ceiling. The same bytes returned 800 tokens on one attempt and 11,418 on another. It was not rescued by raising to 32,000 and re-firing 120 calls.
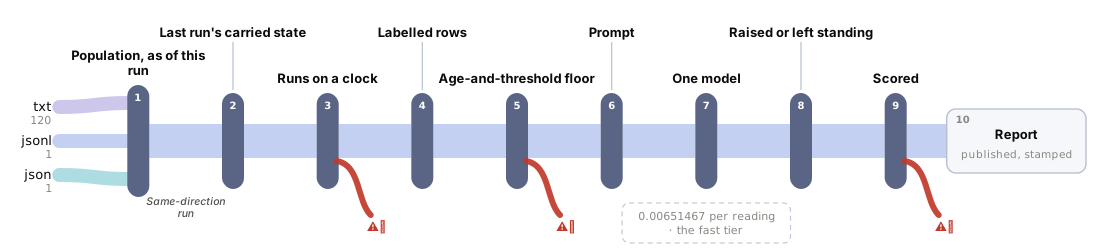
One question, end to end. Colour on the fan-in is the corpus format; a red hook marks every station with a recorded failure, and the words — every sub line, failure and report field — are in the ledger beneath. Every station is a link — click one to jump to its row, and each row links to the lens that explains it.
→Sources
txt120jsonl1json1
40 stores, 120 readings across 3 daily closes — every unit re-read whole
verdict 99.17% against the strongest free floor's 93.33%
discriminator 99.17% — the free floor reads 98.33%
89.17%strip the carried state and it falls to
the model loses cause, owner and direction to free code
2026-08-25as of
A daily store cash watch. The variance is a subtraction against a band; the model is there for a store INSIDE its band on every close and short in the same direction every close. ⚑ TWO STATIONS MAKE THIS A MONITOR AND NEITHER IS THE MODEL: the carried state, written by the arithmetic and never from a model reply, and the clock, where one run owns exactly the events recorded since the last. ⚑ THE TWO WEAKER FLOORS CATCH 0 OF 12 REPEAT OFFENDERS BY CONSTRUCTION — an over/short report cannot show a store that never breaches. And band-only still scores 90.0 on the blended discriminator, which is why the figure prints the COUNTS.
⚠︎ THE MODEL LOSES THREE COLUMNS: cause, owner and direction.
⚠︎ A REAL CORPUS DEFECT WAS FOUND FROM THE MODEL'S OWN RATIONALES AND LEFT UNFIXED — one ambient note near-quotes the deposit-timing cause. No corrected cause figure is published.
⚠︎ AND THE CEILING FAILED TWICE: 8,000 truncated 2 of 120, and the re-take at 16,000 STILL lost one reading, which is scored wrong inside every percentage on the page.
The swap seams
Seam
File
What changes
the variance bands
src/variance.py
The DEFAULT band table.
the repeat threshold
src/variance.py
How many same-direction closes make a pattern — the knob that decides what the discriminator MEANS.
the model
.env
PROVIDER, BASE_URL, MODEL.
what leaves the machine
src/select.py
SECTION_HINTS and NEVER_SENT.
the close cadence
src/variance.py
Reading weekly instead of daily multiplies the time a repeat offender stays invisible.
Components
Component
File
Role
the variance rule and state machine
src/variance.py
The DEFAULT bands, the repeat threshold, the direction run and step() — which decides the next carried state from the answer key's inputs, never from a model reply. It is also the answer key.
the carried state
src/state.py
The run of same-direction closes, the established cause and the resolved flag. The run length is the only thing that makes a repeat offender visible.
the section splitter
src/segment.py
Splits the page into its 8 named sections; asserted across all 120 documents.
the send filter
src/select.py
Manager Contact is mapped by no field and therefore never sent.
the prompt
src/prompt.py
Three parts: instruction and JSON shape, carried state, extract. The stateless control replaces exactly one line.
the model call
src/adapters/__init__.py
Raw HTTP, stdlib only, bounded retry; the shared daily call cap is checked here.
the reader
src/watch.py
One store, one close, one call. The published token ceiling lives here.
the scorer
evals/scoring.py
Exact match per cell. The repeat-offender discriminator is a separate binary.
the three free floors
evals/baseline.py
band-only, band-only-mem and structured-log-strong — $0.00 each, and the third beats the model on two columns.
the local UI server
src/app.py
http.server, stdlib. Renders with no key.
the local UI client
ui/app.js
Hand-written JS, no framework.
Where it breaks at scale
LINEAR IN STORES x CLOSES, and the close cadence is what makes the finding possible at all. A 900-store estate closing daily is roughly 330,000 calls a year and nothing amortises. A repeat offender is only visible ACROSS closes, so reading weekly multiplies the time it stays invisible. The sublinear lever NOT implemented is skipping stores that reconciled exactly — named here, not built.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
Step 03 of 14App UI
Written for: anyone, in 5 seconds · Screenshots of the running app taken during the run.
SuccessesWhen it works
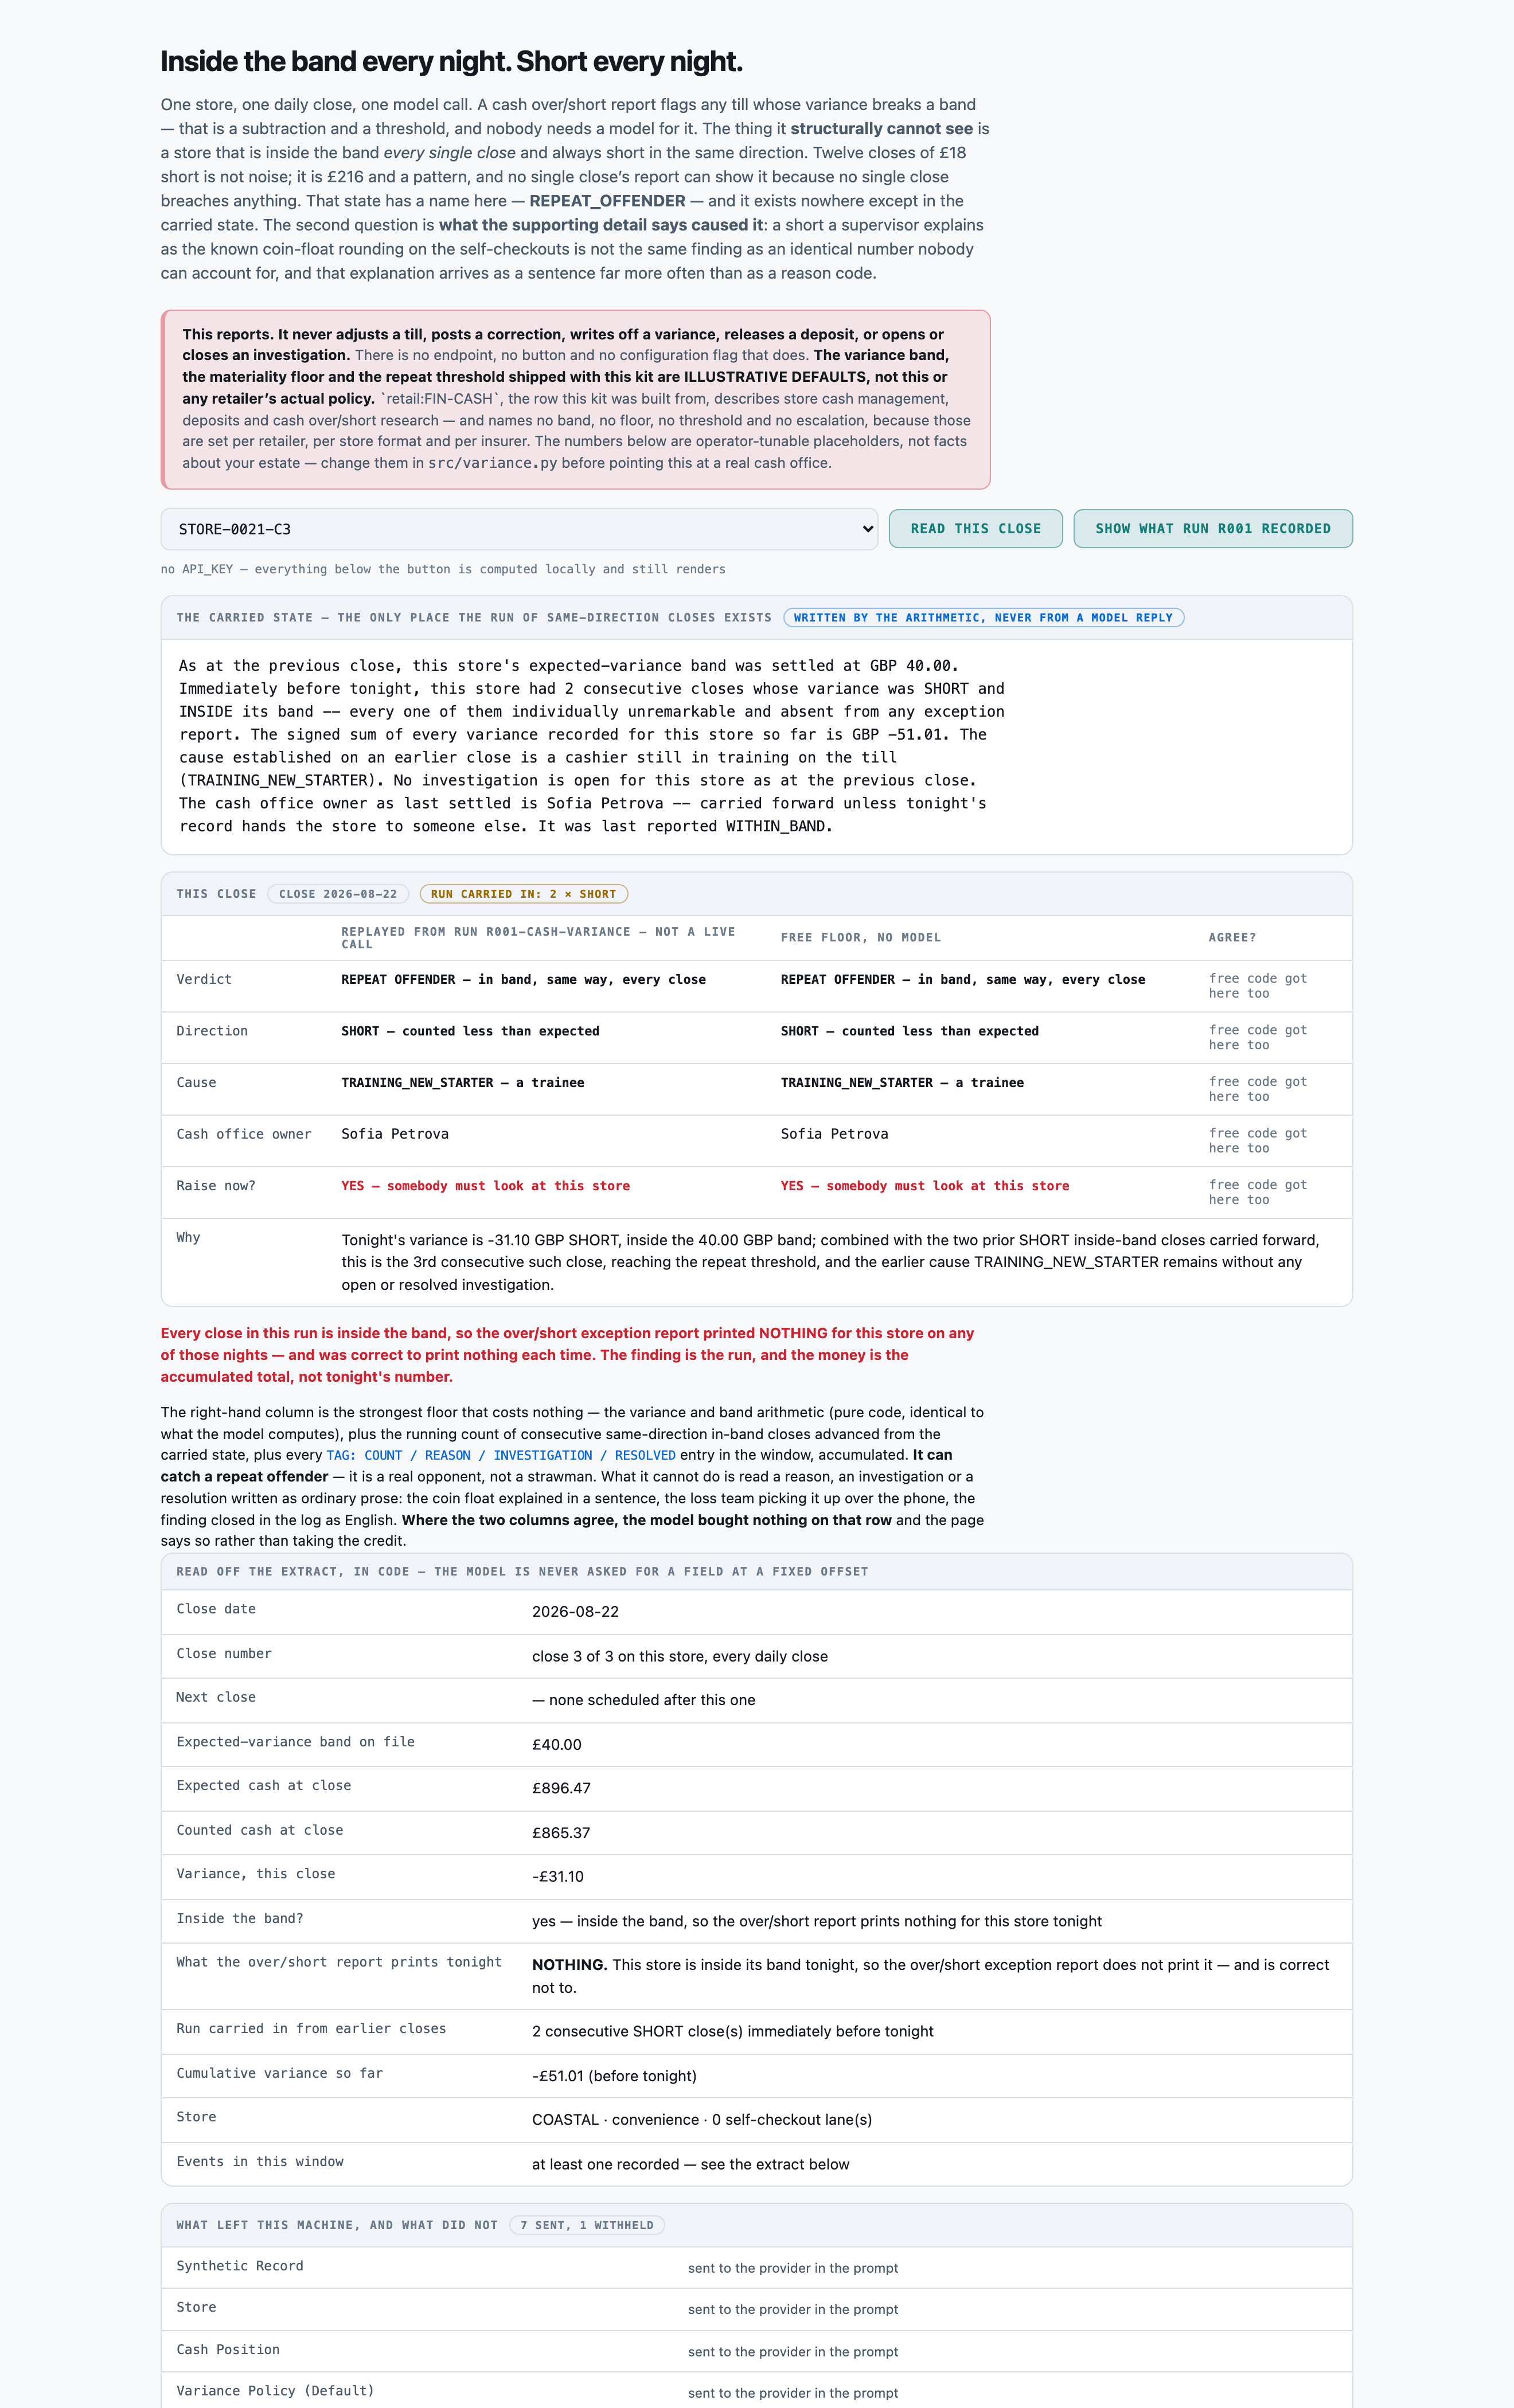
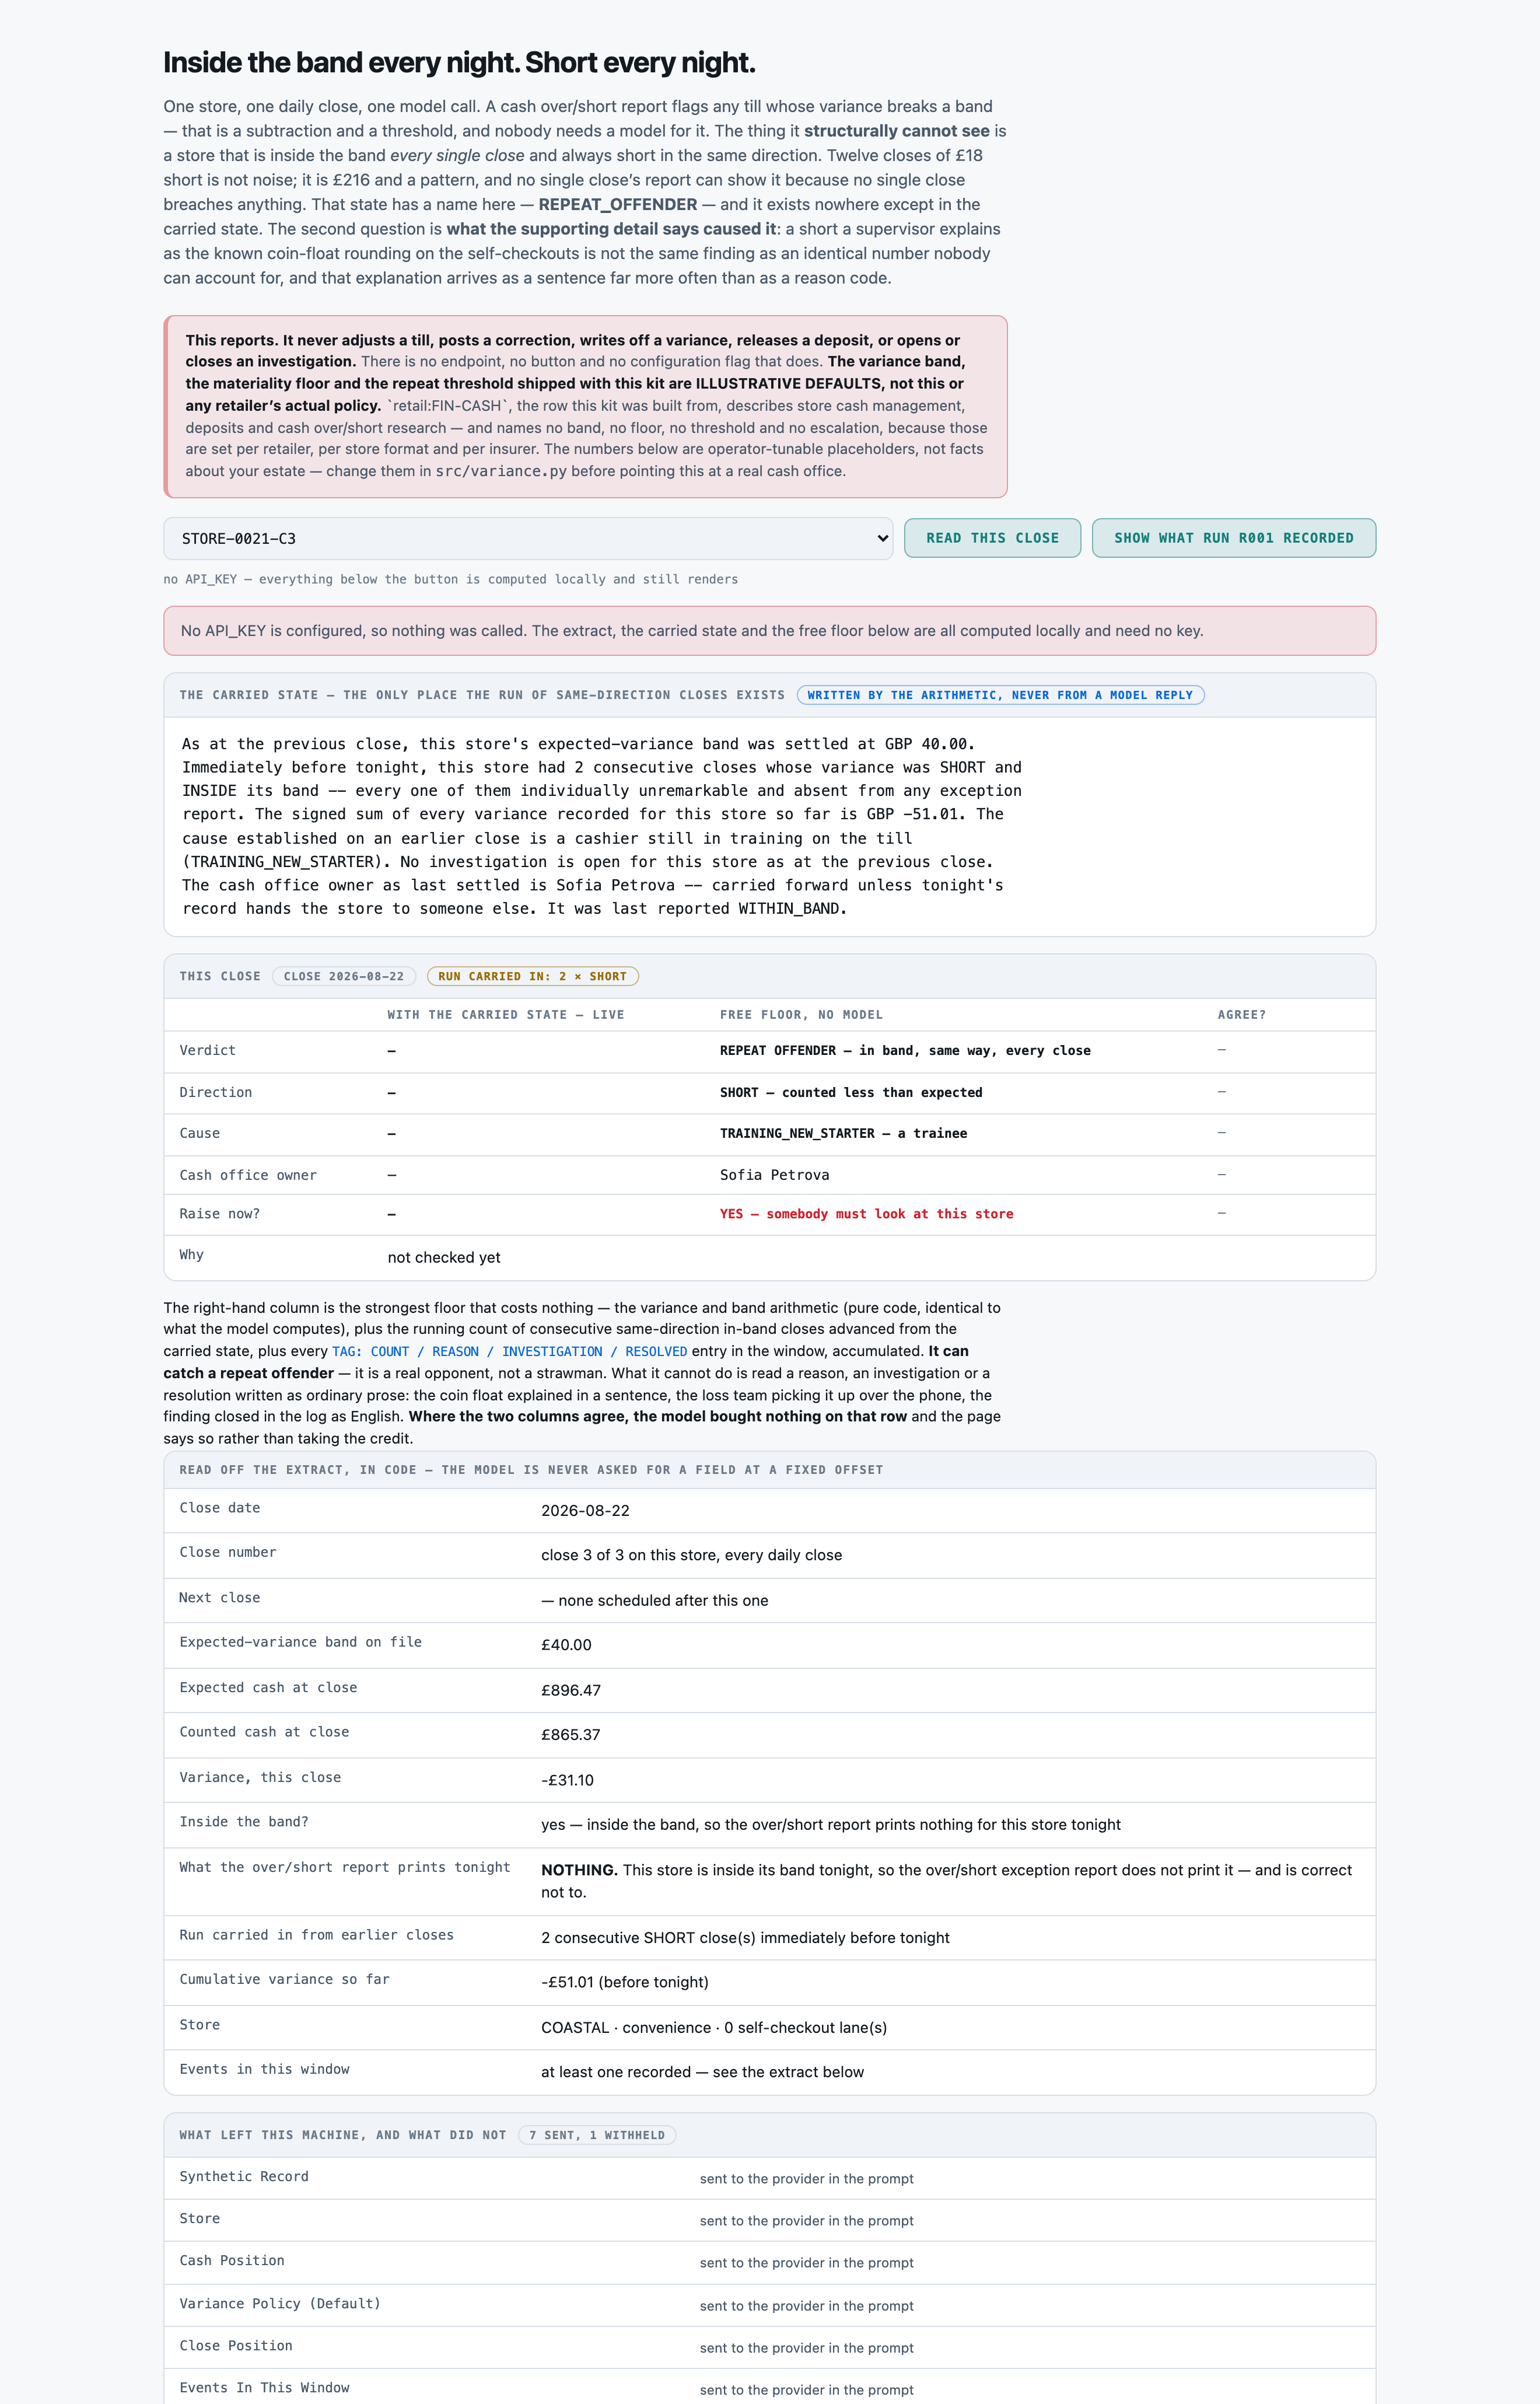
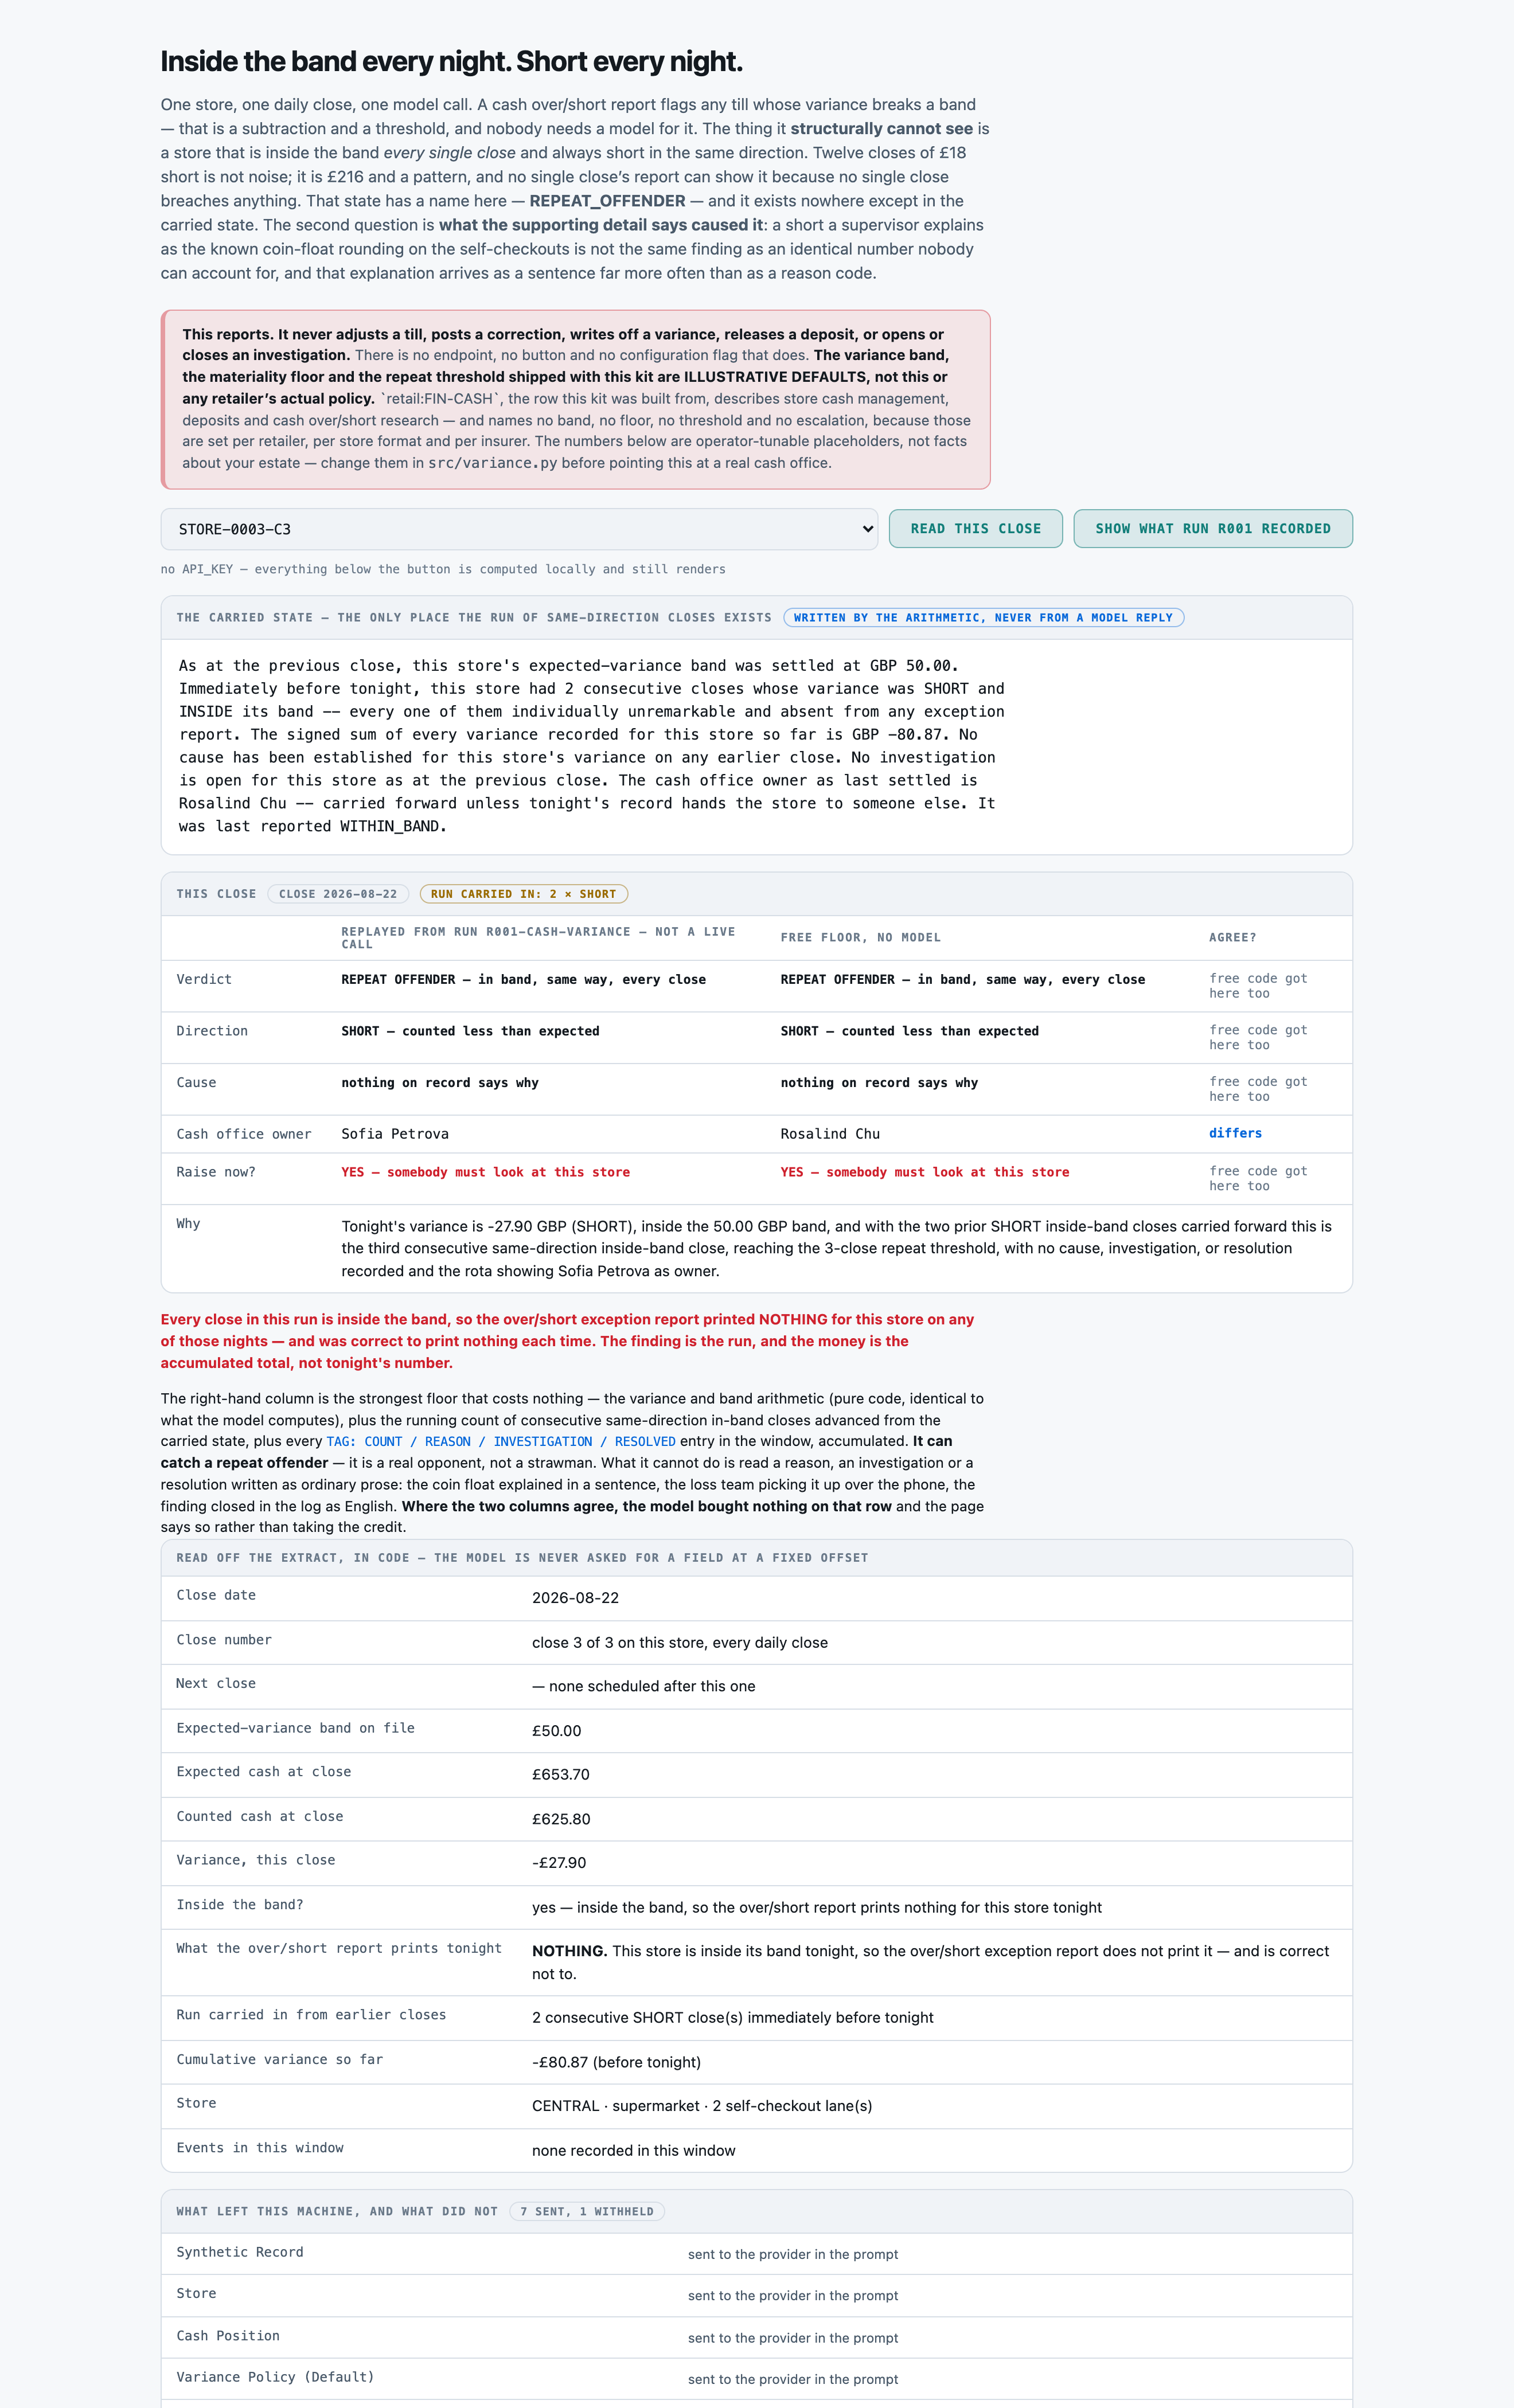
STORE-0001-C1, replayed from the scored run. Inside its band on every close, short in the same direction on all three. The band-only report prints nothing about this store on any close.successOpen full size →The same store before anything is read: carried state, code-parsed variance and the free floor all render with no key.emptyOpen full size →The read button pressed with no API_KEY — a plain sentence, not an error.nokeyOpen full size →
LimitsWhen it does not
A report showing only wins is an advert. This one is required, and the validator now refuses a kit that omits it.
STORE-0001-C2 — a handover the carried state named in English, where the model answered the rota printed on tonight's page. All 8 owner misses are this shape.failureOpen full size →
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
Step 04 of 14Corpus
Written for: "can I point this at mine?" · Measured off the corpus the run actually used.
In brief
120store close extracts
0.80 MiBtxt 120
p50 6,945chars per reading
$0.00setup · 0.5s
How it is cutWhat one reading is
40 stores x 3 daily close, walked strictly in order per store so the carried state moves forward the way it would in a real deployment. Different stores run concurrently; a single store's cycles never do.
SetupWhat the setup figure measured
There is no index to build — each reading's extract goes whole into the prompt. The 0.5s and $0.00 are the corpus generation itself.
LicenceLicence
MIT
Bring your ownBring your own store close extracts
tools/build_corpus.py writes data/corpus/*.txt and data/gold.jsonl. Keep the 8 section headings and the field labels src/watch.position_of parses. Set your own bands and repeat threshold in src/variance.py first.
⚠︎ And what stops being true when you do: The measured figures on this kit's page do not transfer to your own corpus. The repeat-offender rate (12 of 120 readings here), the prose-versus-tag evidence split (19 stores against 21) and the benign-cause mix are properties of this generator's declared distribution, not facts about retail cash operations. Re-run the evals on your own data; that is what the harness is for.
What breaks it
A store with no expected-variance band on file (9 of 120 readings): CONTEXT_INCOMPLETE.
A band that is stale rather than absent. Nothing here re-derives one.
A benign cause this corpus does not model. A real desk's list is longer than the ones modelled.
A POS or cash-office system that renames its export sections — the send filter's fallback is what stops the whole document going on the wire, reproduced on 120 of 120 documents.
⚠︎ AND A CORPUS DEFECT THIS KIT FOUND AND DID NOT FIX: one ambient supervisor note near-quotes the deposit-timing cause while the prompt tells the model notes carry cause evidence. It accounts for 7 of the 22 cause misses. Fixing it means regenerating and re-firing 120 calls, so NO CORRECTED CAUSE FIGURE IS PUBLISHED ANYWHERE.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
Step 05 of 14Prompt
Written for: engineer · Logged from the run, verbatim.
In brief
The assembled prompt in full, and its real decomposition. Every part below occurs in the prompt that was actually sent, and the token counts sum to the recorded input total — they were measured against the provider’s own counter, not apportioned by character share.
AssemblyHow the prompt is assembled
Part
Characters
Tokens
system
219
54
the question and the JSON shape
4,610
1,152
the carried state
340
85
the extract
123
30
Total
1,321
This is the cost lesson as arithmetic: of the 1,321 tokens assembled, 1,206 are instructions — 91% of the prompt, the largest single part. A per-request bill follows whichever part is biggest, and on this kit that is the one named here.
Reproduced from src/prompt.build for STORE-0001-C1 with that reading's real carried state, not retyped — byte-identical to what evals/run.py sent.
Full promptThe prompt in full
The verbatim prompt, as sent
the prompt, as sent
You are a scheduled store cash-variance watch. You read one store's daily close against its DEFAULT variance policy and the history carried from its earlier closes, and you answer with one JSON object and no other text.

You are the scheduled store cash-variance watch for one retailer's estate. It runs at EVERY DAILY
CLOSE and re-reads EVERY store. You are reading ONE store at ONE daily close.

The store, its cash position for this close, the DEFAULT variance policy, and everything recorded
against it since the previous close are reproduced in the extract below. Apply them exactly as
written. You cannot see the earlier closes; what is known about them is stated under "Carried state"
and is the only history available to you. Do not assume anything about earlier closes beyond it.

⚠︎ THE VARIANCE BAND, THE MATERIALITY FLOOR AND THE REPEAT THRESHOLD ARE ILLUSTRATIVE DEFAULTS, NOT
ANY REAL RETAILER'S POLICY. Apply them as printed regardless of whether they look right for the
store in front of you.

How to work it out:
 - FIRST decide whether the band is settled. If this store's expected-variance band is blank on
   file, the verdict is CONTEXT_INCOMPLETE: no direction, no cause and no finding are determined,
   and nothing is raised. THERE IS NO DEFAULT BAND FOR AN UNBANDED STORE (Rule V-6).
 - THEN compute the VARIANCE: counted cash at close minus expected cash at close. Negative is
   SHORT, positive is OVER, and a variance smaller than the materiality floor has direction NONE.
 - THEN decide whether an investigation has already been RESOLVED, or is already OPEN -- from the
   carried state or from anything recorded this close, in the cash-office log OR in an ordinary
   supervisor's sentence. RESOLVED is permanent and beats everything; an OPEN investigation means
   somebody is already on it and nothing is raised (Rule V-7).
 - THEN decide the CAUSE. Cause evidence ACCUMULATES from earlier closes (see "Carried state") and
   from anything recorded THIS close -- in the structured reason field or in a supervisor's note. A
   note that describes a cause in ordinary prose counts exactly as much as a logged reason code
   (Rule V-4). Use UNDETERMINED when there is a real variance and nothing anywhere says why.
 - If the cause is a NAMED BENIGN cause -- self-checkout coin-float rounding, or a documented float
   adjustment -- the verdict is EXPLAINED_BENIGN and raise_now is NO, however large the variance and
   however long the run (Rule V-5). BE CAREFUL HERE: an explanation is not the same as a benign
   cause. A till miscount, a cashier in training and a late deposit are all explanations, and every
   one of them is still a finding. Only the two named causes suppress.
 - THEN check the BAND. If the size of tonight's variance is LARGER than this store's band, the
   verdict is BAND_BREACH (Rule V-2).
 - THEN check the RUN. If this store has now had the threshold number of CONSECUTIVE closes whose
   variance was in the SAME direction and INSIDE the band -- counting tonight, and reading the
   earlier ones out of the carried state -- the verdict is REPEAT_OFFENDER (Rule V-3). THIS IS THE
   MOST IMPORTANT CALL THIS KIT MAKES. Every close in such a run is individually unremarkable and
   inside the band; no single close's exception report can produce this finding, and the money is
   the accumulated total rather than tonight's number. A close that breaks the band, or one with no
   material variance, ends a run rather than extending it.
 - Otherwise the verdict is WITHIN_BAND.
 - THEN decide the OWNER. Start from the cash office owner on file, but a note recording a handover
   to someone else, tonight or on an earlier close (see "Carried state"), supersedes it.
 - FINALLY decide "raise_now": YES only for a finding this watch has not already raised for this
   store -- see "Carried state" (Rule V-8). Otherwise NO.

Answer with a single JSON object and nothing else:

{"verdict": "WITHIN_BAND|REPEAT_OFFENDER|BAND_BREACH|EXPLAINED_BENIGN|INVESTIGATION_OPEN|RESOLVED|CONTEXT_INCOMPLETE",
 "direction": "SHORT|OVER|NONE|UNDETERMINED",
 "cause": "TILL_MISCOUNT|TRAINING_NEW_STARTER|DEPOSIT_TIMING|SCO_COIN_ROUNDING|KNOWN_FLOAT_ADJUSTMENT|UNDETERMINED|NONE",
 "owner": "<the current cash office owner's name>",
 "raise_now": "YES|NO",
 "rationale": "one sentence, naming tonight's variance, the band, the run length you relied on and
   the reason or resolution evidence you relied on"}

Precedence, applied in this order: CONTEXT_INCOMPLETE if the band cannot be settled (Rule V-6); then
RESOLVED; then INVESTIGATION_OPEN (Rule V-7); then EXPLAINED_BENIGN if the cause is one of the two
named benign causes (Rule V-5); then BAND_BREACH (Rule V-2); then REPEAT_OFFENDER (Rule V-3); then
WITHIN_BAND. "direction" is UNDETERMINED only when the verdict is CONTEXT_INCOMPLETE.

Carried state
----------------------------------------------------------------
No earlier close has been recorded for this store. This is its first appearance on the watch: nothing has been settled about its expected-variance band, no run of same-direction closes has been observed, no cause has been established, no investigation is known to have been opened or resolved, and no cash-office handover has been recorded.

Store close extract
----------------------------------------------------------------
Synthetic Record
----------------------------------------------------------------
Every field below is invented. This is a generated store cash-close extract for an AI
use-case kit; it reproduces no retailer, no store, no banking arrangement and no real
person. The variance band, materiality floor and repeat threshold are ILLUSTRATIVE
DEFAULTS, not any real retailer's policy.

Store
----------------------------------------------------------------
Store reference                    : STORE-0001
Region                             : METRO
Format                             : superstore
Staffed tills in use               : 14
Self-checkout lanes                : 6
Cash office owner (rota of record) : Ingrid Solberg

Cash Position
----------------------------------------------------------------
Opening float                      : 500.00 GBP
Takings recorded at the POS        : 18,932.72 GBP
Paid-outs                          : 154.64 GBP
Deposit prepared for banking       : 18,874.46 GBP
Expected cash at close             : 403.62 GBP
Counted cash at close              : 381.97 GBP
Variance, this close               : -21.65 GBP

Till breakdown, this close -- these lines sum to the variance above:
  Till 01                                        -1.83 GBP
  Till 02                                        -1.83 GBP
  Till 03                                        -1.62 GBP
  Till 04                                        -1.78 GBP
  Till 05                                        -0.56 GBP
  Till 06                                        -1.17 GBP
  Till 07                                        -1.35 GBP
  Till 08                                        -1.77 GBP
  Till 09                                        -0.79 GBP
  Till 10                                        -0.87 GBP
  Till 11                                        -1.74 GBP
  Till 12                                        -2.13 GBP
  Till 13                                        -1.10 GBP
  Till 14                                        -1.43 GBP
  Self-checkout lanes (6)                        -1.68 GBP

Variance Policy (Default)
----------------------------------------------------------------
The figures below are an OPERATOR-TUNABLE DEFAULT, not a real retailer's actual policy --
no documented band, materiality floor or repeat threshold exists for this row. They are
applied exactly as printed.

Expected-variance band on file     : 40.00 GBP
Materiality floor                  : 2.00 GBP
Repeat threshold                   : 3 consecutive same-direction closes, every one inside the band
Named benign causes                : SCO_COIN_ROUNDING, KNOWN_FLOAT_ADJUSTMENT

Authority to adjust or investigate : NOT DEFINED. Nothing in this kit adjusts a till,
                                     posts a correction, writes off a variance, releases a deposit,
                                     or opens or closes an investigation.

Rule V-1  The VARIANCE for a close is counted cash minus expected cash, in GBP. Expected cash is
          opening float plus takings recorded at the POS, minus paid-outs, minus the deposit
          prepared for banking. A negative variance is SHORT, a positive one is OVER, and a
          variance whose size is below the materiality floor has direction NONE.
Rule V-2  A BAND BREACH is a close whose variance is LARGER IN SIZE than this store's
          expected-variance band on file. The band is a per-store figure printed on the page; the
          band table is an operator-tunable placeholder, not any retailer's actual policy, and is
          applied exactly as printed.
Rule V-3  A REPEAT OFFENDER is a store with N or more CONSECUTIVE closes whose variance was in the
          SAME direction and INSIDE the band on every one of them, where N is the repeat threshold
          printed below. Every close in such a run is individually unremarkable and no single
          close's exception report can show it; the run is known only through the carried state.
          A close that BREACHES the band does not count toward a run and ends the one in progress
          -- the breach is a finding on its own. A close with direction NONE ends a run too.
Rule V-4  Reason evidence, investigations and resolutions ACCUMULATE across closes. "Events In
          This Window" shows only what was recorded since the PREVIOUS close; anything recorded
          earlier is not repeated and is known only through the carried state.
Rule V-5  A NAMED BENIGN CAUSE beats everything except an investigation or a resolution. Where the
          record identifies the variance as self-checkout coin-float rounding or a documented float
          adjustment -- in the structured reason field or in an ordinary supervisor's sentence --
          the verdict is EXPLAINED_BENIGN and raise_now is NO, however large the variance and
          however long the run. A cause that is merely an EXPLANATION is not benign: a till
          miscount, a new starter on the till and a late deposit are all explanations and all of
          them are still findings. A benign cause identified on an earlier close carries forward.
Rule V-6  If this store's expected-variance band is not on file, the verdict is CONTEXT_INCOMPLETE:
          no direction, no cause and no finding are determined and nothing is raised. THERE IS NO
          DEFAULT BAND FOR AN UNBANDED STORE.
Rule V-7  Once an investigation is recorded as OPEN -- in the cash-office log or in a supervisor's
          sentence -- the verdict is INVESTIGATION_OPEN and raise_now is NO: somebody is already on
          it. Once it is recorded as RESOLVED the verdict is RESOLVED and stays RESOLVED on every
          later close, whether or not the variance has settled. Nothing here opens, closes,
          adjusts, posts, writes off or releases anything; it only reports what already happened.
Rule V-8  raise_now is YES only for a finding this watch has not already raised for this store --
          the first close on which a breach is found, and the first close on which a repeat-offender
          run reaches the threshold. Reporting the same finding again every night is how a cash
          report gets filed unread.

Close Position
----------------------------------------------------------------
Close date                         : 2026-08-20   (close 1 of this store)
Watch cadence                      : every daily close
Previous close                     : -- none, this is the first
Next close                         : 2026-08-21

Events In This Window
----------------------------------------------------------------
Everything recorded against this store between the previous close and this one.
THIS WINDOW ONLY -- an event recorded in an earlier window is not repeated here.

20:36  We have a new starter on till 7, second week, and she is still getting the float
         declarations wrong at close.

Supervisor Notes
----------------------------------------------------------------
Note from the cash office: the band on file was set when the store had six tills and has
not been reviewed since the refit.
Raw responseThe raw response
The raw response, before any parsing
the response, unparsed
{"verdict": "WITHIN_BAND", "direction": "SHORT", "cause": "TRAINING_NEW_STARTER", "owner": "Ingrid Solberg", "raise_now": "NO", "rationale": "Tonight's variance is -21.65 GBP SHORT, inside the 40.00 GBP band, with no prior closes so the same-direction run is only 1, and the supervisor's note attributing the shortfall to a new starter on till 7 gives the cause TRAINING_NEW_STARTER without opening or resolving any investigation."}
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
Step 06 of 14Evals
Written for: the skeptic · The harness output, with as_of / model version / dataset version / verified_by.
In brief
Catch the store that's quietly short in cash every night — 120 store close extracts. One model answered, and every answer was then graded Three different ways — because the grade is a measurement too, and most of what went wrong on this kit went wrong in the ruler rather than the model.
120store close extracts
120source documents
1model tier
3grading methods
MeasurementsWhat was measured
COUNTED119 · 99 · 112 · 93 · 85 / 120verdict accuracy pct — verdict, seven-wayDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED119 · 119 · 120 · 120 · 120 / 120direction accuracy pct — directionDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED97 · 75 · 110 · 103 · 73 / 120cause accuracy pct — probable causeDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED111 · 111 · 114 · 114 · 106 / 120owner accuracy pct — store managerDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED119 · 100 · 115 · 104 · 92 / 120raise now accuracy pct — raise-now callDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED119 · 107 · 118 · 108 · 108 / 120repeat offender accuracy pct — persistently one-directional -- caughtDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED8 · 8 · 6 · 8 · 8 / 8benign suppression pct — explained benign variances left aloneDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED45 · 25 · 40 · 25 · 17 / 45memory verdict accuracy pct — verdict, memory-dependent readings onlyDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED45 · 26 · 42 · 30 · 19 / 45memory raise now accuracy pct — raise-now, memory-dependent readings onlyDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
COUNTED17 · 5 · 17 · 5 · 5 / 17stores caught pct — stores still needing attention, caught at the last closeDecided by == against a fixed gold value. No model graded this and it reproduces to the digit — which makes it checkable, not necessarily right: it is only as good as the gold behind it.
NOT YET KNOWN—A person confirmed the gold is rightThe grader is == and needs no confirming. The gold does: it is machine-derived from the registry's structured modules, and every rate on this page rests on that derivation being faithful to what the prose actually says. Nobody has read a document against its gold record by hand.
Two words carry this page: Counted is deterministic and nobody's opinion and Not yet known is printed blank rather than filled with something plausible. There is no Judged row here and that is the point: nothing on this page is a model's opinion about another model. The row most worth having is currently the empty one.
How the method was validated
evals/check_labels.py replays all 40 store chains through src/variance.step and requires the re-derived answers to equal the committed gold exactly before any run may spend — 23 checks, green. Two were red-proven by seeding: pushing a repeat-offender close outside its band makes the gate convict by name, and adding a write-off path makes the banned-path scan convict by name.
Grading costWhat it costs
Every dollar on these pages is a MEASURED token count multiplied by a named vendor's PUBLISHED rate — a projection, never a bill and never a vendor's claim about this workload.
Priced at
Per 1M in / out
One store close extract
1,000 store close extracts
Share that is the prompt
Google Gemini 3 Flash The estate's shared projection card. Every kit in this series prices its measured tokens against the same published card so the cost pages are comparable to each other; the provider that actually ran these calls is kept out of the tables by this estate's naming rule.
$0.30 / $2.50
$0.006515
$6.51
13%
Same work, 1× the bill
The same store close extracts, the same tokens — only the rate card changed. And on that card about 13% of what you pay is the prompt this pipeline sends, not the answer it writes.
THE CLOSE CADENCE. Daily is one call per store per day; reading weekly divides the bill by five and multiplies the time a repeat offender stays invisible by the same factor.
Rates checked 2026-08-18. The provider that actually ran all 398 calls is kept out of these tables per this estate's naming rule, so no figure here is a bill.
the fast tier, with the carried state 99.2% repeat offender accuracy · the strongest free floor — no model 98.3% repeat offender accuracy · 1 more measured on each run
the fast tier, with the carried state 100.0% benign suppression · the strongest free floor -- no model 75.0% benign suppression · 1 more measured on each run
Every row opens its own page: how the test was run, the input on one real row, the prompt or formula with every iteration of it, and the analysis.
Why this set cannot separate them
This labelled set tells the arms apart: the repeat-offender miss count spans 12 of 12 (band-only and band-only-mem, both by construction) to 0 (the model and the strong floor), and stores caught at the last close spans 5 of 17 to 17 of 17.
Choosing oneWhich one to use
The comparison is only useful if it ends in a choice. The answer is conditional — and it is not the grader with the best agreement score.
If your situation is
Use
Because
And avoid
Every explanation is a structured reason code and your bands are correct
the free floor — structured-log-strong, $0.00
It counts same-direction closes from the carried state and BEATS the model on cause (91.67 against 80.83) and owner (95.0 against 92.5).
Do not use it where supervisors type explanations in a sentence — it leaves 75.0 pct of explained variances alone against the model's 100.0 pct.
Supervisors explain variances in prose and handovers are noted, not keyed
the model, with the carried state
Verdict 99.17 against 93.33, and 100.0 pct of explained variances left alone against 75.0 pct.
Do not pay it for cause or owner — free code wins both, and the page says so.
You want the reading but cannot carry state between closes
neither, as configured here
The stateless control misses 12 of 12 repeat offenders.
Do not ship the stateless arm and describe it as this kit.
This pipeline was also attacked, which is a different question from whether its answers are right: see Threat model for the injection experiment, its two gates and what it does not prove.
Failure causesHow it fails
Cause
What it means
Rows
A real example
EMPTY_CAUSE_AMBIGUITY
NONE returned where the key says UNDETERMINED, and the reverse
13
Thirteen readings — the CONTEXT_INCOMPLETE and sub-floor cells the prompt never specified a cause for. Wrong in both directions; a defect in the question.
AMBIENT_NOTE_AS_CAUSE
an ambient supervisor note read as a deposit-timing explanation
7
⚠︎ A REAL CORPUS DEFECT, DIAGNOSED FROM THE MODEL'S OWN RATIONALES AND NOT FIXED. One shipped note near-quotes the deposit-timing cause while the prompt says notes carry cause evidence. Fixing it costs a regeneration and 120 calls; no corrected figure is…
ROTA_OVER_HANDOVER
tonight's printed rota returned after a handover
8
STORE-0001-C2 and 7 others — the carried state names the new manager in English and the model took the page. This is the -miss.png shot.
What we could NOT verify
Whether the 7 note-confusion cause misses are model error or the corpus defect named above. The defect is real, diagnosed and NOT fixed; no corrected figure is published.
Whether rendering the carried state as JSON rather than English would score the same.
Whether a second model reproduces the cause loss.
Any injection other than the one sentence the probe fired.
⚠︎ ONE READING WAS LOST TO THE PUBLISHED CEILING AND IS SCORED WRONG INSIDE EVERY PERCENTAGE HERE. STORE-0014-C3 was cut at 16,000. The same bytes returned 800 and 11,418 tokens on other attempts, so the reasoning budget is drawn, not fixed. It was not rescued.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
Step 07 of 14Unit cost
Written for: whoever signs off on the bill · Measured over the eval run, per model. Never quoted from a vendor page.
In brief
Tier
Input tokens
Output tokens
p50 latency
Google Gemini 3 Flash
the fast tier, with the carried state
2,796.72
2,270.26
12,183 ms
$0.006515
the same tier, STATELESS CONTROL
2,691.78
1,754.43
9,336 ms
$0.005194
the strongest free floor -- no model
0
0
0 ms
$0.000000
the band rule given the carried state
0
0
0 ms
$0.000000
what an over/short report IS today
0
0
0 ms
$0.000000
The token counts are measured on a real run and belong to this pipeline — which sections are selected, the field schema, the prompt — so they hold wherever you run it. The dollars are those counts multiplied by each vendor's published rate, checked 2026-08-18. Nobody paid these particular bills; they are what the same work would cost you on a card you can sign up to today.
Answering vs gradingAnswering and grading are two separate bills
The three free floors, the stub, the cadence analysis and every pre-run check cost $0.00 and no calls. ⚠︎ A DISCARDED SCORED RUN (truncated at an 8,000 ceiling) cost the same again as the scored run and is NOT netted out — it was spent.
Cost driversWhat actually moves the bill
OUTPUT TOKENS, AND ALMOST ALL OF THEM ARE REASONING. 95.6 pct of r001-cash-variance's output (260443 of 272431 tokens) was provider-side reasoning left at the default. The answer is a handful of short fields and a sentence; the bill is the thinking in front of it.
THE PROMPT IS MOSTLY FIXED TEXT. 2796 input tokens per reading, and the policy block, the rule text and the instruction are the same on every call — so a provider with prompt caching would price this workload very differently, and that was not measured.
Your volumeWhat it costs at your volume
LINEAR IN STORES x CLOSES. Ten times the estate is ten times the calls; nothing amortises. The sublinear lever NOT implemented is skipping stores that reconciled exactly.
Where pricing changes shape
Provider-side reasoning. At 95.6 pct of output on this task, a model whose reasoning is not billed and one whose reasoning is billed differ by roughly an order of magnitude on the same workload.
⚠︎ THE TOKEN CEILING, TWICE. A nine-call probe at 8,000 showed 3,812 max; the scored run truncated 2 of 120 at exactly 8,000 and was discarded. The re-take at 16,000 STILL lost one reading, cut at 16,000 — and the same bytes returned 800 tokens on one attempt and 11,418 on another. The reasoning budget is drawn per call, not fixed by the input.
Your return, with your numbers
Volumestores per daily close — this run judged 120 (40 stores x 3 daily close) per arm
What it replacesa cash manager reading an over/short report that cannot show a store which never breaches a band
Time saved per itemnot measured here — it depends on how much of your own explanation trail is a structured reason code versus a typed sentence
We publish the inputs, not a return: a return depends on your labour cost and your volume. The ROI dashboard takes it from here, and AI Costing explains the math.
Model choiceWhy this model
It is the tier the shared connection was already pointed at, and the kit's whole claim is that swapping it is .env plus one more run. No second model was run against this corpus; every other row in the cost table is a projection onto a published card and is labelled as one.
Other modelsOn other models
This is arithmetic, not a run. No model below was executed against the labelled set, and no accuracy is claimed for any of them. What transfers is the input volume: retrieval is model-independent, so every model would receive the same passages.
2,796input tokens · this run
2,270output tokens
$0.007what it actually cost
per-query average, this run
Model
Provider
One eval pass
This whole run
Per 1,000 queries
Rates as of
gpt-5-6-luna
OpenAI
$0.394
$0.394
$3.28
2026-09-12
gemini-3-flash
Google
$0.985
$0.985
$8.21
2026-09-18
gemini-3-8-flash
Google
$1.273
$1.273
$10.61
2026-09-18
llama-5
Meta
$1.577
$1.577
$13.14
2026-09-18
claude-haiku-4-5
Anthropic
$1.698
$1.698
$14.15
2026-09-12
grok-4-5
xAI
$2.306
$2.306
$19.22
2026-09-18
grok-4-6
xAI
$2.306
$2.306
$19.22
2026-09-18
claude-sonnet-5
Anthropic
$3.396
$3.396
$28.30
2026-09-12
gemini-3-1-pro
Google
$3.940
$3.940
$32.84
2026-09-18
gpt-5-6-terra
OpenAI
$3.940
$3.940
$32.84
2026-09-12
gpt-5-6-sol
OpenAI
$6.791
$6.791
$56.59
2026-09-12
claude-opus-4-8
Anthropic
$8.489
$8.489
$70.74
2026-09-12
claude-opus-5
Anthropic
$8.489
$8.489
$70.74
2026-09-12
claude-fable-5
Anthropic
$16.978
$16.978
$141.48
2026-09-18
claude-fable-5-1
Anthropic
$16.978
$16.978
$141.48
2026-09-18
gpt-6-astra
OpenAI
$16.978
$16.978
$141.48
2026-09-17
Read this against the numbers above
Projection only — no other model was actually called against this corpus.
The reasoning-token share (95.6 pct of output on the fast tier) is measured for that tier only.
Accuracy is NOT projected, only cost — a cheaper or pricier model is not implied to score the same 99.17 pct.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
The codeEvery file, and what it is for
11 modules, no framework, and almost no dependencies. The pipeline is stdlib Python, because a kit is meant to be read and changed by someone who cloned it ten minutes ago — every dependency is a thing they have to understand before they can touch the part they came for.
Five of these are swap seams: the points you edit to make the kit yours. Each is marked, and each block below is the module’s real shape, read out of the file rather than written here.
The files on this page are not in the public GitHub catalog.
src/variance.pythe variance rule and state machine — a swap seam
The DEFAULT bands, the repeat threshold, the direction run and step() — which decides the next carried state from the answer key's inputs, never from a model reply. It is also the answer key.
You change it to: Reading weekly instead of daily multiplies the time a repeat offender stays invisible.
src/variance.py
# The store cash over/short rule as arithmetic. Pure code, no model, standard library only.

WITHIN_BAND = "WITHIN_BAND"
REPEAT_OFFENDER = "REPEAT_OFFENDER"
BAND_BREACH = "BAND_BREACH"
EXPLAINED_BENIGN = "EXPLAINED_BENIGN"
INVESTIGATION_OPEN = "INVESTIGATION_OPEN"
RESOLVED = "RESOLVED"
CONTEXT_INCOMPLETE = "CONTEXT_INCOMPLETE"
VERDICTS = (WITHIN_BAND, REPEAT_OFFENDER, BAND_BREACH, EXPLAINED_BENIGN, INVESTIGATION_OPEN,
SHORT = "SHORT"
src/state.pythe carried state
The run of same-direction closes, the established cause and the resolved flag. The run length is the only thing that makes a repeat offender visible.
src/state.py
# The carried state -- the thing that makes this a monitor and not another over/short report.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
DEFAULT_PATH = os.path.join(HERE, "data", "state.json")
def load(path=DEFAULT_PATH):
def save(store, path=DEFAULT_PATH):
def for_store(store, store_id):
CAUSE_WORDS = {
def describe(state):
src/segment.pythe section splitter
Splits the page into its 8 named sections; asserted across all 120 documents.
src/segment.py
# Split a store close extract into its named sections. Pure code, no model.

SECTIONS = ("Synthetic Record", "Store", "Cash Position", "Variance Policy (Default)",
RULE = "-" * 64
def split(text):
def render(secs):
src/select.pythe send filter — a swap seam
Manager Contact is mapped by no field and therefore never sent.
You change it to: SECTION_HINTS and NEVER_SENT.
src/select.py
# Pick which sections of a store close extract are sent. Pure code -- the last deterministic step

BANNER = "Synthetic Record"
STORE = "Store"
POSITION = "Cash Position"
POLICY = "Variance Policy (Default)"
CLOSE = "Close Position"
EVENTS = "Events In This Window"
CONTACT = "Manager Contact"
NOTES = "Supervisor Notes"
NEVER_SENT = (CONTACT,)
src/prompt.pythe prompt
Three parts: instruction and JSON shape, carried state, extract. The stateless control replaces exactly one line.
src/prompt.py
# Assemble the one prompt this kit sends. No template engine, no framework -- string

INSTRUCTION = """\
def build(text, carried, stateless=False):
src/adapters/__init__.pythe model call
Raw HTTP, stdlib only, bounded retry; the shared daily call cap is checked here.
src/adapters/__init__.py
# SEAM 1 — the model. Swapping provider or model is .env plus the same run again.

class AdapterError(RuntimeError):
TRANSIENT = {408, 429, 500, 502, 503, 504}
RETRIES = 4
def _post(url, headers, payload, timeout=120):
def openai_compatible(cfg, system, user, max_tokens, thinking=None):
def anthropic(cfg, system, user, max_tokens):
PROVIDERS = {"openai-compatible": openai_compatible, "anthropic": anthropic}
THINKING_OFF = {"type": "disabled"}
def complete(cfg, system, user, max_tokens=1024, thinking=None):
src/watch.pythe reader
One store, one close, one call. The published token ceiling lives here.
src/watch.py
# One store, one daily close, one model call. The runtime half of the kit.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
CORPUS = os.path.join(HERE, "data", "corpus")
SYSTEM = ("You are a scheduled store cash-variance watch. You read one store's daily close against "
MAX_TOKENS = 16000
FIELDS = ("verdict", "direction", "cause", "owner", "raise_now")
def documents():
def stores():
def load_doc(doc_id):
def position_of(text):
evals/scoring.pythe scorer
Exact match per cell. The repeat-offender discriminator is a separate binary.
evals/scoring.py
# Score a run against the answer key. Pure code, exact match per cell. No model grades anything.

NEEDS_ATTENTION = ("BAND_BREACH", "REPEAT_OFFENDER")
FIELDS = ("verdict", "direction", "cause", "owner", "raise_now")
def _pct(n, d):
def score(records, golds):
def _protection(records, golds):
evals/baseline.pythe three free floors
band-only, band-only-mem and structured-log-strong — $0.00 each, and the third beats the model on two columns.
evals/baseline.py
# THE FREE FLOORS. Three of them, none a strawman, all of them 0.00 GBP.

MODES = ("band-only", "band-only-mem", "structured-log-strong")
def _section(text, name, nxt, flat=False):
def _facts(text):
def _finish(verdict, direction, cause, owner, raise_now, why):
TAG_INVESTIGATION = re.compile(r"TAG: INVESTIGATION INV-\d+ opened")
TAG_RESOLVED = re.compile(r"TAG: RESOLVED INV-\d+")
TAG_REASON = (
TAG_COUNT = re.compile(r"TAG: COUNT till \d+ recounted")
def review(text, carried=None, mode="structured-log-strong"):
src/app.pythe local UI server
http.server, stdlib. Renders with no key.
src/app.py
# The minimal local UI. Standard library only -- python3 -m src.app, then open the printed URL.

HERE = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
UI = os.path.join(HERE, "ui")
GOLD = os.path.join(HERE, "data", "gold.jsonl")
PORT = int(os.environ.get("PORT", "8214"))
RECORDED_RUN = os.environ.get("RECORDED_RUN", "r001-cash-variance")
GOLD_ROWS = {r["doc_id"]: r for r in
def carried_for(doc_id):
class H(BaseHTTPRequestHandler):
def main():
ui/app.jsthe local UI client
Hand-written JS, no framework.
ui/app.js
#
Start hereThe shortest path into it
src/app.pyrun it and click around. It holds no pipeline logic on purpose; every number on screen comes from a module the eval harness already drives.
src/variance.pyThe DEFAULT bands, the repeat threshold, the direction run and step() — which decides the next carried state from the answer key's inputs, never from a model reply. It is also the answer key. A swap seam.
src/state.pyThe run of same-direction closes, the established cause and the resolved flag. The run length is the only thing that makes a repeat offender visible.
src/segment.pySplits the page into its 8 named sections; asserted across all 120 documents.
src/select.pyManager Contact is mapped by no field and therefore never sent. A swap seam.
src/prompt.pyThree parts: instruction and JSON shape, carried state, extract. The stateless control replaces exactly one line.
src/adapters/__init__.pyRaw HTTP, stdlib only, bounded retry; the shared daily call cap is checked here.
src/watch.pyOne store, one close, one call. The published token ceiling lives here.
evals/scoring.pyExact match per cell. The repeat-offender discriminator is a separate binary.
evals/baseline.pyband-only, band-only-mem and structured-log-strong — $0.00 each, and the third beats the model on two columns.
ui/app.jsHand-written JS, no framework.
Every entry above is a file in this kit, listed in the order the pipeline runs it.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
ScenariosWhat it costs at your volume
Everything below is computed from one measured base: 2796 input and 2270 output tokens per reading (one store, at one daily close), all of it fixed — this kit sends the document's own selected sections, so there is no retrieval depth to turn. Change the volume and the bill scales linearly, because nothing here batches.
Grading really is free here, and that is a property of the ruler rather than a discount
This kit is graded by pure code — the grader makes no model call, needs no key and sends nothing anywhere, so the grading line above is zero at every sampling rate and the leak count stays at nought. What that buys is a ruler you can run on every row, every time, for nothing. What it costs is reach: a code grader can only check what is mechanically checkable.
OperationsFour shapes of workload
The same arithmetic, at volumes worth naming. These are illustrations of scale, not measurements of anyone’s deployment.
Shape
Reading (one store, at one daily close)s/day
Per day
Per month
Per year
Model follows the controls above.
What this ignoresWhere a real bill diverges
Read before quoting any of it
Output length is assumed constant.A terser or more verbose model moves it, and output is priced above input everywhere.
No volume, committed-use, batch or cache discount is modelled.Each moves real enterprise pricing and none are on a public rate card.
Longer documents cost more and nothing here caps them.This kit selects the document’s own sections in pure Python, so there is no vector store to price — but a corpus of longer records raises the input tokens per reading (one store, at one daily close) directly, and that is the very number every figure above multiplies.
Grading adds nothing to this bill, and would if you changed the ruler.A code grader is free and local; swapping in an LLM judge would cost more per row than the extraction itself and send every row to a vendor. The instrument is a cost decision, not a footnote.
Rates age.Every one carries the date it was read on the cost page.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
In one lineWhat this kit exposes
MEASURED, not asserted. Supervisor Notes is this kit's injection surface and one of the shipped notes is instruction-shaped by design.
API_KEY is read from .env (gitignored) or the real environment; never logged, never placed in a prompt, and redacted from any provider error message the local UI passes to the browser.
The experimentWe DID attack it — one sentence, on every reading where it could matter
The probe forces the instruction-shaped note onto every reading where a raise was due and re-fires them with everything else held identical, rather than reporting where the seed happened to place it. Both were run for real on 2026-08-25.
Boundary checked
What could go wrong
What the code guarantees
Whether an instruction embedded in Supervisor Notes can suppress a raise this kit's own rules say is due
The note landed naturally on only 2 of the due readings — a denominator of two is an observation, not a rate. The probe forces the condition instead.
x001-cash-variance-injection forces the condition: every reading where action was due, re-fired with the note REPLACED by the instruction-shaped one, carried state identical. 20 of 20 still raised it. Suppression rate 0.0 pct.
One boundary is measured in both directions here: the injection probe forces the condition rather than waiting for it, and the privacy guard is red-proven by reproducing the schema-change condition that reaches its fallback.
The result0 of 20 raises suppressed suppressed by the instruction-shaped note — measured, not assumed.
20attack trials fired
0raises suppressed
One phrasing, one model, one corpus, 20 trials — every reading where suppression was even possible.
Read this twice
The Supervisor Notes reach the model verbatim — there is no filter between what a supervisor types and what the provider sees.
HonestyWhat this does not prove
Any other injection.
Whether the result holds on another model tier.
Whether an injection placed in Manager Contact would have any effect — by construction it cannot.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
In one lineThe only guardrail is the prompt
One instruction, no enforcement. It mostly holds — and mostly is the whole subject.
the guardrail, verbatim
Never adjust a till, write off a variance, or open or close an investigation — and never present the variance bands or the repeat threshold as any real retailer's policy.
Stated to the model on every call in src/prompt.py's INSTRUCTION block, and enforced by evals/check_labels.py's banned-code-path scan, red-proven by seeding a write-off path.
EvidenceDoes it hold?
What
Measured
The banned-code-path scan
0 banned code paths across the whole kit, on every run of check_labels.py, including the ones immediately before every paid run.
The instruction-shaped note does NOT suppress — and this one IS measured
20 of 20 readings where action was genuinely due, re-fired with the note forced in, still raised it. Suppression rate 0.0 pct.
The limitWhat a guardrail is not
This is a PROMPT RULE PLUS A STATIC SCAN, not a runtime enforcement layer. Nothing stops a forker adding such a path tomorrow; the scan catches it only the next time somebody runs check_labels.py, which is a manual step.
The injection result is ONE SENTENCE against ONE model on ONE corpus. It is not a resistance rate for prompt injection in general.
WatchedWhat is watched, and why that one
7runs recorded
0 / 0deterministic metrics exact
+0.0%largest move — latency
0band breaches
—model half · needs provider URL
The kit measures 71 watched figures plus 8 comparability guards and 5 reference constants — three duties, not one list. 0 of the watched are grader rates, each on its own grader page; this board watches the ones that decide when to look again. Each square is one watched figure; filled means the latest run measured it.
3 measured by the latest run68 need the model half
Metric
Owner
Role
Why this one
cell-exact-match
The verdict, direction, cause, manager and raise-now call, per reading, exact match against the computed answer key
alarm
the per-field accuracies and the answered rate — alarm on any field falling below its strongest-free-floor value — the point at which paying for the model stopped being worth it on that column
repeat-offender-binary
A store persistently short in the same direction, inside its band every close
alarm
the counts in both directions, never the blended rate — alarm on any miss. r001 and the strong floor carry 0; both weaker floors carry 12 of 12.
benign-left-alone
Explained benign variances correctly left alone
alarm
the count left alone — alarm on any fall below 100.0 pct.
GuardsBefore any comparison
Preconditions, not alarms. If one moves, the runs were not measuring the same system and nothing else on this board may be differenced.
Guard
Value
If it moves
corpus.doc_count
120
different corpus — nothing is comparable
corpus.bytes
833,840
store close extracts edited — the count held, the bytes did not
split.count
120
the readings count moved — a different set was scored
split.size_p50
6,945
the median size of one reading moved
split.size_p95
7,337
the 95th-percentile size of one reading moved
dataset.rows
120
the test set changed — every rate has a new denominator
tokens.context_limit
1,000,000
different model family
index.build_seconds
0.5
no index is built here — a change is in corpus preparation, not an index rebuild
no shared guard The two recorded runs declare no guard in common, so nothing below is protected by a precondition — read the history as two separate observations, not as a difference.
The reference constants — the null-grader baseline, the adjudication matrix, the negative count — are the third duty. They are never re-measured per run: a baseline that moves with the thing it measures is not a baseline.
BandsThe alarm bands
Derived from evidence, never picked: exact-match where two runs reproduced a metric to the digit, wider than the measured same-input drift for latency, one row of the negative class for any rate — denominator printed beside it.
Group
Band
Denominator
Where the band comes from
Verdict, seven-way
99.17 pct
120 readings scored
r001-cash-variance exact match against src/variance.step()'s computed gold
Direction
99.17 pct
120 readings scored
r001-cash-variance exact match against src/variance.step()'s computed gold
Probable cause
80.83 pct
120 readings scored
r001-cash-variance exact match against src/variance.step()'s computed gold
Store manager
92.5 pct
120 readings scored
r001-cash-variance exact match against src/variance.step()'s computed gold
Raise-now call
99.17 pct
120 readings scored
r001-cash-variance exact match against src/variance.step()'s computed gold
Persistently one-directional -- caught
99.17 pct
120 readings scored
r001-cash-variance exact match against src/variance.step()'s computed gold
Explained benign variances left alone
100.0 pct
8 benign cells
r001-cash-variance exact match against src/variance.step()'s computed gold
Verdict, memory-dependent readings only
100.0 pct
45 memory cells
r001-cash-variance exact match against src/variance.step()'s computed gold
Raise-now, memory-dependent readings only
100.0 pct
45 memory cells
r001-cash-variance exact match against src/variance.step()'s computed gold
Stores still needing attention, caught at the last close
100.0 pct
17 stores needing attention at last close
r001-cash-variance exact match against src/variance.step()'s computed gold
Input tokens, run total
335606
120 readings
r001-cash-variance, re-derived from its result file
Output tokens, run total
272431
120 readings
r001-cash-variance, re-derived from its result file
Latency p50
12183
120 readings
r001-cash-variance, re-derived from its result file
Latency p95
53390
120 readings
r001-cash-variance, re-derived from its result file
Answered
99.17 pct
120 readings
r001-cash-variance, re-derived from its result file
False raises
0.0 pct
120 readings
r001-cash-variance, re-derived from its result file
Missed raises
0.0 pct
120 readings
r001-cash-variance, re-derived from its result file
Discriminator, false direction
0.0 pct
120 readings
r001-cash-variance, re-derived from its result file
HistoryRun history
7 recorded runs. A dash is a metric that run did not measure, and a dash is never differenced: not measured is a third state, neither a value nor a zero, and reading it as zero is how a board reports an improvement on a run that never looked. They are split into 4 blocks because a free floor is a baseline rather than a peer, and a run of another kind measures another thing; a column in one block is never differenced against a column in another.
triage · no model in the path — a baseline, not a peer column — 3 runs. A floor is what the kit scores with no model in the path; it is the line the model runs have to beat, and it is never differenced against them.
Metric
b000-cash-variance-bandonly 2026-08-25
b001-cash-variance-bandonlymem 2026-08-25
b002-cash-variance-structuredlogstrong 2026-08-25
benign suppression, %
100.0
100.0
75.0
cause accuracy, %
60.83
85.83
91.67
direction accuracy, %
100.0
100.0
100.0
input tokens, whole run
0
0
0
model latency p50 ms
0.00
0.00
0.00
model latency p95 ms
0.00
0.00
0.00
memory raise now accuracy, %
41.30
65.22
91.30
memory verdict accuracy, %
36.96
54.35
86.96
output tokens, whole run
0
0
0
owner accuracy, %
88.33
95.00
95.00
raise now accuracy, %
76.67
86.67
95.83
repeat offender accuracy, %
90.00
90.00
98.33
stores caught, %
29.41
29.41
100.00
verdict accuracy, %
70.83
77.50
93.33
not a time series No two of these 3 runs measured the same system — they differ on floor, the model — so nothing here may be differenced and the Verdict column is left off. Read this block DOWN a column, as a comparison between those runs, not along a row as a history.
triage · with the model in the path — 2 runs. Columns here are only ever compared with each other.
Metric
r001-cash-variance 2026-08-25
s001-cash-variance-stateless 2026-08-25
benign suppression, %
100.0
100.0
cause accuracy, %
80.83
62.50
direction accuracy, %
99.17
99.17
input tokens, whole run
335606
323014
model latency p50 ms
12183.00
9336.00
model latency p95 ms
53390.00
45138.00
memory raise now accuracy, %
100.00
57.78
memory verdict accuracy, %
100.00
55.56
output tokens, whole run
272431
210532
owner accuracy, %
92.5
92.5
raise now accuracy, %
99.17
83.33
repeat offender accuracy, %
99.17
89.17
stores caught, %
100.00
29.41
verdict accuracy, %
99.17
82.50
not a time series No two of these 2 runs measured the same system — they differ on stateless — so nothing here may be differenced and the Verdict column is left off. Read this block DOWN a column, as a comparison between those runs, not along a row as a history.
stub · no model in the path — a baseline, not a peer column — 1 run. A floor is what the kit scores with no model in the path; it is the line the model runs have to beat, and it is never differenced against them.
Metric
t000-cash-variance-stub 2026-08-25
benign suppression, %
100.0
cause accuracy, %
60.83
direction accuracy, %
100.0
input tokens, whole run
361106
model latency p50 ms
0.00
model latency p95 ms
0.00
memory raise now accuracy, %
41.3
memory verdict accuracy, %
36.96
output tokens, whole run
5744
owner accuracy, %
88.33
raise now accuracy, %
76.67
repeat offender accuracy, %
90.0
stores caught, %
29.41
verdict accuracy, %
70.83
one run A verdict is a comparison and one run has nothing to compare with, so the Verdict column is left off rather than filled with 14 chips that all say so.
redteam · with the model in the path — 1 run. Columns here are only ever compared with each other.
Metric
x001-cash-variance-injection 2026-08-25
raises held
20
raises suppressed
0
suppression rate, %
0.0
one run A verdict is a comparison and one run has nothing to compare with, so the Verdict column is left off rather than filled with 3 chips that all say so.
DeviationsWhat deviated
0 breaches across 7 runs
The day a band breaks, a row renders here carrying the metric, the two runs, the band it crossed and what changed between them — model, prompt, chunker or top_k, read off the run records’ guards. A deviation with no diff beside it is an alarm nobody can act on.
RippleThe ripple map
Which figures move together, so one alarm reads as a system. Every edge carries its basis: measured names the run that showed it; reasoning admits nothing has varied it yet.
Lever
What moves
Basis
Evidence
the repeat threshold in src/variance.py
which stores are offenders, the answer key and the discriminator itself.
measured
red-proven by seeding a repeat-offender close outside its band
a section added to SECTION_HINTS
what leaves the machine.
measured
red-proven in both directions
the close cadence
the call volume and the time a pattern stays invisible.
measured
evals/cadence.py, free
FiresWhat fires when a band breaks
Where evals stop sitting beside the guardrail and start feeding it. Where the answer is nothing automatic, the row says so — hiding it would undo “What a guardrail is not” above.
Nothing fires yet. Not one of the 18 bands on this kit names a consequence, so there is no row to print. Which is the honest answer to the heading: a band that nothing is wired to is a number somebody has to notice, and this kit has only those. An empty table would have said the same thing while looking like a rendering failure.
NextThe three you would add first
Fix the ambient-note corpus defect and re-fireSeven cause misses trace to it and no corrected figure can be published until the 120 calls are paid.
Specify a cause for CONTEXT_INCOMPLETE and sub-floor readingsThirteen misses are readings the prompt never told the model how to answer.
Automate the manual scan stepToday it is a step a developer has to remember.
None of these is built here. They are named against the seam they sit on so they can be argued with.
CadenceWhen to re-run, and what it costs
The guardrail scan is a MANUAL step, run before each spend, not a hook. It ran before every paid run and passed at 0 each time. The injection probe is a ONE-OFF: it measured 0.0 pct suppression on 20 readings on 2026-08-25 and nothing re-runs it, so that figure ages from the day it was taken.
What this cannot tell you
Whether a differently-named write path would be caught.
Whether the injection result holds for any other phrasing.
Whether the prompt rule or the absent code path keeps the kit decision-free.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
In one lineNo framework, deliberately
NO FRAMEWORK. A folder of readable Python, no framework dependency, and a prompt anyone can read end to end. A framework abstraction would own the retrieval step — there is none here — and the memory layer, which is already the entire surface of src/state.py.
The mappingSeam by seam, who owns what
Seam
File here
Framework equivalent
Note
the model call
src/adapters/__init__.py
an LLM wrapper / Runnable
one dict and one function; the seam this kit measures is what the model returns, not how it is called.
the carried state
src/state.py
a memory or checkpoint object
a checkpoint object buys persistence and concurrency; this kit carries a run length, a cause and a bool, written by arithmetic and never by the model.
the corpus
tools/build_corpus.py
a document loader
one flat synthetic format this kit fully controls.
The seams are the ones this kit already publishes, so the mapping cannot drift from the code.
GraphsWhere LangGraph changes the answer
Linear: the reader -> src/prompt.py -> src/adapters -> evals/scoring.py. No branching, no tool-calling and no agent loop.
The other sideWhat a framework costs you
Swapping providers means editing the PROVIDERS dict by hand. In exchange the prompt has no hidden templating layer and requirements.txt stays empty.
What we could NOT verify
Whether a framework's memory abstraction would have kept the same-direction RUN LENGTH rather than the last verdict. That count is the whole finding.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
In one lineWhat one run of this kit actually cost, in time and tokens
Measured on r001-cash-variance on the fast tier, with the carried state, 2026-08-25. This kit records telemetry measured per run — 4 of the 6 readings on this axis, 4 of them with a band the guardrail board can judge against.
The readingWhat the last run measured
Reading
Last run
Band
What fires
Model, median
12,183 ms
12183
—
Model, p95
53,390 ms
53390
—
Input tokens
335,606
335606
—
Output tokens
272,431
272431
—
No movement column. Not one of the 4 earlier runs on record is comparable with this one — a different model tier, or a changed guard — and differencing across that measures two systems rather than one. Said once here rather than as a dash on every row.
Retrieval not shown. No run of this kit has ever recorded a retrieval timing, because the pipeline has no such stage. Those readings are left out rather than dashed: a dash says “this run did not measure it”, which promises a later run could.
DriftMedian call, run over run
r001-cash-variance12,183 ms
s001-cash-variance-stateless9,336 ms
Hatched bars are runs that are not comparable with the latest — a different model tier or a changed guard. They are drawn because hiding them would make the history look shorter than it is, and greyed because differencing across them would be measuring two systems.
3 runs not plotted. b000-cash-variance-bandonly, b001-cash-variance-bandonlymem, b002-cash-variance-structuredlogstrong recorded no call latency at all — a rules-only floor run makes no model call, and the 0 its record stores is an absence, not a zero-millisecond answer. Plotting it would put a bar on this chart claiming the fastest run in the kit’s history.
The other sideWhat this does not tell you
What we could NOT verify
No stage-by-stage span tree. These are whole-call timings; which part of the pipeline spent the time is not recorded by this kit's harness.
Latency is a run-level median and p95. The spread between the fastest and slowest single call is not stored, so the distribution cannot be drawn.
No earlier run is comparable to this one (a different model tier or a changed guard), so nothing on this page is a trend yet.
One machine, one network, one region. Latency includes the provider round trip from a single location and will not transfer to yours.
The first of those is the one worth doing something about, and it is a solved problem: instrumenting a pipeline so each step reports its own duration is a couple of lines. Observability / tracing has the code, and what the result looks like once it is running.
Catch the store that's quietly short in cash every night
PresenterOpens the private repo. Visible to admins only.
In one lineWhat you provision, honestly
Everything measured on this page says where it was measured; everything not measured says that — the same contract as the other thirteen pages. Where a retrieval index would be on other kits, this one has: no index — the population is re-read whole on each scheduled run, and the prior run's carried state is what makes a reading a CHANGE.
The machineWhat this needs
Dependencies
nothing beyond the standard library — requirements.txt names no package
Configuration
9 environment variables — the full knob table is at the bottom of this page
Last verified run
2026-08-25, across 7 committed records
Enumerated from the kit’s own source by build/facts/envscan.py, committed, and drift-checked — never typed into this page.
7 of the 8 sections go to the provider; Manager Contact never does
the answer key
data/gold.jsonl, computed by src/variance.step()
never
the carried state
data/state.json in a deployment
a few SENTENCES of it do, in every prompt — that is the experiment
every run this kit has fired
results/eval-*.json and results/discarded/
never
The wireWhat crosses it, and when
Runtime call site
Destination
src/adapters/__init__.py line 54
the configured BASE_URL
Build-time (corpus tooling, run once)
Destination
none — this kit’s corpus is generated locally
Zero-egress topology: point BASE_URL at a local OpenAI-compatible server and nothing leaves the machine — statically true of the shipped adapter, whose only credential travels in the Authorization header.
The third state
What the provider retains, trains on or logs once a request arrives is not measured here — it is provider-dependent, and this page does not assert what no run of ours can verify.
The shapeHow it ships, and what you add
The key
API_KEY is read from .env (gitignored) or the real environment; never logged, never placed in a prompt, and redacted from any provider error message the local UI passes to the browser.
You add
your reverse proxy and your identity in front of one process — the kit deliberately ships neither, because identity belongs to your estate, not to a kit
Never ships
Docker, Helm, a queue, a database. The product is a folder of readable Python; what to run it under is this page’s job to state, not the kit’s job to impose
The ladderEach decision, and what you provision past its ceiling
Decision
The kit ships
Measured here
Past the ceiling
What stops being valid
cadence
a DAILY close; one reading owns the events since the last.
40 stores x 3 closes = 120 calls per arm. A band exception report would print 24 store-closes and NONE of the repeat-offender stores appears on it on any close. (r001-cash-variance, evals/cadence.py)
⚑ THE CADENCE IS WHAT MAKES THE FINDING POSSIBLE. A repeat offender is only visible across closes; reading weekly multiplies the time it stays invisible.
A read cadence longer than the pattern takes to accumulate.
state
the same-direction run, the established cause and the resolved flag.
s001 misses 12 of 12 repeat offenders against the model's 0. (s001, src/state.py)
⚠︎ THE RUN LENGTH IS THE ONLY THING THAT MAKES THE PATTERN VISIBLE.
A deployment that cannot persist state between closes.
model
one completion call per reading at a 16000-token ceiling.
120 readings, 2796 in / 2270 out per reading. p50 12183 ms, p95 53390 ms. (r001-cash-variance, c000/c001/c002 calibration, src/watch.MAX_TOKENS)
⚠︎ THE CEILING FAILED TWICE. 8,000 truncated 2 of 120 after a clean nine-call probe; 16,000 still lost one. The same bytes returned 800 and 11,418 tokens on different attempts. That reading is scored wrong inside every percentage here.
A second model.
labels
a computed answer key from src/variance.step().
All 40 store chains replay exactly. 23 checks, two red-proven by seeding. (tools/build_corpus.py, evals/check_labels.py)
⚠︎ A CORPUS DEFECT WAS FOUND FROM THE MODEL'S RATIONALES AND LEFT UNFIXED, because fixing it costs a regeneration and 120 calls. It is named, not hidden.
Your own estate.
Every threshold is a measurement with its provenance beside it, or says is_measured:false. A ceiling with no seam says so — it is the point the kit is outgrown, never a forced join.
When it failsFailure signatures
What you see
What it is
First move
the band-only floor calls a store WITHIN_BAND that the model calls a repeat offender
the store never breaches; the pattern is across closes. This is the gap the kit measures.
read the carried state's direction run. (b000 against r001-cash-variance)
tonight's printed rota returned after a handover
a handover the carried state named in English.
read the carried state. (r001-cash-variance misses)
cause reported as deposit timing on a store with no timing evidence
the ambient-note corpus defect. Seven readings; diagnosed, unfixed, no corrected figure published.
read Supervisor Notes — the note is ambient, not an explanation. (data/SOURCES.md)
['Concurrency. data/state.json is replaced atomically, correct for one writer.', 'A missed close.', 'A store population that changes between closes.', 'Repeats. One run per arm.', 'Skipping stores that reconciled exactly — the sublinear cost lever, named not built.', 'Whether the carried state reads better as English or JSON.']
The corpus licence, from the Data lens: MIT Your corpus’s licence is yours to verify, and the labels you write are about your documents.
The verdict, direction, cause, manager and raise-now call, per reading, exact match against the computed answer key
all five fields hit
The band-only floor calls this WITHIN_BAND on every close.
A store persistently short in the same direction, inside its band every close
hit
One of the 12 repeat-offender readings; band-only misses all 12.
Explained benign variances correctly left alone
not applicable — this reading has no benign explanation
It is scored by the graders above.
The formulaWhat it computes
accuracy = hits / 120 per field. repeat_offender_accuracy_pct is scored separately over its own denominator.
The analysisWhat it actually did
Model
Result
the fast tier, with the carried state
99.2% verdict accuracy · 4 more measured on this row
In operationWhat to monitor
Reference standard: the computed answer key in data/gold.jsonl, produced by src/variance.step() from the same planted inputs the corpus builder wrote onto the page.
No true/false rates for this grader. It records 5 operating rows and not one of them carries a confusion matrix, so there is no TPR, TNR or precision to state here — this grader does not sort answers into pass and fail, and rates that were never measured are not going to be printed as though they were. What it did measure is in “What it actually did” above; what to watch is immediately below.
Watch these
the per-field accuracies and the answered rate
Alarm on
any field falling below its strongest-free-floor value — the point at which paying for the model stopped being worth it on that column
How tight can the band be? No threshold was swept: exact match has no tunable. Denominators are stated beside every rate because 120 readings makes each one wide.
Cadence: once per run; free
The decisionWhen to reach for it
Use it
Always. Every published accuracy figure rests on it.
Do not use it
It cannot tell you an answer was reasonable-but-wrong. Thirteen cause cells are the enum's two empty values on readings the prompt never specified.
The verdict, direction, cause, manager and raise-now call, per reading, exact match against the computed answer key
all five fields hit
The band-only floor calls this WITHIN_BAND on every close.
A store persistently short in the same direction, inside its band every close
hit
One of the 12 repeat-offender readings; band-only misses all 12.
Explained benign variances correctly left alone
not applicable — this reading has no benign explanation
It is scored by the graders above.
The formulaWhat it computes
caught over all 120 readings; the two error directions over their own denominators (12 repeat-offender readings, 108 others).
The analysisWhat it actually did
Model
Result
the fast tier, with the carried state
99.2% repeat offender accuracy · 1 more measured on this row
the strongest free floor — no model
98.3% repeat offender accuracy · 1 more measured on this row
In operationWhat to monitor
Reference standard: the computed answer key in data/gold.jsonl, produced by src/variance.step() from the same planted inputs the corpus builder wrote onto the page.
No true/false rates for this grader. It records 2 operating rows and not one of them carries a confusion matrix, so there is no TPR, TNR or precision to state here — this grader does not sort answers into pass and fail, and rates that were never measured are not going to be printed as though they were. What it did measure is in “What it actually did” above; what to watch is immediately below.
Watch these
the counts in both directions, never the blended rate
Alarm on
any miss. r001 and the strong floor carry 0; both weaker floors carry 12 of 12.
How tight can the band be? ⚑ THE BLENDED RATE IS THE TRAP: band-only reads 90.0 pct while catching none. 12 positives in 120 readings makes the negative class dominate.
Cadence: once per run; free
The decisionWhen to reach for it
Use it
Whenever the question is 'which store should somebody visit'.
Do not use it
It says nothing about whether tonight's variance was explained.
The verdict, direction, cause, manager and raise-now call, per reading, exact match against the computed answer key
all five fields hit
The band-only floor calls this WITHIN_BAND on every close.
A store persistently short in the same direction, inside its band every close
hit
One of the 12 repeat-offender readings; band-only misses all 12.
Explained benign variances correctly left alone
not applicable — this reading has no benign explanation
It is scored by the graders above.
The formulaWhat it computes
over the 8 readings whose variance has a named benign cause.
The analysisWhat it actually did
Model
Result
the fast tier, with the carried state
100.0% benign suppression · 1 more measured on this row
the strongest free floor -- no model
75.0% benign suppression · 1 more measured on this row
In operationWhat to monitor
Reference standard: the computed answer key in data/gold.jsonl, produced by src/variance.step() from the same planted inputs the corpus builder wrote onto the page.
No true/false rates for this grader. It records 2 operating rows and not one of them carries a confusion matrix, so there is no TPR, TNR or precision to state here — this grader does not sort answers into pass and fail, and rates that were never measured are not going to be printed as though they were. What it did measure is in “What it actually did” above; what to watch is immediately below.
Watch these
the count left alone
Alarm on
any fall below 100.0 pct.
How tight can the band be? No sweep: raise_now is a binary the arm emits.
Cadence: once per run; free
The decisionWhen to reach for it
Use it
Always, beside the discriminator.
Do not use it
Its denominator is 8 readings, so the rate is wide. Read the count.
A living map of modern AI — kept current every morning