The business caseThe problem this solves
A branch closes and a drawer is ninety dollars short. Subtraction is not the work — the balancing system has already produced the difference and the number is not in dispute. The work is saying WHICH PATTERN it is, because the pattern decides who fixes it, whether it will be there again tomorrow and whether it goes to the month's review. Today a supervisor reads eight panels per case at close, when everybody wants to go home, and the codes drift between supervisors and between branches. the supervisor's end-of-day read of every panel on a balancing case before a difference is coded — it does not replace the count, the balancing system, or the decision to adjust.
Audience
A branch operations manager deciding whether to put a model in front of the difference queue. This report's own answer is NO for the model alone, and yes for a build that calls the model on 23 of 60 cases. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual balancing cases
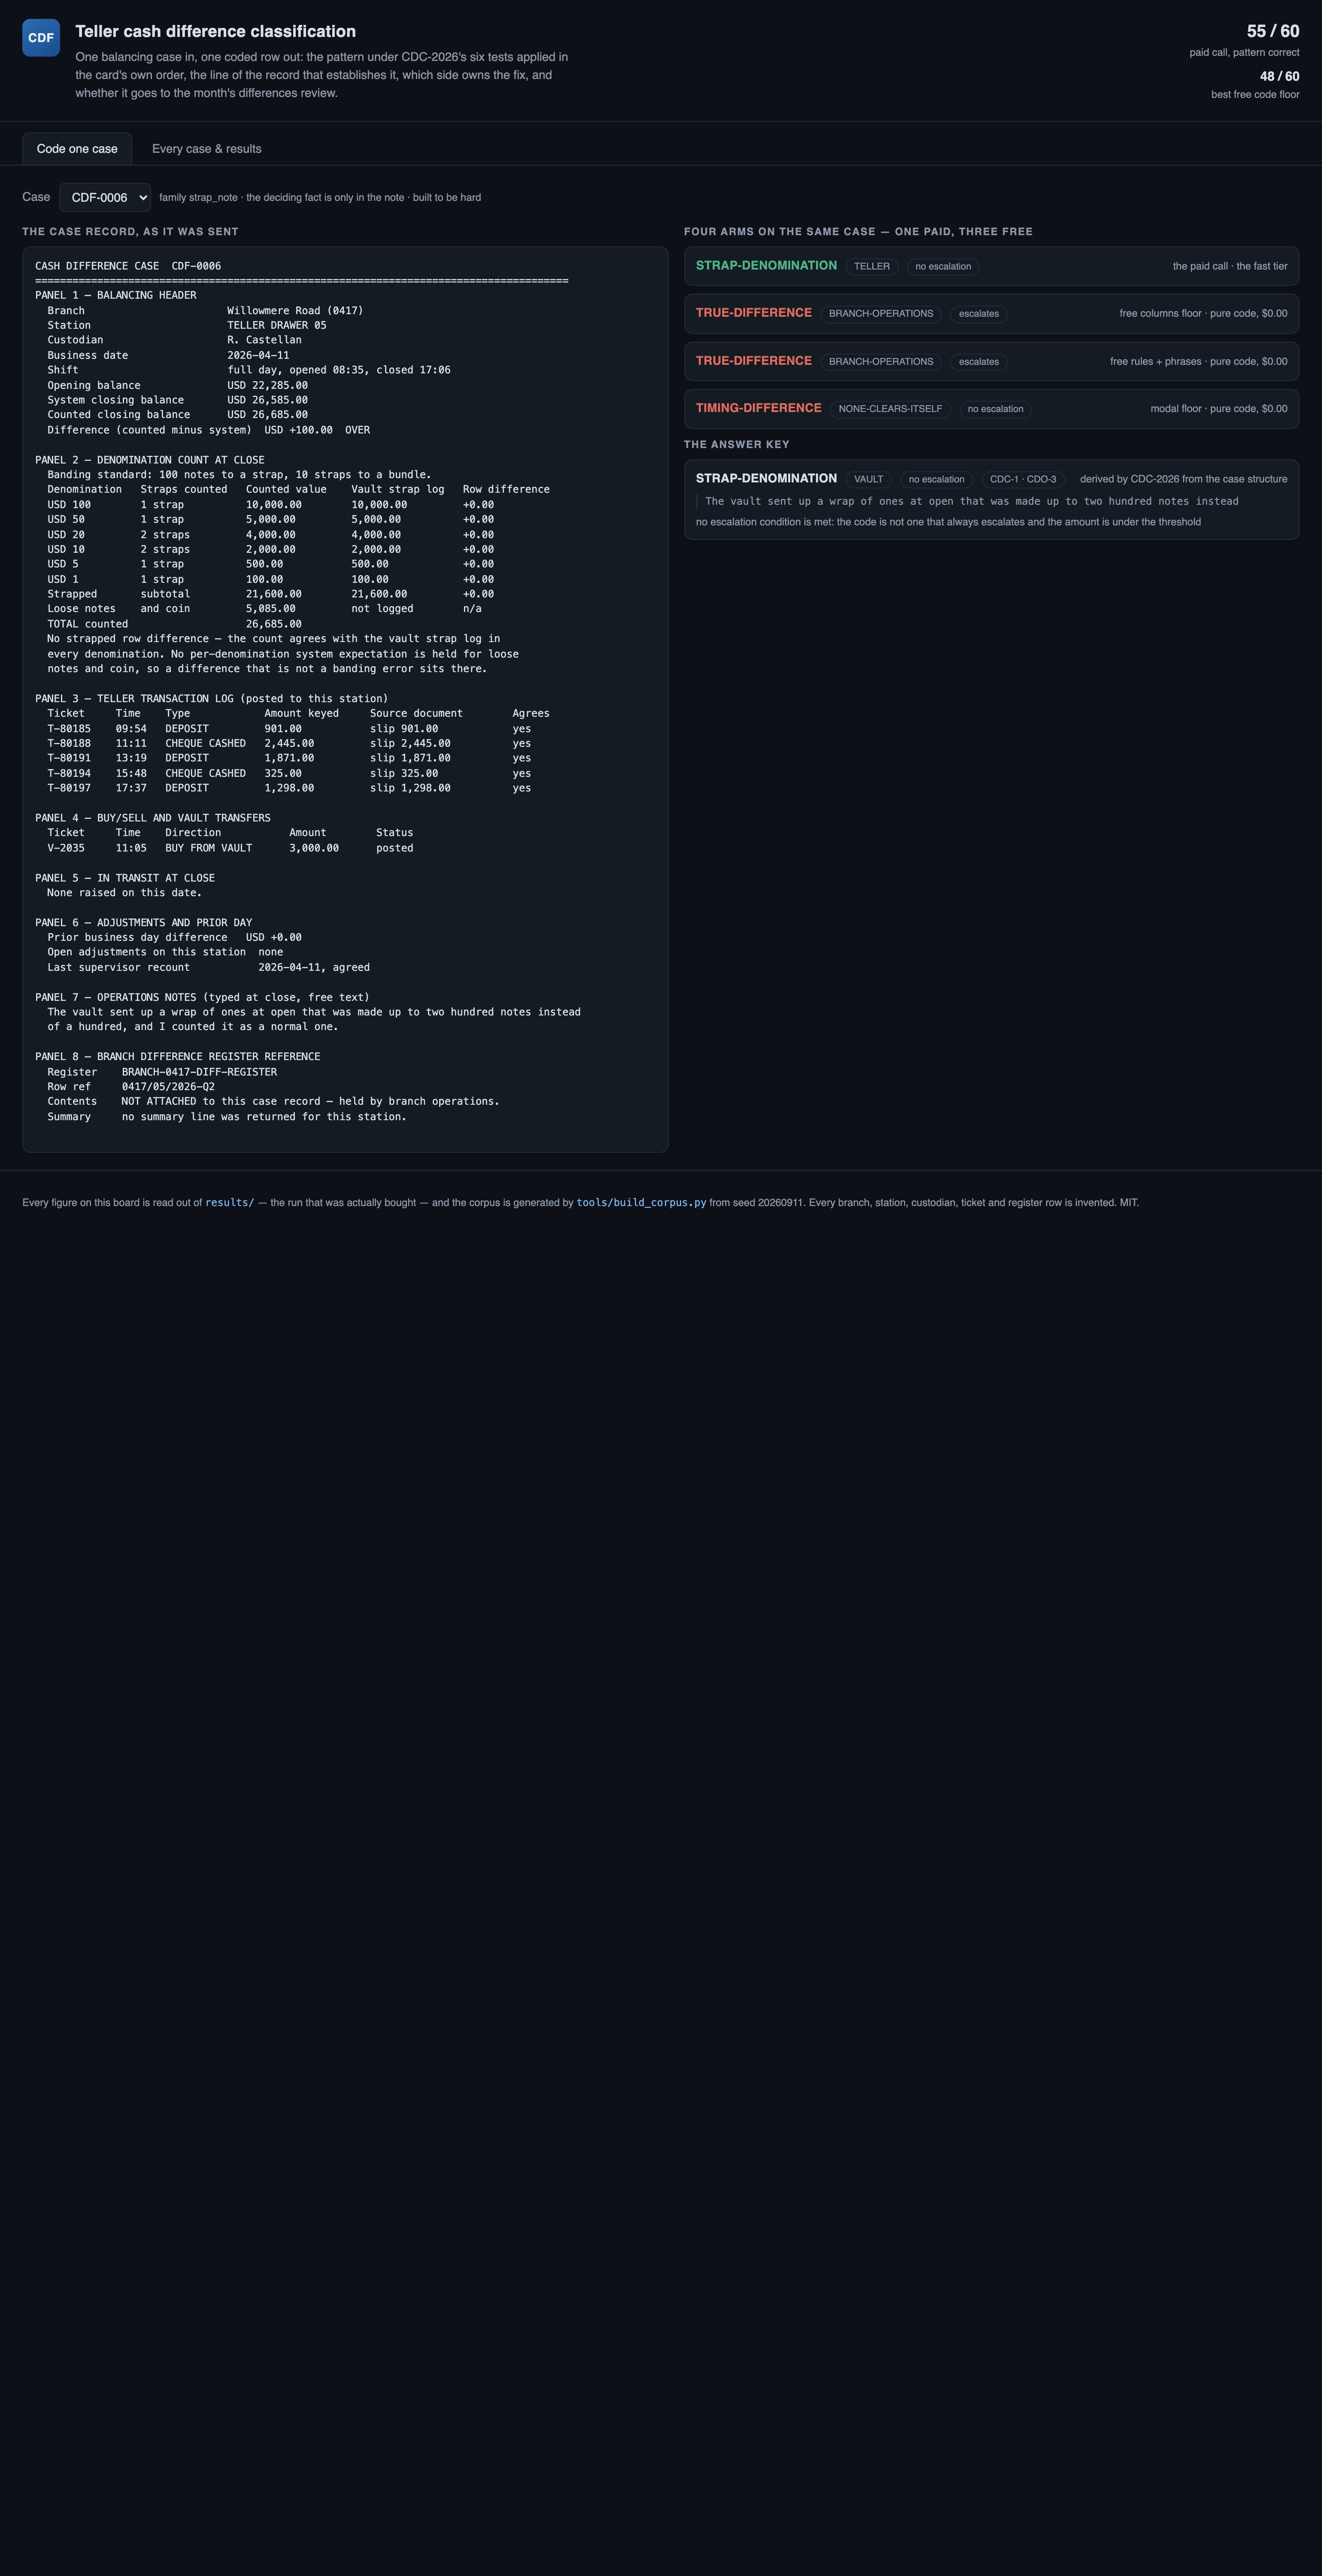
The corpus is 60 balancing cases, 0.17 MB (json 3 · jsonl 1 · md 1 · txt 60). A real branch difference queue carries employee names, customer deposits and account numbers, so it cannot be shipped and a redacted one cannot be labelled. This one is BUILT as structures and the answer key is CDC-2026 applied to those same structures, which is the only way to have 60 labelled cases whose key is derivable rather than opinion. It is deliberately unbalanced towards the mechanical patterns, because a real queue is: 48 of the 60 cases carry their cause in a printed column and 12 carry it only in a sentence a head teller typed.
The corpus
- The 60 balancing casesgenerated from a fixed seed, so no real record, person or institution appears in it.
- Where each came fromwritten for this kit rather than collected — the corpus is generated in the kit's own repository, so there is no third-party data in it.
Swap this folder for your own material and the kit is pointed at your balancing cases. That is the whole change — there is no database to migrate.
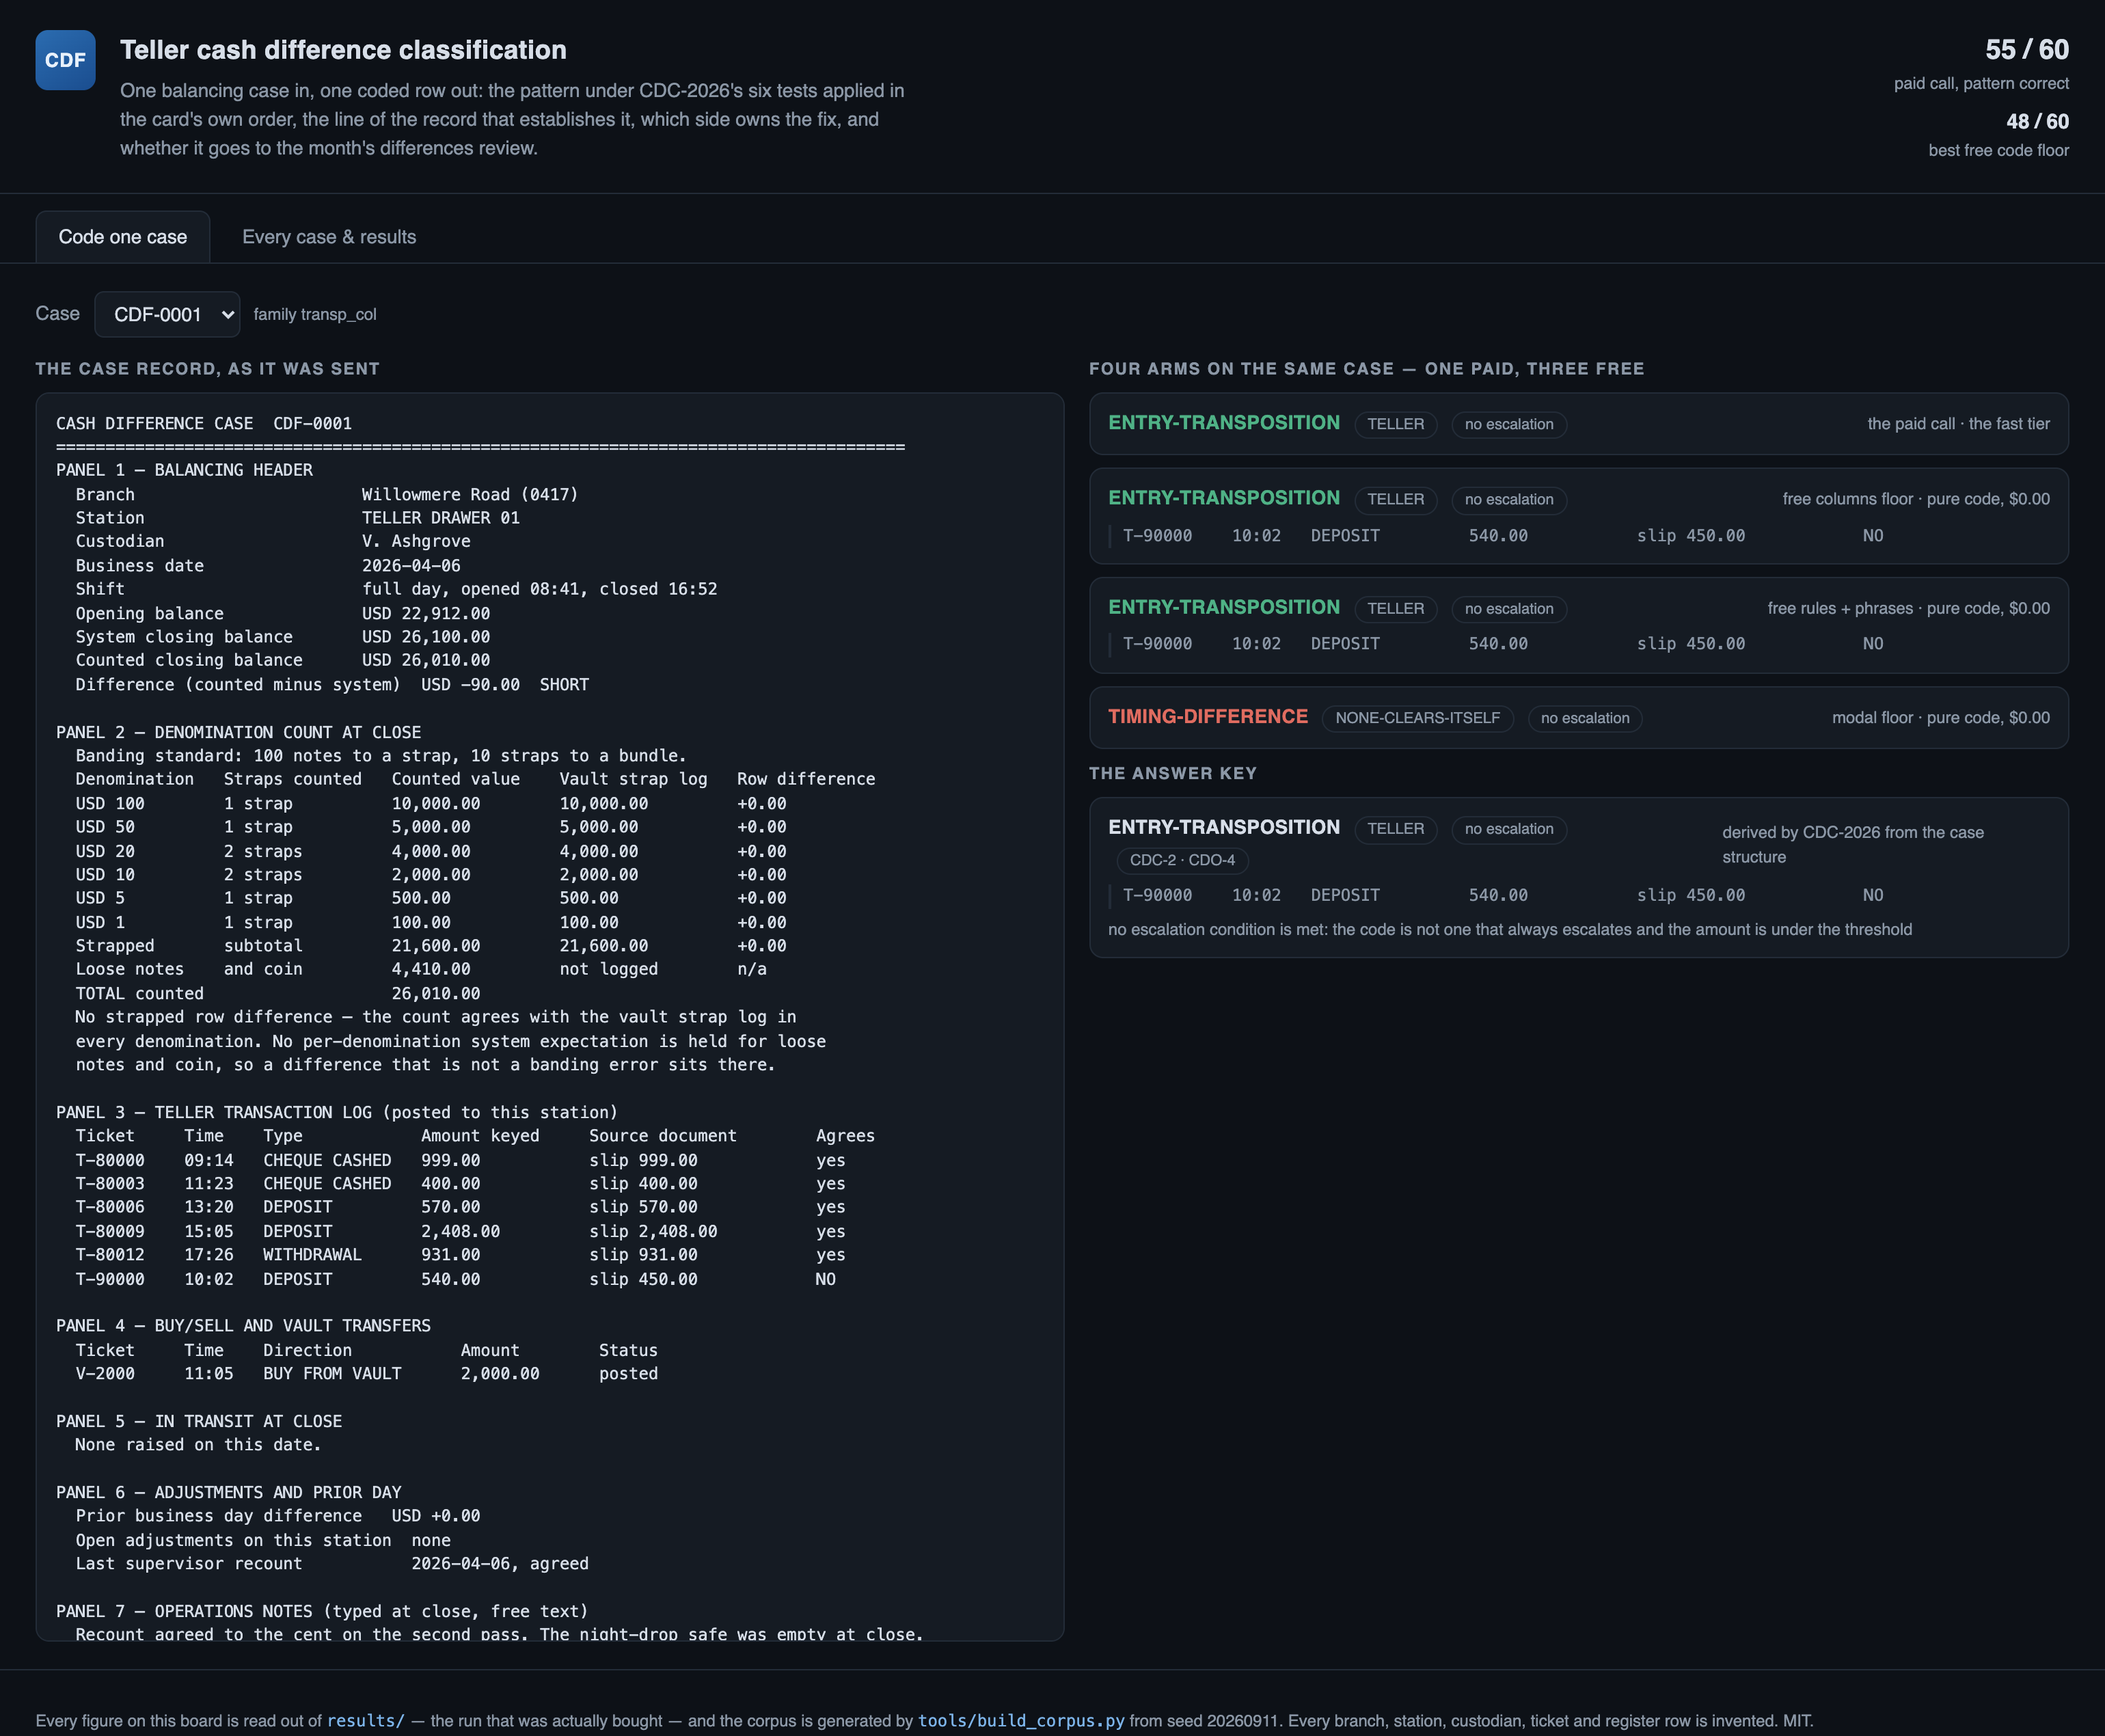
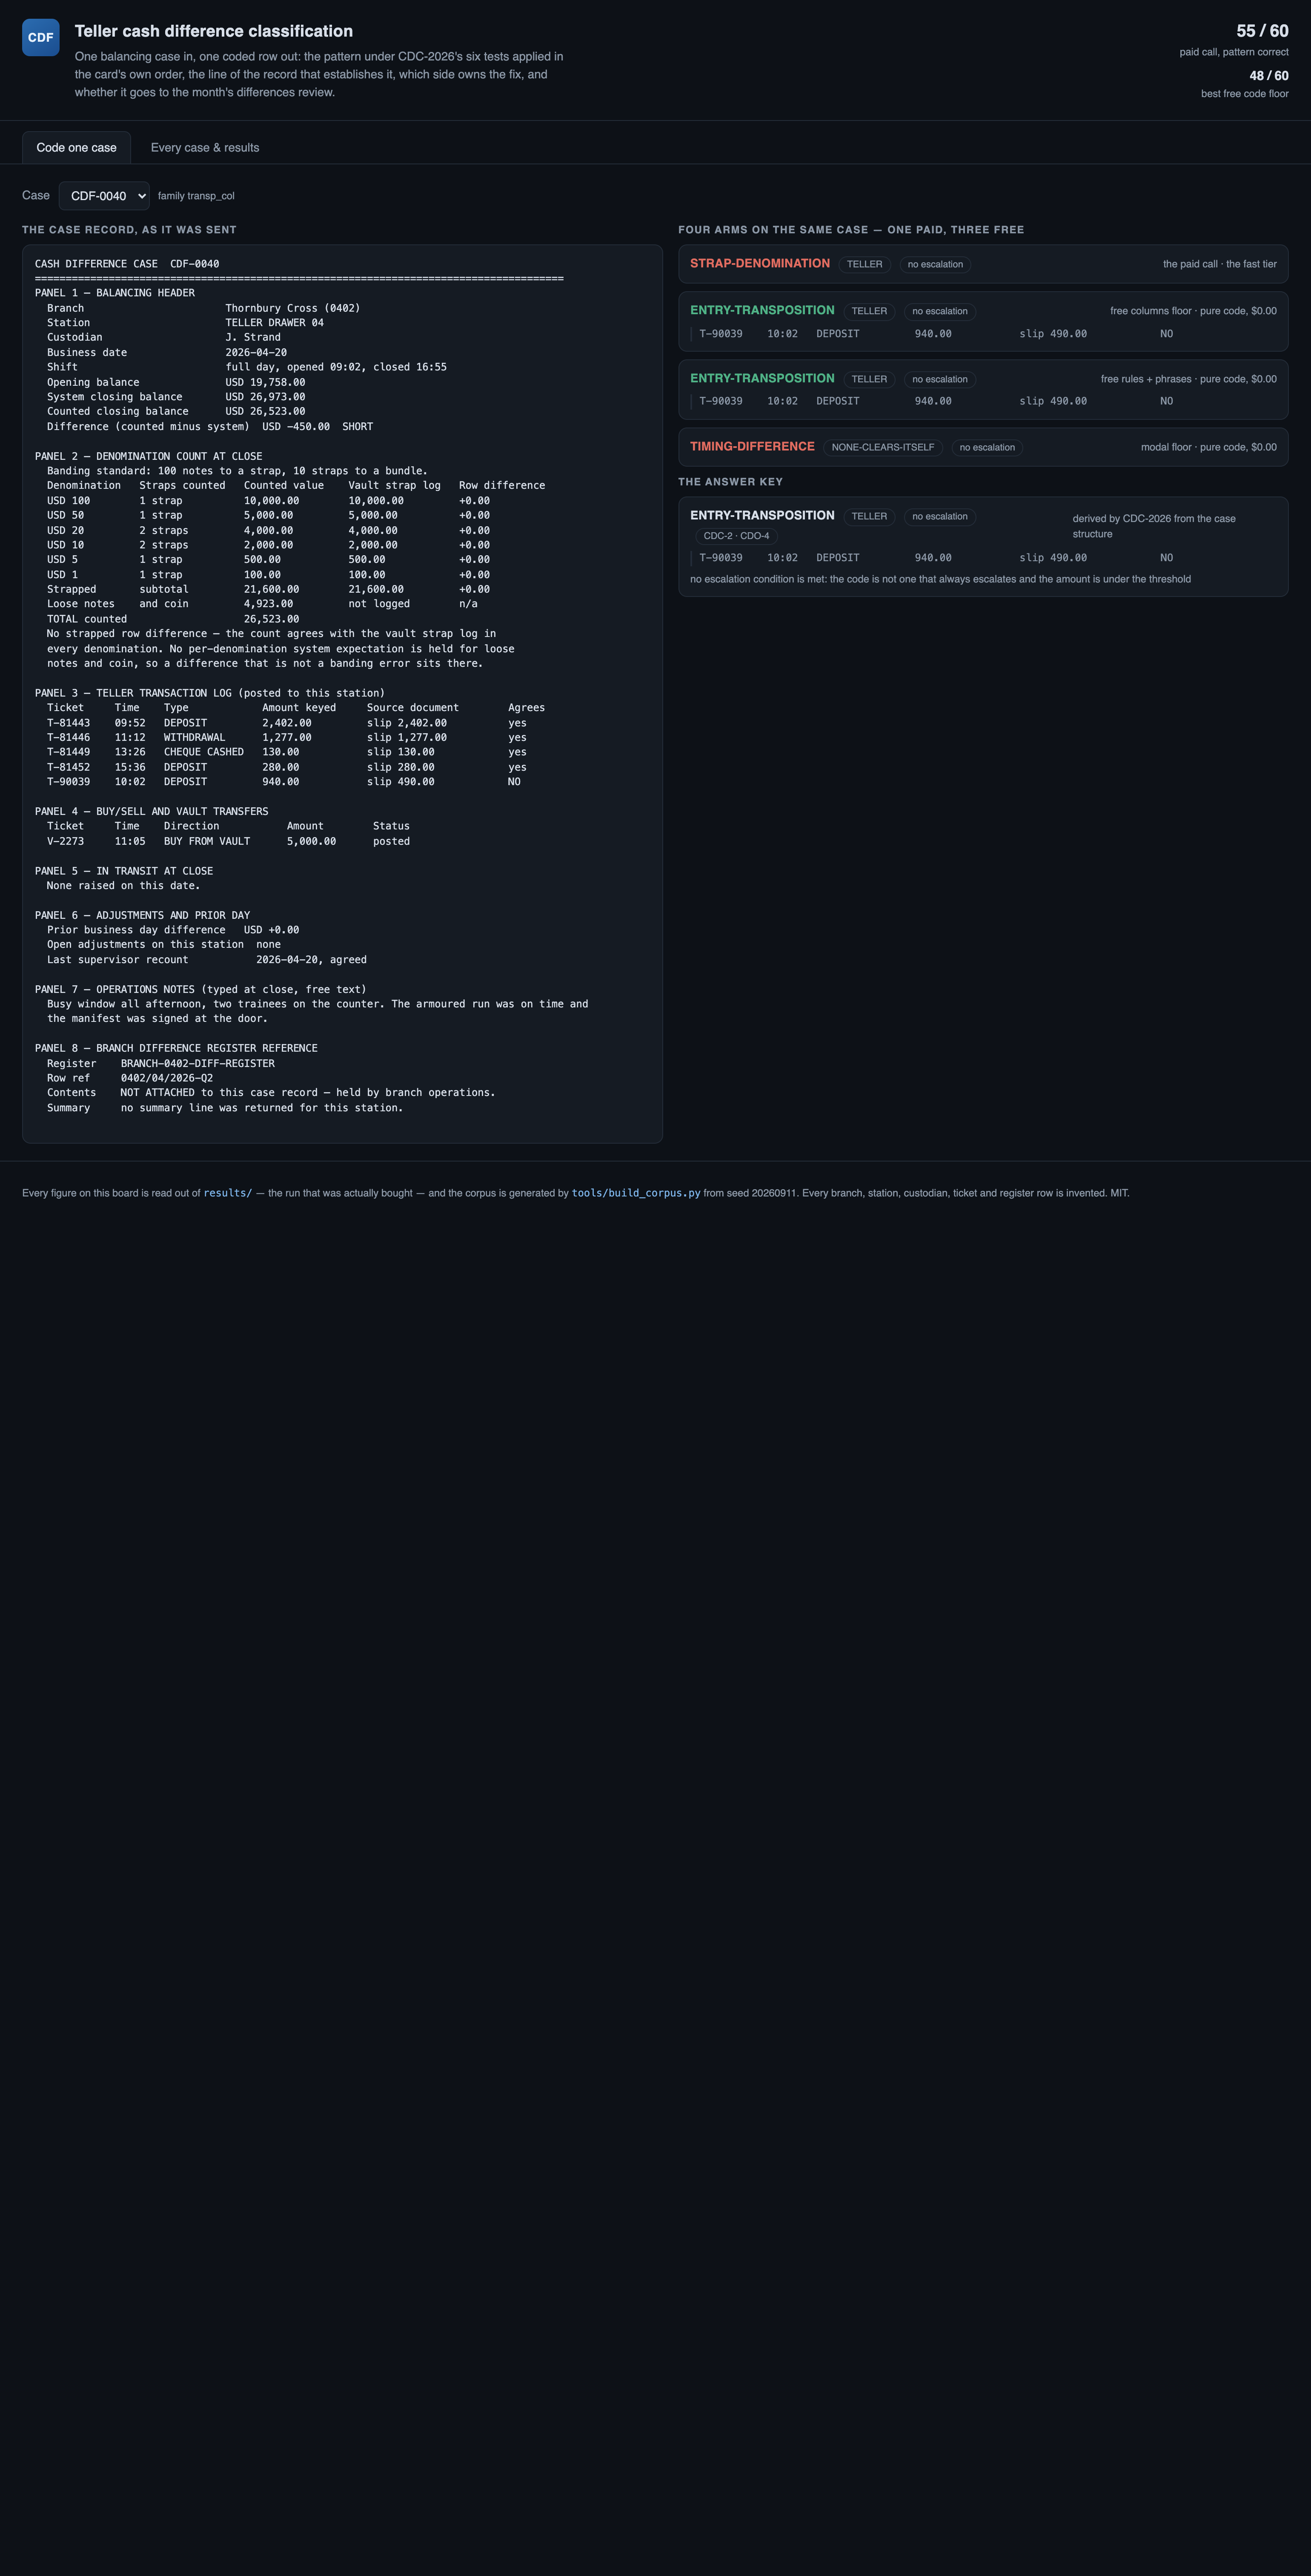
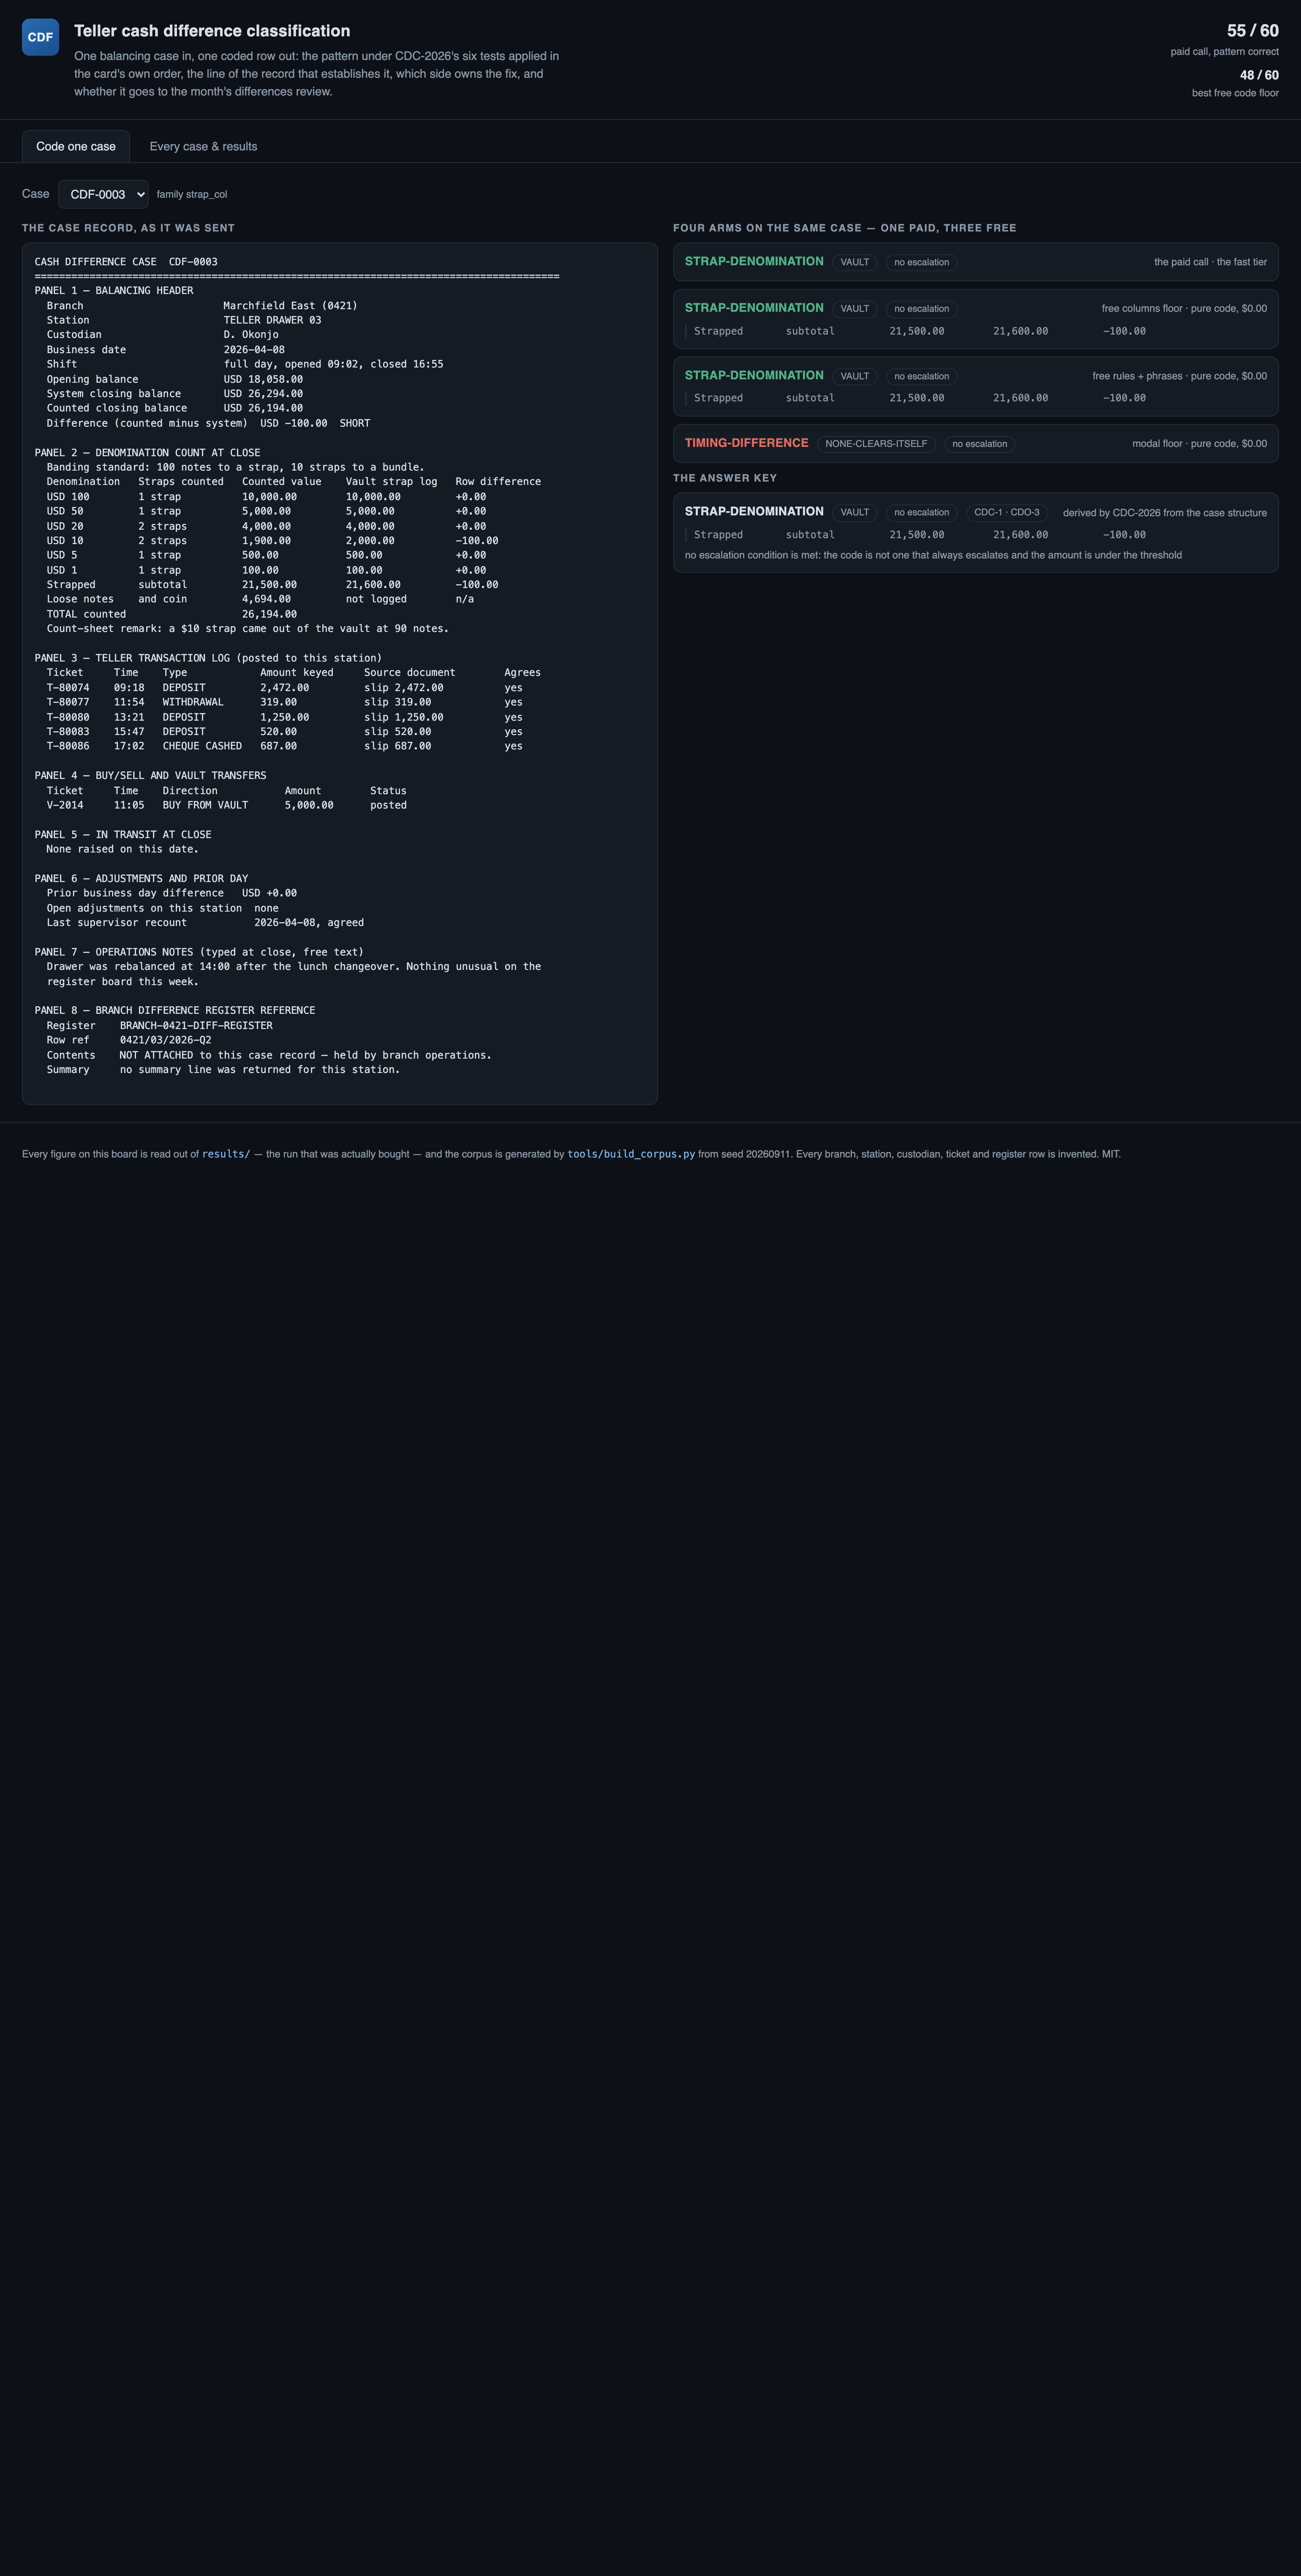
CASH DIFFERENCE CASE  CDF-0001
======================================================================================
PANEL 1 — BALANCING HEADER
  Branch                       Willowmere Road (0417)
  Station                      TELLER DRAWER 01
  Custodian                    V. Ashgrove
  Business date                2026-04-06
  Shift                        full day, opened 08:41, closed 16:52
  Opening balance              USD 22,912.00
  System closing balance       USD 26,100.00
  Counted closing balance      USD 26,010.00
  Difference (counted minus system)  USD -90.00  SHORT

PANEL 2 — DENOMINATION COUNT AT CLOSE
  Banding standard: 100 notes to a strap, 10 straps to a bundle.
  Denomination   Straps counted   Counted value    Vault strap log   Row difference
  USD 100        1 strap          10,000.00        10,000.00         +0.00
  USD 50         1 strap          5,000.00         5,000.00          +0.00
  USD 20         2 straps         4,000.00         4,000.00          +0.00
  USD 10         2 straps         2,000.00         2,000.00          +0.00
  USD 5          1 strap          500.00           500.00            +0.00
  USD 1          1 strap          100.00           100.00            +0.00
  Strapped       subtotal         21,600.00        21,600.00         +0.00
  Loose notes    and coin         4,410.00         not logged        n/a
  TOTAL counted                   26,010.00
  No strapped row difference — the count agrees with the vault strap log in
  every denomination. No per-denomination system expectation is held for loose
  notes and coin, so a difference that is not a banding error sits there.

PANEL 3 — TELLER TRANSACTION LOG (posted to this station)
Abridged — the file continues.
The outcomeWhat a good result looks like
One coded row per case that an operations clerk could work as written: a pattern under CDC-2026, the line that establishes it, the owning side, and the review flag.
And when it cannot
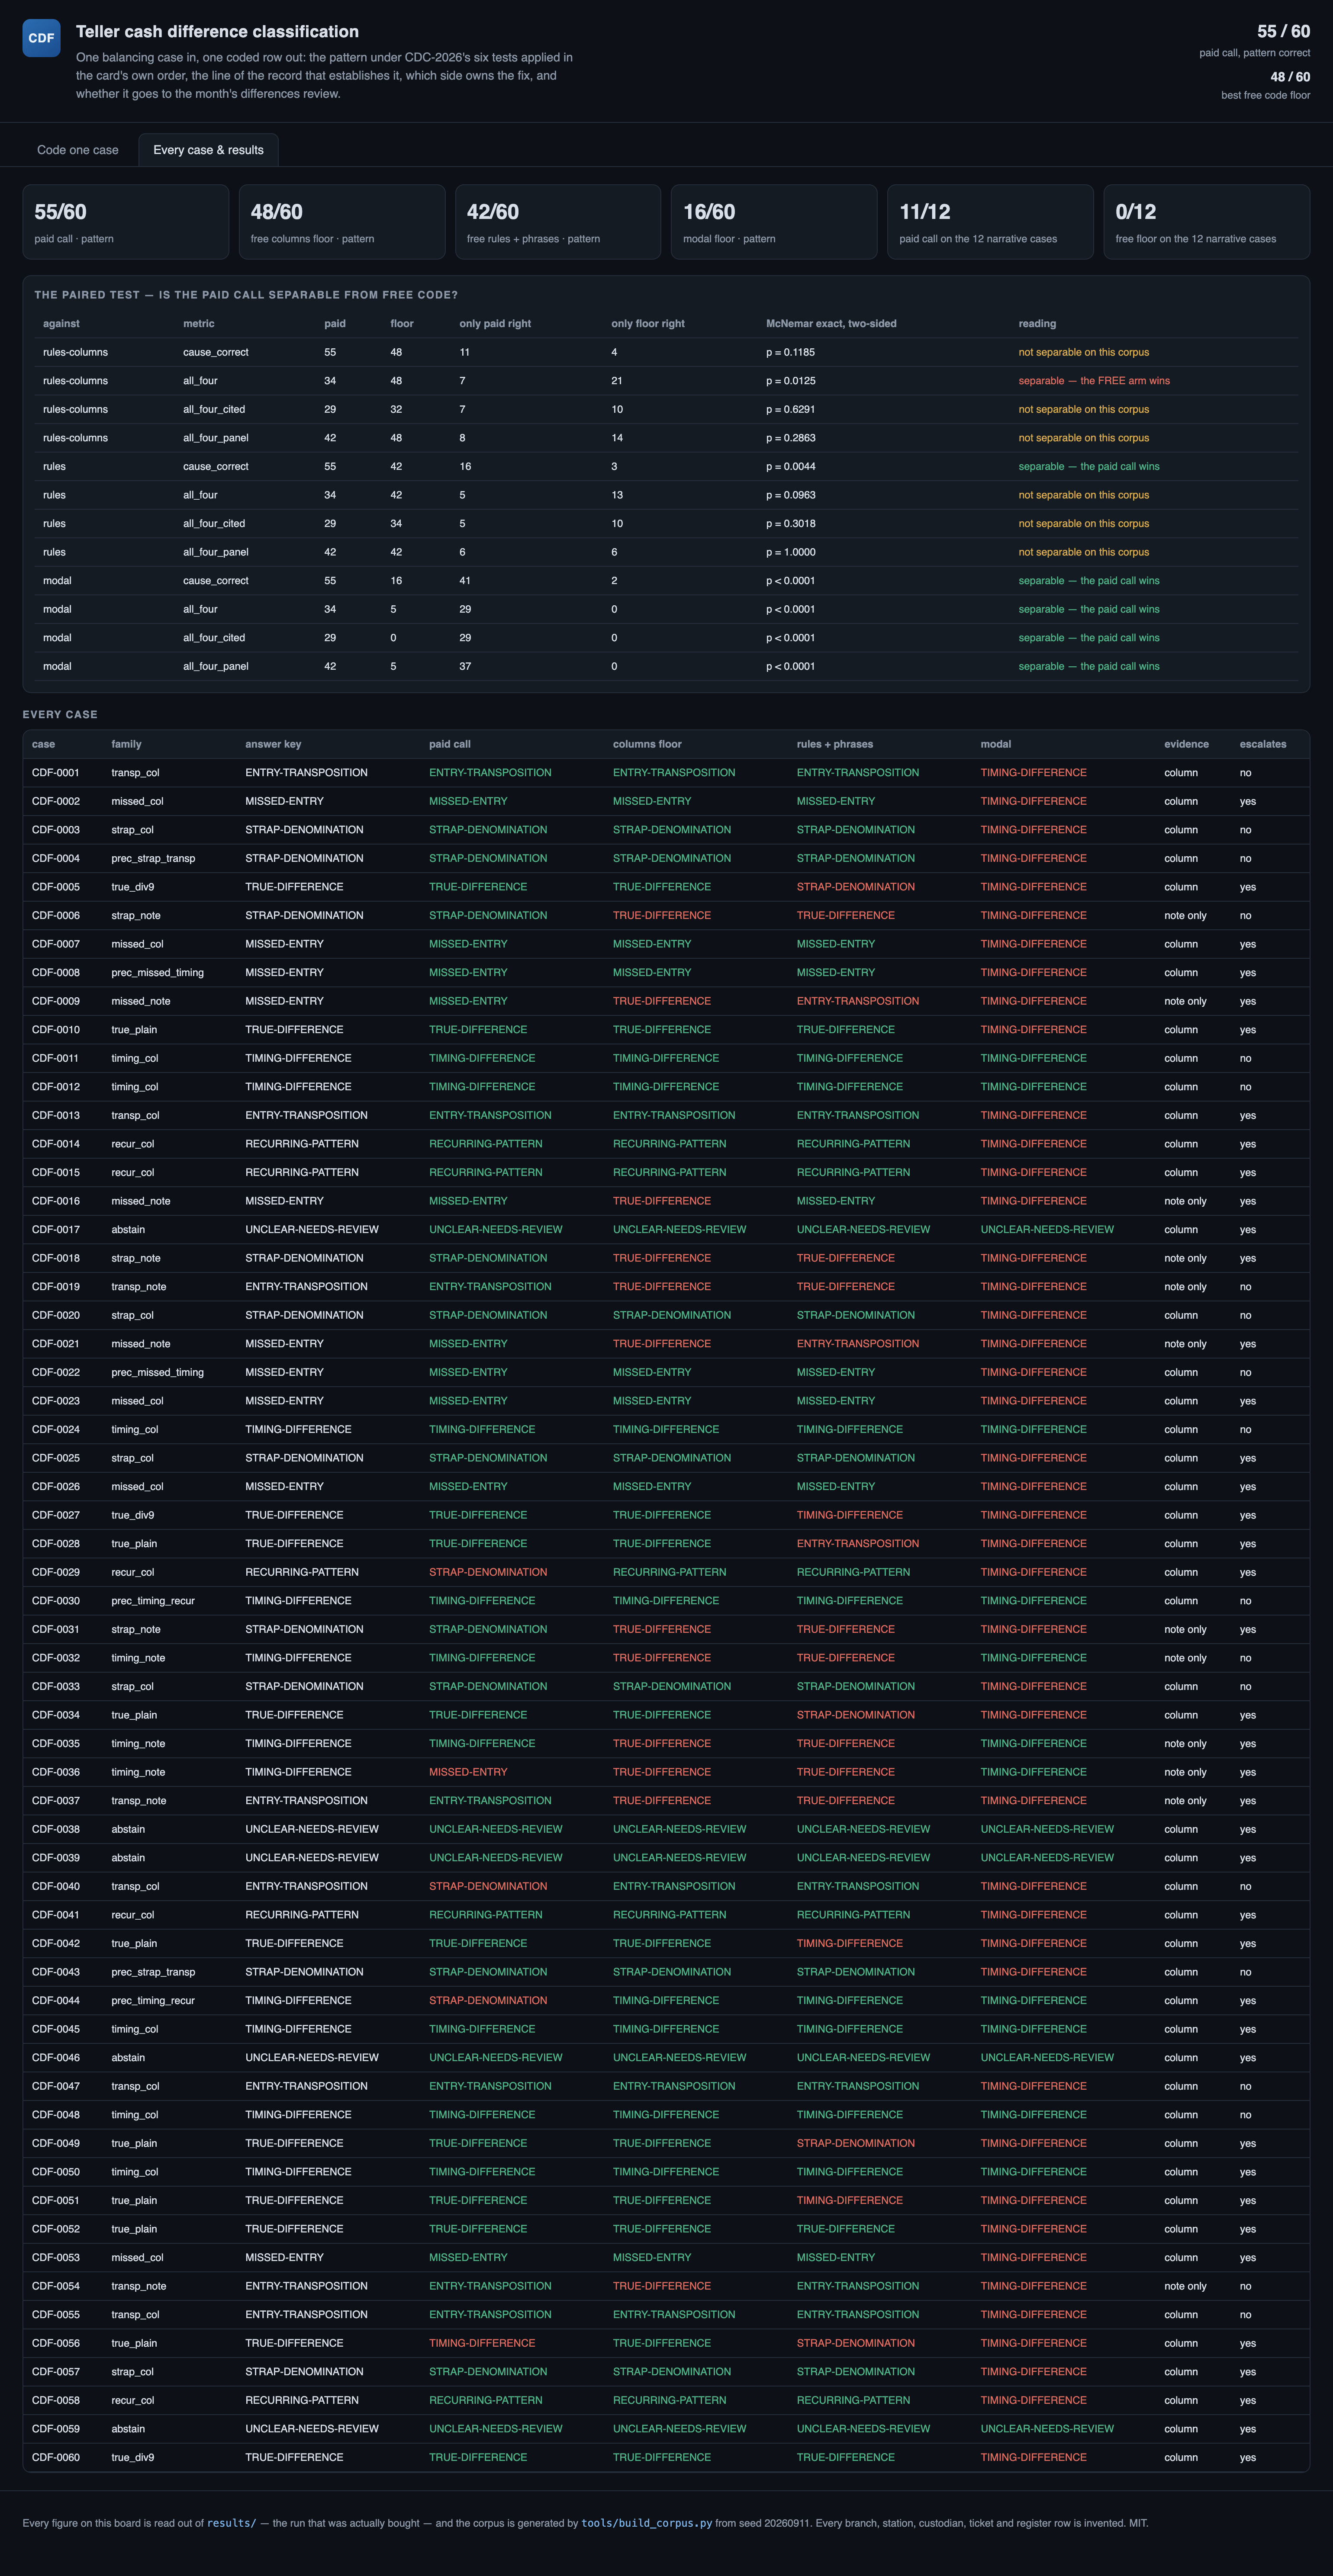
It abstains. A record that does not print the denomination count panel cannot be coded from the page, and the walk stops rather than guessing — 5 of 60 cases, and every arm gets all 5 of them right, because the rule is structural.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
- your panels are structured and your card's tests read columns — the free columns floor alone — evals/baseline.py, $0.00
it is 48 of 60 here and PERFECT on every case whose cause is printed. A paid call on those cases buys nothing and can only lose you ones you already had. - your custodians type what happened and your panels do not carry it — the paid call
it takes 11 of the 12 cases whose cause is only in a sentence, against 0 for every free arm. - both, which is every real branch — floor first, model on the residual — evals/hybrid.py
58 of 60 on 23 bought calls, p = 0.0063 against the floor. It is the only arm here that beats free code.
At a glanceHow the whole thing runs
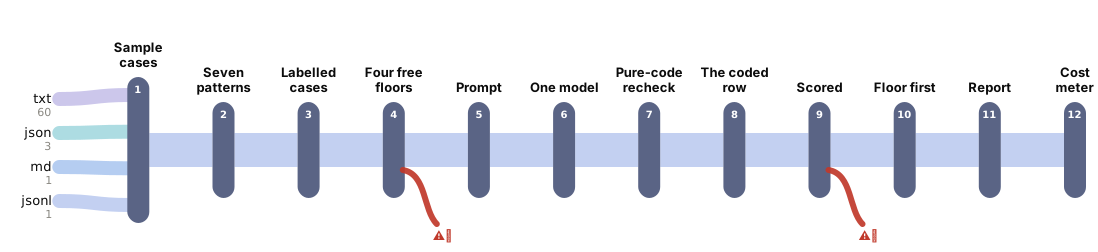
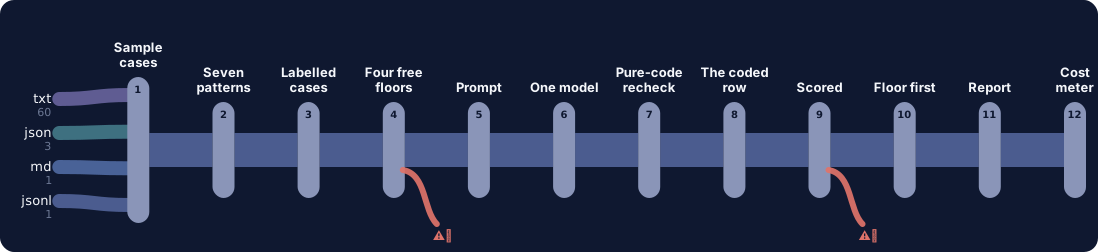
Run once, for real, on 2026-09-11. Every figure on these pages was captured from that run — nothing is written from intent.
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
| What do I have to bring? | Replace data/policy.md with your own card, data/policy.json's owner rules and threshold with yours, and src/taxonomy.py's codes with yours — the import-time assertions will refuse a code that is in one list and not another. The measured result does not travel. Corpus lens → |
| When is this the wrong choice? | Avoid: Paying per case for arithmetic. That is the case against the best-fitting scenario (“your panels are structured and your card's tests read columns”). 3 scenarios scored in all, each with its own. Eval lens → |
| Where does it stop working? | a case record whose panels are not the fixed-width tables src/panels.py expects — the parser is positional and a re-laid-out balancing print-out yields empty panels, which the recheck station then reads as a missing count panel and abstains on. 5 recorded failure modes, each from a run rather than a guess. Corpus lens → |
| What was never verified? | WHETHER ANY OF THIS HOLDS ON REAL BRANCH DATA. The corpus is generated and no real balancing print-out was used, so every number here is a statement about a synthetic distribution chosen by tools/build_corpus.py. 5 items this kit says it could not check. Eval lens → |
| Can I run this on a model I control? | The shipped adapter is one OpenAI-compatible endpoint, reached over urllib in src/adapters/; the Prompt lens states what swapping it costs. The published figures come from 1 model on the fast tier, off-peak. Prompt lens → |
| And if it fits — what do I stand up? | 5 artifacts with a stated home and a stated egress, and 3 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one. step 14 — Run it in your environment → |
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-09-11 — r001-cash-difference. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
- The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
- The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — A clean checkout with no key configured renders the whole board, replays the committed run, scores all four free floors offline and reproduces every paired test in this spec — measured on this machine, 0 calls and $0.00. What a clean checkout CANNOT do is re-run the paid arm: that needs a provider key, and the repository is private.