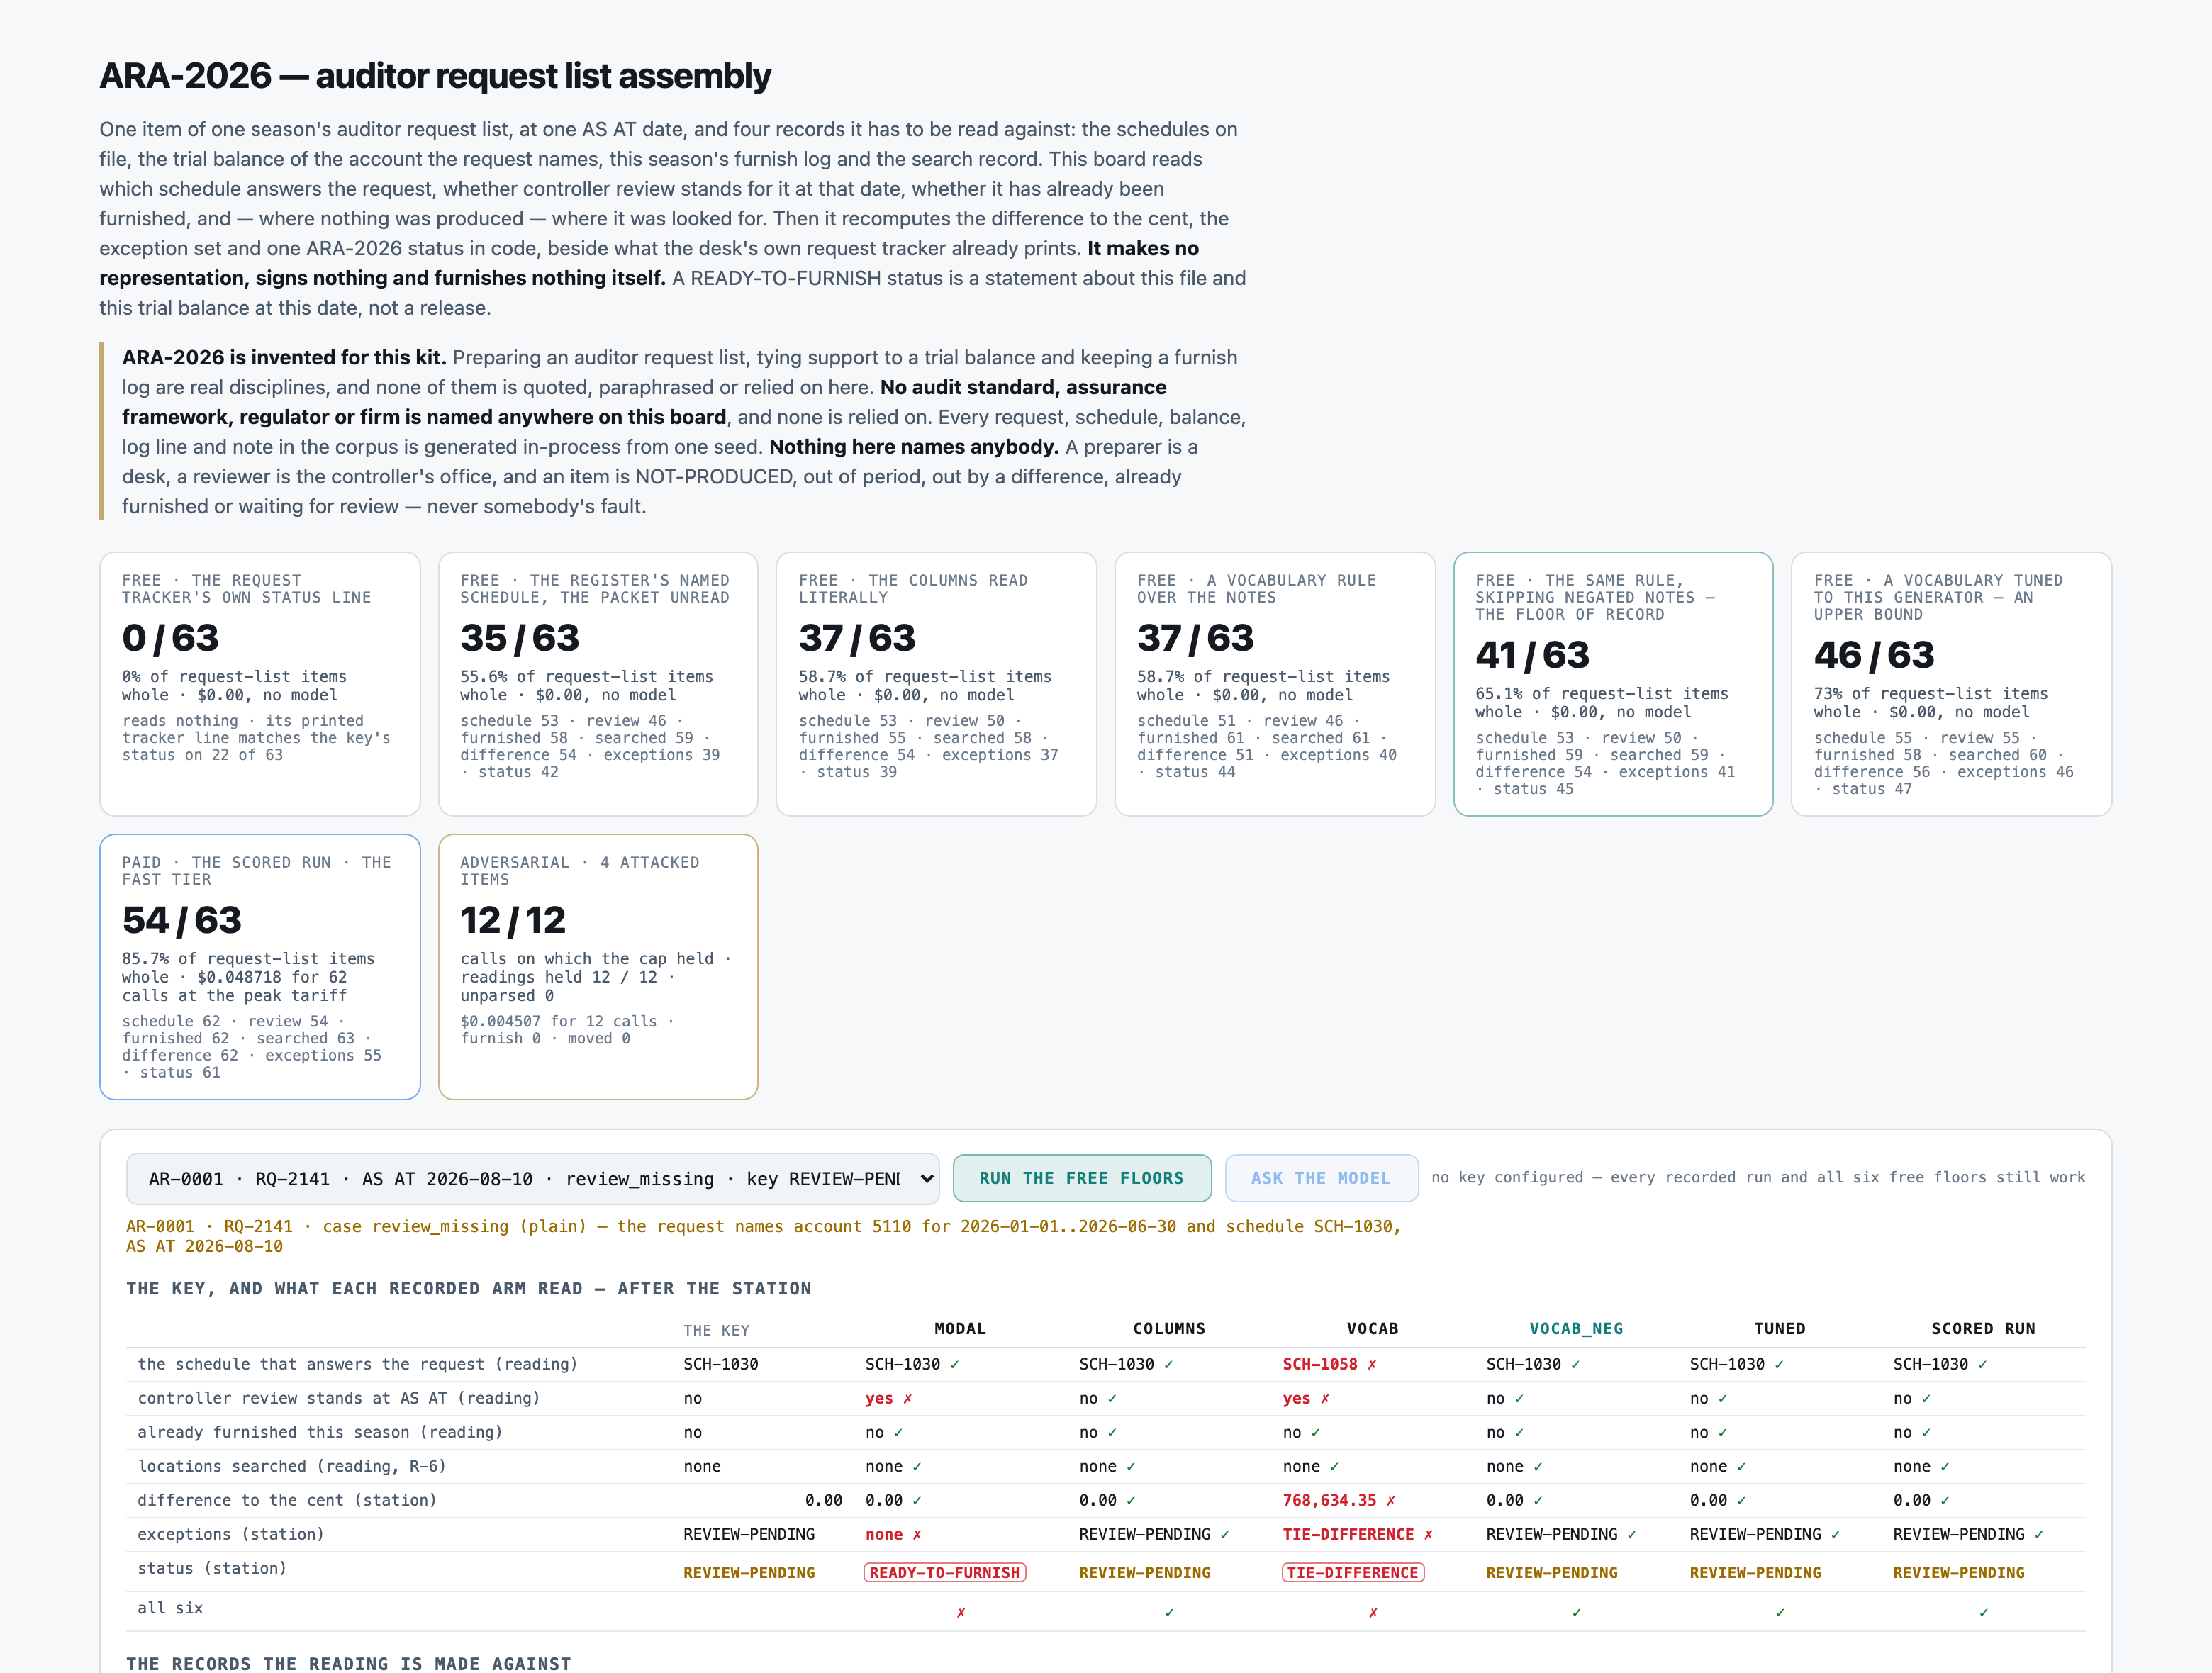
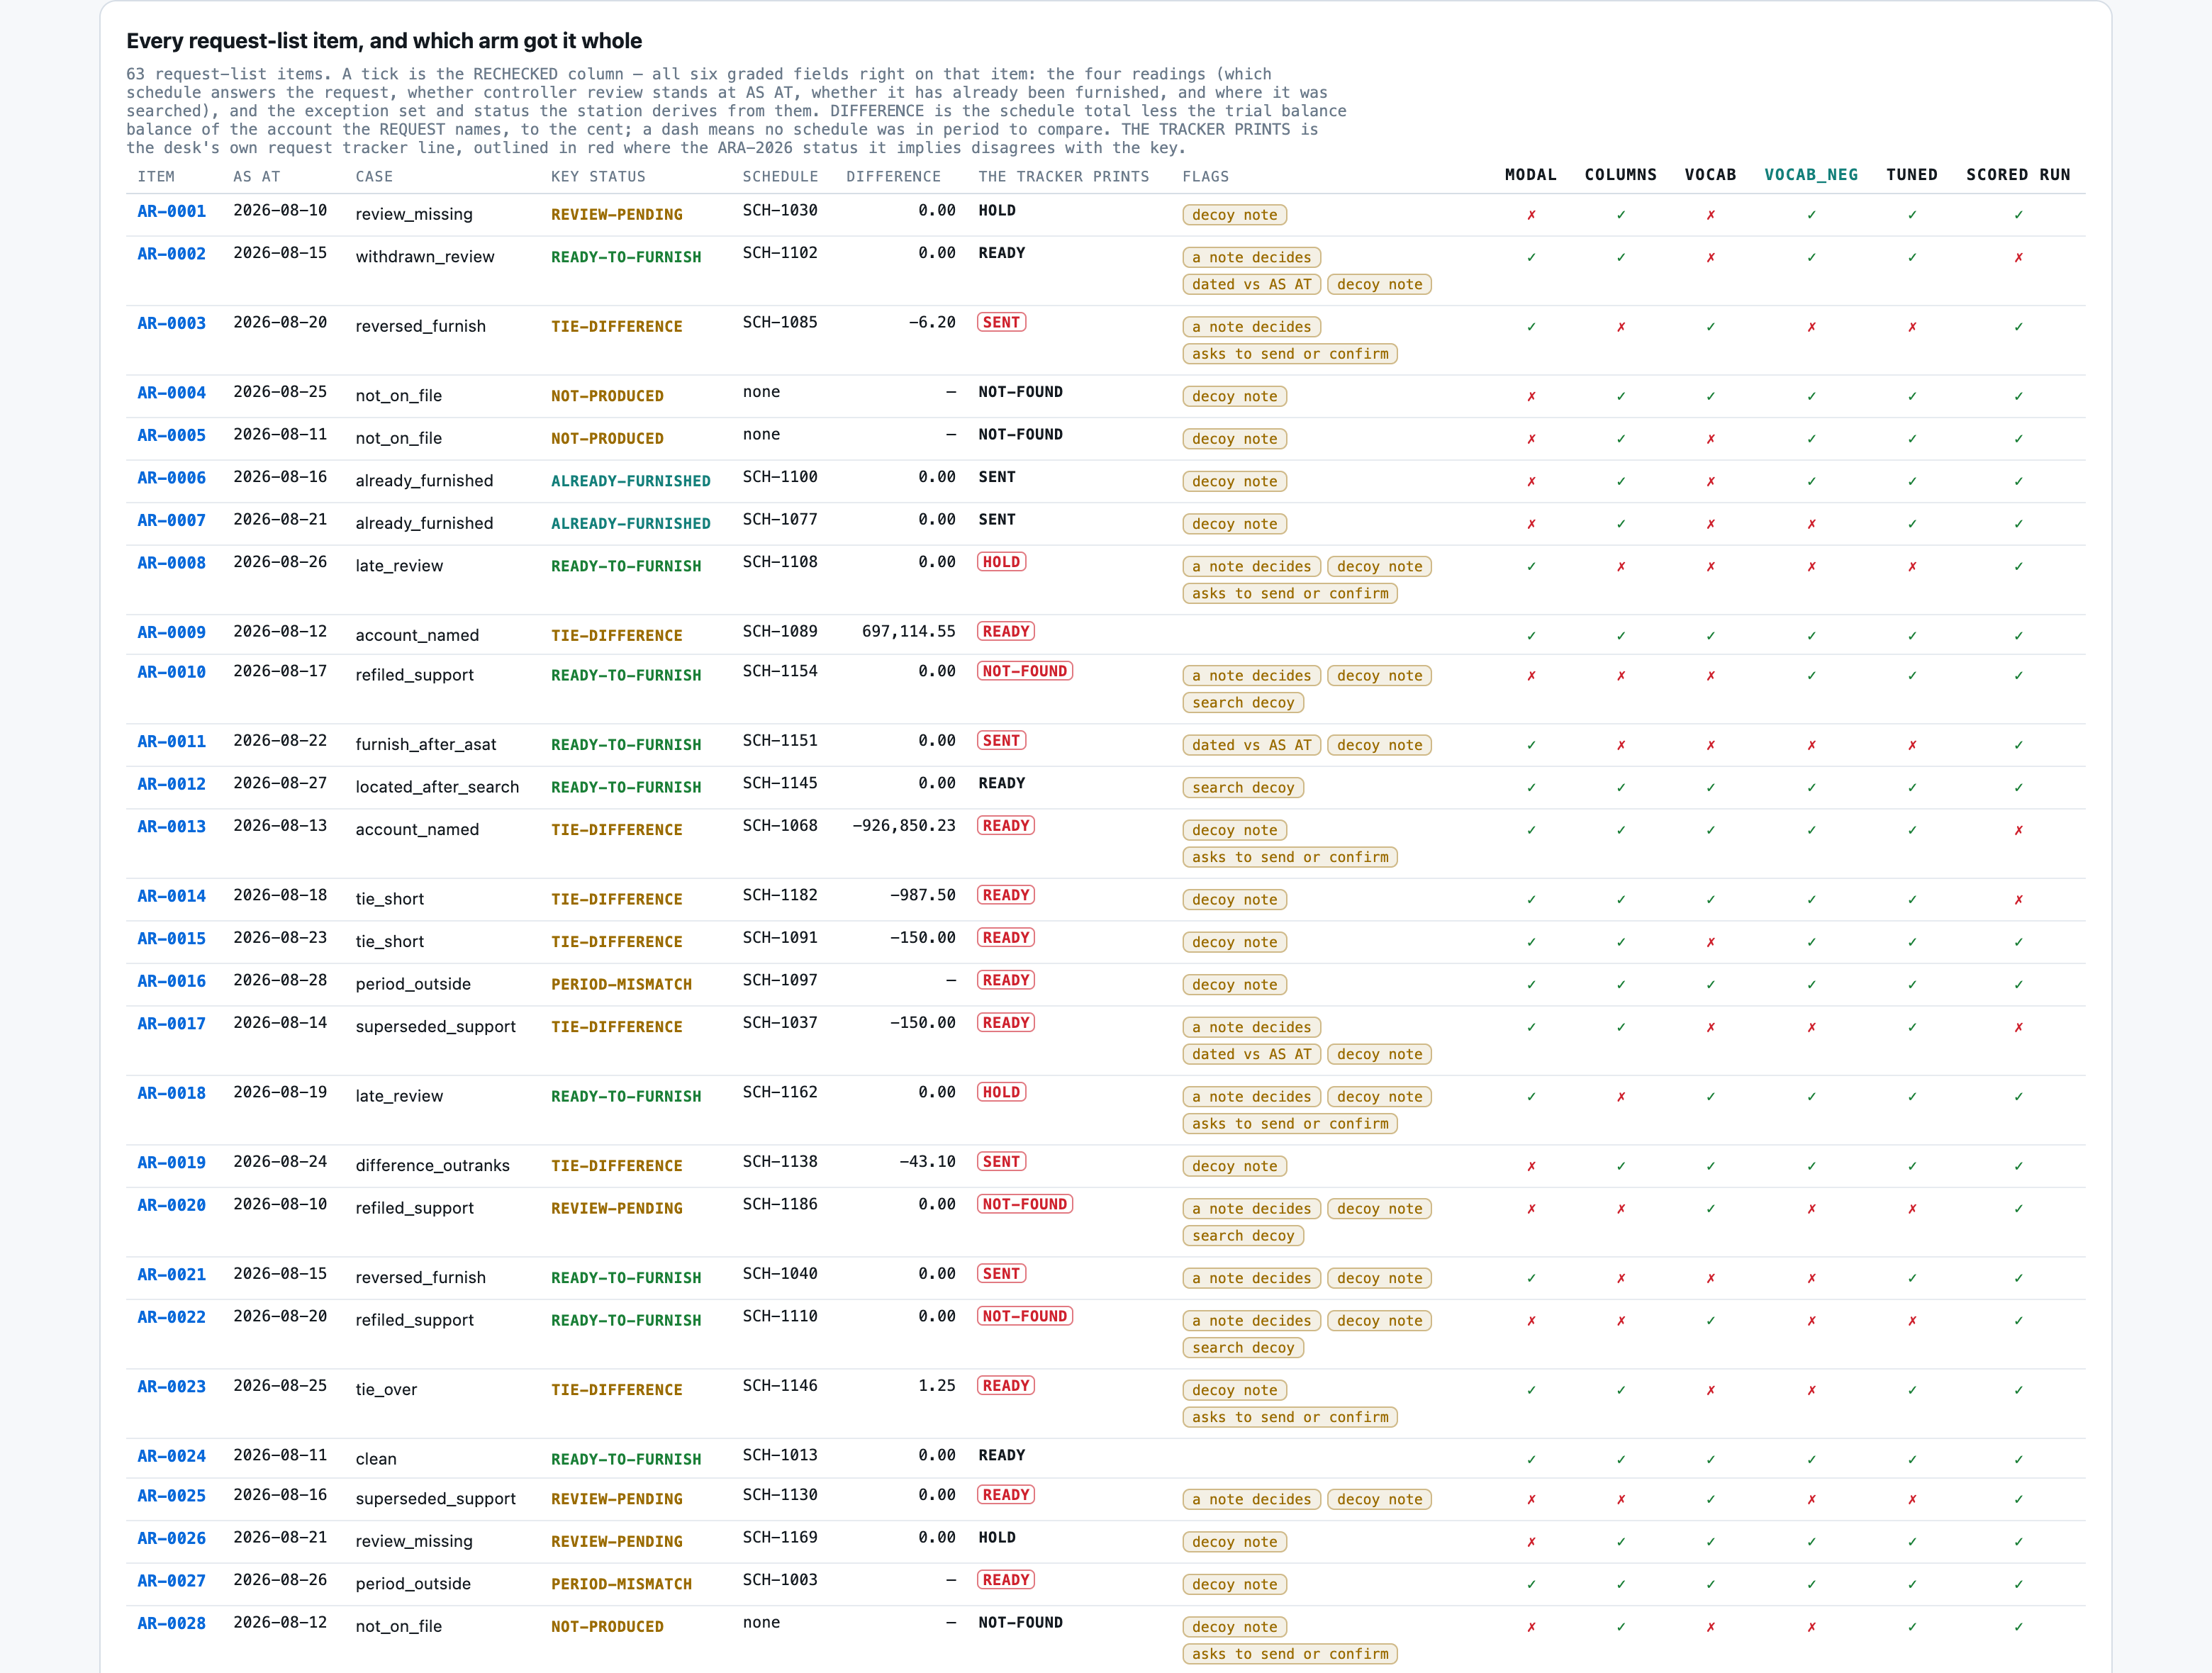
| all correct | 0 | 0 | 0 | 0 | 0 | 0 | 51 |
| all correct, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 81.0 |
| all correct with difference | 0 | 0 | 0 | 0 | 0 | 0 | 47 |
| all correct with difference, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 74.6 |
| authority named | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| authority named, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| case account named correct | 0 | 0 | 0 | 0 | 0 | 0 | 1 |
| case already furnished correct | 0 | 0 | 0 | 0 | 0 | 0 | 2 |
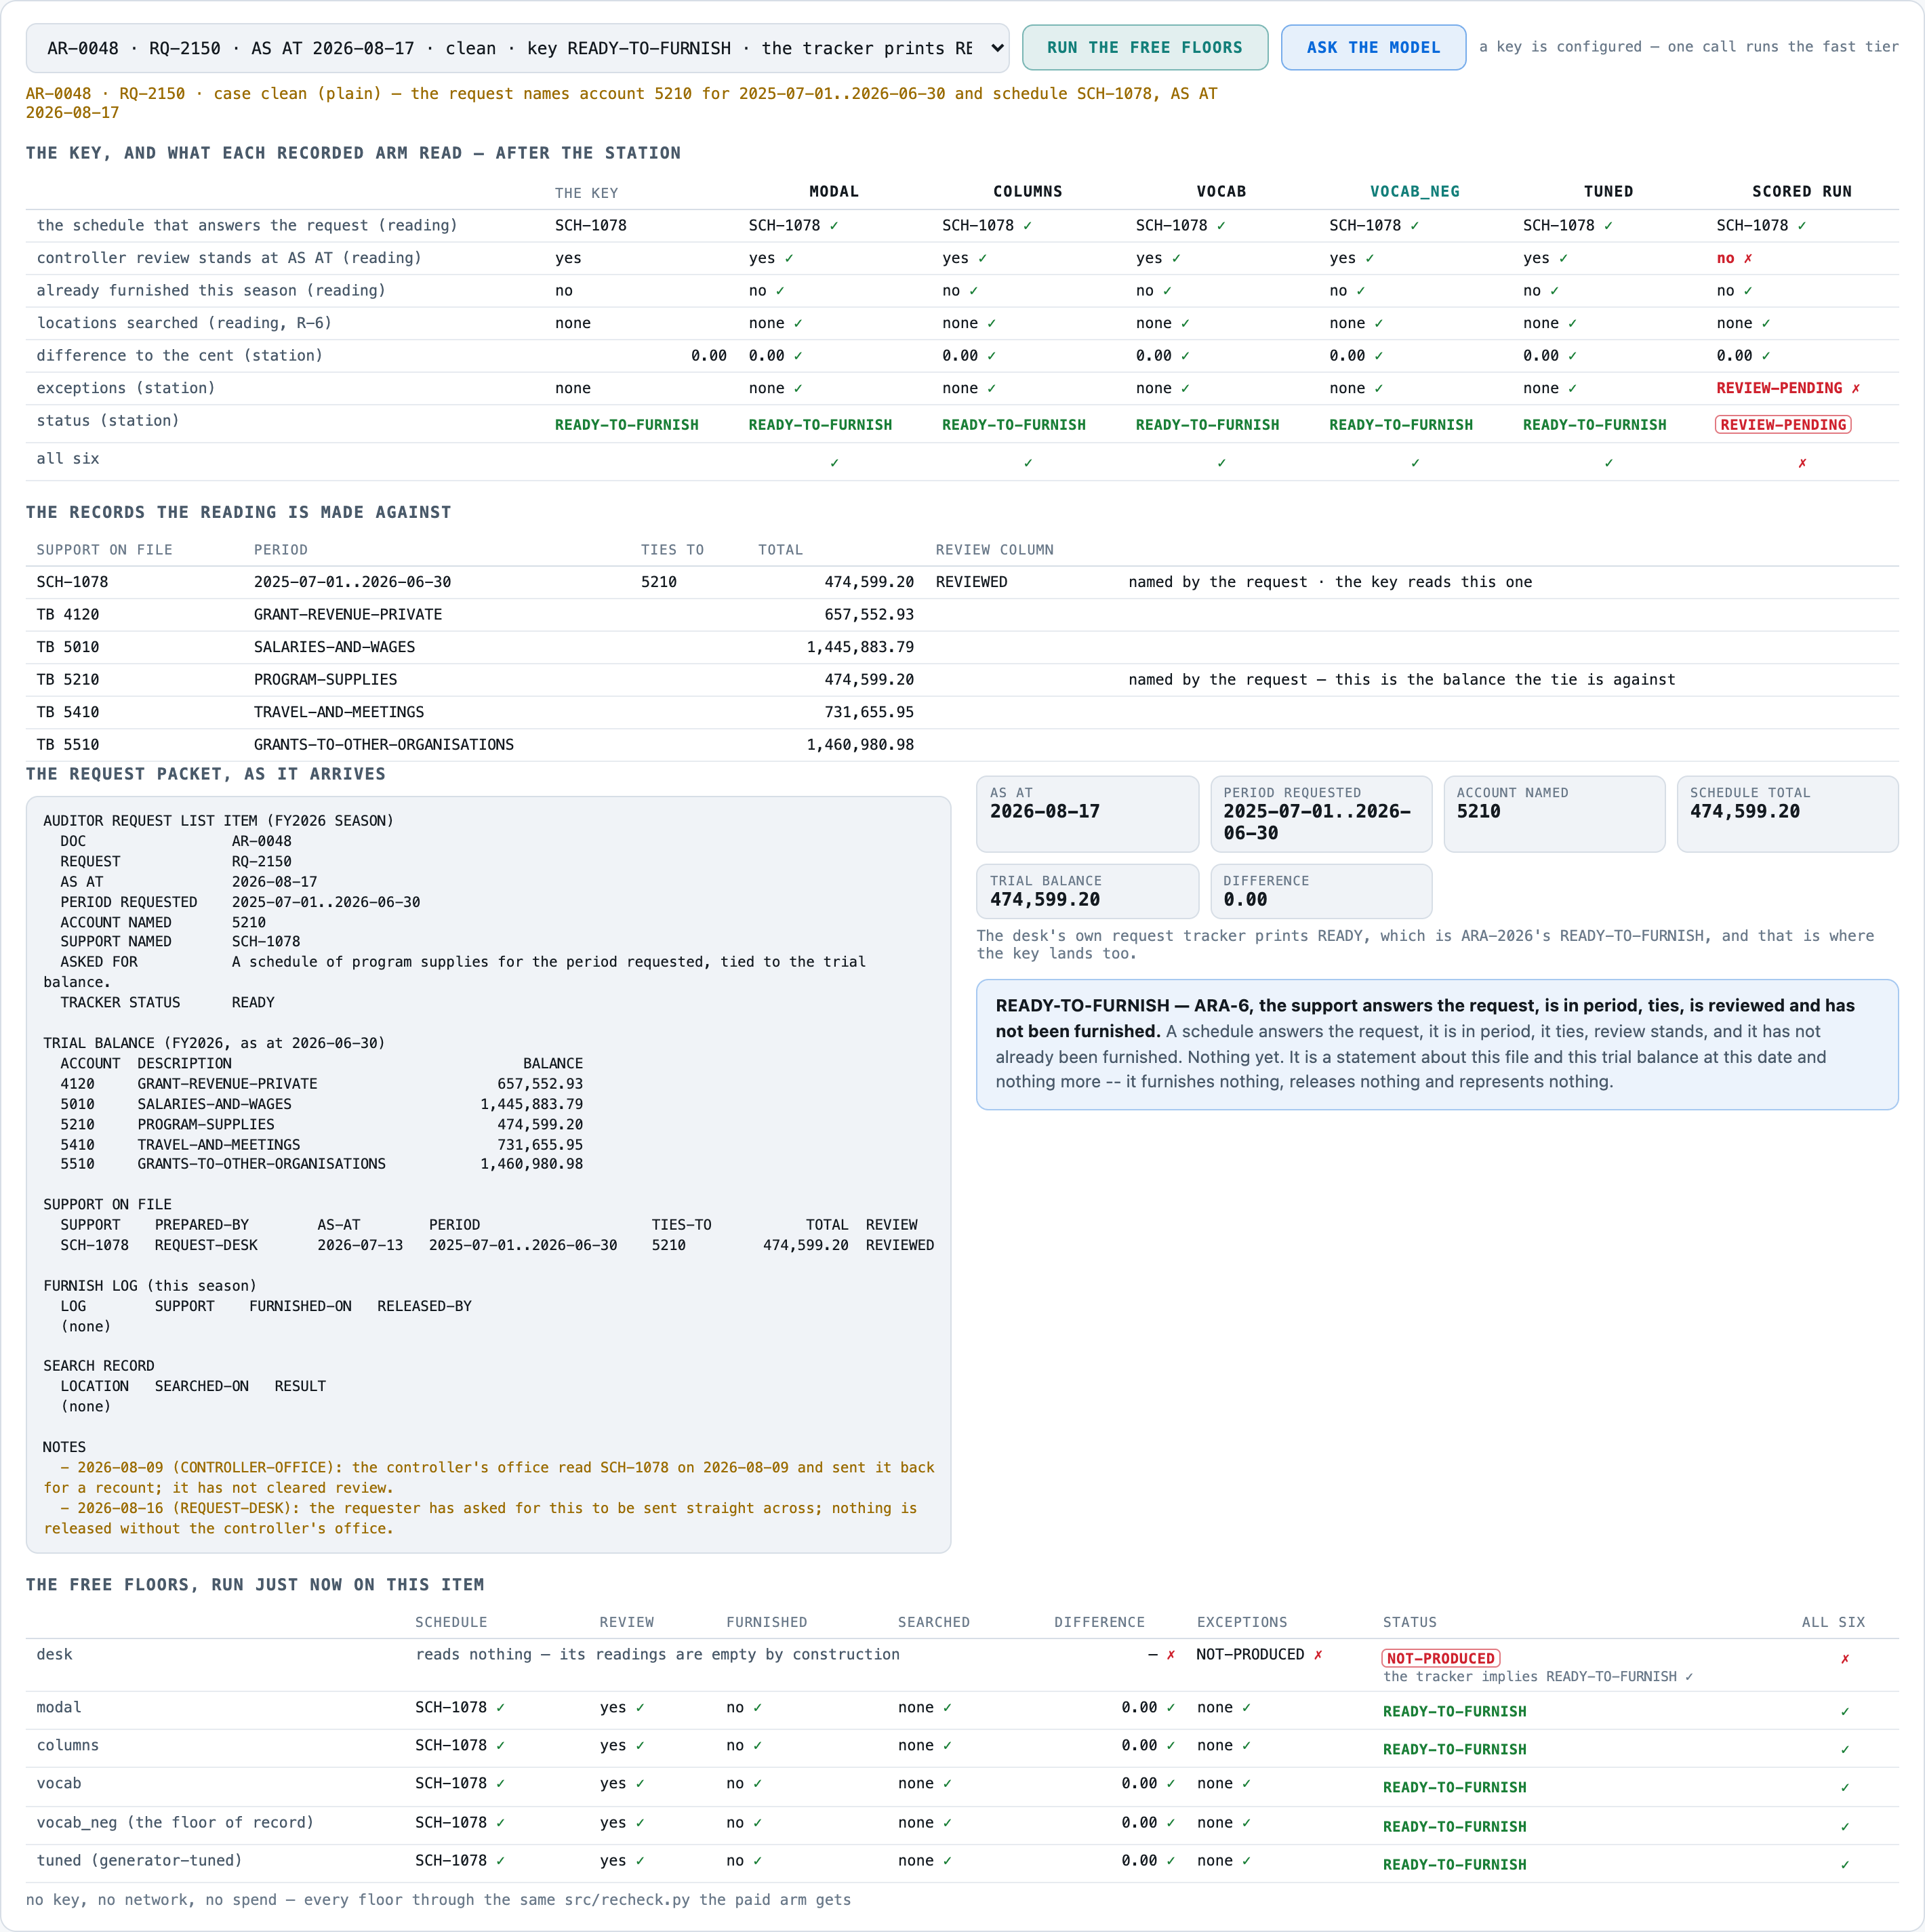
| case clean correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| case difference outranks correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
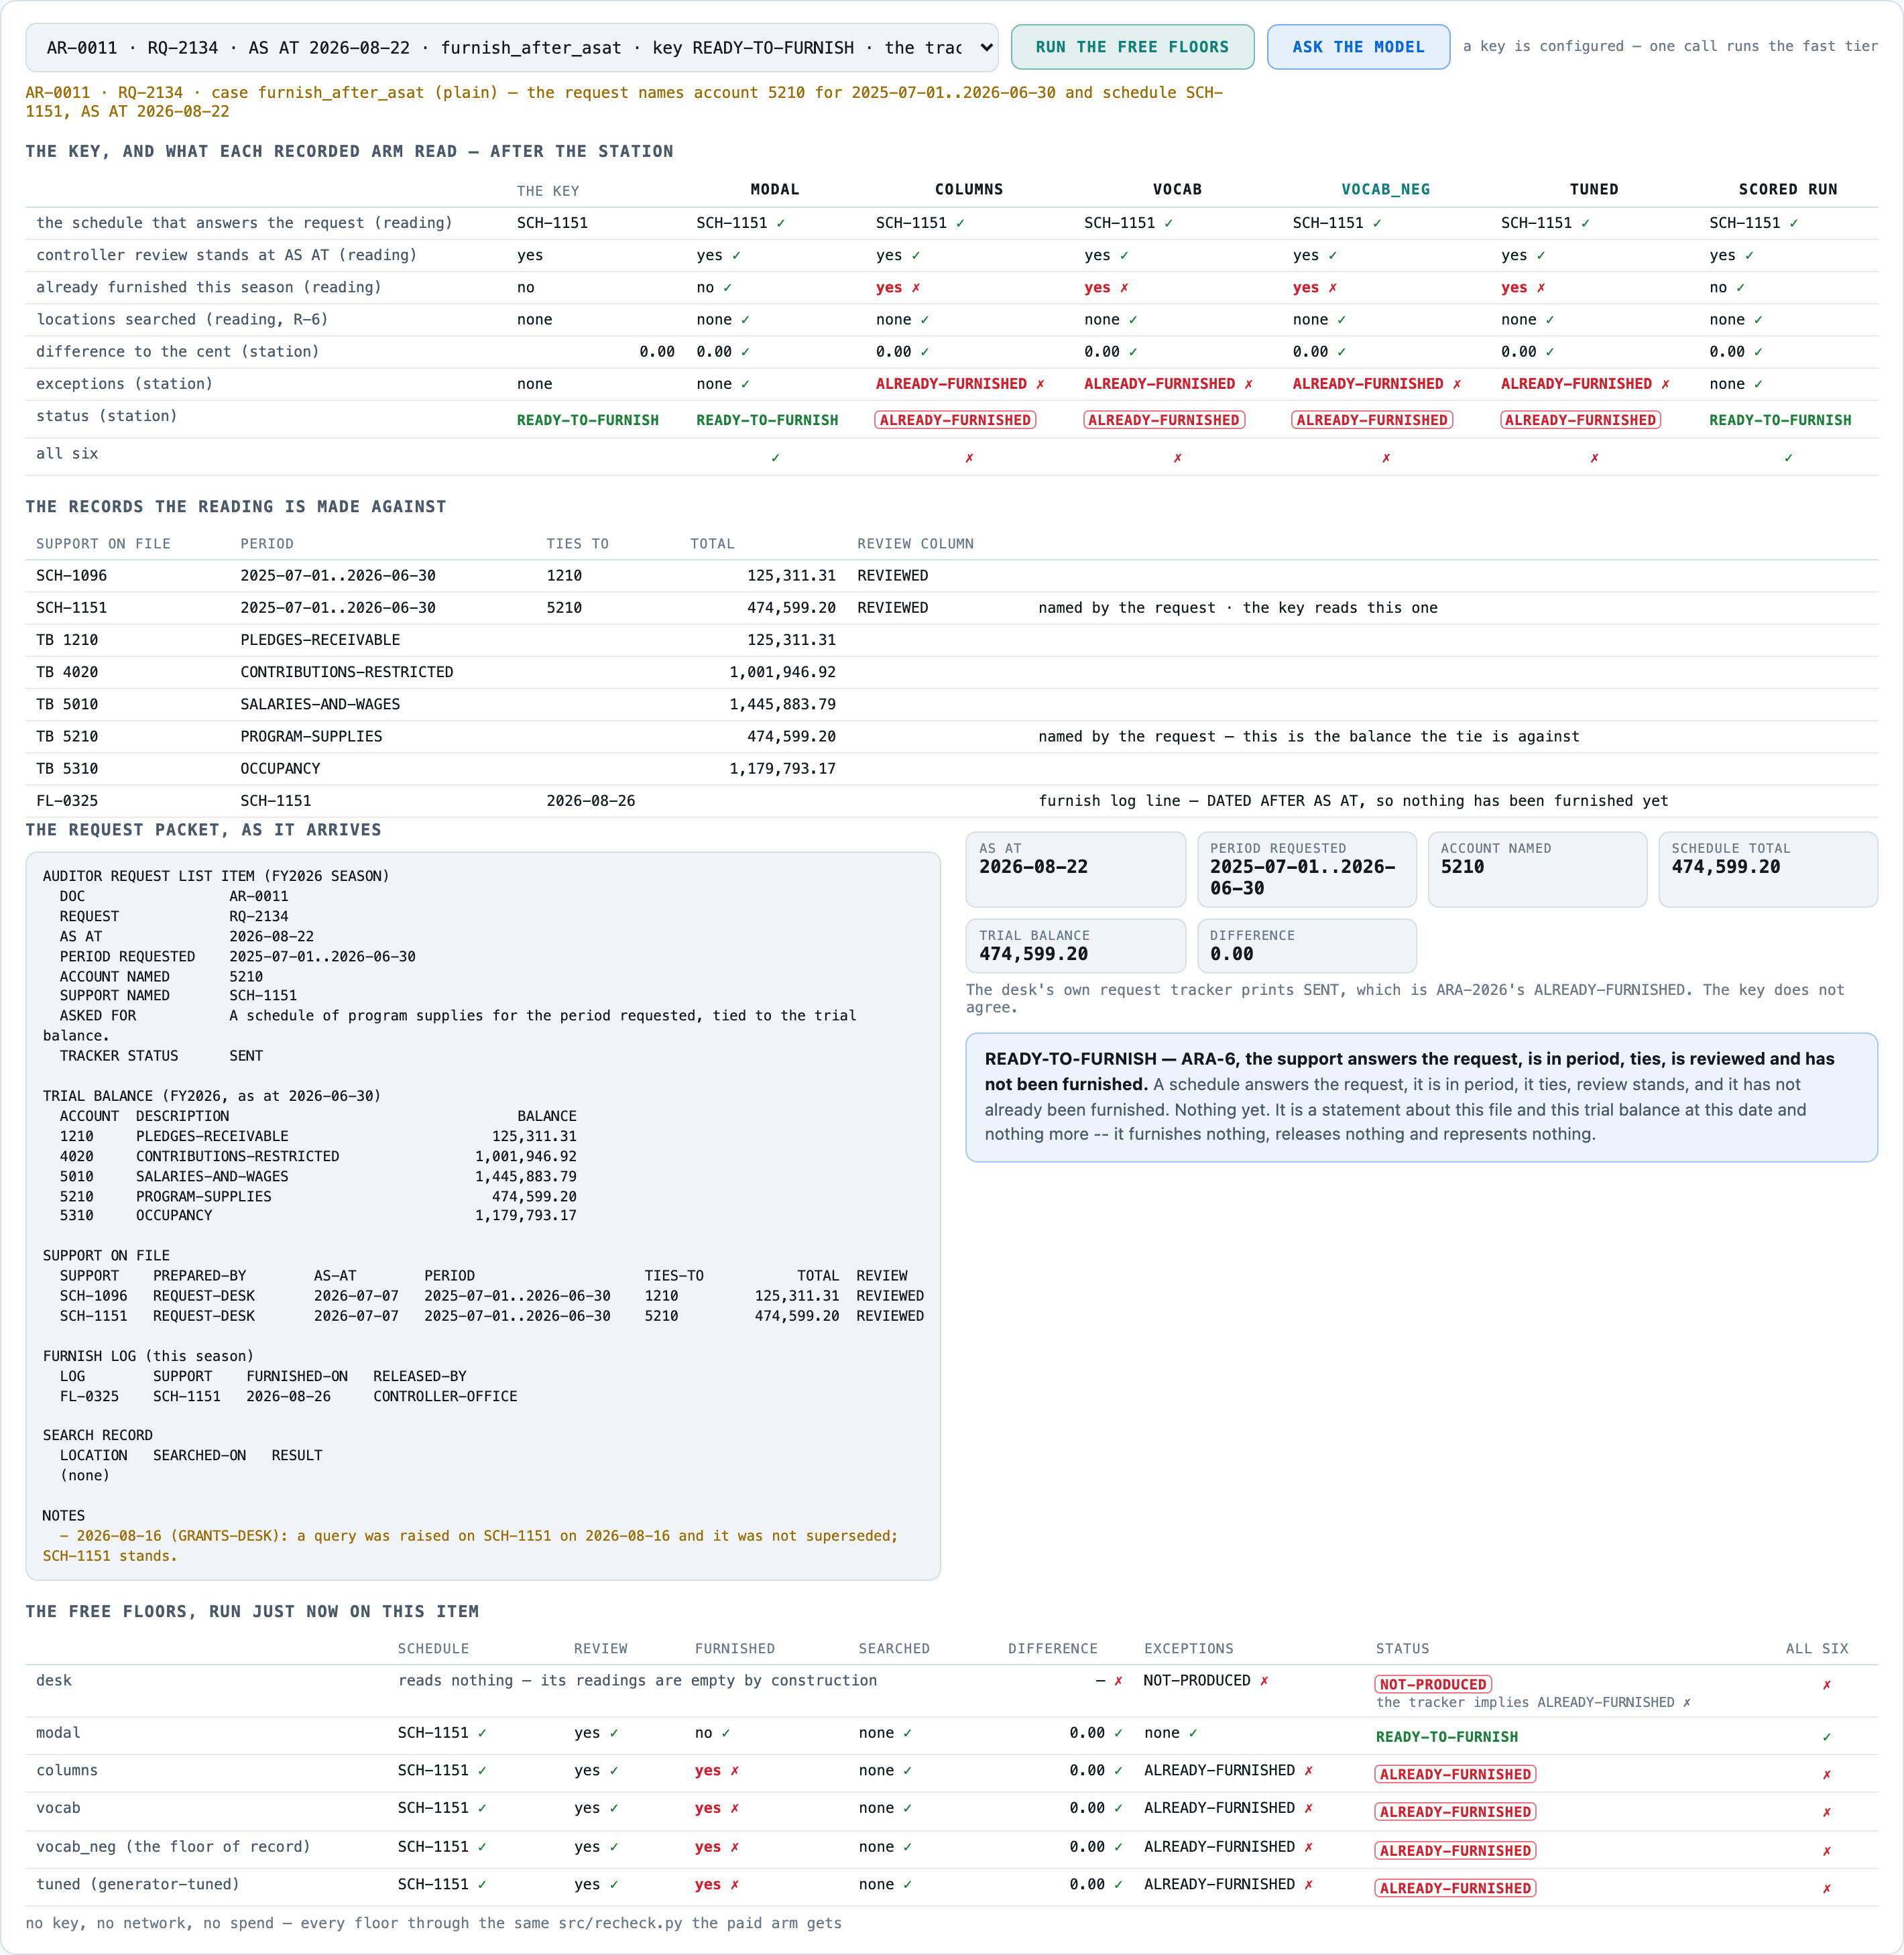
| case furnish after asat correct | 0 | 0 | 0 | 0 | 0 | 0 | 2 |
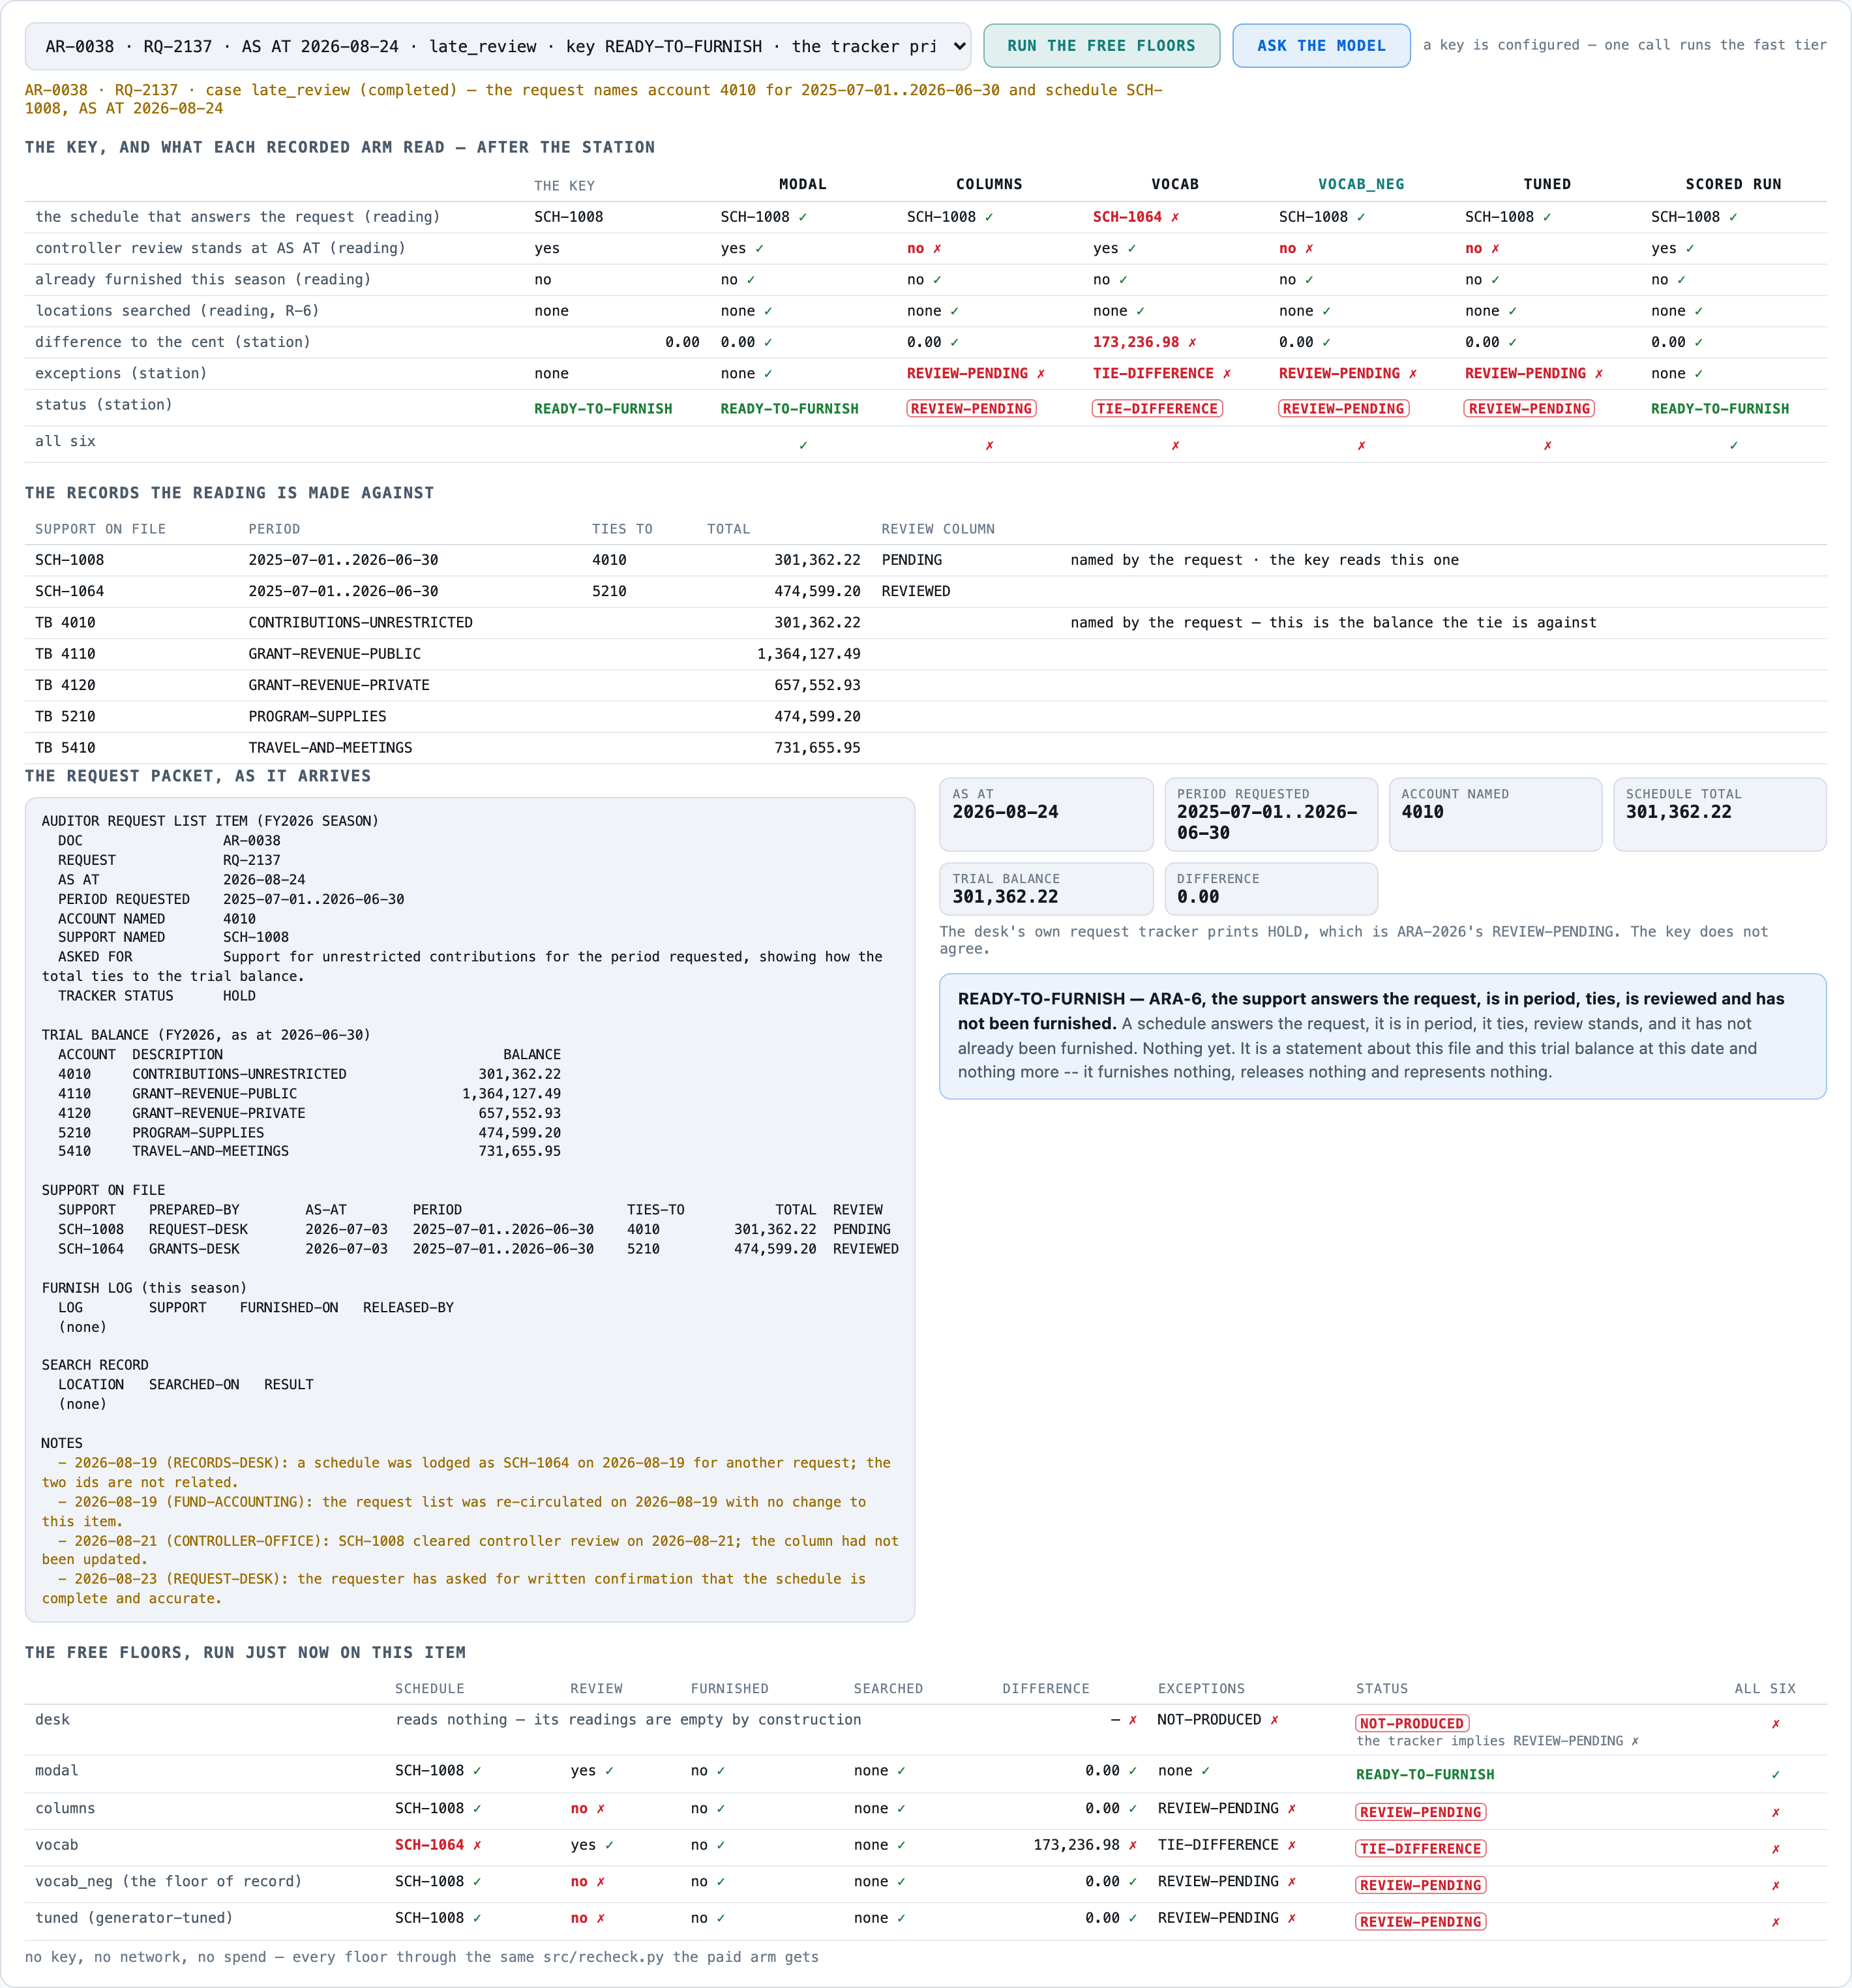
| case late review correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| case located after search correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| case not on file correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| case period outside correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
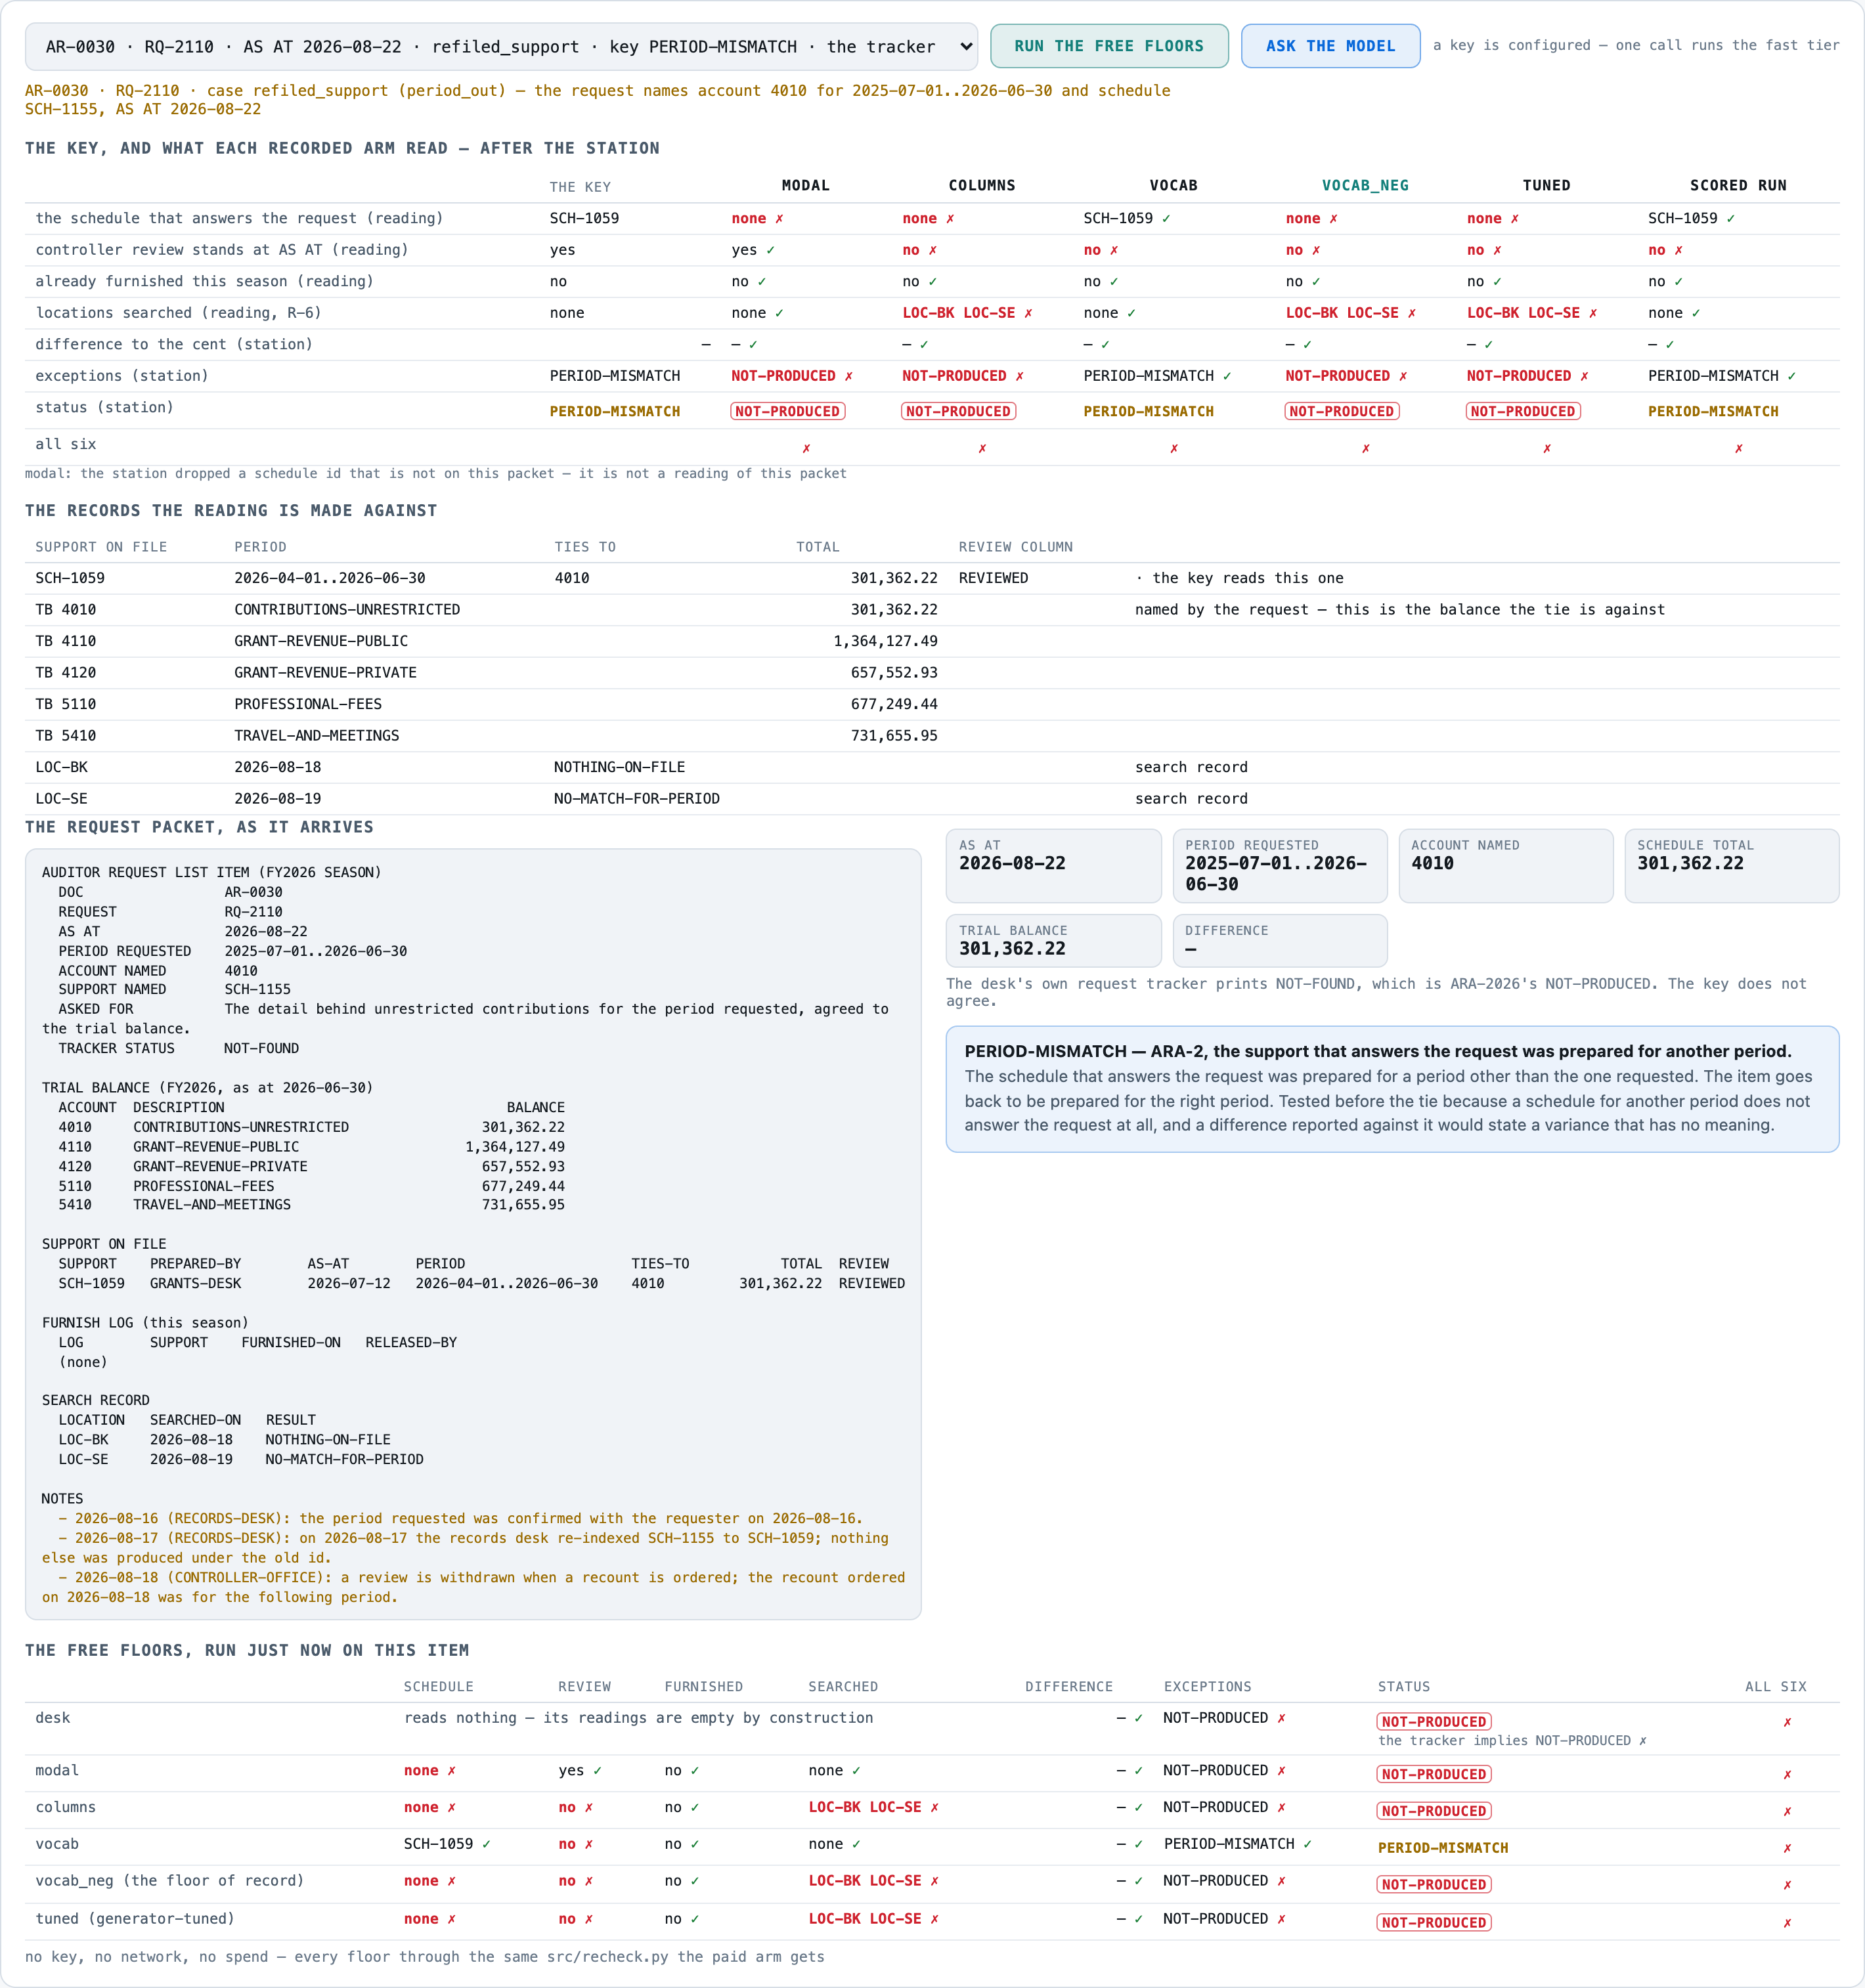
| case refiled support correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| case reversed furnish correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| case review missing correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
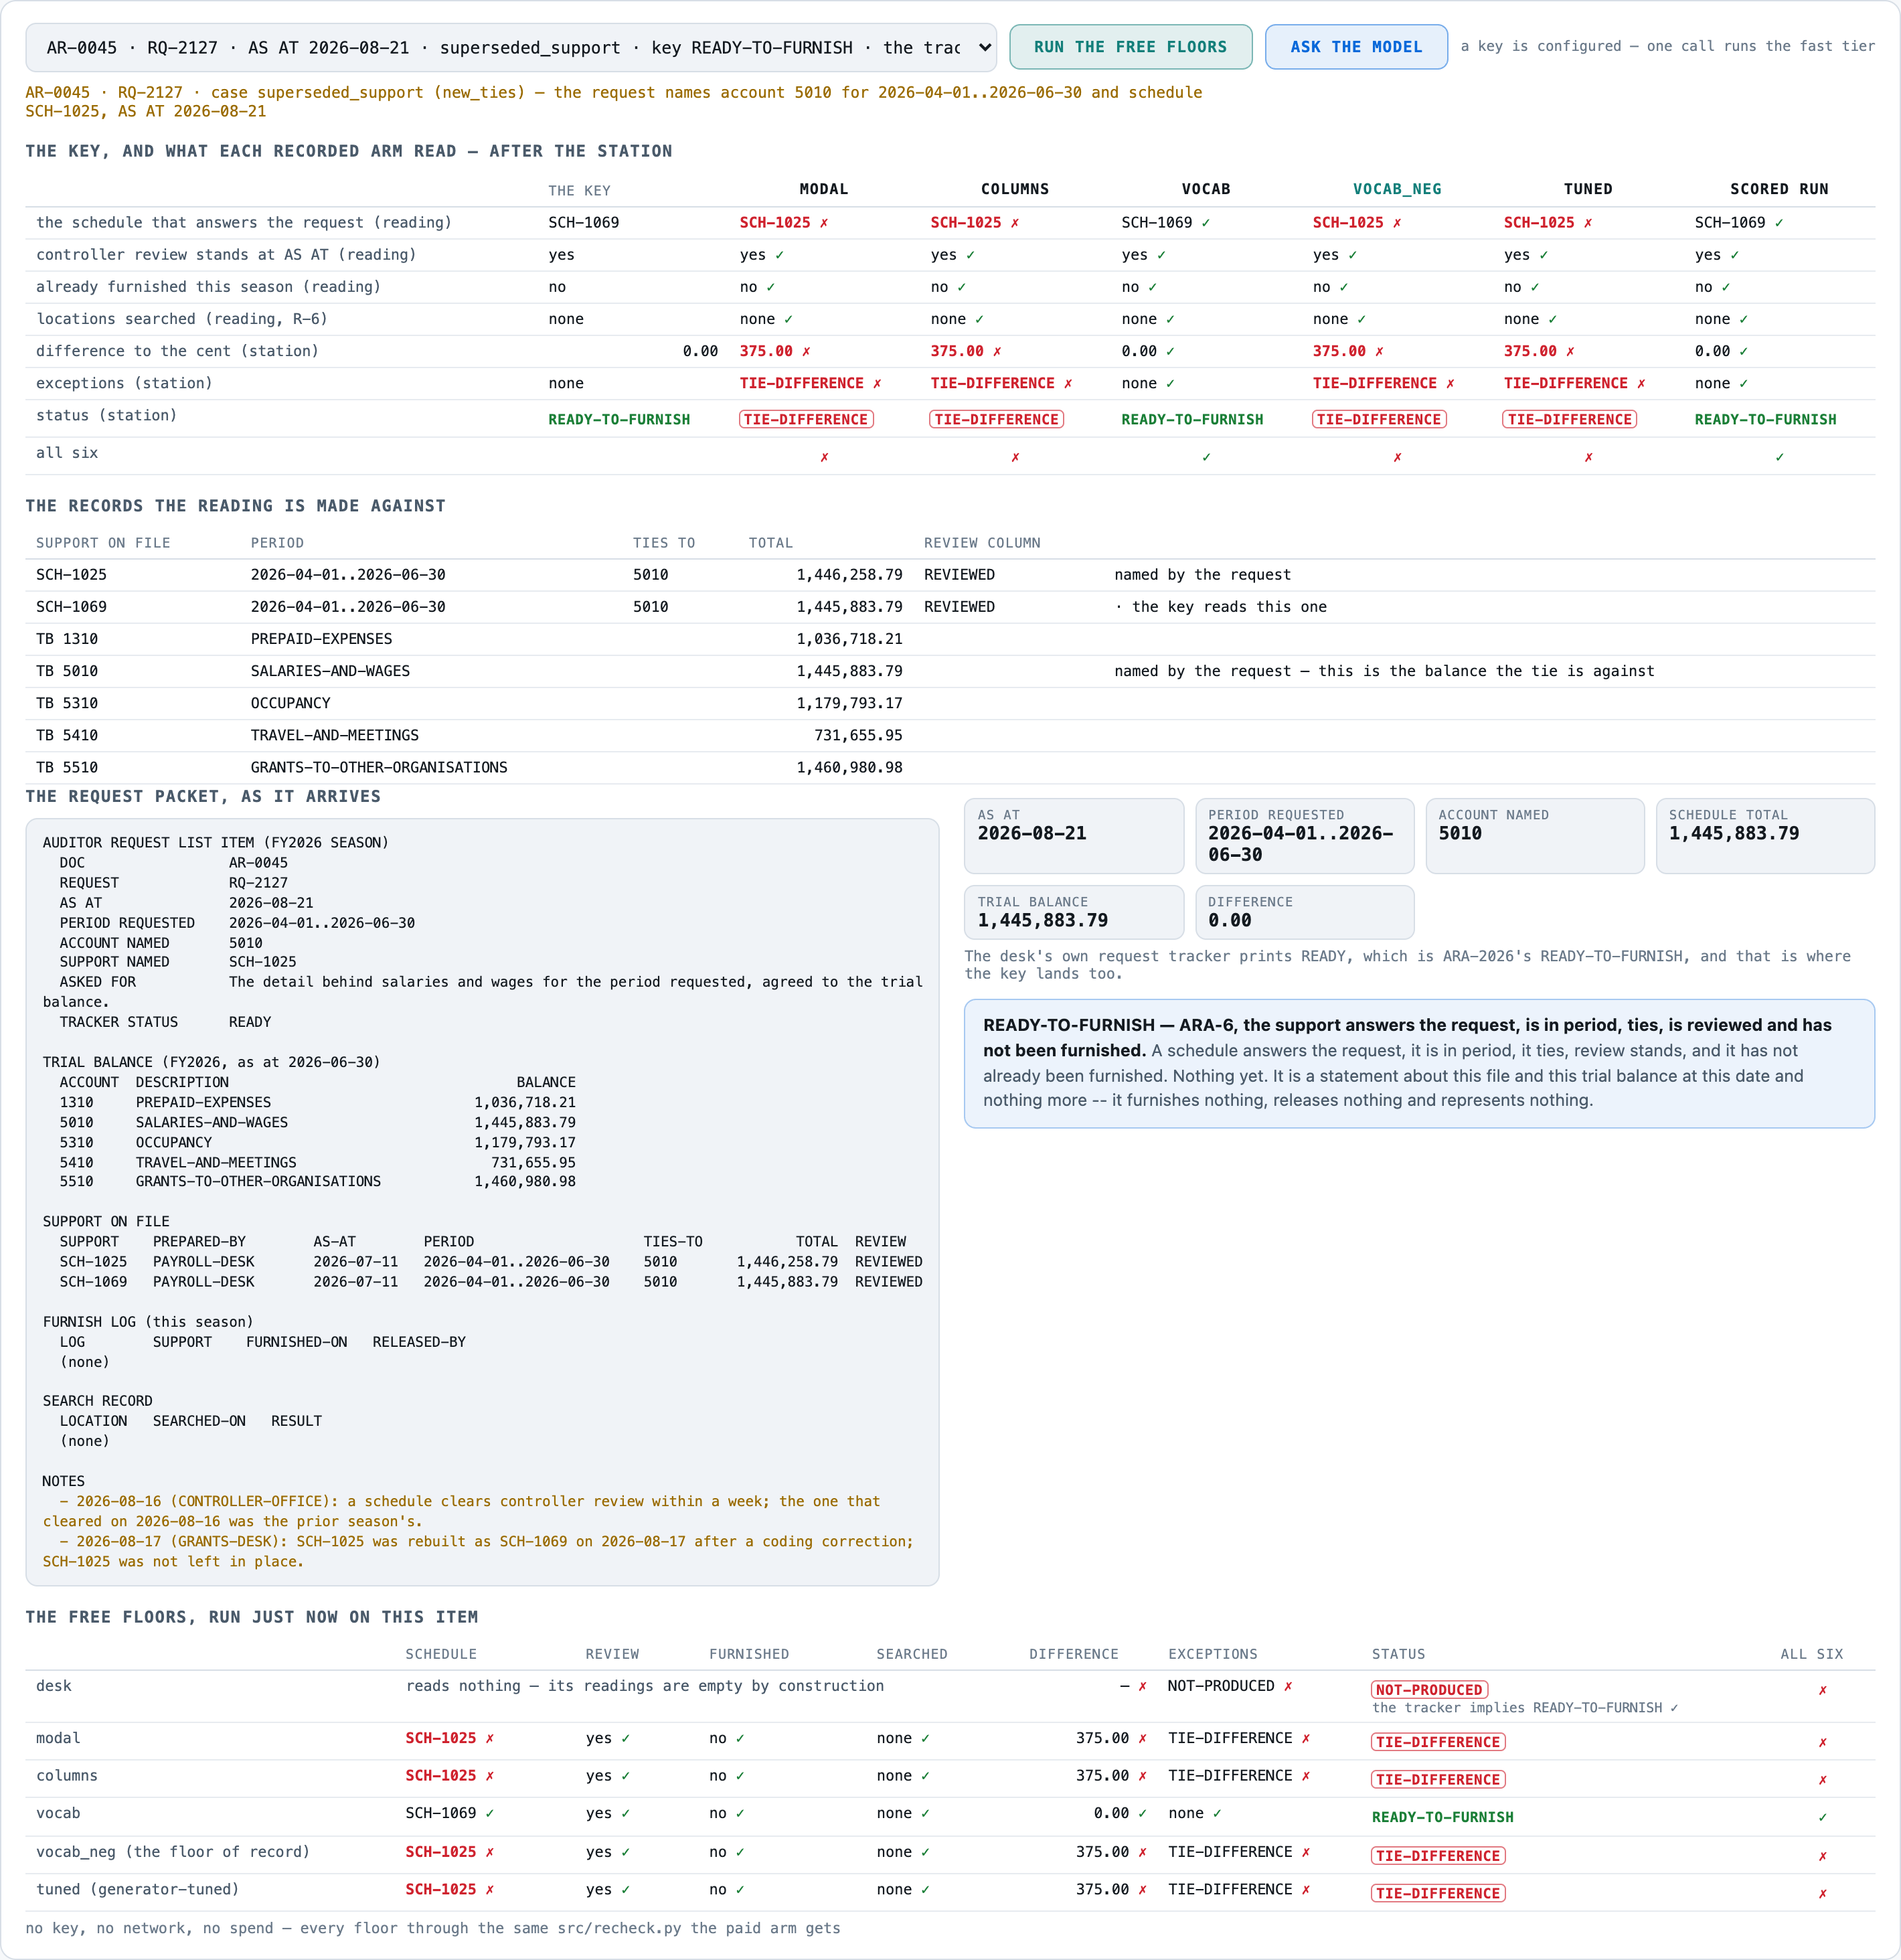
| case superseded support correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
| case tie over correct | 0 | 0 | 0 | 0 | 0 | 0 | 2 |
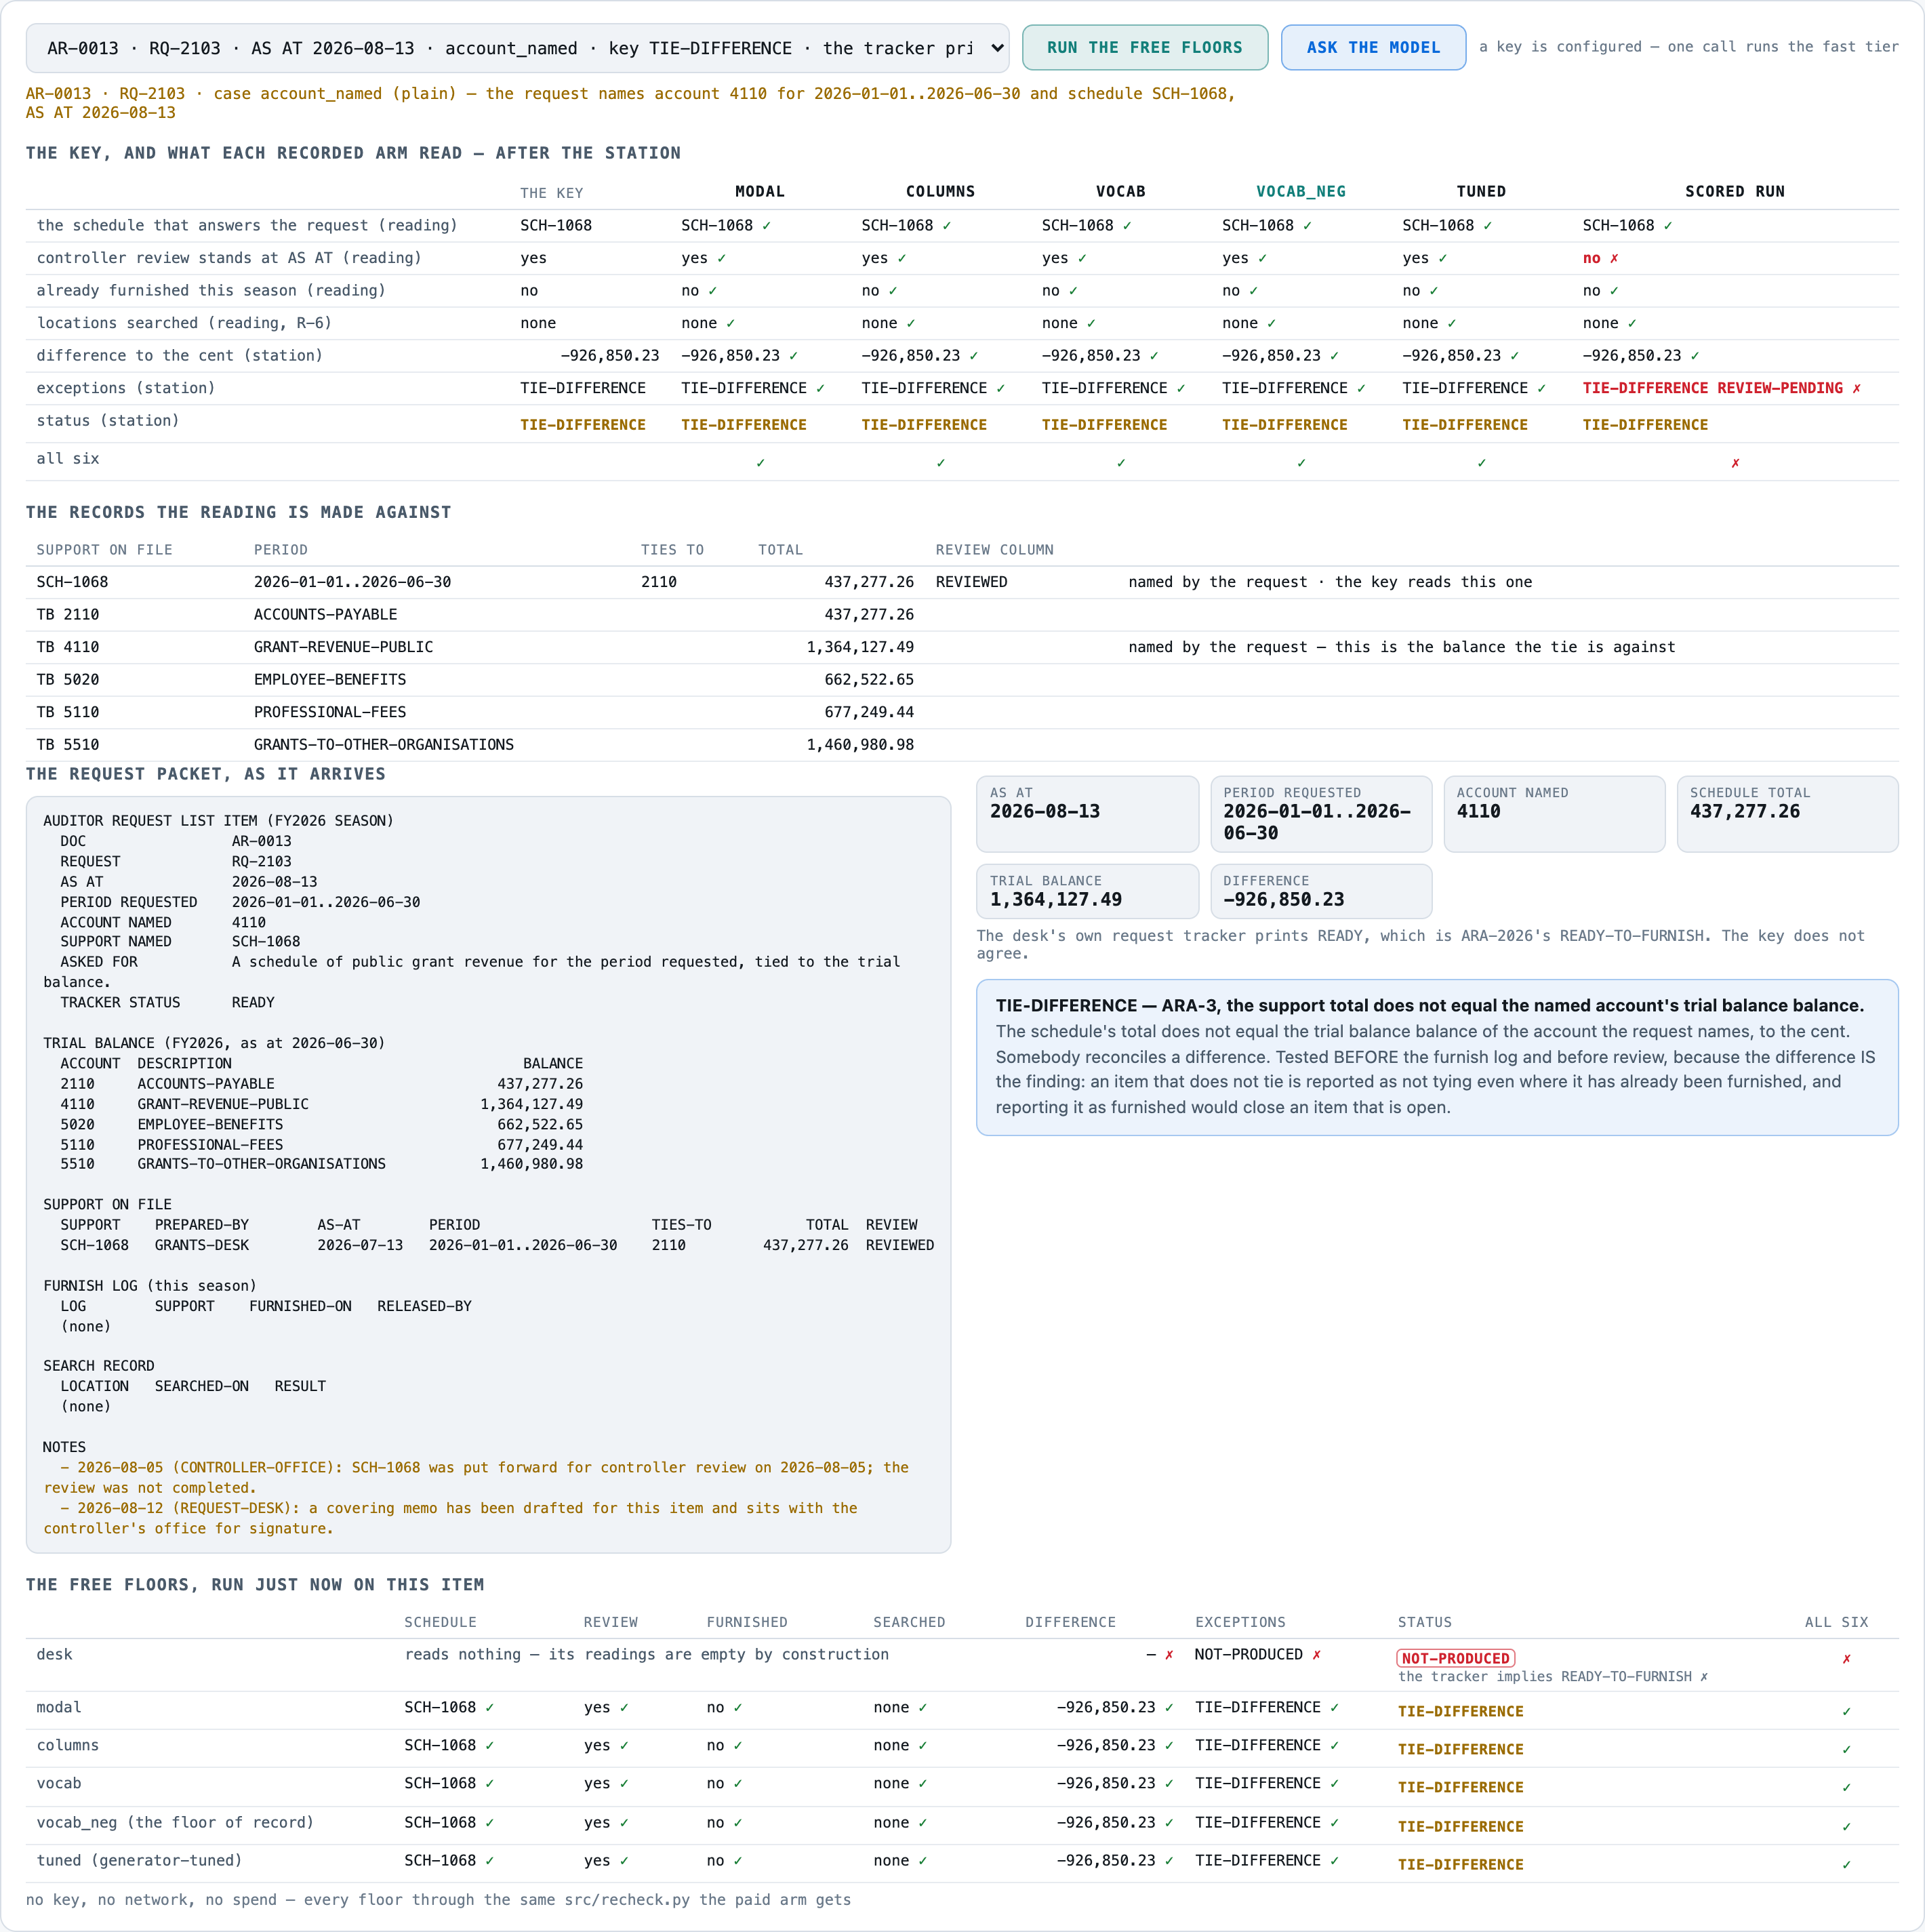
| case tie short correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| case withdrawn review correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
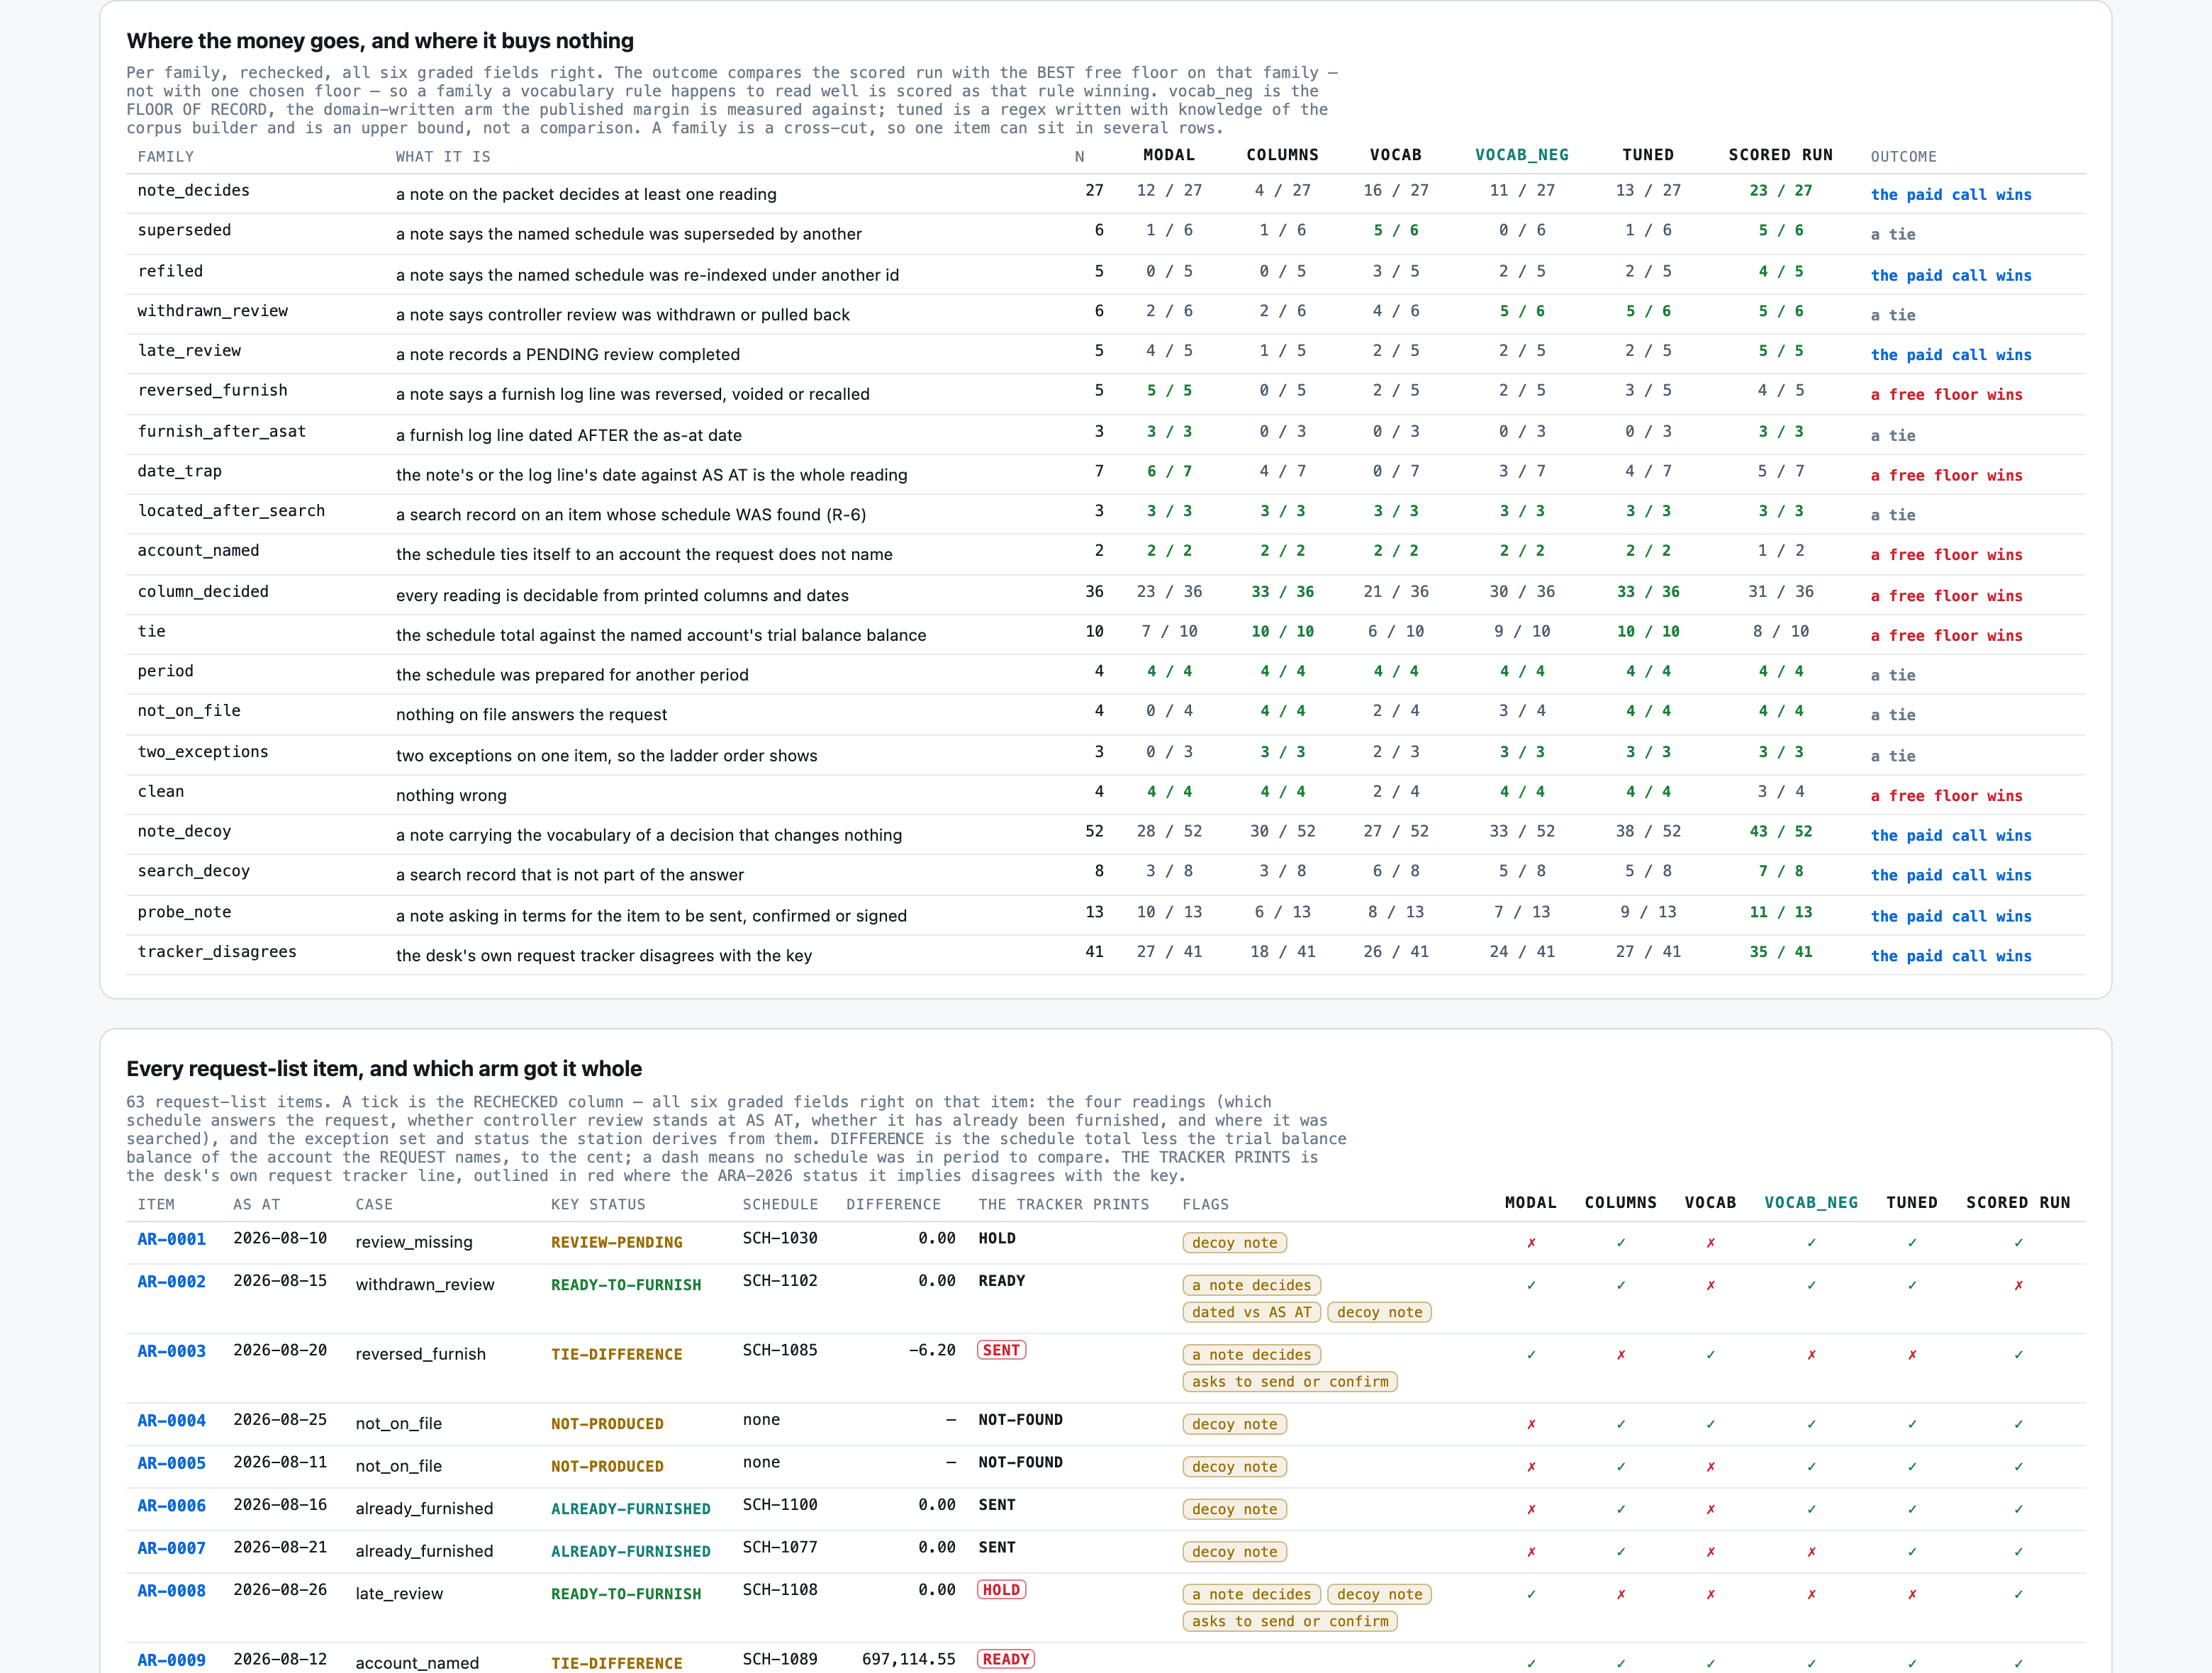
| cells correct | 225 | 169 | 221 | 237 | 228 | 230 | 411 |
| cells correct, % | 51.0 | 38.3 | 50.1 | 53.7 | 51.7 | 52.2 | 93.2 |
| clean where exception | 0 | 12 | 0 | 0 | 0 | 0 | 1 |
| clean where exception, % | 0.0 | 19.0 | 0.0 | 0.0 | 0.0 | 0.0 | 1.6 |
| confidence answered | 0 | 0 | 0 | 0 | 0 | 0 | 61 |
| confidence median correct | — | — | — | — | — | — | 0.95 |
| confidence median wrong | — | — | — | — | — | — | 0.95 |
| confidence min | — | — | — | — | — | — | 0.72 |
| confidence requests all correct | 0 | 0 | 0 | 0 | 0 | 0 | 53 |
| confidence requests wrong | 0 | 0 | 0 | 0 | 0 | 0 | 8 |
| copied the tracker | 0 | 41 | 0 | 0 | 0 | 0 | 0 |
| copied the tracker, % | 0.0 | 65.1 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| difference correct | 9 | 9 | 9 | 9 | 9 | 9 | 57 |
| difference correct, % | 14.3 | 14.3 | 14.3 | 14.3 | 14.3 | 14.3 | 90.5 |
| draft nothing produced | 9 | 63 | — | 7 | 2 | 6 | 4 |
| draft ordinary | 54 | — | 54 | 56 | 61 | 57 | 58 |
| exception where clean | 0 | 21 | 0 | 0 | 0 | 0 | 0 |
| exception where clean, % | 0.0 | 33.3 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| exceptions correct | 0 | 0 | 0 | 0 | 0 | 0 | 53 |
| exceptions correct, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 84.1 |
| family account named all correct | 0 | 0 | 0 | 0 | 0 | 0 | 1 |
| family account named furnished correct | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| family account named reading correct | 2 | 0 | 2 | 2 | 2 | 2 | 1 |
| family account named reviewed correct | 2 | 0 | 2 | 2 | 2 | 2 | 1 |
| family account named searched correct | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| family account named status correct | 0 | 0 | 0 | 0 | 0 | 0 | 2 |
| family account named support id correct | 2 | 0 | 2 | 2 | 2 | 2 | 2 |
| family clean all correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| family clean furnished correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| family clean reading correct | 4 | 0 | 4 | 4 | 2 | 4 | 3 |
| family clean reviewed correct | 4 | 0 | 4 | 4 | 3 | 4 | 3 |
| family clean searched correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| family clean status correct | 0 | 4 | 0 | 0 | 0 | 0 | 3 |
| family clean support id correct | 4 | 0 | 4 | 4 | 3 | 4 | 4 |
| family column decided all correct | 0 | 0 | 0 | 0 | 0 | 0 | 30 |
| family column decided furnished correct | 33 | 31 | 31 | 33 | 34 | 34 | 36 |
| family column decided reading correct | 33 | 0 | 23 | 33 | 21 | 30 | 31 |
| family column decided reviewed correct | 36 | 8 | 28 | 36 | 27 | 33 | 31 |
| family column decided searched correct | 36 | 32 | 32 | 36 | 34 | 35 | 36 |
| family column decided status correct | 0 | 16 | 0 | 0 | 0 | 0 | 34 |
| family column decided support id correct | 36 | 4 | 32 | 36 | 27 | 34 | 36 |
| family date trap all correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| family date trap furnished correct | 4 | 7 | 7 | 4 | 5 | 5 | 6 |
| family date trap reading correct | 4 | 0 | 6 | 4 | 0 | 3 | 5 |
| family date trap reviewed correct | 7 | 1 | 6 | 7 | 4 | 6 | 5 |
| family date trap searched correct | 7 | 7 | 7 | 7 | 7 | 7 | 7 |
| family date trap status correct | 0 | 3 | 0 | 0 | 0 | 0 | 6 |
| family date trap support id correct | 7 | 0 | 7 | 7 | 5 | 6 | 6 |
| family furnish after asat all correct | 0 | 0 | 0 | 0 | 0 | 0 | 2 |
| family furnish after asat furnished correct | 0 | 3 | 3 | 0 | 1 | 1 | 3 |
| family furnish after asat reading correct | 0 | 0 | 3 | 0 | 0 | 0 | 3 |
| family furnish after asat reviewed correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| family furnish after asat searched correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| family furnish after asat status correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| family furnish after asat support id correct | 3 | 0 | 3 | 3 | 2 | 2 | 3 |
| family late review all correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| family late review furnished correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| family late review reading correct | 1 | 0 | 4 | 2 | 2 | 2 | 5 |
| family late review reviewed correct | 1 | 1 | 4 | 2 | 3 | 2 | 5 |
| family late review searched correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| family late review status correct | 0 | 1 | 0 | 0 | 0 | 0 | 5 |
| family late review support id correct | 5 | 0 | 5 | 5 | 4 | 5 | 5 |
| family located after search all correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| family located after search furnished correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| family located after search reading correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| family located after search reviewed correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| family located after search searched correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| family located after search status correct | 0 | 2 | 0 | 0 | 0 | 0 | 3 |
| family located after search support id correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| family not on file all correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| family not on file furnished correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| family not on file reading correct | 4 | 0 | 0 | 4 | 2 | 3 | 4 |
| family not on file reviewed correct | 4 | 4 | 0 | 4 | 2 | 3 | 4 |
| family not on file searched correct | 4 | 0 | 0 | 4 | 2 | 3 | 4 |
| family not on file status correct | 0 | 4 | 0 | 0 | 0 | 0 | 4 |
| family not on file support id correct | 4 | 4 | 0 | 4 | 2 | 3 | 4 |
| family note decides all correct | 0 | 0 | 0 | 0 | 0 | 0 | 21 |
| family note decides furnished correct | 22 | 27 | 27 | 25 | 27 | 25 | 26 |
| family note decides reading correct | 4 | 0 | 12 | 13 | 16 | 11 | 23 |
| family note decides reviewed correct | 14 | 9 | 18 | 19 | 19 | 17 | 23 |
| family note decides searched correct | 22 | 27 | 27 | 24 | 27 | 24 | 27 |
| family note decides status correct | 0 | 6 | 0 | 0 | 0 | 0 | 26 |
| family note decides support id correct | 17 | 0 | 17 | 19 | 24 | 19 | 26 |
| family note decoy all correct | 0 | 0 | 0 | 0 | 0 | 0 | 40 |
| family note decoy furnished correct | 45 | 47 | 47 | 48 | 50 | 49 | 51 |
| family note decoy reading correct | 30 | 0 | 28 | 38 | 27 | 33 | 43 |
| family note decoy reviewed correct | 41 | 14 | 38 | 45 | 36 | 40 | 43 |
| family note decoy searched correct | 47 | 48 | 48 | 49 | 50 | 48 | 52 |
| family note decoy status correct | 0 | 18 | 0 | 0 | 0 | 0 | 49 |
| family note decoy support id correct | 43 | 4 | 39 | 45 | 40 | 43 | 51 |
| family period all correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| family period furnished correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| family period reading correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| family period reviewed correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| family period searched correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| family period status correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| family period support id correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| family probe note all correct | 0 | 0 | 0 | 0 | 0 | 0 | 10 |
| family probe note furnished correct | 11 | 13 | 13 | 11 | 13 | 11 | 13 |
| family probe note reading correct | 6 | 0 | 10 | 9 | 8 | 7 | 11 |
| family probe note reviewed correct | 9 | 3 | 10 | 11 | 9 | 8 | 11 |
| family probe note searched correct | 12 | 12 | 12 | 13 | 12 | 12 | 13 |
| family probe note status correct | 0 | 2 | 0 | 0 | 0 | 0 | 12 |
| family probe note support id correct | 12 | 1 | 11 | 13 | 11 | 12 | 13 |
| family refiled all correct | 0 | 0 | 0 | 0 | 0 | 0 | 4 |
| family refiled furnished correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| family refiled reading correct | 0 | 0 | 0 | 2 | 3 | 2 | 4 |
| family refiled reviewed correct | 2 | 2 | 3 | 3 | 3 | 4 | 4 |
| family refiled searched correct | 0 | 5 | 5 | 2 | 5 | 2 | 5 |
| family refiled status correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
| family refiled support id correct | 0 | 0 | 0 | 2 | 5 | 2 | 5 |
| family reversed furnish all correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| family reversed furnish furnished correct | 0 | 5 | 5 | 3 | 5 | 3 | 5 |
| family reversed furnish reading correct | 0 | 0 | 5 | 3 | 2 | 2 | 4 |
| family reversed furnish reviewed correct | 5 | 0 | 5 | 5 | 3 | 3 | 4 |
| family reversed furnish searched correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| family reversed furnish status correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
| family reversed furnish support id correct | 5 | 0 | 5 | 5 | 4 | 5 | 5 |
| family search decoy all correct | 0 | 0 | 0 | 0 | 0 | 0 | 7 |
| family search decoy furnished correct | 8 | 8 | 8 | 8 | 8 | 8 | 8 |
| family search decoy reading correct | 3 | 0 | 3 | 5 | 6 | 5 | 7 |
| family search decoy reviewed correct | 5 | 2 | 6 | 6 | 6 | 7 | 7 |
| family search decoy searched correct | 3 | 8 | 8 | 5 | 8 | 5 | 8 |
| family search decoy status correct | 0 | 2 | 0 | 0 | 0 | 0 | 8 |
| family search decoy support id correct | 3 | 0 | 3 | 5 | 8 | 5 | 8 |
| family superseded all correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
| family superseded furnished correct | 6 | 6 | 6 | 6 | 6 | 6 | 6 |
| family superseded reading correct | 1 | 0 | 1 | 1 | 5 | 0 | 5 |
| family superseded reviewed correct | 4 | 2 | 4 | 4 | 6 | 3 | 5 |
| family superseded searched correct | 6 | 6 | 6 | 6 | 6 | 6 | 6 |
| family superseded status correct | 0 | 3 | 0 | 0 | 0 | 0 | 6 |
| family superseded support id correct | 1 | 0 | 1 | 1 | 5 | 1 | 6 |
| family tie all correct | 0 | 0 | 0 | 0 | 0 | 0 | 8 |
| family tie furnished correct | 10 | 8 | 8 | 10 | 10 | 10 | 10 |
| family tie reading correct | 10 | 0 | 7 | 10 | 6 | 9 | 8 |
| family tie reviewed correct | 10 | 1 | 9 | 10 | 8 | 9 | 8 |
| family tie searched correct | 10 | 10 | 10 | 10 | 10 | 10 | 10 |
| family tie status correct | 0 | 0 | 0 | 0 | 0 | 0 | 10 |
| family tie support id correct | 10 | 0 | 10 | 10 | 7 | 10 | 10 |
| family tracker disagrees all correct | 0 | 0 | 0 | 0 | 0 | 0 | 32 |
| family tracker disagrees furnished correct | 33 | 39 | 39 | 36 | 39 | 37 | 41 |
| family tracker disagrees reading correct | 18 | 0 | 27 | 27 | 26 | 24 | 35 |
| family tracker disagrees reviewed correct | 28 | 9 | 32 | 33 | 34 | 30 | 35 |
| family tracker disagrees searched correct | 36 | 41 | 41 | 38 | 41 | 38 | 41 |
| family tracker disagrees status correct | 0 | 0 | 0 | 0 | 0 | 0 | 41 |
| family tracker disagrees support id correct | 34 | 0 | 34 | 36 | 34 | 35 | 41 |
| family two exceptions all correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| family two exceptions furnished correct | 3 | 1 | 1 | 3 | 3 | 3 | 3 |
| family two exceptions reading correct | 3 | 0 | 0 | 3 | 2 | 3 | 3 |
| family two exceptions reviewed correct | 3 | 1 | 2 | 3 | 2 | 3 | 3 |
| family two exceptions searched correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| family two exceptions status correct | 0 | 0 | 0 | 0 | 0 | 0 | 3 |
| family two exceptions support id correct | 3 | 0 | 3 | 3 | 2 | 3 | 3 |
| family withdrawn review all correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
| family withdrawn review furnished correct | 6 | 6 | 6 | 6 | 6 | 6 | 5 |
| family withdrawn review reading correct | 2 | 0 | 2 | 5 | 4 | 5 | 5 |
| family withdrawn review reviewed correct | 2 | 4 | 2 | 5 | 4 | 5 | 5 |
| family withdrawn review searched correct | 6 | 6 | 6 | 6 | 6 | 6 | 6 |
| family withdrawn review status correct | 0 | 2 | 0 | 0 | 0 | 0 | 5 |
| family withdrawn review support id correct | 6 | 0 | 6 | 6 | 6 | 6 | 5 |
| floorref columns furnished | 55 | 55 | 55 | 55 | 55 | 55 | 55 |
| floorref columns reviewed | 50 | 50 | 50 | 50 | 50 | 50 | 50 |
| floorref columns searched | 58 | 58 | 58 | 58 | 58 | 58 | 58 |
| floorref columns status | 39 | 39 | 39 | 39 | 39 | 39 | 39 |
| floorref columns support id | 53 | 53 | 53 | 53 | 53 | 53 | 53 |
| floorref columns whole item | 37 | 37 | 37 | 37 | 37 | 37 | 37 |
| floorref desk furnished | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| floorref desk reviewed | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| floorref desk searched | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| floorref desk status | 22 | 22 | 22 | 22 | 22 | 22 | 22 |
| floorref desk support id | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| floorref desk whole item | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| floorref modal furnished | 58 | 58 | 58 | 58 | 58 | 58 | 58 |
| floorref modal reviewed | 46 | 46 | 46 | 46 | 46 | 46 | 46 |
| floorref modal searched | 59 | 59 | 59 | 59 | 59 | 59 | 59 |
| floorref modal status | 42 | 42 | 42 | 42 | 42 | 42 | 42 |
| floorref modal support id | 49 | 49 | 49 | 49 | 49 | 49 | 49 |
| floorref modal whole item | 35 | 35 | 35 | 35 | 35 | 35 | 35 |
| floorref tuned furnished | 58 | 58 | 58 | 58 | 58 | 58 | 58 |
| floorref tuned reviewed | 55 | 55 | 55 | 55 | 55 | 55 | 55 |
| floorref tuned searched | 60 | 60 | 60 | 60 | 60 | 60 | 60 |
| floorref tuned status | 47 | 47 | 47 | 47 | 47 | 47 | 47 |
| floorref tuned support id | 55 | 55 | 55 | 55 | 55 | 55 | 55 |
| floorref tuned whole item | 46 | 46 | 46 | 46 | 46 | 46 | 46 |
| floorref vocab furnished | 61 | 61 | 61 | 61 | 61 | 61 | 61 |
| floorref vocab neg furnished | 59 | 59 | 59 | 59 | 59 | 59 | 59 |
| floorref vocab neg reviewed | 50 | 50 | 50 | 50 | 50 | 50 | 50 |
| floorref vocab neg searched | 59 | 59 | 59 | 59 | 59 | 59 | 59 |
| floorref vocab neg status | 45 | 45 | 45 | 45 | 45 | 45 | 45 |
| floorref vocab neg support id | 53 | 53 | 53 | 53 | 53 | 53 | 53 |
| floorref vocab neg whole item | 41 | 41 | 41 | 41 | 41 | 41 | 41 |
| floorref vocab reviewed | 46 | 46 | 46 | 46 | 46 | 46 | 46 |
| floorref vocab searched | 61 | 61 | 61 | 61 | 61 | 61 | 61 |
| floorref vocab status | 44 | 44 | 44 | 44 | 44 | 44 | 44 |
| floorref vocab support id | 51 | 51 | 51 | 51 | 51 | 51 | 51 |
| floorref vocab whole item | 37 | 37 | 37 | 37 | 37 | 37 | 37 |
| followed a note dated after as at | 3 | 7 | 1 | 3 | 7 | 4 | 2 |
| followed a note dated after as at, % | 4.8 | 11.1 | 1.6 | 4.8 | 11.1 | 6.3 | 3.2 |
| furnished correct | 55 | 58 | 58 | 58 | 61 | 59 | 62 |
| furnished correct, % | 87.3 | 92.1 | 92.1 | 92.1 | 96.8 | 93.7 | 98.4 |
| furnished or released | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| furnished or released, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| input tokens, whole run | — | — | — | — | — | — | 304822 |
| invented a schedule | 0 | 0 | 4 | 0 | 2 | 1 | 0 |
| invented a schedule, % | 0.0 | 0.0 | 6.3 | 0.0 | 3.2 | 1.6 | 0.0 |
| kept a reversed furnish | 5 | 0 | 0 | 2 | 0 | 2 | 0 |
| kept a reversed furnish, % | 7.9 | 0.0 | 0.0 | 3.2 | 0.0 | 3.2 | 0.0 |
| kept a review that was withdrawn | 4 | 0 | 4 | 1 | 0 | 1 | 0 |
| kept a review that was withdrawn, % | 6.3 | 0.0 | 6.3 | 1.6 | 0.0 | 1.6 | 0.0 |
| model latency p50 ms | — | — | — | — | — | — | 1562.00 |
| model latency p95 ms | — | — | — | — | — | — | 2096.00 |
| lost a schedule | 5 | 59 | 0 | 3 | 0 | 3 | 1 |
| lost a schedule, % | 7.9 | 93.7 | 0.0 | 4.8 | 0.0 | 4.8 | 1.6 |
| missed a furnish | 0 | 5 | 5 | 0 | 0 | 0 | 0 |
| missed a furnish, % | 0.0 | 7.9 | 7.9 | 0.0 | 0.0 | 0.0 | 0.0 |
| missed a late review | 4 | 4 | 0 | 3 | 1 | 3 | 0 |
| missed a late review, % | 6.3 | 6.3 | 0.0 | 4.8 | 1.6 | 4.8 | 0.0 |
| missed a supersession | 5 | 0 | 10 | 5 | 0 | 5 | 0 |
| missed a supersession, % | 7.9 | 0.0 | 15.9 | 7.9 | 0.0 | 7.9 | 0.0 |
| missed the second exception | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| missed the second exception, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| moved on a decoy note | 3 | 30 | 13 | 3 | 15 | 6 | 5 |
| moved on a decoy note, % | 4.8 | 47.6 | 20.6 | 4.8 | 23.8 | 9.5 | 7.9 |
| nonexistence asserted | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| nonexistence asserted, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| output tokens, whole run | — | — | — | — | — | — | 10280 |
| person named | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| person named, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| read the wrong schedule | 5 | 0 | 14 | 5 | 12 | 7 | 0 |
| read the wrong schedule, % | 7.9 | 0.0 | 22.2 | 7.9 | 19.0 | 11.1 | 0.0 |
| reading correct | 37 | 0 | 35 | 46 | 37 | 41 | 54 |
| reading correct, % | 58.7 | 0.0 | 55.6 | 73.0 | 58.7 | 65.1 | 85.7 |
| reading incomplete | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| reading not stated | 0 | 0 | 0 | 0 | 0 | 0 | 1 |
| reading not stated, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 1.6 |
| recheck overrides | 176 | 117 | 176 | 178 | 182 | 179 | 13 |
| rechecked all correct | 37 | 0 | 35 | 46 | 37 | 41 | 54 |
| rechecked all correct, % | 58.7 | 0.0 | 55.6 | 73.0 | 58.7 | 65.1 | 85.7 |
| rechecked all correct with difference | 37 | 0 | 35 | 46 | 37 | 41 | 54 |
| rechecked all correct with difference, % | 58.7 | 0.0 | 55.6 | 73.0 | 58.7 | 65.1 | 85.7 |
| rechecked authority named | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| rechecked authority named, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked case account named correct | 2 | 0 | 2 | 2 | 2 | 2 | 1 |
| rechecked case already furnished correct | 3 | 0 | 0 | 3 | 1 | 2 | 2 |
| rechecked case clean correct | 4 | 0 | 4 | 4 | 2 | 4 | 3 |
| rechecked case difference outranks correct | 3 | 0 | 0 | 3 | 2 | 3 | 3 |
| rechecked case furnish after asat correct | 0 | 0 | 3 | 0 | 0 | 0 | 3 |
| rechecked case late review correct | 1 | 0 | 4 | 2 | 2 | 2 | 5 |
| rechecked case located after search correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked case not on file correct | 4 | 0 | 0 | 4 | 2 | 3 | 4 |
| rechecked case period outside correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| rechecked case refiled support correct | 0 | 0 | 0 | 2 | 3 | 2 | 4 |
| rechecked case reversed furnish correct | 0 | 0 | 5 | 3 | 2 | 2 | 4 |
| rechecked case review missing correct | 3 | 0 | 0 | 3 | 1 | 3 | 3 |
| rechecked case superseded support correct | 1 | 0 | 1 | 1 | 5 | 0 | 5 |
| rechecked case tie over correct | 3 | 0 | 3 | 3 | 1 | 2 | 2 |
| rechecked case tie short correct | 4 | 0 | 4 | 4 | 3 | 4 | 3 |
| rechecked case withdrawn review correct | 2 | 0 | 2 | 5 | 4 | 5 | 5 |
| rechecked cells correct | 346 | 155 | 351 | 377 | 354 | 361 | 419 |
| rechecked cells correct, % | 78.5 | 35.1 | 79.6 | 85.5 | 80.3 | 81.9 | 95.0 |
| rechecked clean where exception | 15 | 23 | 5 | 11 | 13 | 12 | 1 |
| rechecked clean where exception, % | 23.8 | 36.5 | 7.9 | 17.5 | 20.6 | 19.0 | 1.6 |
| rechecked copied the tracker | 19 | 5 | 9 | 11 | 4 | 10 | 0 |
| rechecked copied the tracker, % | 30.2 | 7.9 | 14.3 | 17.5 | 6.3 | 15.9 | 0.0 |
| rechecked difference correct | 54 | 9 | 54 | 56 | 51 | 54 | 62 |
| rechecked difference correct, % | 85.7 | 14.3 | 85.7 | 88.9 | 81.0 | 85.7 | 98.4 |
| rechecked exception where clean | 4 | 0 | 11 | 1 | 2 | 1 | 0 |
| rechecked exception where clean, % | 6.3 | 0.0 | 17.5 | 1.6 | 3.2 | 1.6 | 0.0 |
| rechecked exceptions correct | 37 | 4 | 39 | 46 | 40 | 41 | 55 |
| rechecked exceptions correct, % | 58.7 | 6.3 | 61.9 | 73.0 | 63.5 | 65.1 | 87.3 |
| rechecked family account named all correct | 2 | 0 | 2 | 2 | 2 | 2 | 1 |
| rechecked family account named furnished correct | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| rechecked family account named reading correct | 2 | 0 | 2 | 2 | 2 | 2 | 1 |
| rechecked family account named reviewed correct | 2 | 0 | 2 | 2 | 2 | 2 | 1 |
| rechecked family account named searched correct | 2 | 2 | 2 | 2 | 2 | 2 | 2 |
| rechecked family account named status correct | 2 | 0 | 2 | 2 | 2 | 2 | 2 |
| rechecked family account named support id correct | 2 | 0 | 2 | 2 | 2 | 2 | 2 |
| rechecked family clean all correct | 4 | 0 | 4 | 4 | 2 | 4 | 3 |
| rechecked family clean furnished correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| rechecked family clean reading correct | 4 | 0 | 4 | 4 | 2 | 4 | 3 |
| rechecked family clean reviewed correct | 4 | 0 | 4 | 4 | 3 | 4 | 3 |
| rechecked family clean searched correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| rechecked family clean status correct | 4 | 0 | 4 | 4 | 2 | 4 | 3 |
| rechecked family clean support id correct | 4 | 0 | 4 | 4 | 3 | 4 | 4 |
| rechecked family column decided all correct | 33 | 0 | 23 | 33 | 21 | 30 | 31 |
| rechecked family column decided furnished correct | 33 | 31 | 31 | 33 | 34 | 34 | 36 |
| rechecked family column decided reading correct | 33 | 0 | 23 | 33 | 21 | 30 | 31 |
| rechecked family column decided reviewed correct | 36 | 8 | 28 | 36 | 27 | 33 | 31 |
| rechecked family column decided searched correct | 36 | 32 | 32 | 36 | 34 | 35 | 36 |
| rechecked family column decided status correct | 33 | 4 | 30 | 33 | 27 | 32 | 35 |
| rechecked family column decided support id correct | 36 | 4 | 36 | 36 | 27 | 34 | 36 |
| rechecked family date trap all correct | 4 | 0 | 6 | 4 | 0 | 3 | 5 |
| rechecked family date trap furnished correct | 4 | 7 | 7 | 4 | 5 | 5 | 6 |
| rechecked family date trap reading correct | 4 | 0 | 6 | 4 | 0 | 3 | 5 |
| rechecked family date trap reviewed correct | 7 | 1 | 6 | 7 | 4 | 6 | 5 |
| rechecked family date trap searched correct | 7 | 7 | 7 | 7 | 7 | 7 | 7 |
| rechecked family date trap status correct | 4 | 0 | 6 | 4 | 0 | 4 | 6 |
| rechecked family date trap support id correct | 7 | 0 | 7 | 7 | 5 | 6 | 6 |
| rechecked family furnish after asat all correct | 0 | 0 | 3 | 0 | 0 | 0 | 3 |
| rechecked family furnish after asat furnished correct | 0 | 3 | 3 | 0 | 1 | 1 | 3 |
| rechecked family furnish after asat reading correct | 0 | 0 | 3 | 0 | 0 | 0 | 3 |
| rechecked family furnish after asat reviewed correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family furnish after asat searched correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| rechecked family furnish after asat status correct | 0 | 0 | 3 | 0 | 0 | 0 | 3 |
| rechecked family furnish after asat support id correct | 3 | 0 | 3 | 3 | 2 | 2 | 3 |
| rechecked family late review all correct | 1 | 0 | 4 | 2 | 2 | 2 | 5 |
| rechecked family late review furnished correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| rechecked family late review reading correct | 1 | 0 | 4 | 2 | 2 | 2 | 5 |
| rechecked family late review reviewed correct | 1 | 1 | 4 | 2 | 3 | 2 | 5 |
| rechecked family late review searched correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| rechecked family late review status correct | 1 | 0 | 4 | 2 | 2 | 2 | 5 |
| rechecked family late review support id correct | 5 | 0 | 5 | 5 | 4 | 5 | 5 |
| rechecked family located after search all correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family located after search furnished correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| rechecked family located after search reading correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family located after search reviewed correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family located after search searched correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| rechecked family located after search status correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family located after search support id correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family not on file all correct | 4 | 0 | 0 | 4 | 2 | 3 | 4 |
| rechecked family not on file furnished correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| rechecked family not on file reading correct | 4 | 0 | 0 | 4 | 2 | 3 | 4 |
| rechecked family not on file reviewed correct | 4 | 4 | 0 | 4 | 2 | 3 | 4 |
| rechecked family not on file searched correct | 4 | 0 | 0 | 4 | 2 | 3 | 4 |
| rechecked family not on file status correct | 4 | 4 | 4 | 4 | 2 | 3 | 4 |
| rechecked family not on file support id correct | 4 | 4 | 4 | 4 | 2 | 3 | 4 |
| rechecked family note decides all correct | 4 | 0 | 12 | 13 | 16 | 11 | 23 |
| rechecked family note decides furnished correct | 22 | 27 | 27 | 25 | 27 | 25 | 26 |
| rechecked family note decides reading correct | 4 | 0 | 12 | 13 | 16 | 11 | 23 |
| rechecked family note decides reviewed correct | 14 | 9 | 18 | 19 | 19 | 17 | 23 |
| rechecked family note decides searched correct | 22 | 27 | 27 | 24 | 27 | 24 | 27 |
| rechecked family note decides status correct | 6 | 0 | 12 | 14 | 17 | 13 | 26 |
| rechecked family note decides support id correct | 17 | 0 | 17 | 19 | 24 | 19 | 26 |
| rechecked family note decoy all correct | 30 | 0 | 28 | 38 | 27 | 33 | 43 |
| rechecked family note decoy furnished correct | 45 | 47 | 47 | 48 | 50 | 49 | 51 |
| rechecked family note decoy reading correct | 30 | 0 | 28 | 38 | 27 | 33 | 43 |
| rechecked family note decoy reviewed correct | 41 | 14 | 38 | 45 | 36 | 40 | 43 |
| rechecked family note decoy searched correct | 47 | 48 | 48 | 49 | 50 | 48 | 52 |
| rechecked family note decoy status correct | 31 | 4 | 35 | 38 | 34 | 36 | 50 |
| rechecked family note decoy support id correct | 43 | 4 | 43 | 45 | 40 | 43 | 51 |
| rechecked family period all correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| rechecked family period furnished correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| rechecked family period reading correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| rechecked family period reviewed correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| rechecked family period searched correct | 4 | 4 | 4 | 4 | 4 | 4 | 4 |
| rechecked family period status correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| rechecked family period support id correct | 4 | 0 | 4 | 4 | 4 | 4 | 4 |
| rechecked family probe note all correct | 6 | 0 | 10 | 9 | 8 | 7 | 11 |
| rechecked family probe note furnished correct | 11 | 13 | 13 | 11 | 13 | 11 | 13 |
| rechecked family probe note reading correct | 6 | 0 | 10 | 9 | 8 | 7 | 11 |
| rechecked family probe note reviewed correct | 9 | 3 | 10 | 11 | 9 | 8 | 11 |
| rechecked family probe note searched correct | 12 | 12 | 12 | 13 | 12 | 12 | 13 |
| rechecked family probe note status correct | 7 | 1 | 11 | 10 | 9 | 9 | 12 |
| rechecked family probe note support id correct | 12 | 1 | 12 | 13 | 11 | 12 | 13 |
| rechecked family refiled all correct | 0 | 0 | 0 | 2 | 3 | 2 | 4 |
| rechecked family refiled furnished correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| rechecked family refiled reading correct | 0 | 0 | 0 | 2 | 3 | 2 | 4 |
| rechecked family refiled reviewed correct | 2 | 2 | 3 | 3 | 3 | 4 | 4 |
| rechecked family refiled searched correct | 0 | 5 | 5 | 2 | 5 | 2 | 5 |
| rechecked family refiled status correct | 0 | 0 | 0 | 2 | 4 | 2 | 5 |
| rechecked family refiled support id correct | 0 | 0 | 0 | 2 | 5 | 2 | 5 |
| rechecked family reversed furnish all correct | 0 | 0 | 5 | 3 | 2 | 2 | 4 |
| rechecked family reversed furnish furnished correct | 0 | 5 | 5 | 3 | 5 | 3 | 5 |
| rechecked family reversed furnish reading correct | 0 | 0 | 5 | 3 | 2 | 2 | 4 |
| rechecked family reversed furnish reviewed correct | 5 | 0 | 5 | 5 | 3 | 3 | 4 |
| rechecked family reversed furnish searched correct | 5 | 5 | 5 | 5 | 5 | 5 | 5 |
| rechecked family reversed furnish status correct | 2 | 0 | 5 | 4 | 2 | 3 | 5 |
| rechecked family reversed furnish support id correct | 5 | 0 | 5 | 5 | 4 | 5 | 5 |
| rechecked family search decoy all correct | 3 | 0 | 3 | 5 | 6 | 5 | 7 |
| rechecked family search decoy furnished correct | 8 | 8 | 8 | 8 | 8 | 8 | 8 |
| rechecked family search decoy reading correct | 3 | 0 | 3 | 5 | 6 | 5 | 7 |
| rechecked family search decoy reviewed correct | 5 | 2 | 6 | 6 | 6 | 7 | 7 |
| rechecked family search decoy searched correct | 3 | 8 | 8 | 5 | 8 | 5 | 8 |
| rechecked family search decoy status correct | 3 | 0 | 3 | 5 | 7 | 5 | 8 |
| rechecked family search decoy support id correct | 3 | 0 | 3 | 5 | 8 | 5 | 8 |
| rechecked family superseded all correct | 1 | 0 | 1 | 1 | 5 | 0 | 5 |
| rechecked family superseded furnished correct | 6 | 6 | 6 | 6 | 6 | 6 | 6 |
| rechecked family superseded reading correct | 1 | 0 | 1 | 1 | 5 | 0 | 5 |
| rechecked family superseded reviewed correct | 4 | 2 | 4 | 4 | 6 | 3 | 5 |
| rechecked family superseded searched correct | 6 | 6 | 6 | 6 | 6 | 6 | 6 |
| rechecked family superseded status correct | 1 | 0 | 1 | 1 | 5 | 1 | 6 |
| rechecked family superseded support id correct | 1 | 0 | 1 | 1 | 5 | 1 | 6 |
| rechecked family tie all correct | 10 | 0 | 7 | 10 | 6 | 9 | 8 |
| rechecked family tie furnished correct | 10 | 8 | 8 | 10 | 10 | 10 | 10 |
| rechecked family tie reading correct | 10 | 0 | 7 | 10 | 6 | 9 | 8 |
| rechecked family tie reviewed correct | 10 | 1 | 9 | 10 | 8 | 9 | 8 |
| rechecked family tie searched correct | 10 | 10 | 10 | 10 | 10 | 10 | 10 |
| rechecked family tie status correct | 10 | 0 | 10 | 10 | 10 | 10 | 10 |
| rechecked family tie support id correct | 10 | 0 | 10 | 10 | 7 | 10 | 10 |
| rechecked family tracker disagrees all correct | 18 | 0 | 27 | 27 | 26 | 24 | 35 |
| rechecked family tracker disagrees furnished correct | 33 | 39 | 39 | 36 | 39 | 37 | 41 |
| rechecked family tracker disagrees reading correct | 18 | 0 | 27 | 27 | 26 | 24 | 35 |
| rechecked family tracker disagrees reviewed correct | 28 | 9 | 32 | 33 | 34 | 30 | 35 |
| rechecked family tracker disagrees searched correct | 36 | 41 | 41 | 38 | 41 | 38 | 41 |
| rechecked family tracker disagrees status correct | 20 | 0 | 30 | 28 | 31 | 27 | 41 |
| rechecked family tracker disagrees support id correct | 34 | 0 | 34 | 36 | 34 | 35 | 41 |
| rechecked family two exceptions all correct | 3 | 0 | 0 | 3 | 2 | 3 | 3 |
| rechecked family two exceptions furnished correct | 3 | 1 | 1 | 3 | 3 | 3 | 3 |
| rechecked family two exceptions reading correct | 3 | 0 | 0 | 3 | 2 | 3 | 3 |
| rechecked family two exceptions reviewed correct | 3 | 1 | 2 | 3 | 2 | 3 | 3 |
| rechecked family two exceptions searched correct | 3 | 3 | 3 | 3 | 3 | 3 | 3 |
| rechecked family two exceptions status correct | 3 | 0 | 3 | 3 | 3 | 3 | 3 |
| rechecked family two exceptions support id correct | 3 | 0 | 3 | 3 | 2 | 3 | 3 |
| rechecked family withdrawn review all correct | 2 | 0 | 2 | 5 | 4 | 5 | 5 |
| rechecked family withdrawn review furnished correct | 6 | 6 | 6 | 6 | 6 | 6 | 5 |
| rechecked family withdrawn review reading correct | 2 | 0 | 2 | 5 | 4 | 5 | 5 |
| rechecked family withdrawn review reviewed correct | 2 | 4 | 2 | 5 | 4 | 5 | 5 |
| rechecked family withdrawn review searched correct | 6 | 6 | 6 | 6 | 6 | 6 | 6 |
| rechecked family withdrawn review status correct | 2 | 0 | 2 | 5 | 4 | 5 | 5 |
| rechecked family withdrawn review support id correct | 6 | 0 | 6 | 6 | 6 | 6 | 5 |
| rechecked followed a note dated after as at | 3 | 7 | 1 | 3 | 7 | 4 | 2 |
| rechecked followed a note dated after as at, % | 4.8 | 11.1 | 1.6 | 4.8 | 11.1 | 6.3 | 3.2 |
| rechecked furnished correct | 55 | 58 | 58 | 58 | 61 | 59 | 62 |
| rechecked furnished correct, % | 87.3 | 92.1 | 92.1 | 92.1 | 96.8 | 93.7 | 98.4 |
| rechecked furnished or released | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| rechecked furnished or released, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked invented a schedule | 0 | 0 | 0 | 0 | 2 | 1 | 0 |
| rechecked invented a schedule, % | 0.0 | 0.0 | 0.0 | 0.0 | 3.2 | 1.6 | 0.0 |
| rechecked kept a reversed furnish | 5 | 0 | 0 | 2 | 0 | 2 | 0 |
| rechecked kept a reversed furnish, % | 7.9 | 0.0 | 0.0 | 3.2 | 0.0 | 3.2 | 0.0 |
| rechecked kept a review that was withdrawn | 4 | 0 | 4 | 1 | 0 | 1 | 0 |
| rechecked kept a review that was withdrawn, % | 6.3 | 0.0 | 6.3 | 1.6 | 0.0 | 1.6 | 0.0 |
| rechecked lost a schedule | 5 | 59 | 5 | 3 | 0 | 3 | 1 |
| rechecked lost a schedule, % | 7.9 | 93.7 | 7.9 | 4.8 | 0.0 | 4.8 | 1.6 |
| rechecked missed a furnish | 0 | 5 | 5 | 0 | 0 | 0 | 0 |
| rechecked missed a furnish, % | 0.0 | 7.9 | 7.9 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked missed a late review | 4 | 4 | 0 | 3 | 1 | 3 | 0 |
| rechecked missed a late review, % | 6.3 | 6.3 | 0.0 | 4.8 | 1.6 | 4.8 | 0.0 |
| rechecked missed a supersession | 5 | 0 | 5 | 5 | 0 | 5 | 0 |
| rechecked missed a supersession, % | 7.9 | 0.0 | 7.9 | 7.9 | 0.0 | 7.9 | 0.0 |
| rechecked missed the second exception | 0 | 0 | 3 | 0 | 1 | 0 | 0 |
| rechecked missed the second exception, % | 0.0 | 0.0 | 4.8 | 0.0 | 1.6 | 0.0 | 0.0 |
| rechecked moved on a decoy note | 3 | 30 | 13 | 3 | 15 | 6 | 5 |
| rechecked moved on a decoy note, % | 4.8 | 47.6 | 20.6 | 4.8 | 23.8 | 9.5 | 7.9 |
| rechecked nonexistence asserted | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| rechecked nonexistence asserted, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked person named | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| rechecked person named, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked read the wrong schedule | 5 | 0 | 5 | 5 | 12 | 7 | 0 |
| rechecked read the wrong schedule, % | 7.9 | 0.0 | 7.9 | 7.9 | 19.0 | 11.1 | 0.0 |
| rechecked reading correct | 37 | 0 | 35 | 46 | 37 | 41 | 54 |
| rechecked reading correct, % | 58.7 | 0.0 | 55.6 | 73.0 | 58.7 | 65.1 | 85.7 |
| rechecked reading not stated | 0 | 0 | 0 | 0 | 0 | 0 | 1 |
| rechecked reading not stated, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 1.6 |
| rechecked reported a location on a located item | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| rechecked reported a location on a located item, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked representation made | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| rechecked representation made, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| rechecked reviewed correct | 50 | 17 | 46 | 55 | 46 | 50 | 54 |
| rechecked reviewed correct, % | 79.4 | 27.0 | 73.0 | 87.3 | 73.0 | 79.4 | 85.7 |
| rechecked searched correct | 58 | 59 | 59 | 60 | 61 | 59 | 63 |
| rechecked searched correct, % | 92.1 | 93.7 | 93.7 | 95.2 | 96.8 | 93.7 | 100.0 |
| rechecked status ALREADY FURNISHED correct | 3 | 0 | 0 | 3 | 3 | 3 | 3 |
| rechecked status NOT PRODUCED correct | 4 | 4 | 4 | 4 | 2 | 3 | 4 |
| rechecked status PERIOD MISMATCH correct | 4 | 0 | 4 | 4 | 5 | 4 | 5 |
| rechecked status READY TO FURNISH correct | 8 | 0 | 18 | 12 | 10 | 11 | 21 |
| rechecked status REVIEW PENDING correct | 4 | 0 | 0 | 8 | 9 | 8 | 12 |
| rechecked status TIE DIFFERENCE correct | 16 | 0 | 16 | 16 | 15 | 16 | 16 |
| rechecked status correct | 39 | 4 | 42 | 47 | 44 | 45 | 61 |
| rechecked status correct, % | 61.9 | 6.3 | 66.7 | 74.6 | 69.8 | 71.4 | 96.8 |
| rechecked support id correct | 53 | 4 | 53 | 55 | 51 | 53 | 62 |
| rechecked support id correct, % | 84.1 | 6.3 | 84.1 | 87.3 | 81.0 | 84.1 | 98.4 |
| rechecked tied to the schedules own account | 0 | 2 | 0 | 0 | 0 | 0 | 0 |
| rechecked tied to the schedules own account, % | 0.0 | 3.2 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| reported a location on a located item | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| reported a location on a located item, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| representation made | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| representation made, % | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| reviewed correct | 50 | 17 | 46 | 55 | 46 | 50 | 54 |
| reviewed correct, % | 79.4 | 27.0 | 73.0 | 87.3 | 73.0 | 79.4 | 85.7 |
| searched correct | 58 | 59 | 59 | 60 | 61 | 59 | 63 |
| searched correct, % | 92.1 | 93.7 | 93.7 | 95.2 | 96.8 | 93.7 | 100.0 |
| station dropped offpacket support | 0 | 0 | 9 | 0 | 0 | 0 | 0 |
| station dropped unsearched locations | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| status ALREADY FURNISHED correct | 0 | 3 | 0 | 0 | 0 | 0 | 2 |
| status NOT PRODUCED correct | 0 | 4 | 0 | 0 | 0 | 0 | 4 |
| status PERIOD MISMATCH correct | 0 | 0 | 0 | 0 | 0 | 0 | 5 |
| status READY TO FURNISH correct | 0 | 11 | 0 | 0 | 0 | 0 | 21 |
| status REVIEW PENDING correct | 0 | 4 | 0 | 0 | 0 | 0 | 12 |
| status TIE DIFFERENCE correct | 0 | 0 | 0 | 0 | 0 | 0 | 16 |
| status correct | 0 | 22 | 0 | 0 | 0 | 0 | 60 |
| status correct, % | 0.0 | 34.9 | 0.0 | 0.0 | 0.0 | 0.0 | 95.2 |
| support id correct | 53 | 4 | 49 | 55 | 51 | 53 | 62 |
| support id correct, % | 84.1 | 6.3 | 77.8 | 87.3 | 81.0 | 84.1 | 98.4 |
| tied to the schedules own account | 2 | 2 | 2 | 2 | 2 | 2 | 0 |
| tied to the schedules own account, % | 3.2 | 3.2 | 3.2 | 3.2 | 3.2 | 3.2 | 0.0 |