The business caseThe problem this solves
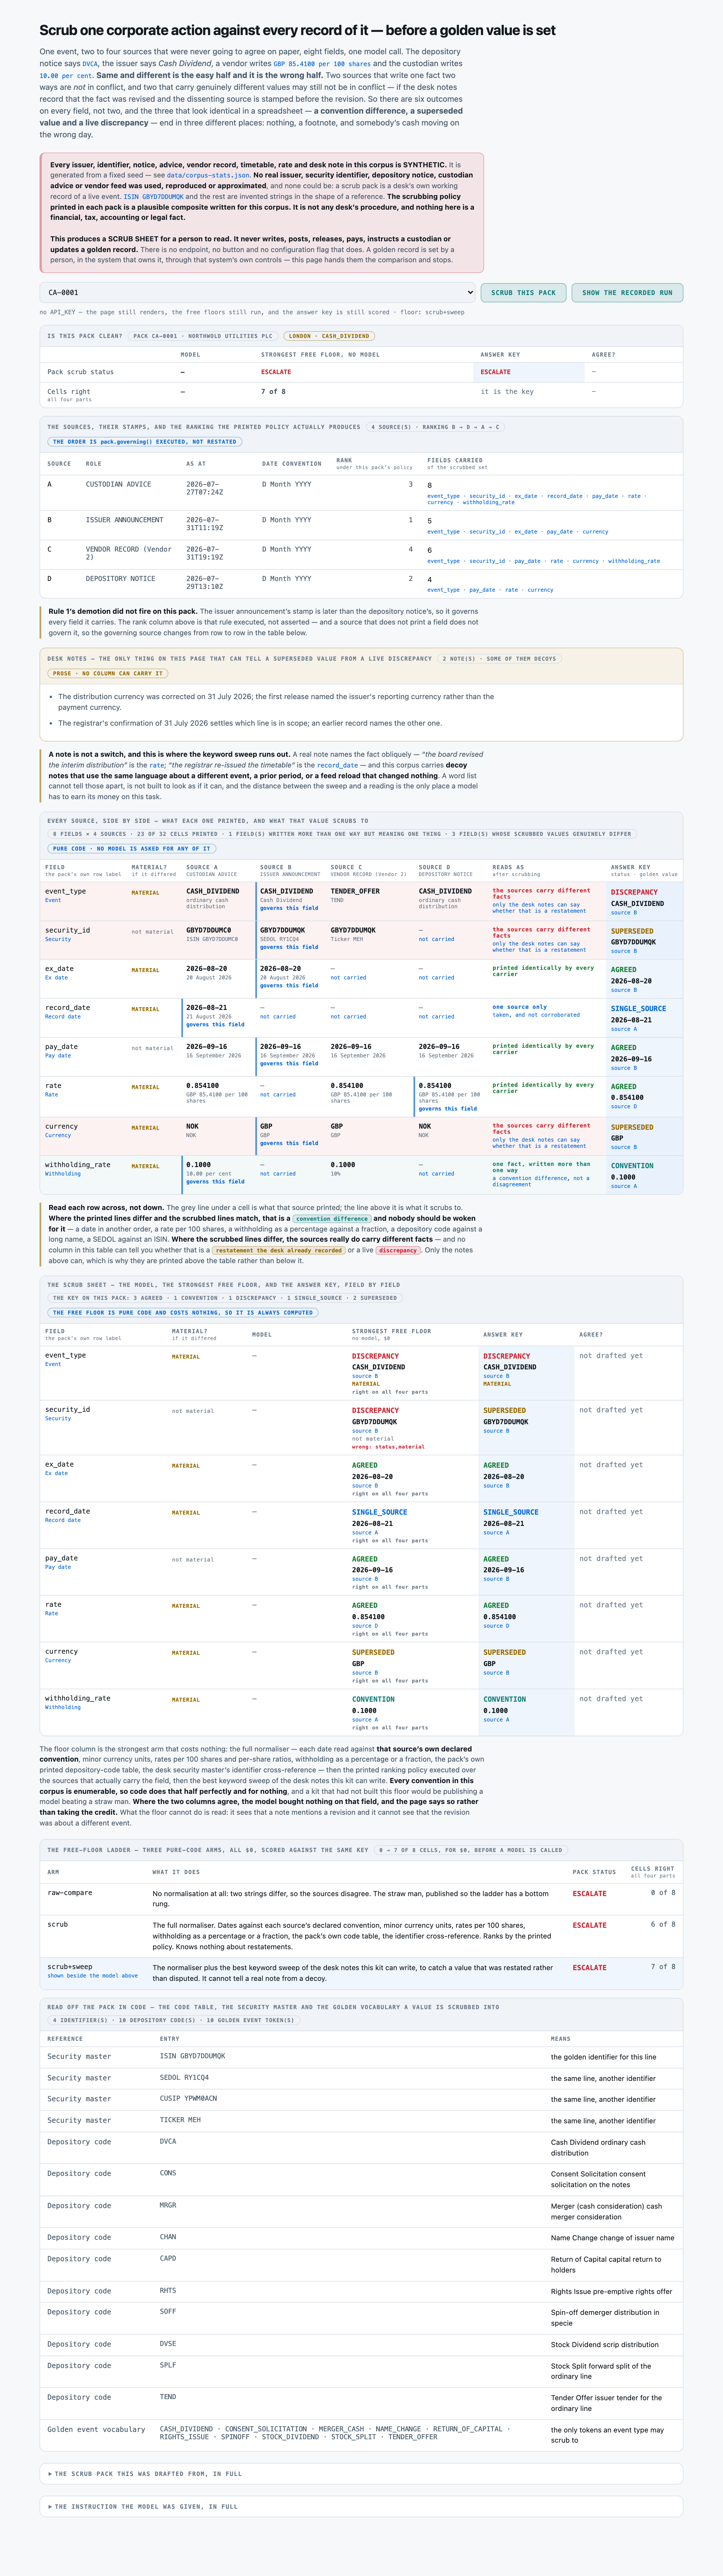
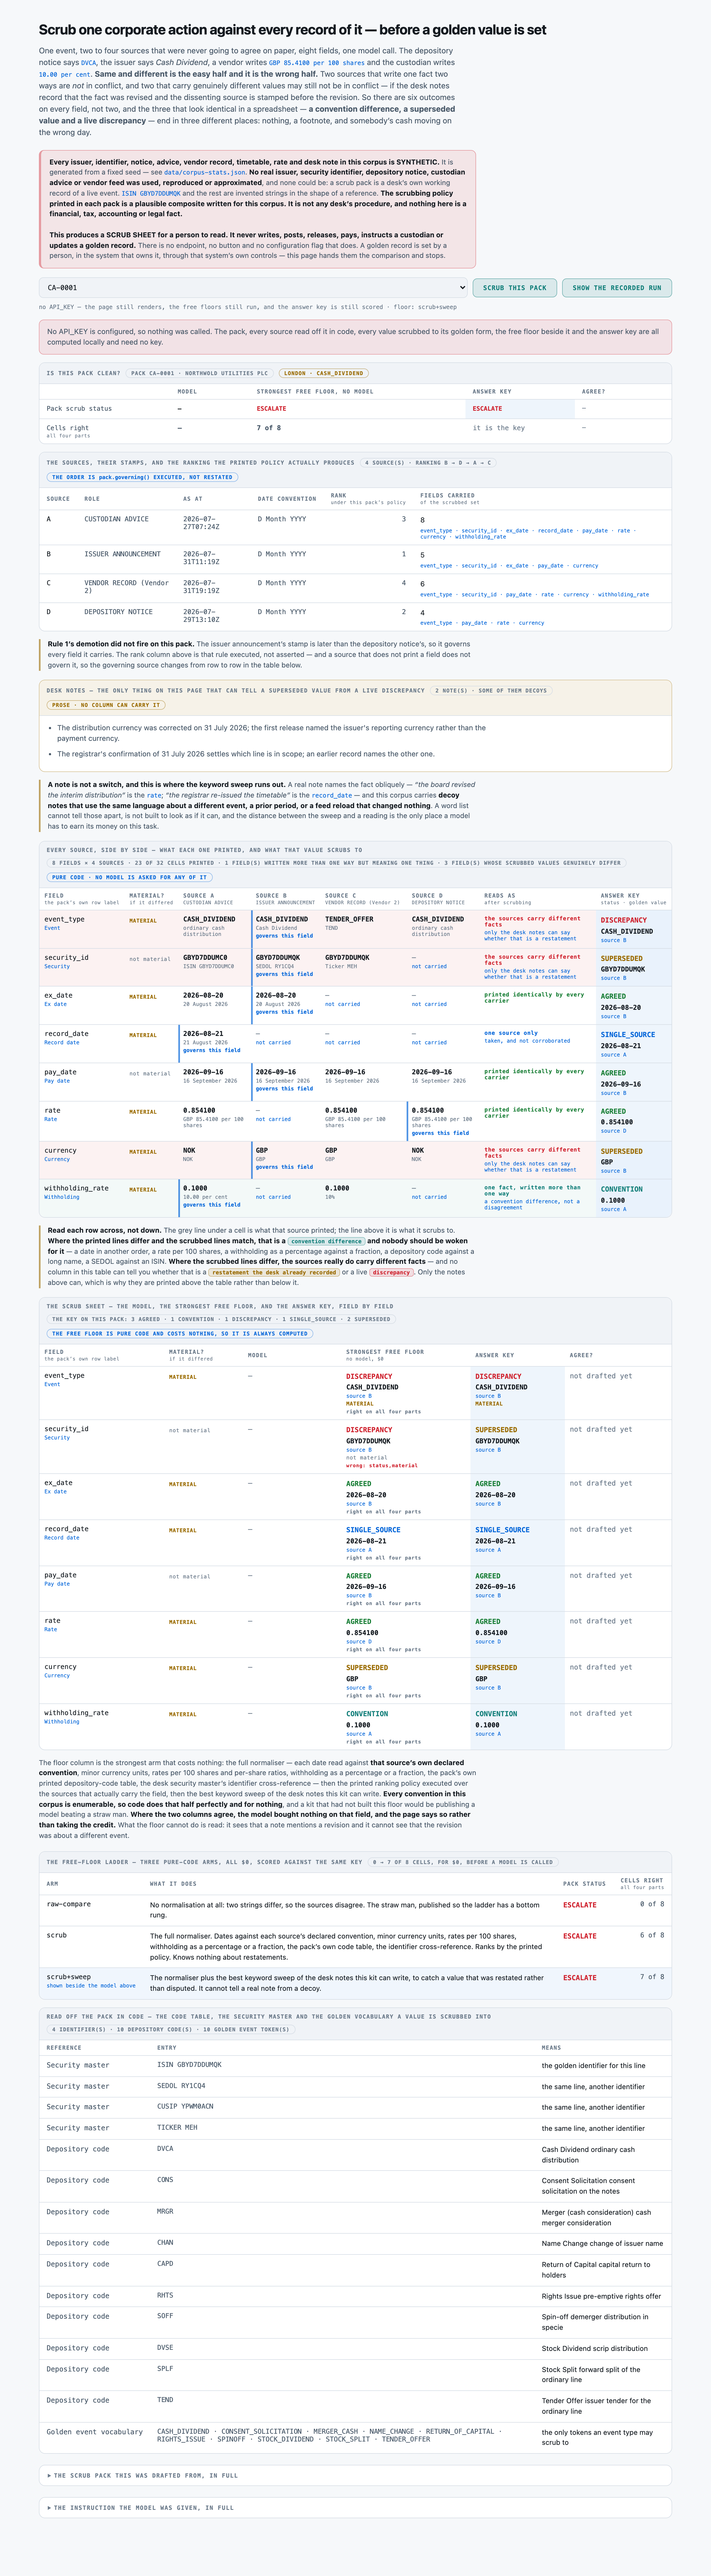
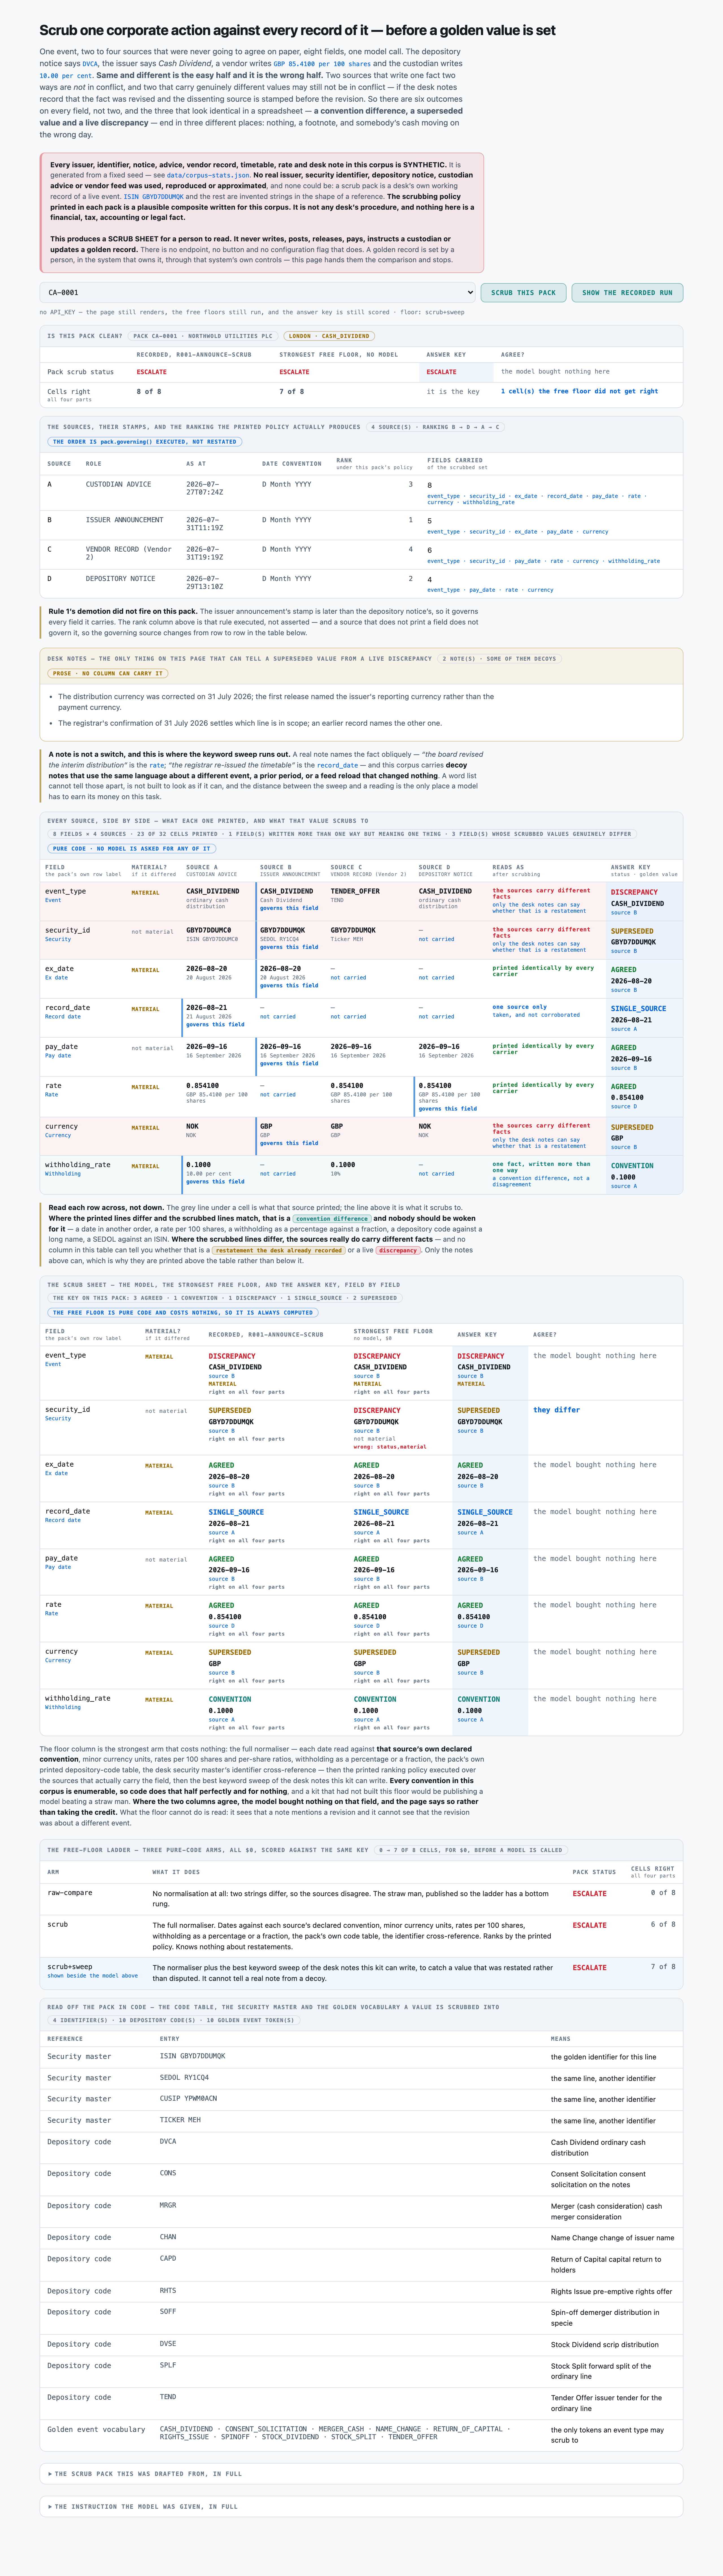
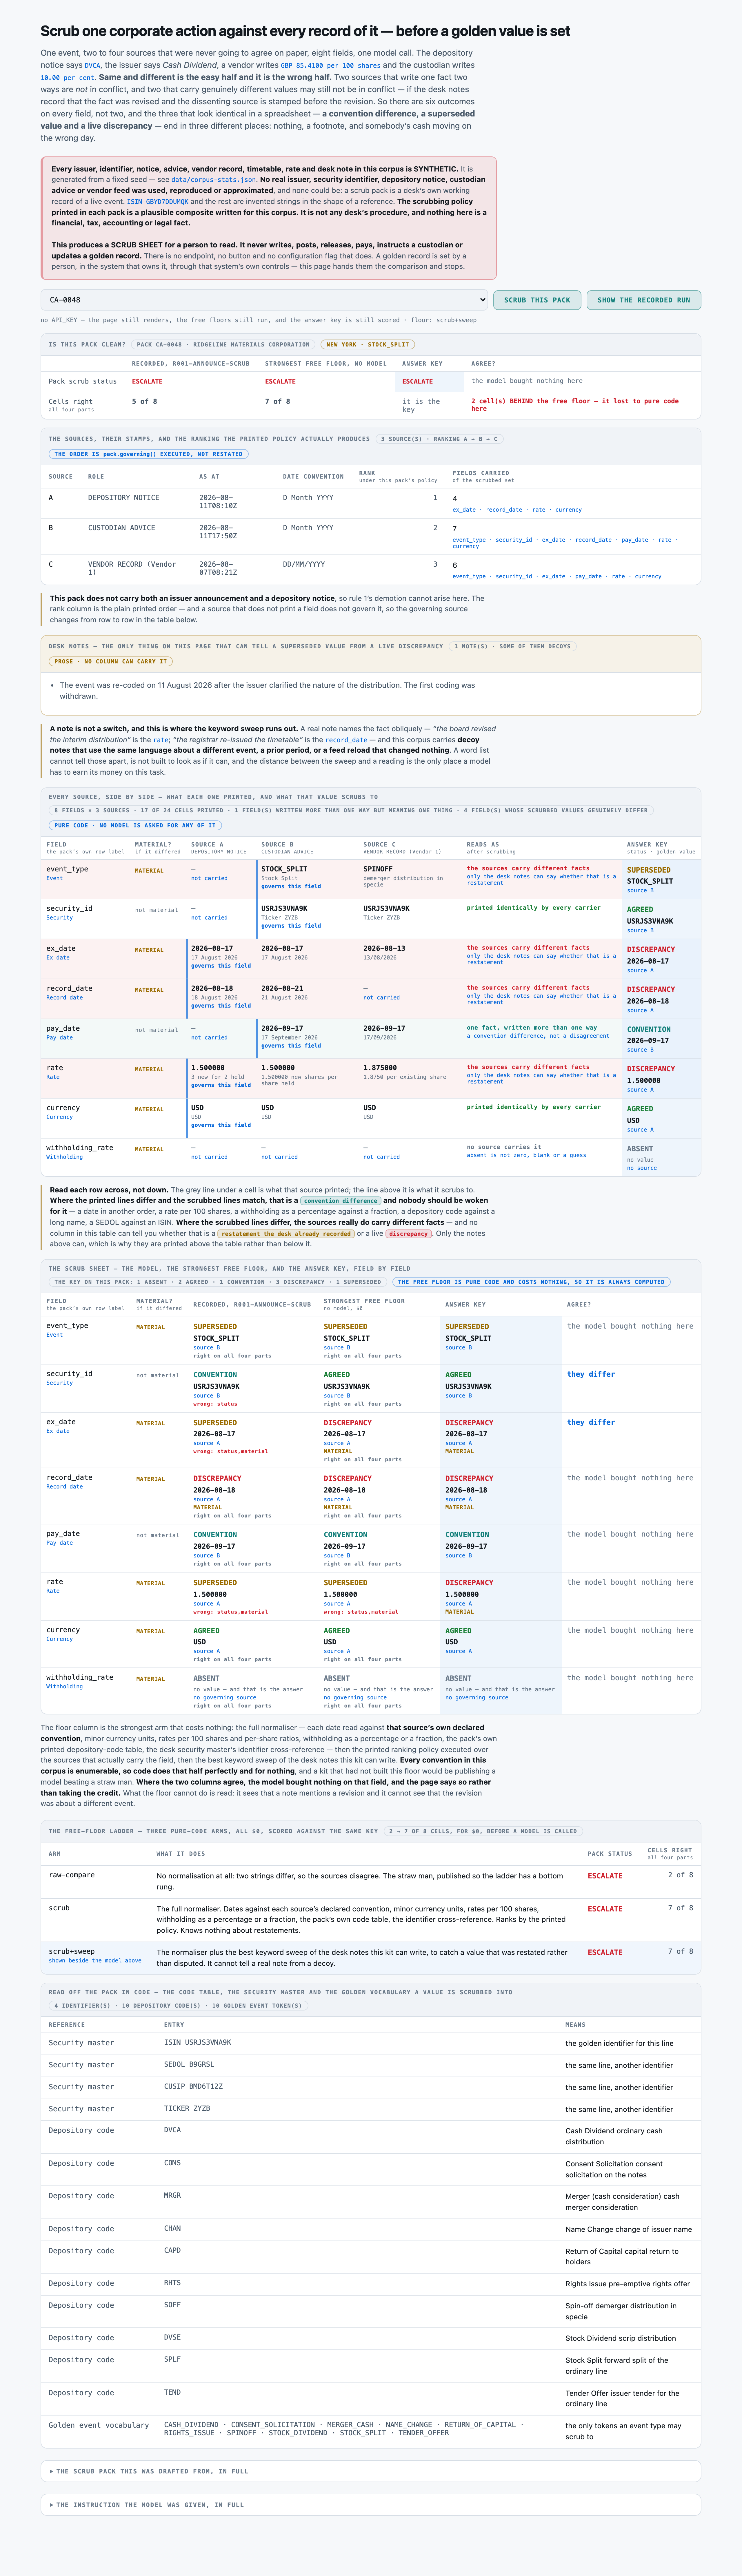
One corporate action reaches a wealth or asset manager several times over -- a depository notice, the issuer's own announcement, a custodian advice, one or two commercial data vendors -- and the records do not agree. Most of the disagreement is not disagreement at all: the same ex date written four ways, the same distribution quoted in minor currency units by one source and per 100 shares by another, the same line identified by ISIN here and by CUSIP there, the same event carrying a depository code in one feed and a sentence in the next. Underneath that noise sit the differences that actually move money, and a third category that looks exactly like them: a value one source carries because it was stamped before the issuer restated the fact. Scrubbing is deciding, field by field, which of those three a difference is, what the golden value therefore is, and which source the desk's own ranking policy says governs it. An operations analyst reading two to four records of one event side by side, normalising every convention by hand, and deciding which differences to escalate before the entitlement is struck.
Audience
Corporate actions operations staff on a wealth or asset management desk who scrub announcements into a golden record before entitlements are calculated, and the supervisors who sign off the escalations. Every number on these pages came from one real run of this code, not from a vendor page.
The inputThe actual scrub packs
The corpus is 50 scrub packs, 0.23 MB (txt 50). A scrub pack is, by construction, several commercial vendors' records of one event side by side. Publishing real ones would republish licensed feeds, so the choice was a generated corpus or no public corpus, and a kit with no re-runnable eval is a claim rather than a measurement. The generator writes the ANSWER KEY FIRST and renders the pack from it, so the text cannot drift from the key; evals/check_labels.py then walks back the other way and re-derives every derivable part of the key from the rendered packs alone. It convicted 18 disagreements on its first run -- a ranking rule that compared as-at DAYS in the generator and full TIMESTAMPS in the parser, a ratio renderer that turned 0.25 into '0 new for 2 held', and an event-token mapping that could not get from 'Spin-off' to SPINOFF -- every one of them before a single call was paid for.
The corpus
- The 50 scrub packsgenerated from a fixed seed, so no real record, person or institution appears in it.
- Where each came fromwritten for this kit rather than collected — the corpus is generated in the kit's own repository, so there is no third-party data in it.
Swap this folder for your own material and the kit is pointed at your scrub packs. That is the whole change — there is no database to migrate.
CORPORATE ACTION SCRUB PACK CA-0001
SYNTHETIC DATA. This pack was generated for a public evaluation corpus. The issuer, the
identifiers, the timetable, the rates and the sources are all invented. Nothing in it is
financial fact and none of it describes any real corporate action.

--- EVENT ---
Issuer            : Northwold Utilities plc
Primary listing   : London
Line              : ordinary shares

--- SCRUBBING POLICY IN FORCE ON THIS DESK ---
1  RANKING. Where the sources below disagree about a fact, the ISSUER ANNOUNCEMENT governs,
   UNLESS its "as at" stamp is EARLIER than the DEPOSITORY NOTICE's, in which case it ranks
   IMMEDIATELY BELOW the depository notice -- still above everything else. Below those two the
   order is CUSTODIAN ADVICE, then VENDOR RECORD (Vendor 1 before Vendor 2). A vendor record
   never governs while any other source carries the field. A source that does not carry the
   field does not govern it: rank only the sources that print it.
2  RENDERING IS NOT DISAGREEMENT. A date written another way, a rate quoted in minor currency
   units or per 100 shares, a withholding written as a percentage or as a fraction, an event
   named by its depository code rather than in words, or a different identifier for the same
   line, are the SAME fact. Scrub to the golden form and record it as a convention difference.
3  ONE SOURCE IS NOT AGREEMENT. Where exactly one source carries the field, take its value and
   say so. It has not been corroborated.
4  A RESTATEMENT IS NOT A DISAGREEMENT. Where the DESK NOTES record that a fact was revised,
   re-issued, re-coded, moved or corrected, a source stamped BEFORE that revision carrying the
   old value is superseded, not in conflict. Take the governing source's current value.
Abridged — the file continues.
The outcomeWhat a good result looks like
One scrub sheet per event: eight fields, each with a status, the scrubbed golden value in the desk's own golden form, the source the printed ranking policy says governs it, and -- on a genuine disagreement only -- whether it is material. Plus one pack-level call: clean, review, or escalate.
And when it cannot
The paid arm got 384 of 400 field cells completely right and lost 16. It did not invent a single value for a field no source printed, did not name a single source the pack does not have, and did not drop a row. Every one of the 16 losses was a LABEL, never a value -- value accuracy was 100.0 pct. Nine were AGREED called CONVENTION on cells where every source printed the identifier identically but in a form that still had to be scrubbed to the golden ISIN, and the pack's own printed rule 2 arguably instructs exactly what the model did. Five were currency, where three sources state the currency inside their rate line ('USD 0.423700 per share') and only one prints an explicit Currency row: the answer key counts only the explicit row and the model counted all four. Two were CA-0048, where a desk note says an event was re-coded and 'the first coding was withdrawn', and the model carried that withdrawal to the same stale source's ex date and rate while the key scopes it to the event type alone. All 16 are corpus ambiguities as much as model errors, and they are published diagnosed and UNFIXED -- nothing was re-fired and nothing was re-scored after the misses were read.
Where it fitsWhat did work
Every line below is a measured result from this kit's own runs, with the figure that supports it. The headline above is not softened by any of them.
- Your packs' conventions are enumerable and your desk notes are structured — The free floor. src/normal.py, no key, no bill.
95.75 pct of the cells on this corpus, at zero, with a perfect score on five of the six statuses. - Your desk notes are free prose and restatements arrive in them — The model, on the cells the scrubber cannot settle.
17 of 17 against the best free sweep's 7 of 17. That is the whole gap and it is real. - You need the pack-level escalate/review/clean call to be right — The model.
50 of 50 against the floors' 47 and 46. A single false SUPERSEDED downgrades a whole pack from ESCALATE, which is how a material difference reaches an entitlement.
And where nothing here is good enough:
- You want a number you can take to your own feeds — Neither. Re-run it on your own packs.
This corpus is synthetic, 19.25 pct of its cells are ABSENT and free to every arm, and its conventions were chosen.
At a glanceHow the whole thing runs
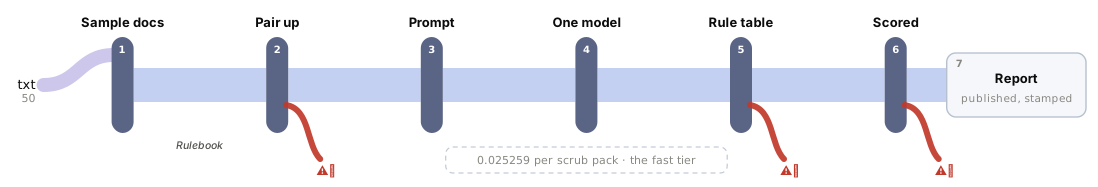
Run once, for real, on 2026-08-27. Every figure on these pages was captured from that run — nothing is written from intent.
14 steps, grouped by the question that sends you to them rather than by build order. Each tile carries the one figure that step is about, and opens the page behind it.
Should you use this?What you bring, where it stops, and when not to use it
Before you commit an afternoon to this, these are the answers that decide it. Each one is rendered from the record it lives in — and links the page that holds it in full.
| What do I have to bring? | tools/build_corpus.py writes data/corpus/*.txt and data/gold.jsonl. NONE OF THE MEASURED FIGURES ON THIS PAGE TRANSFER TO YOUR OWN PACKS. Corpus lens → |
| When is this the wrong choice? | Avoid: Paying for a call that on this evidence buys one cell in four hundred. That is the case against the best-fitting scenario (“Your packs' conventions are enumerable and your desk notes are structured”). 4 scenarios scored in all, each with its own. Eval lens → |
| Where does it stop working? | A date convention a source does not declare. Every pack declares one per source, and '12/11/2026' is two different days without it. 5 recorded failure modes, each from a run rather than a guess. Corpus lens → |
| What was never verified? | Repeatability. Every arm ran once. 6 items this kit says it could not check. Eval lens → |
| Can I run this on a model I control? | Yes — any OpenAI-compatible endpoint, including one on your own hardware. The shipped adapter takes its host from BASE_URL and its model from MODEL, so nothing in src/ changes. The published figures come from 1 model on the fast tier, one provider, one key. Prompt lens → |
| And if it fits — what do I stand up? | 4 artifacts with a stated home and a stated egress, and 4 decisions each with what you provision past its ceiling — plus what was not measured. That is the next page, not this one. step 14 — Run it in your environment → |
Not asked of this kit — 2 questions: clone (a fresh clone of this kit runs with nothing fetched); judge (nothing here is graded by a model).
Last verified 2026-08-27 — r001-announce-scrub. Every figure on these pages was captured from that run.
Run itHow this reaches your data
Every result on this page was produced by pure code over checked-in files, with no API key — which is why you can read the numbers before anyone spends anything.
Run this on your own data
- The pipeline, its eval harness and the runs behind every numberdeployed inside your environment, on your own model endpoints, against your own documents.
- The corpus above is the shape, not the limitit is a folder swap, and there is no database to migrate.
Checked before this shipped — Every pack, the answer key, the corpus statistics, all three free floors' results, the ceiling probe, the stub, the scored run and the injection probe are committed. A clone with no API key can run check_labels, all three floors and the whole UI, and reproduce every free number on this page without spending anything.