Why it matters
Today's manual process, and the same job with the app
Cost control and joint-venture accounting staff at an oil and gas operator, reviewing each well against its approved budget before the quarter closes.
✕Today's manual process
1Read the cost report line by line against the AFE's approved detail for every category.
2Add up each category and compare it with the approved amount and the allowed overrun.
3Check the alert log and the cost notes, to see if a breach was already answered.
4Miss the window and the partners find out only when the invoice confirms it.
Every AFE reviewed manually, months late
✓With the app
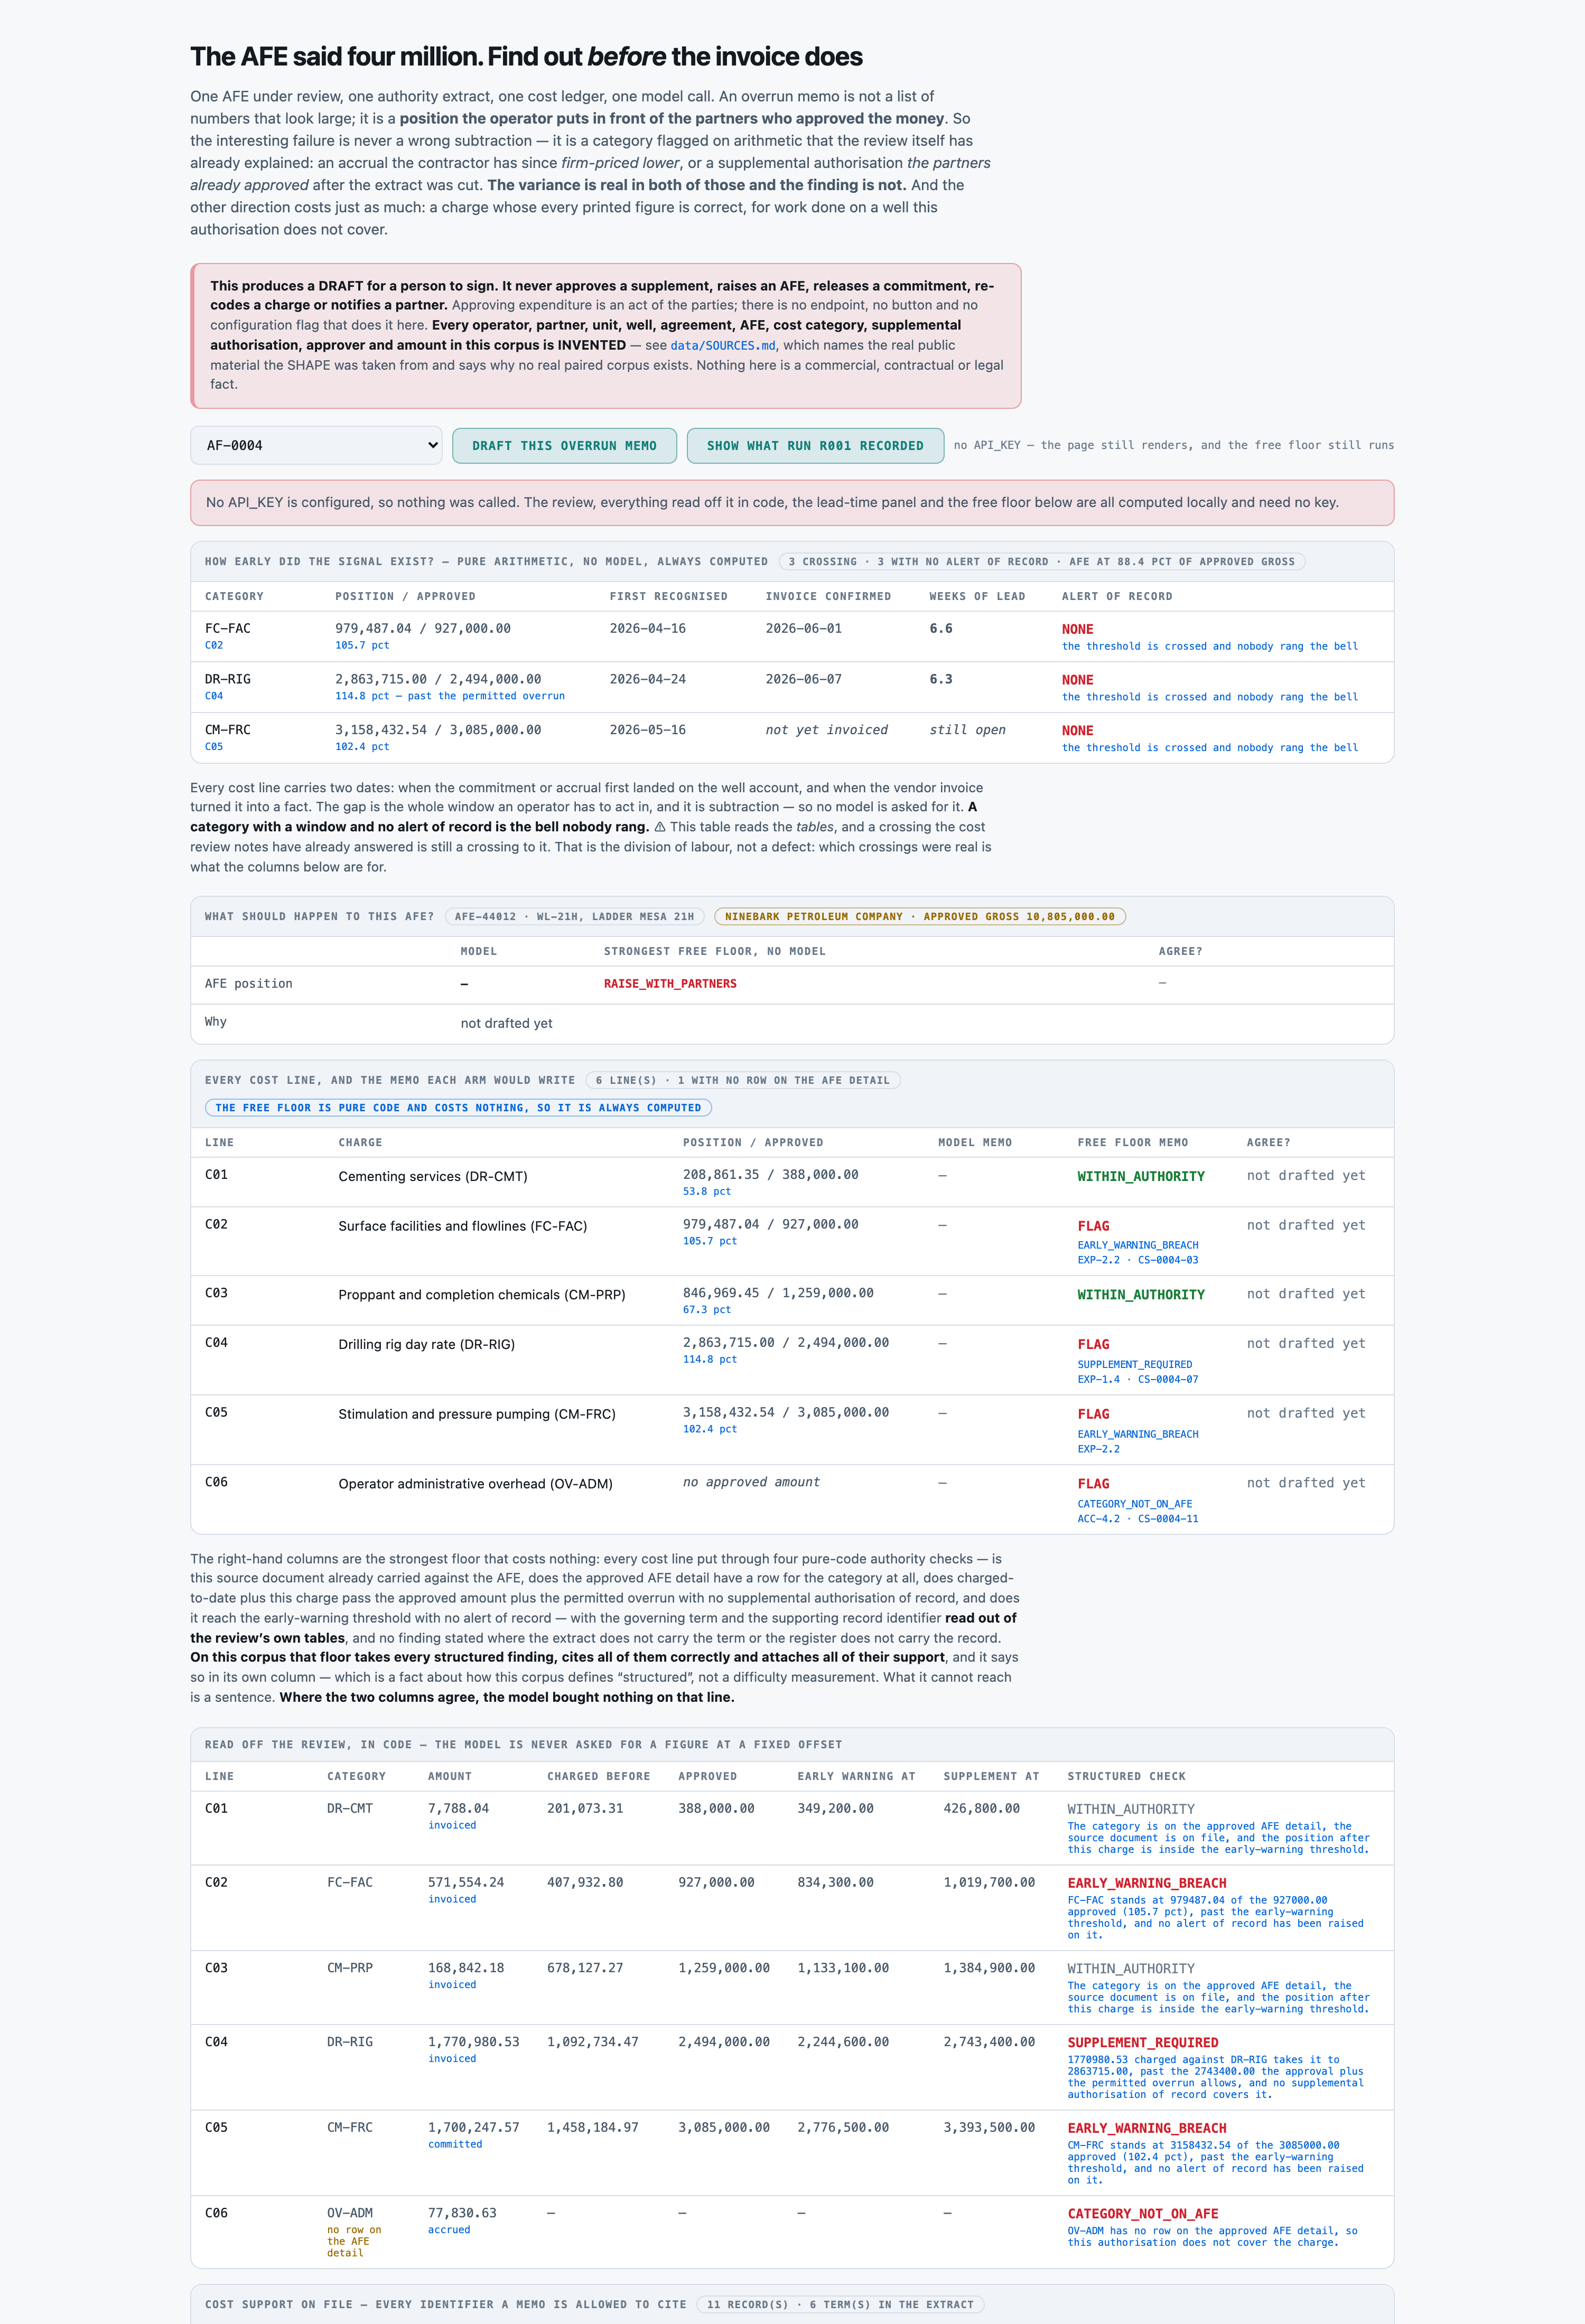
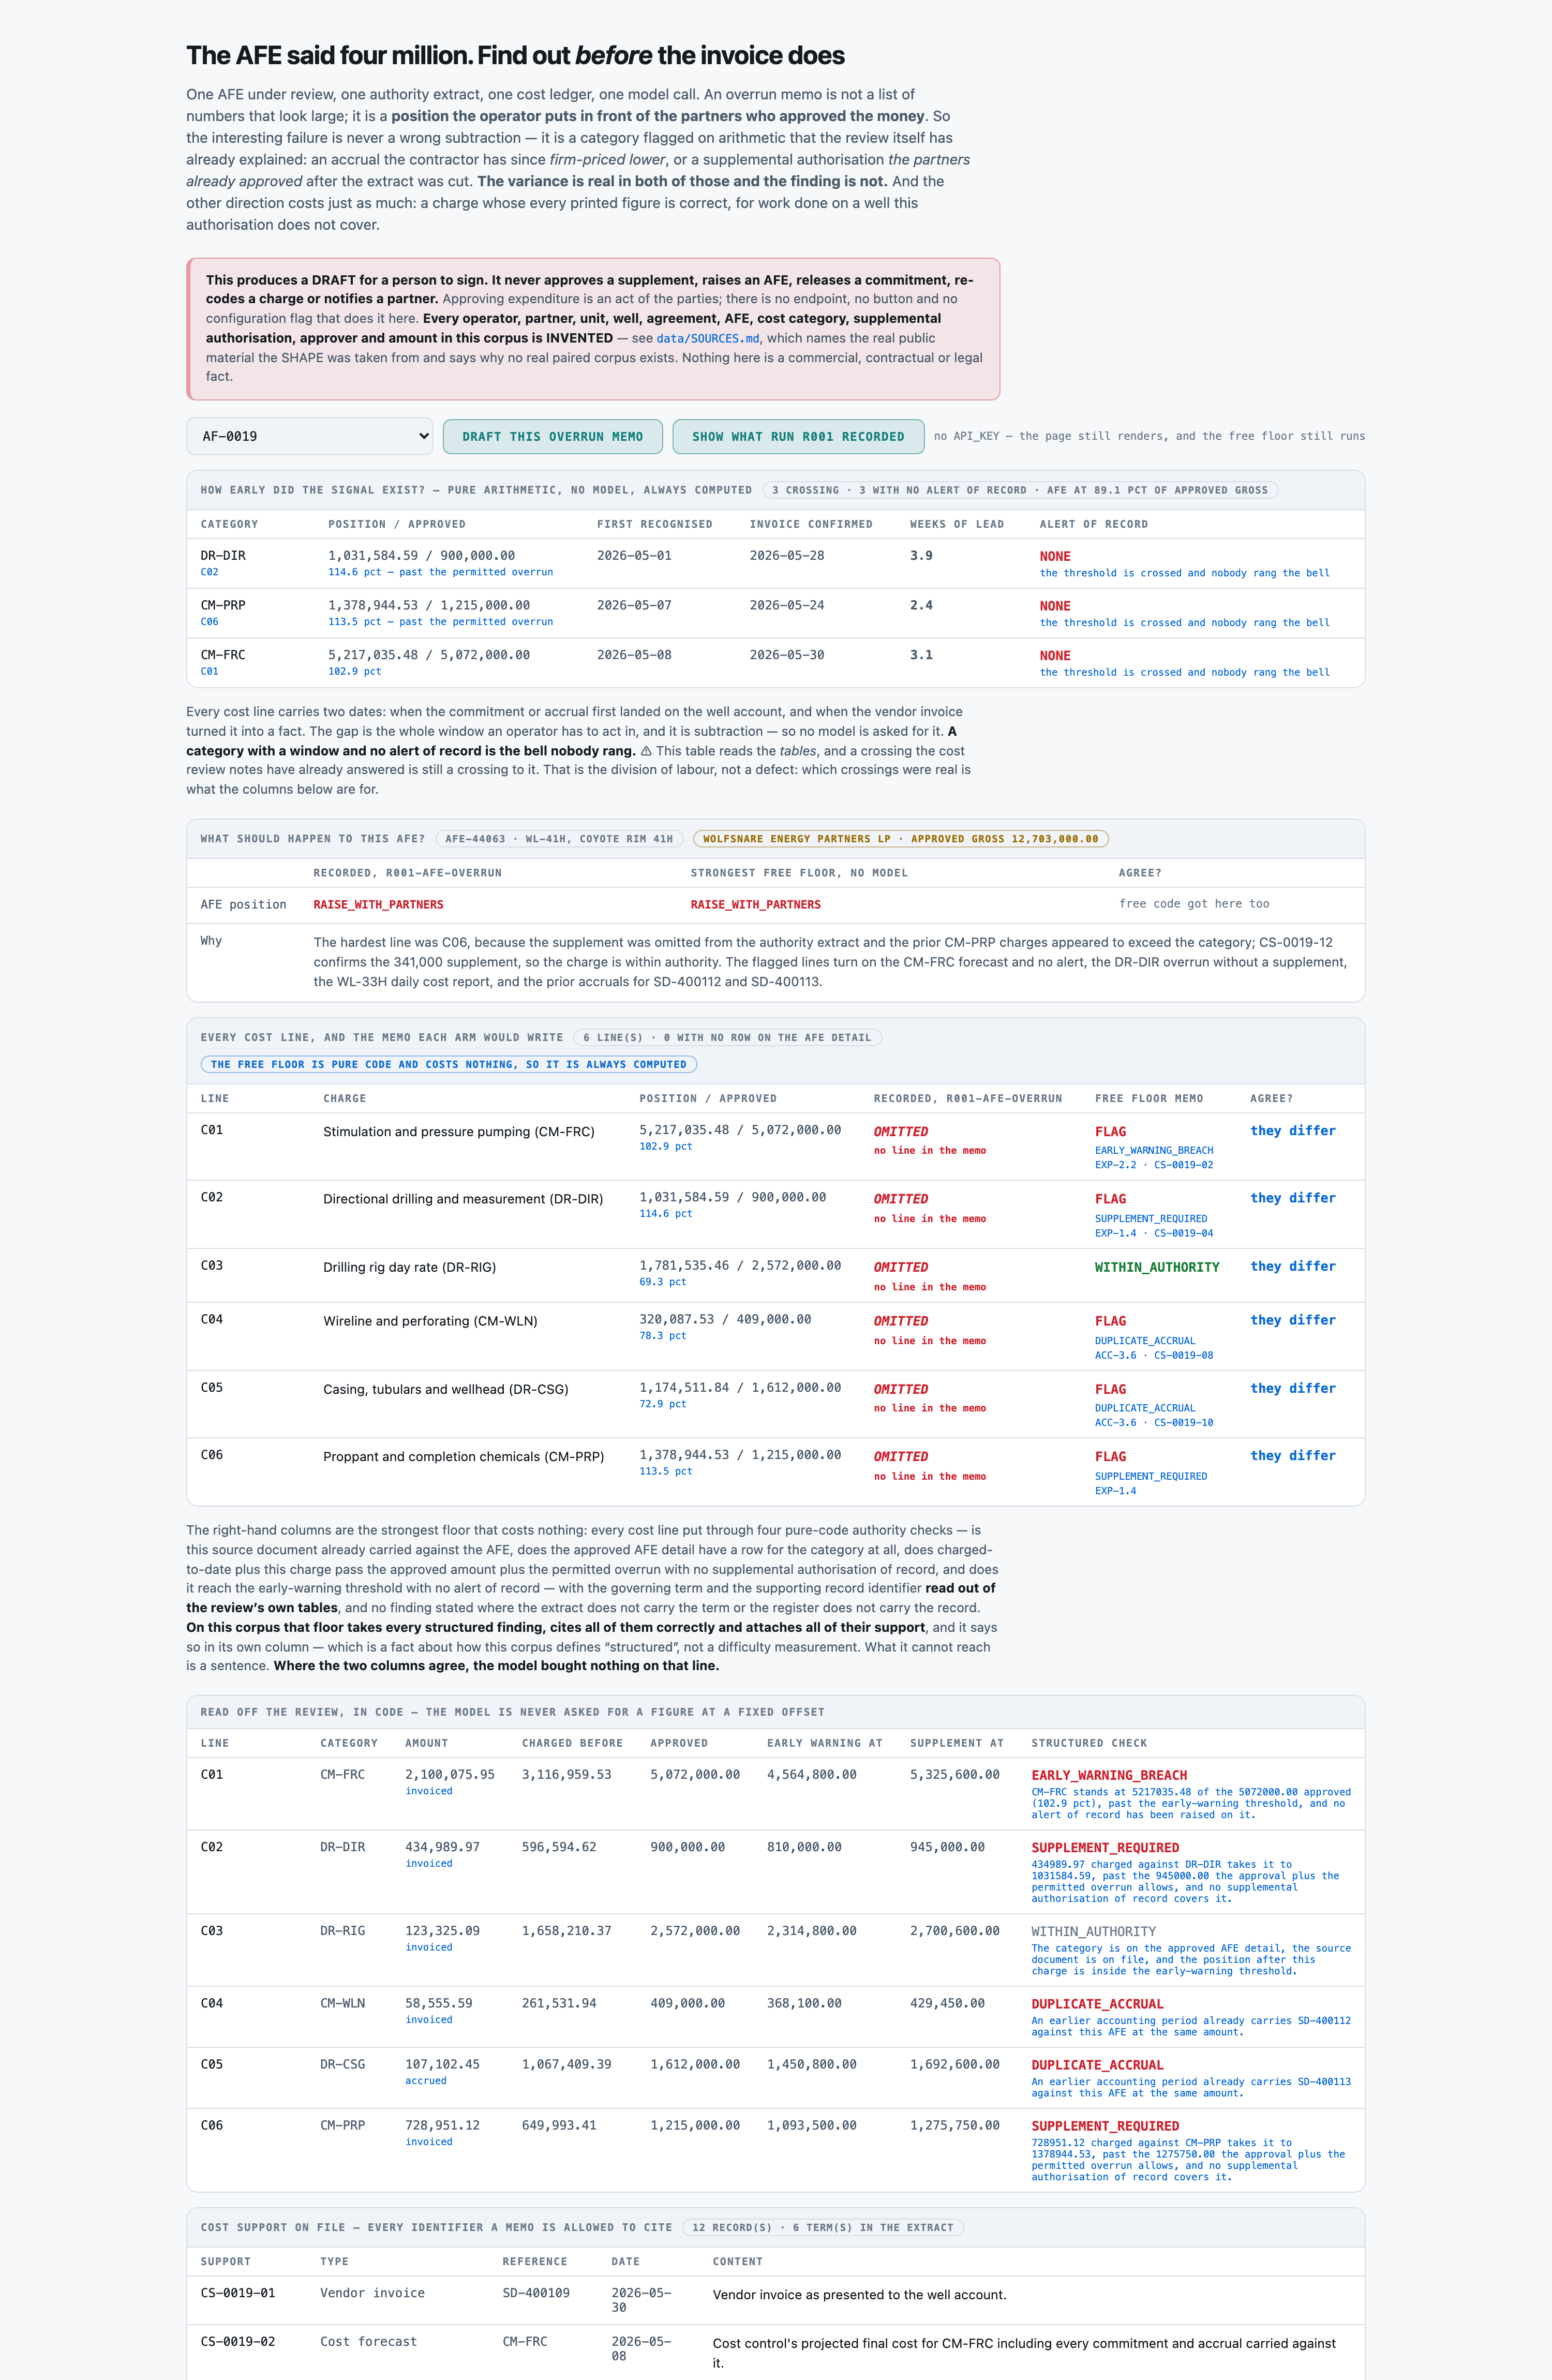
1The well account is read and every category is compared with its approved amount automatically.
2Early crossings are found weeks before the invoice, with the alert log checked for each one.
3Each line gets a memo entry with the finding, the contract term, and the record behind it.
4Clean lines are left alone so the partners only see what actually needs a decision.
Overruns caught weeks before the invoice
See it work
One real case, read by the app, step by step
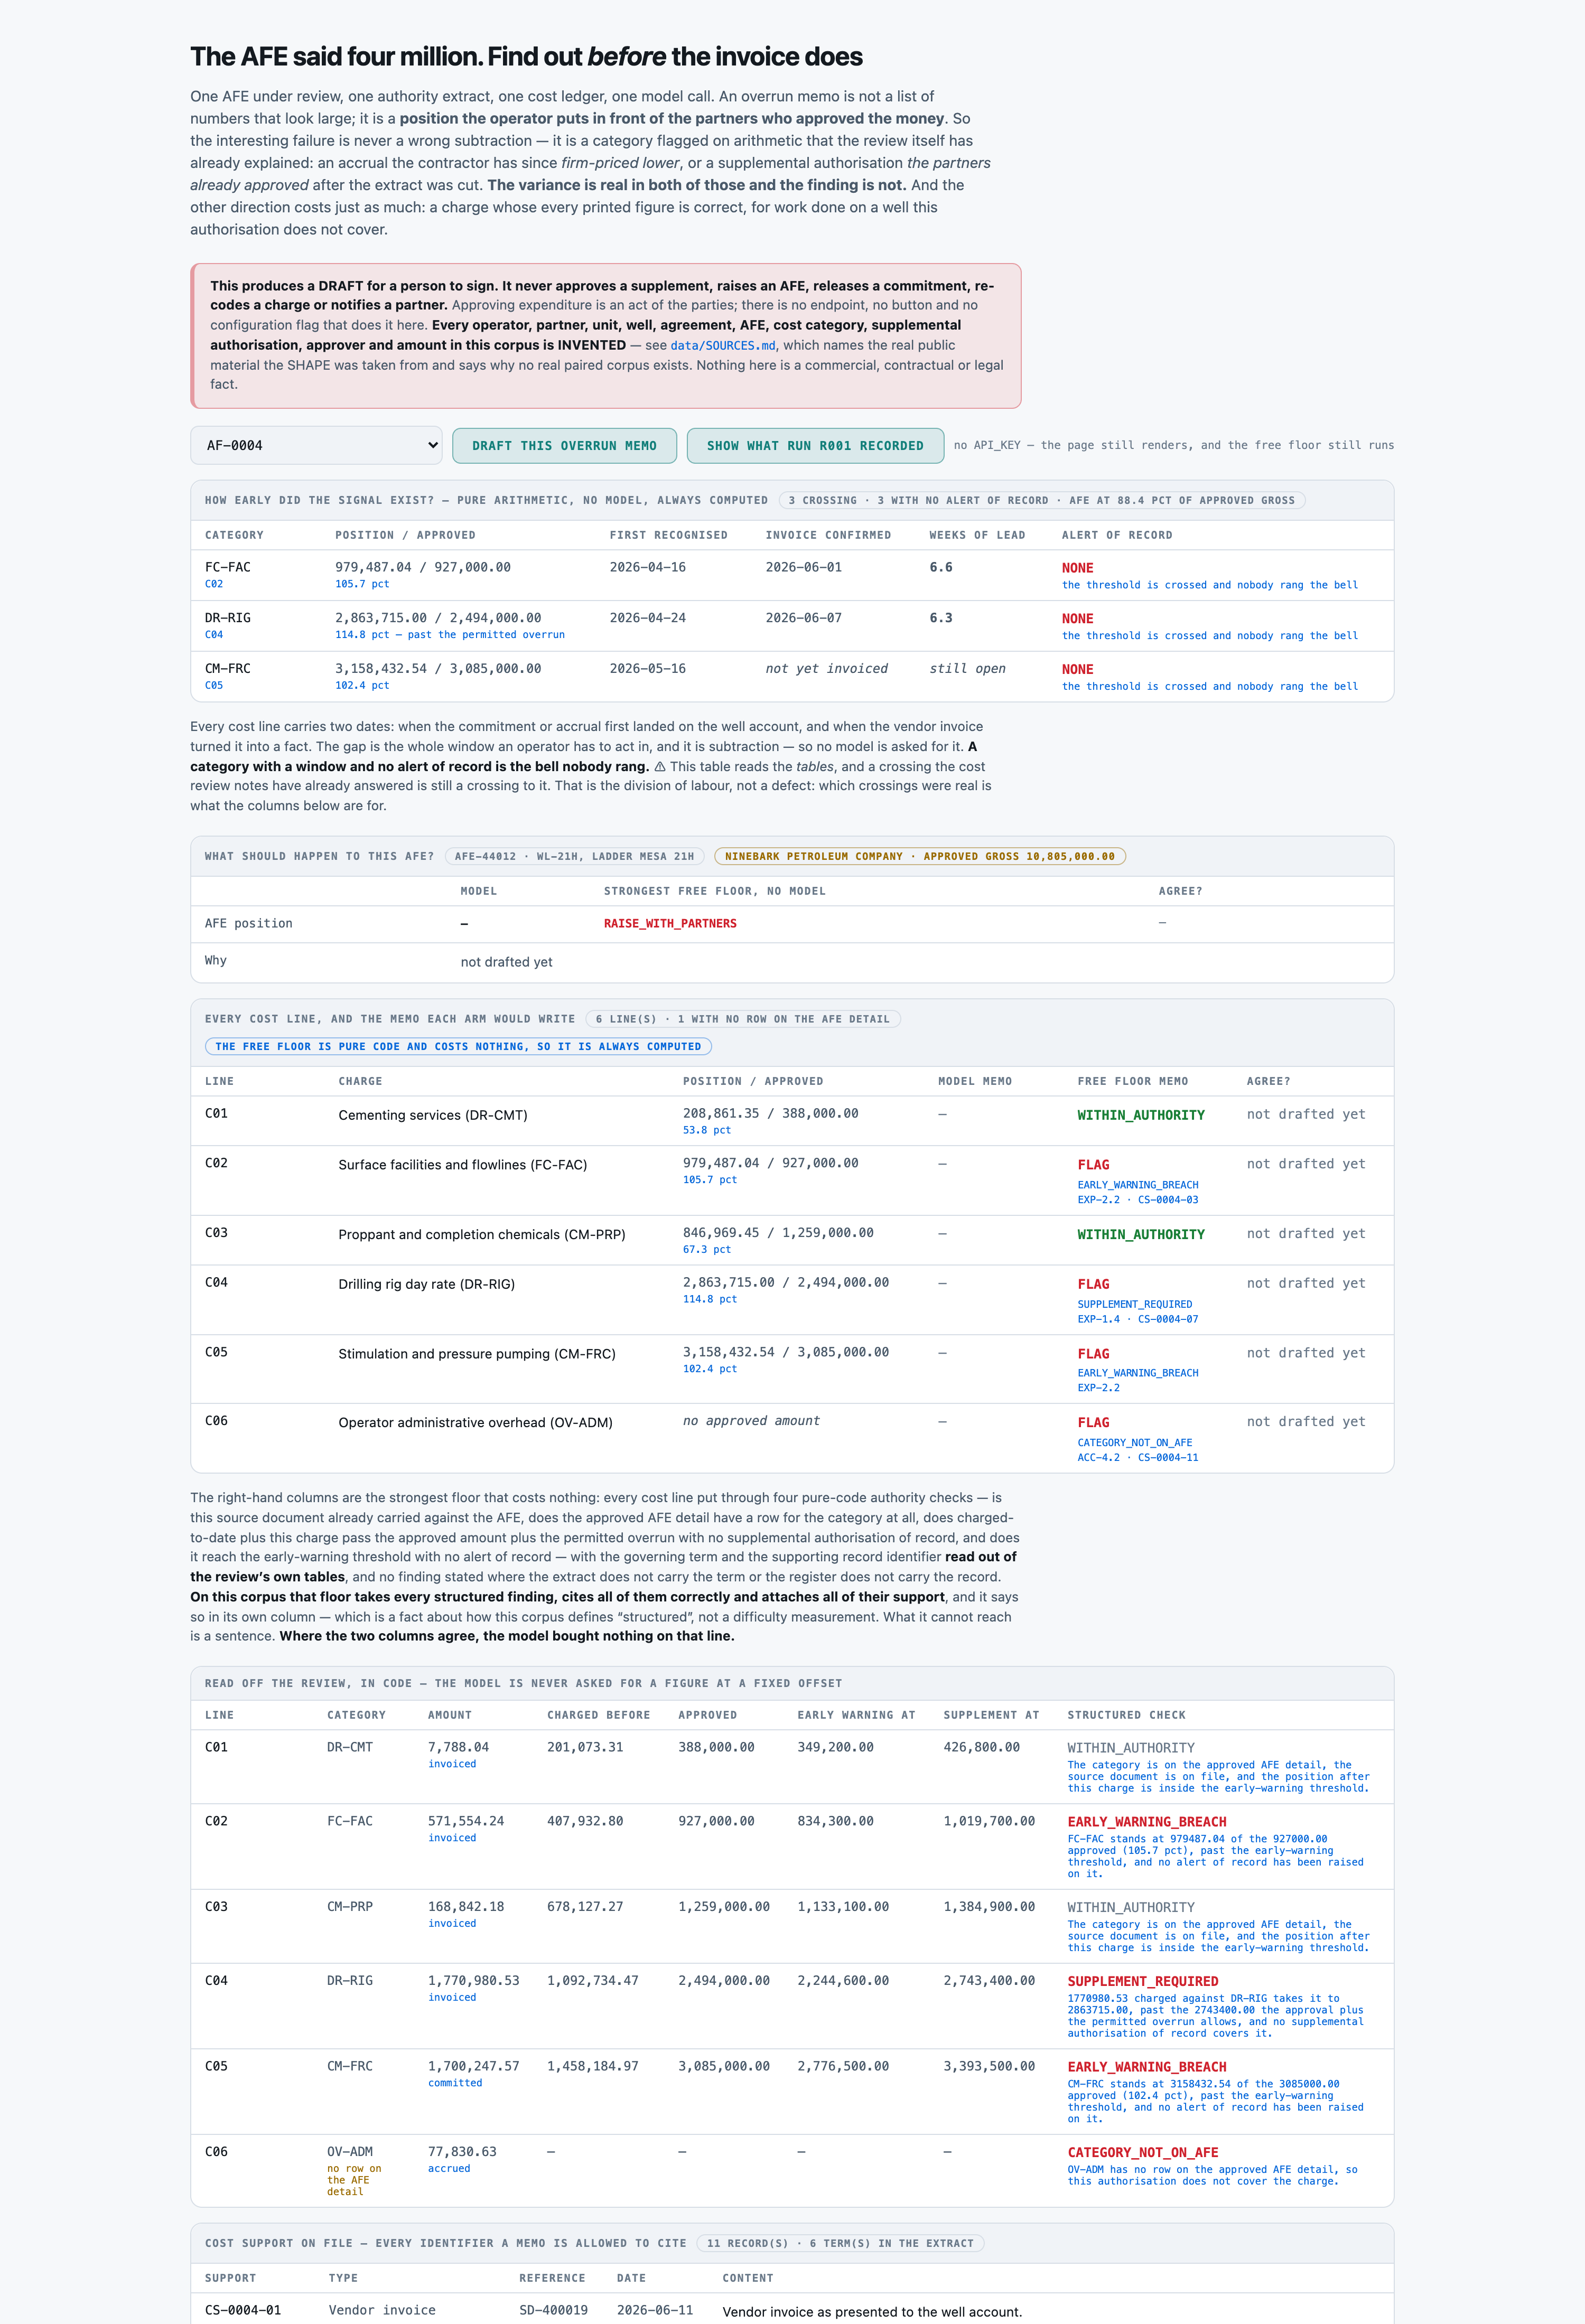
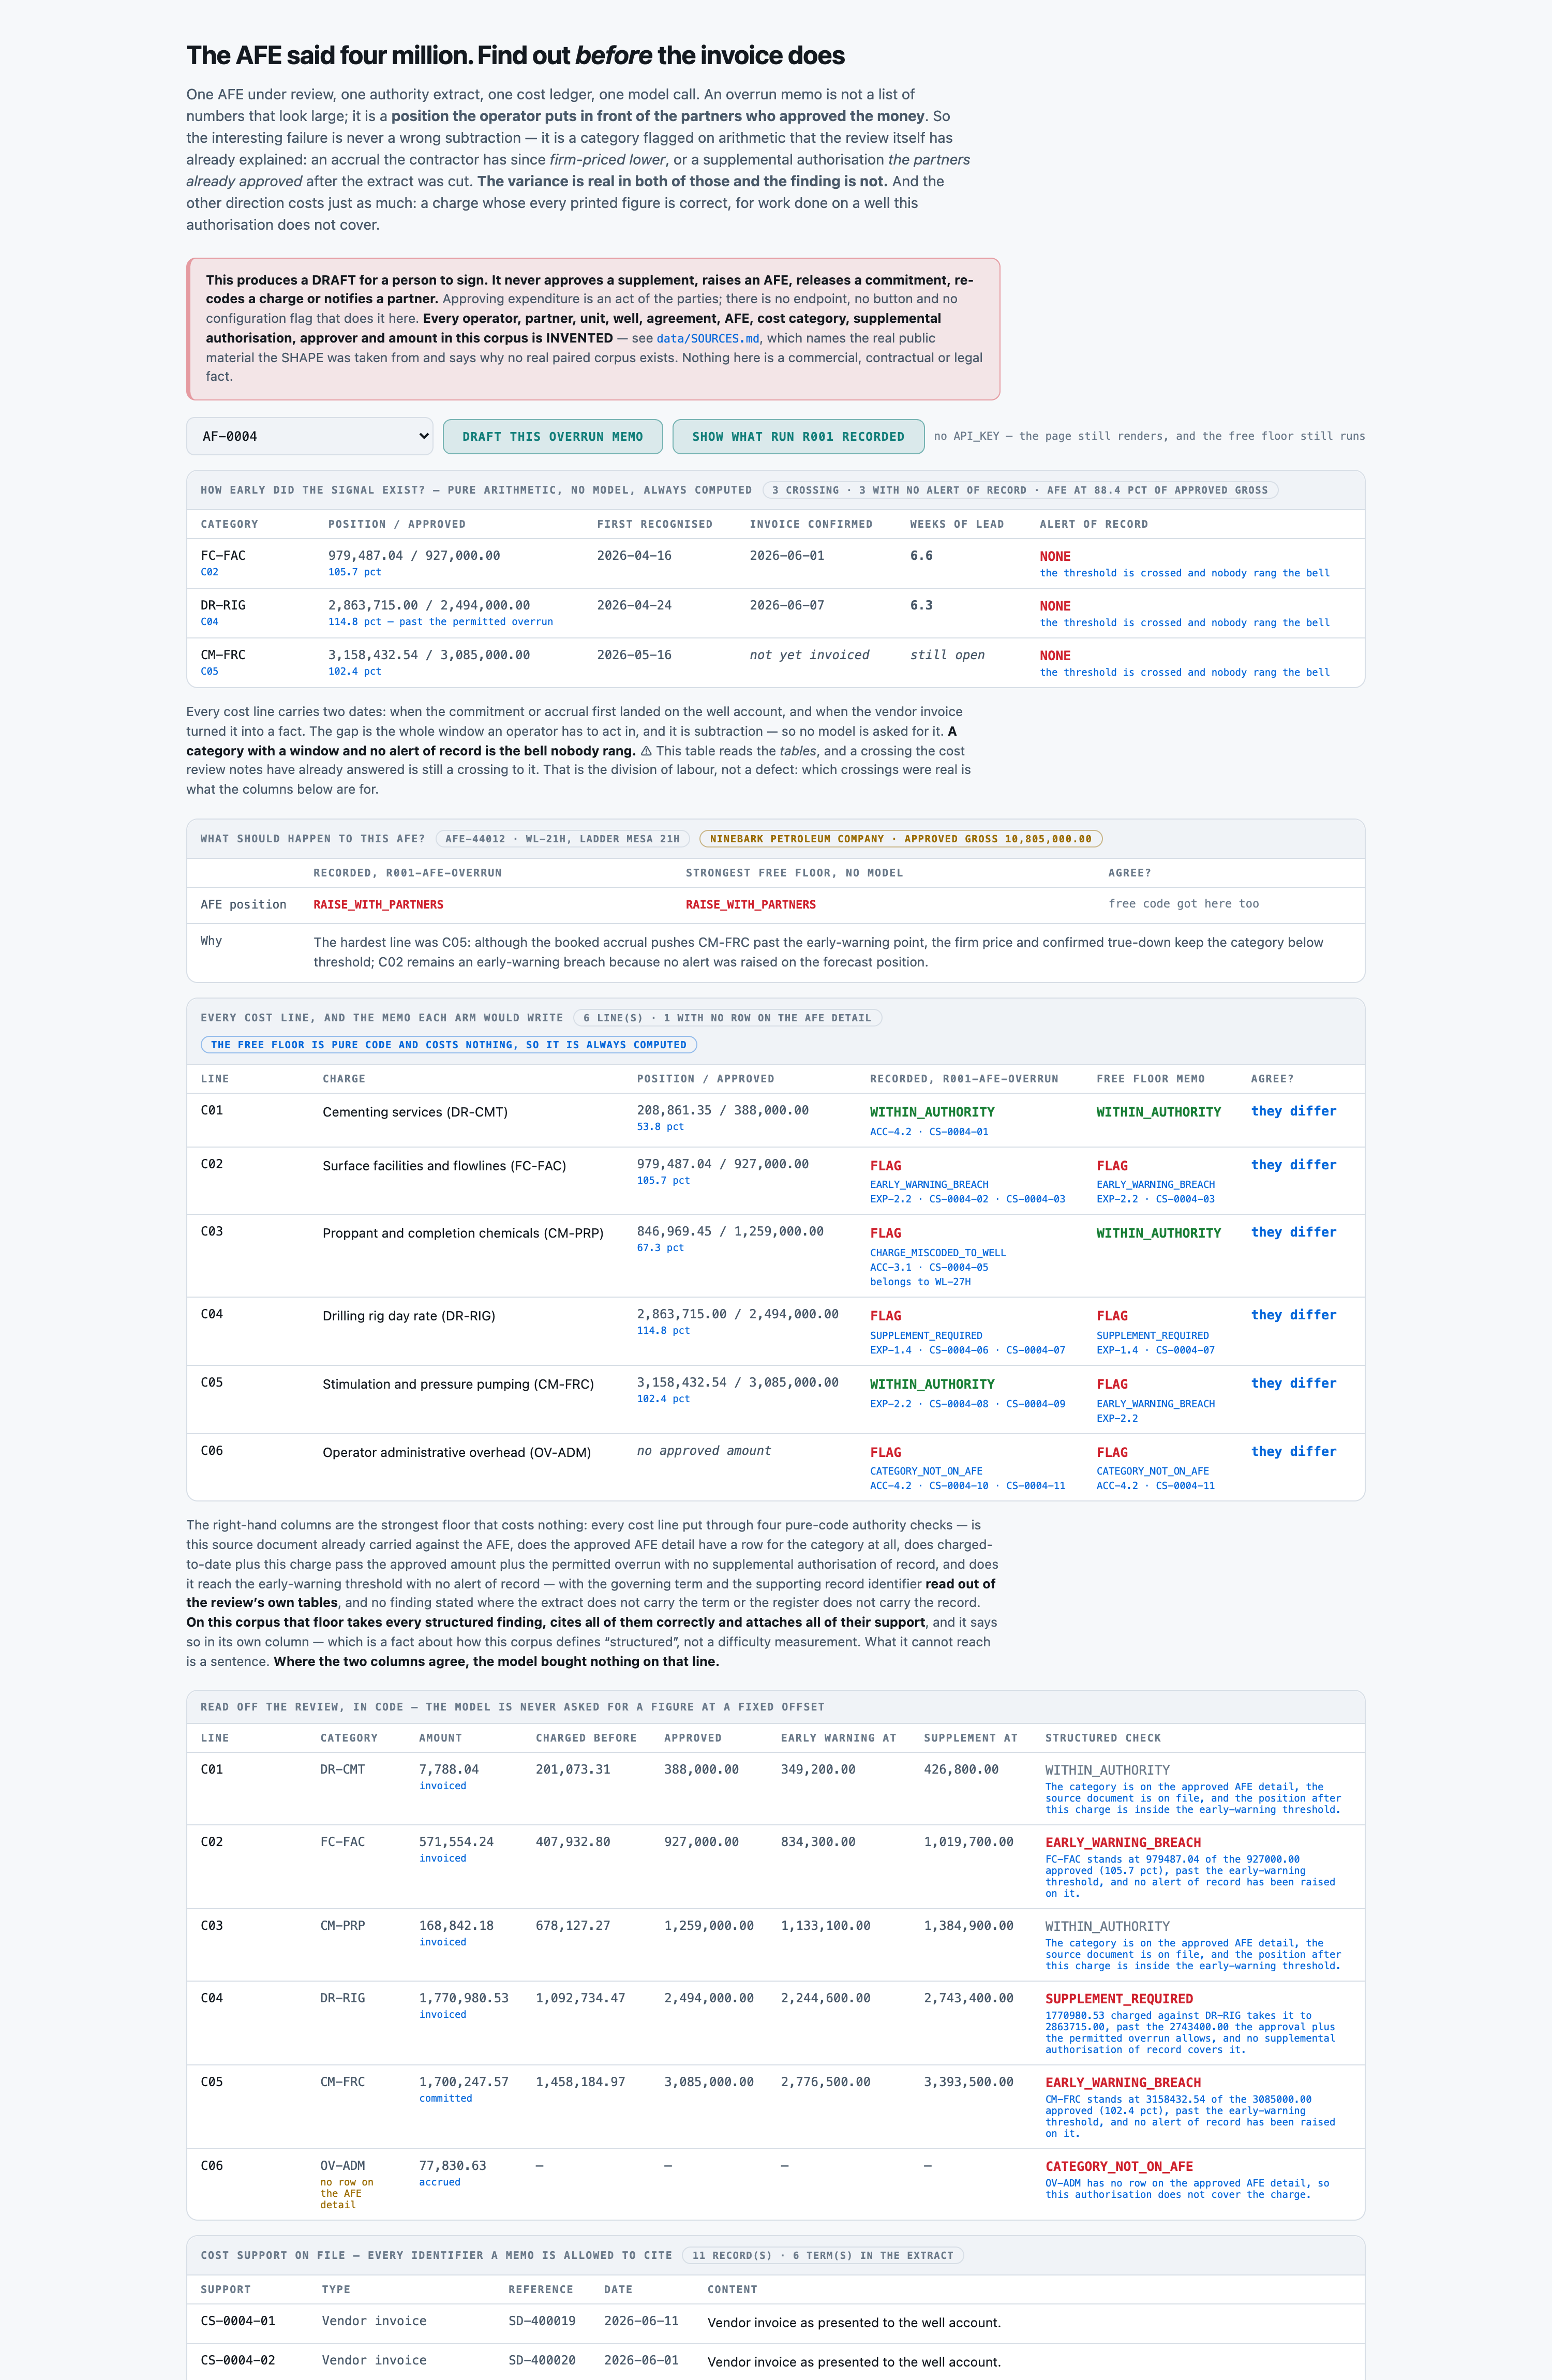
AFE-44012 on the Ladder Mesa well: surface facilities already 6.6 weeks past its early-warning limit, with no alert on file.
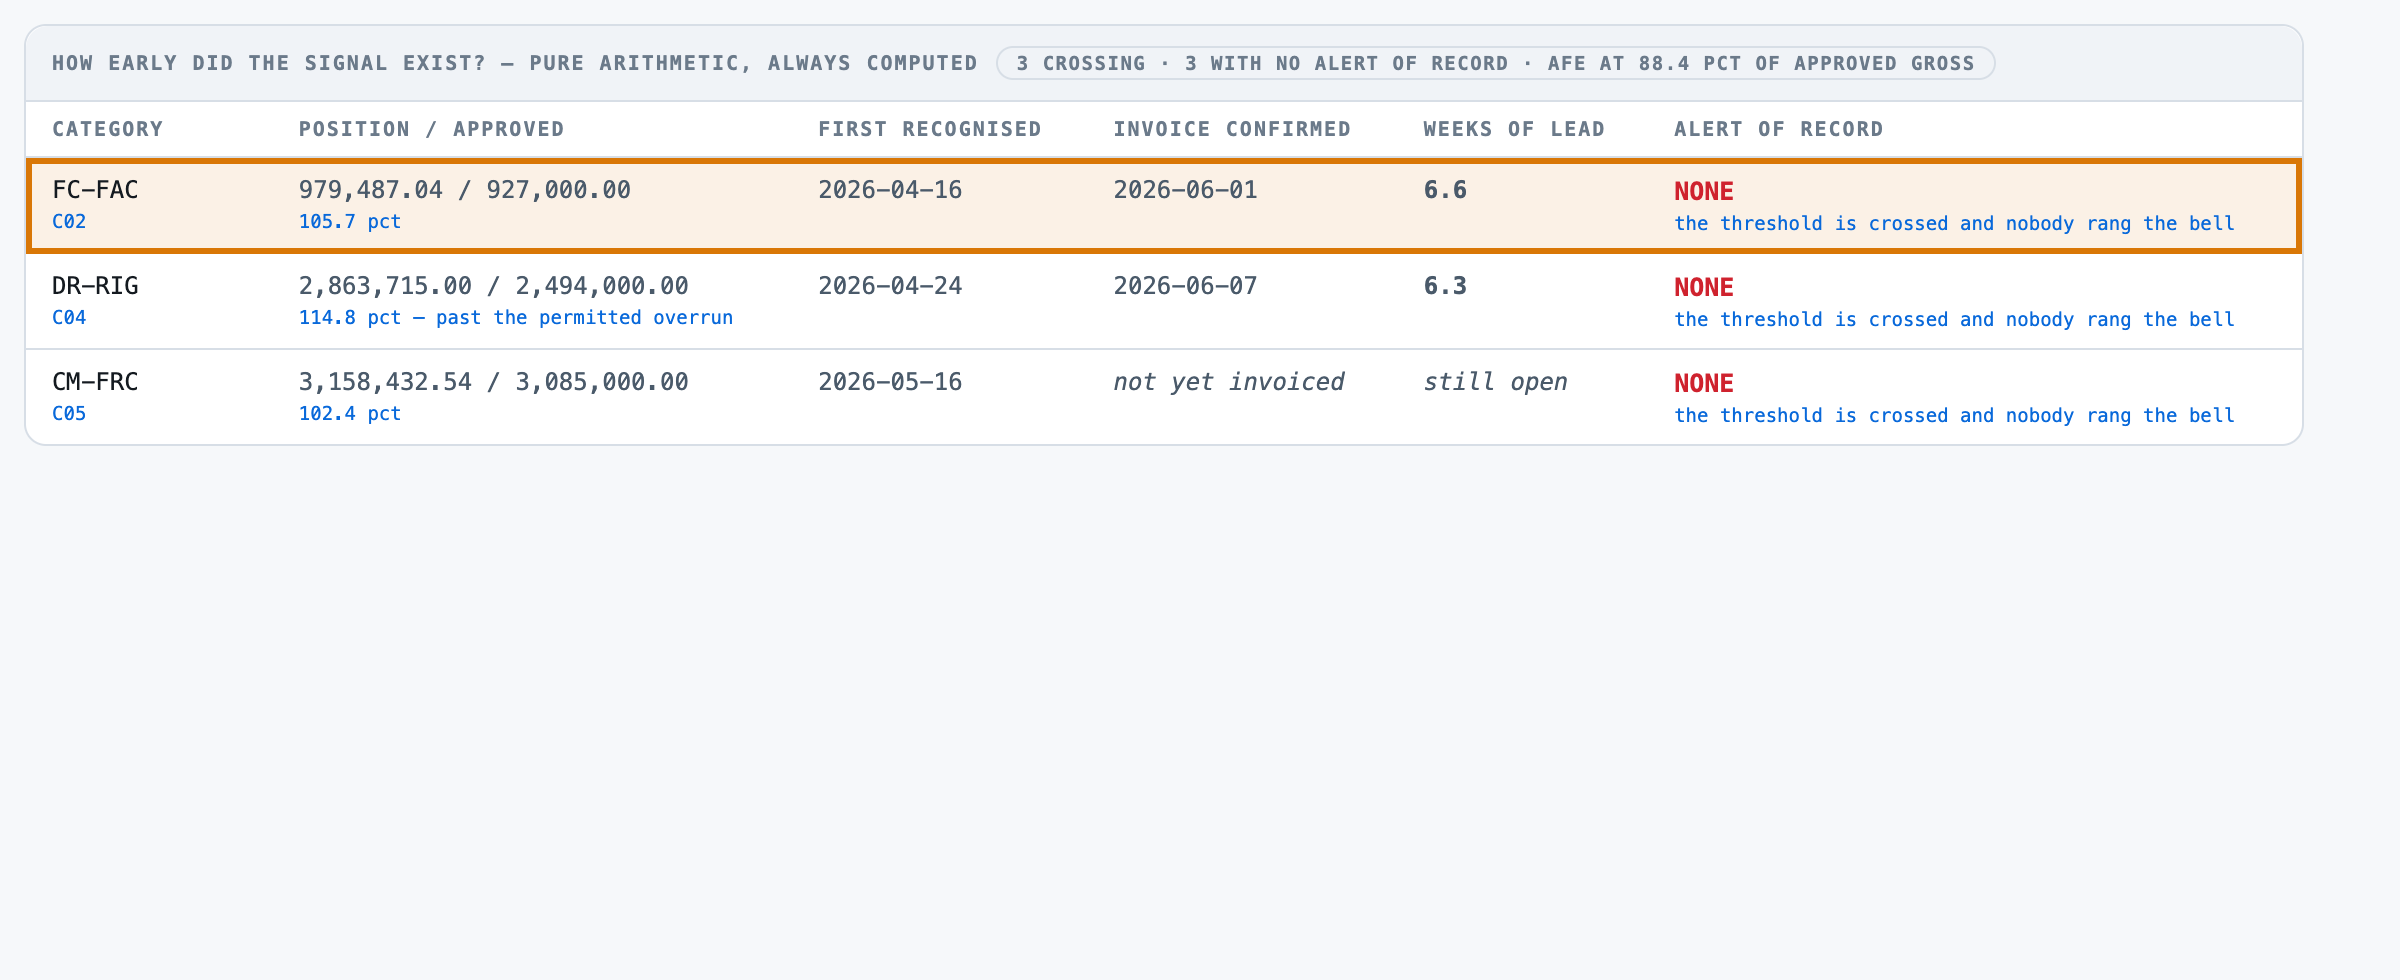
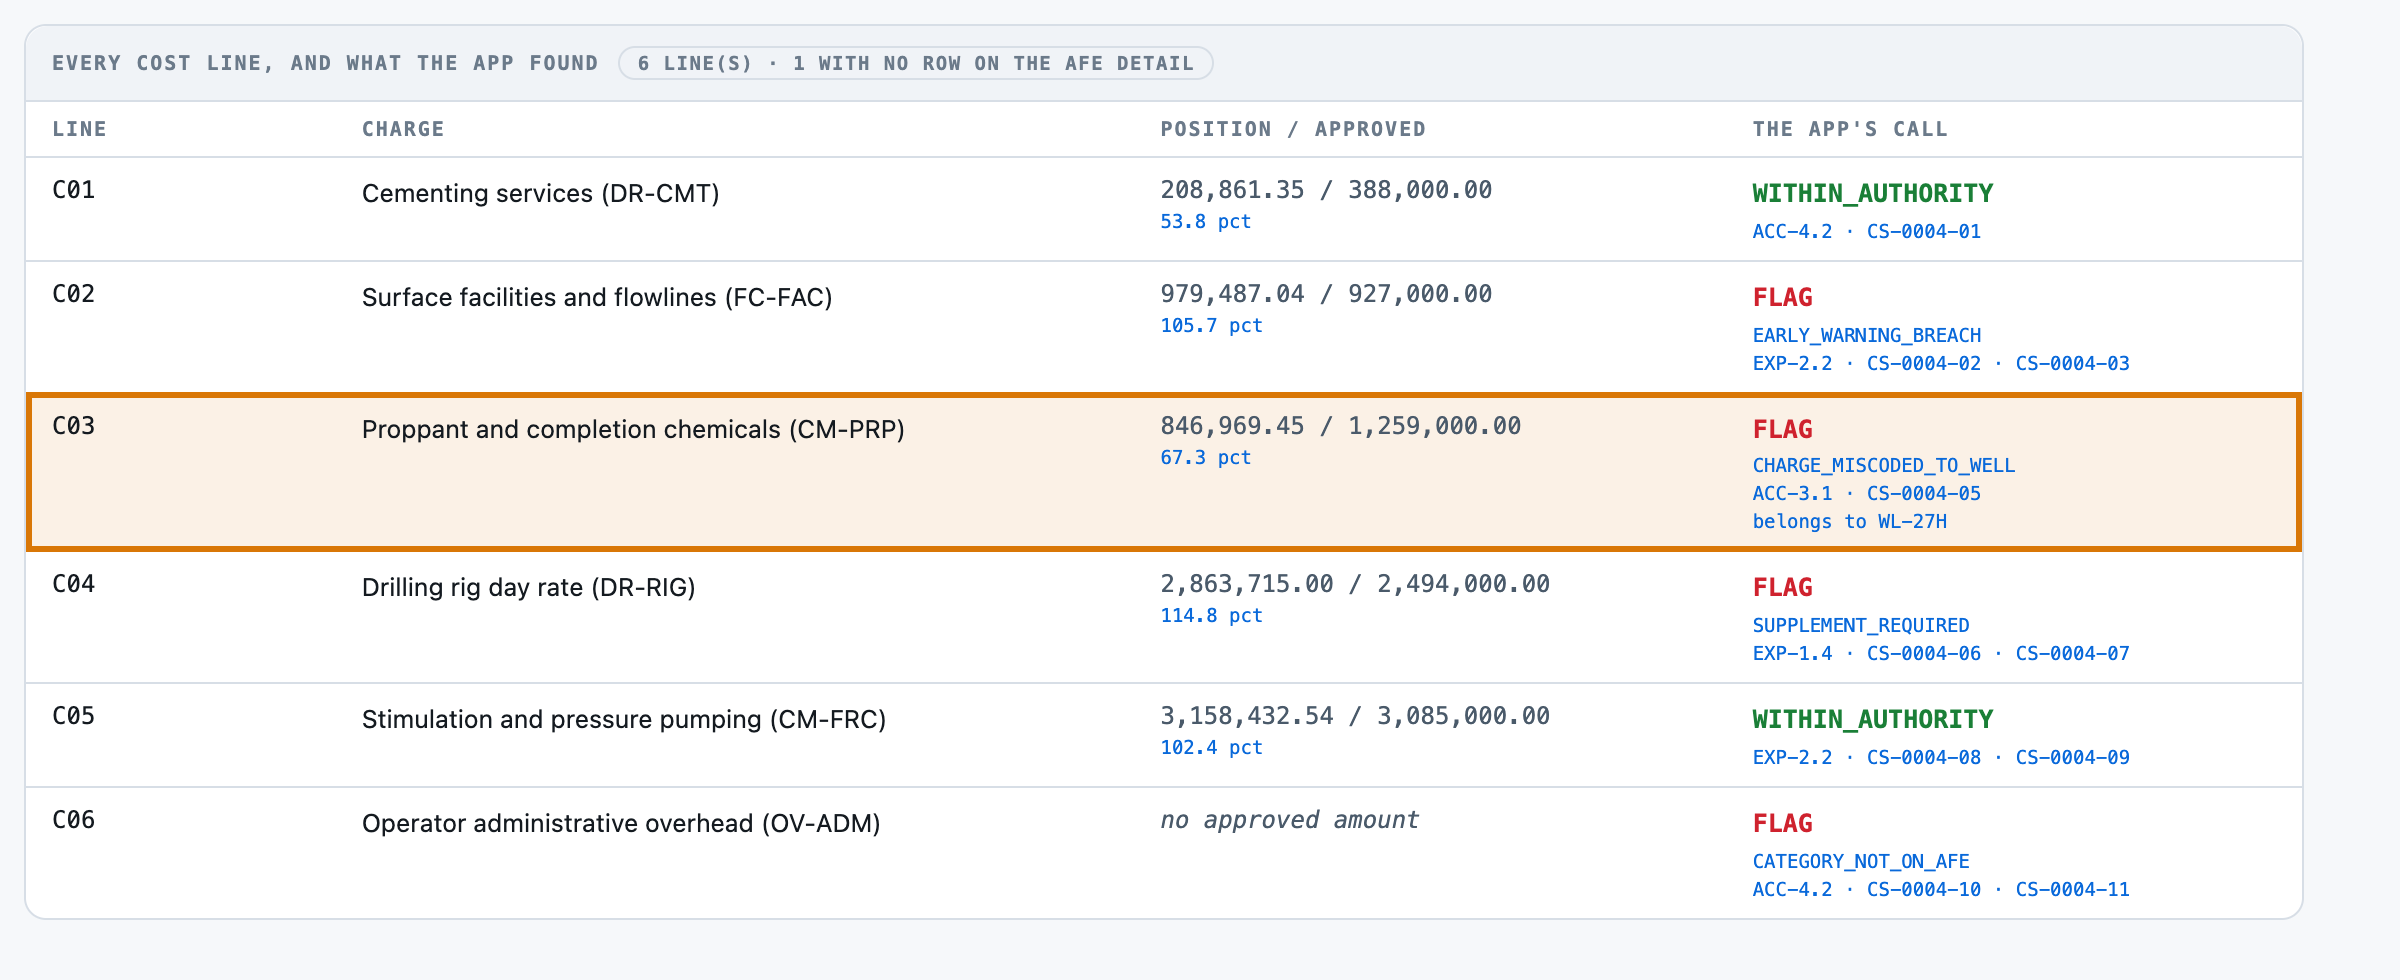
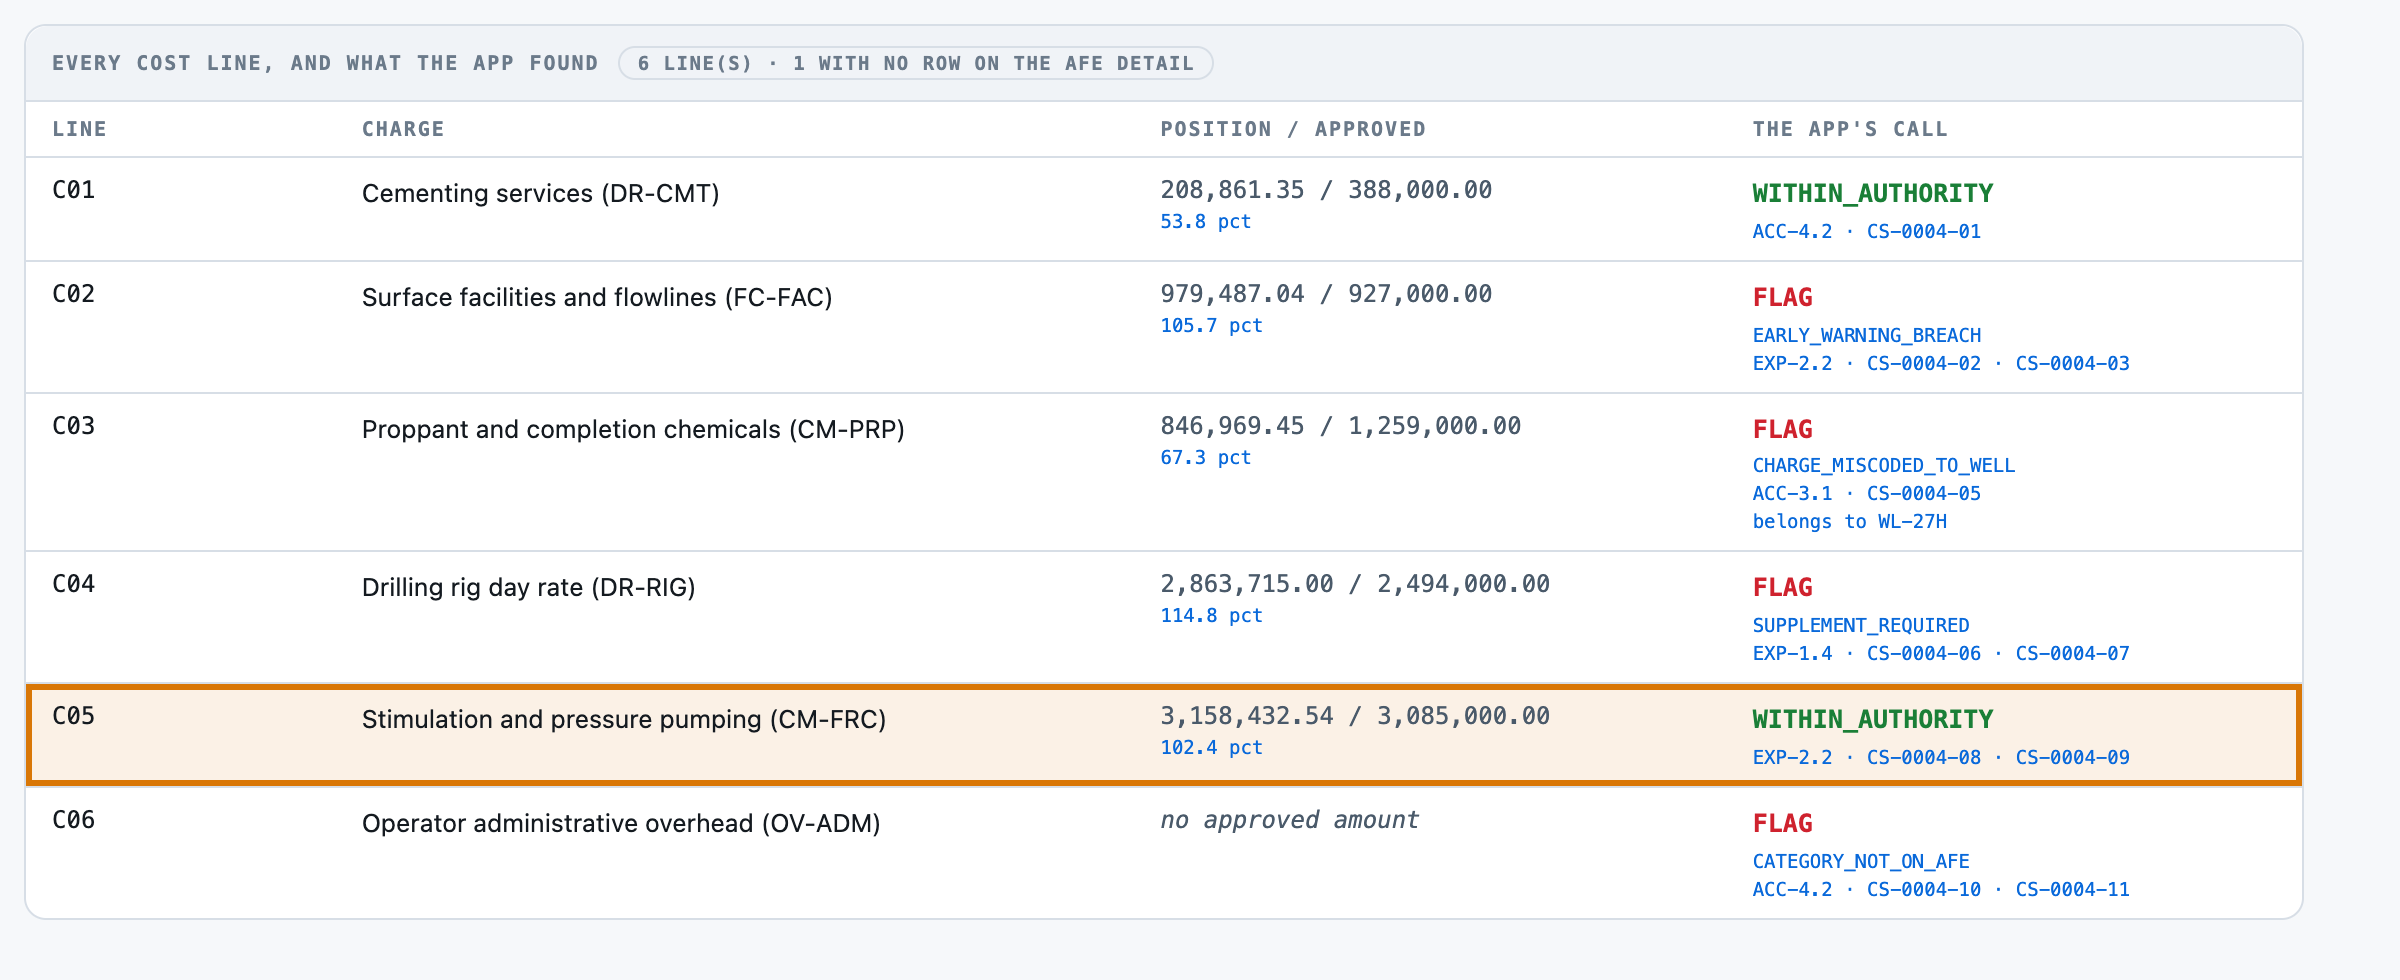
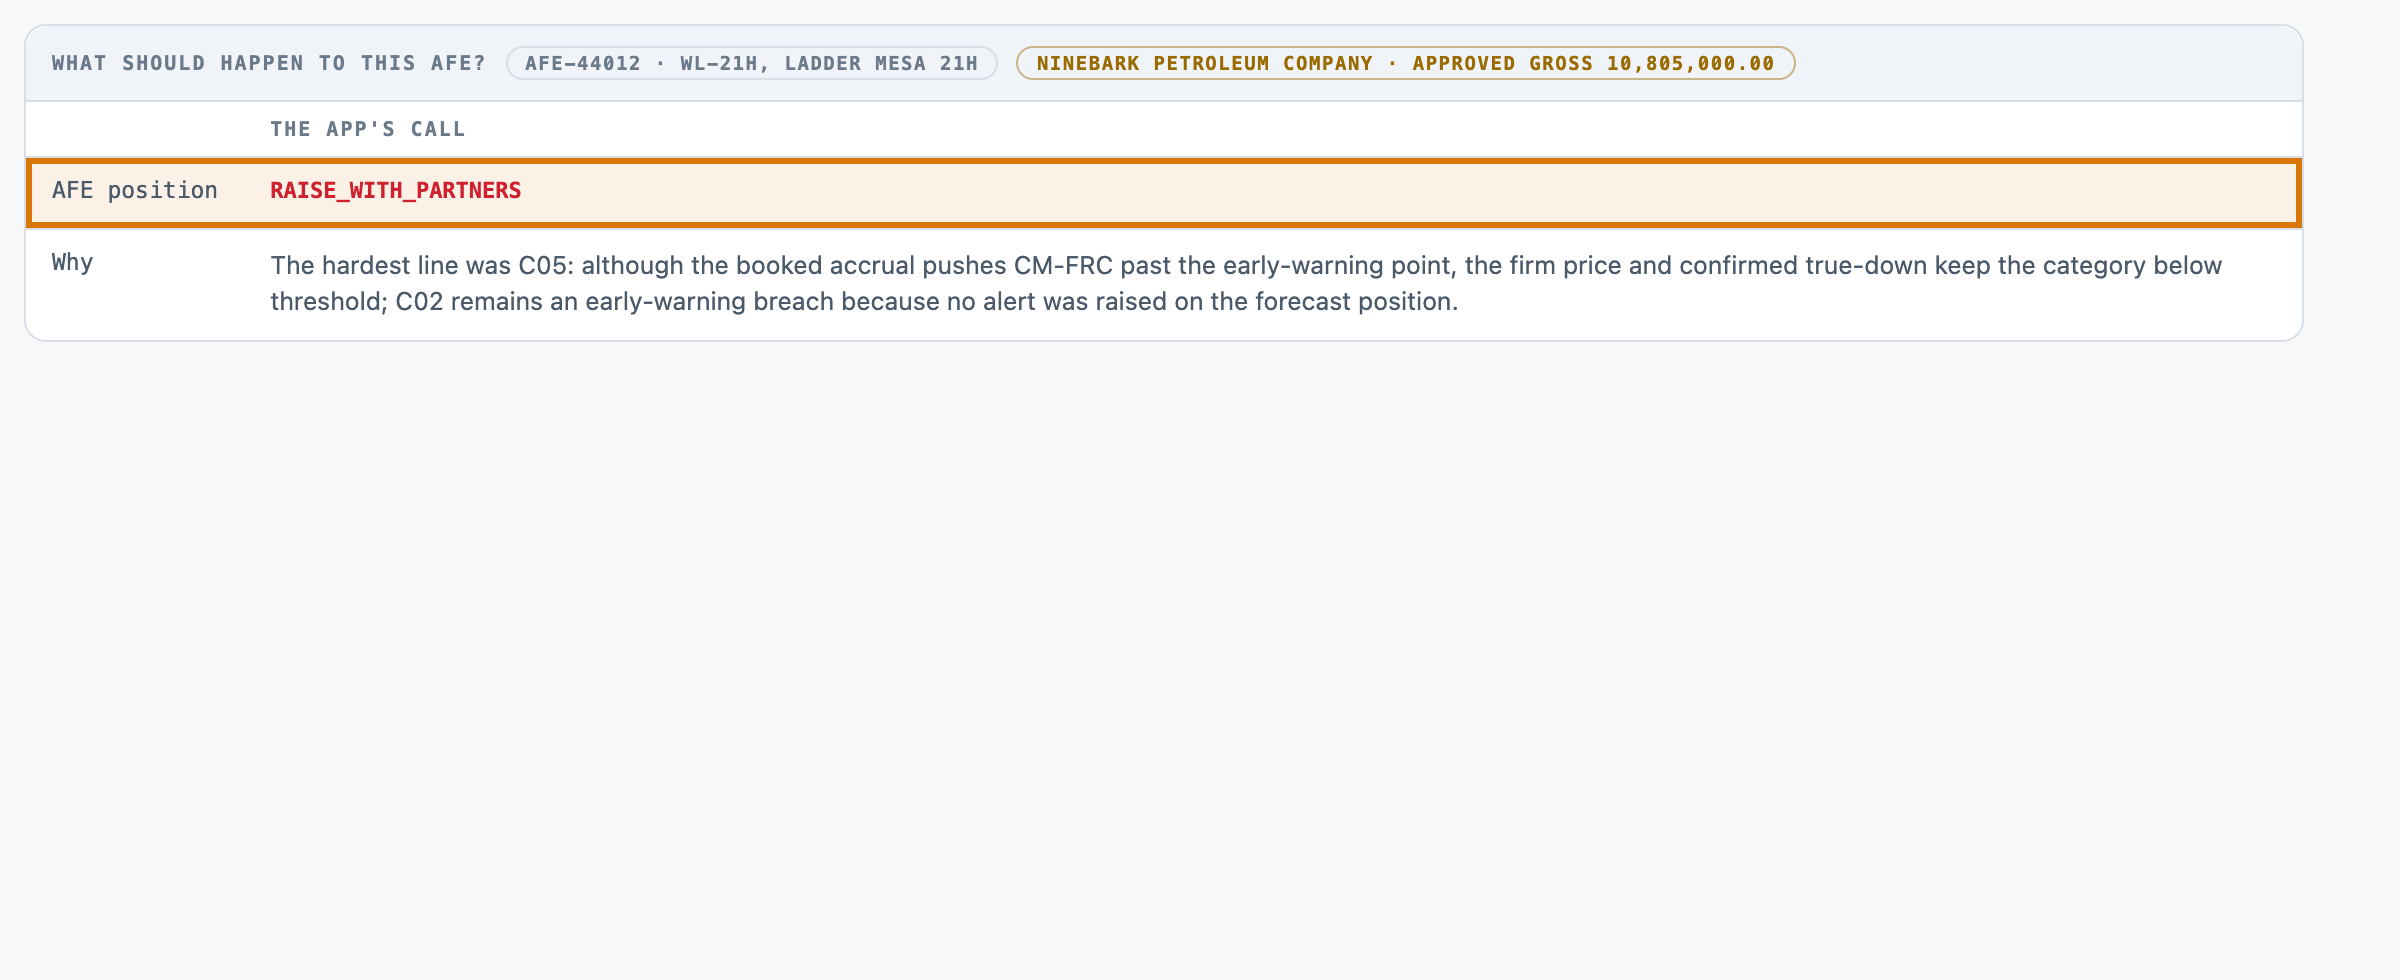
- 1The early signal Surface facilities crossed its threshold 6.6 weeks before the invoice, with no alert.
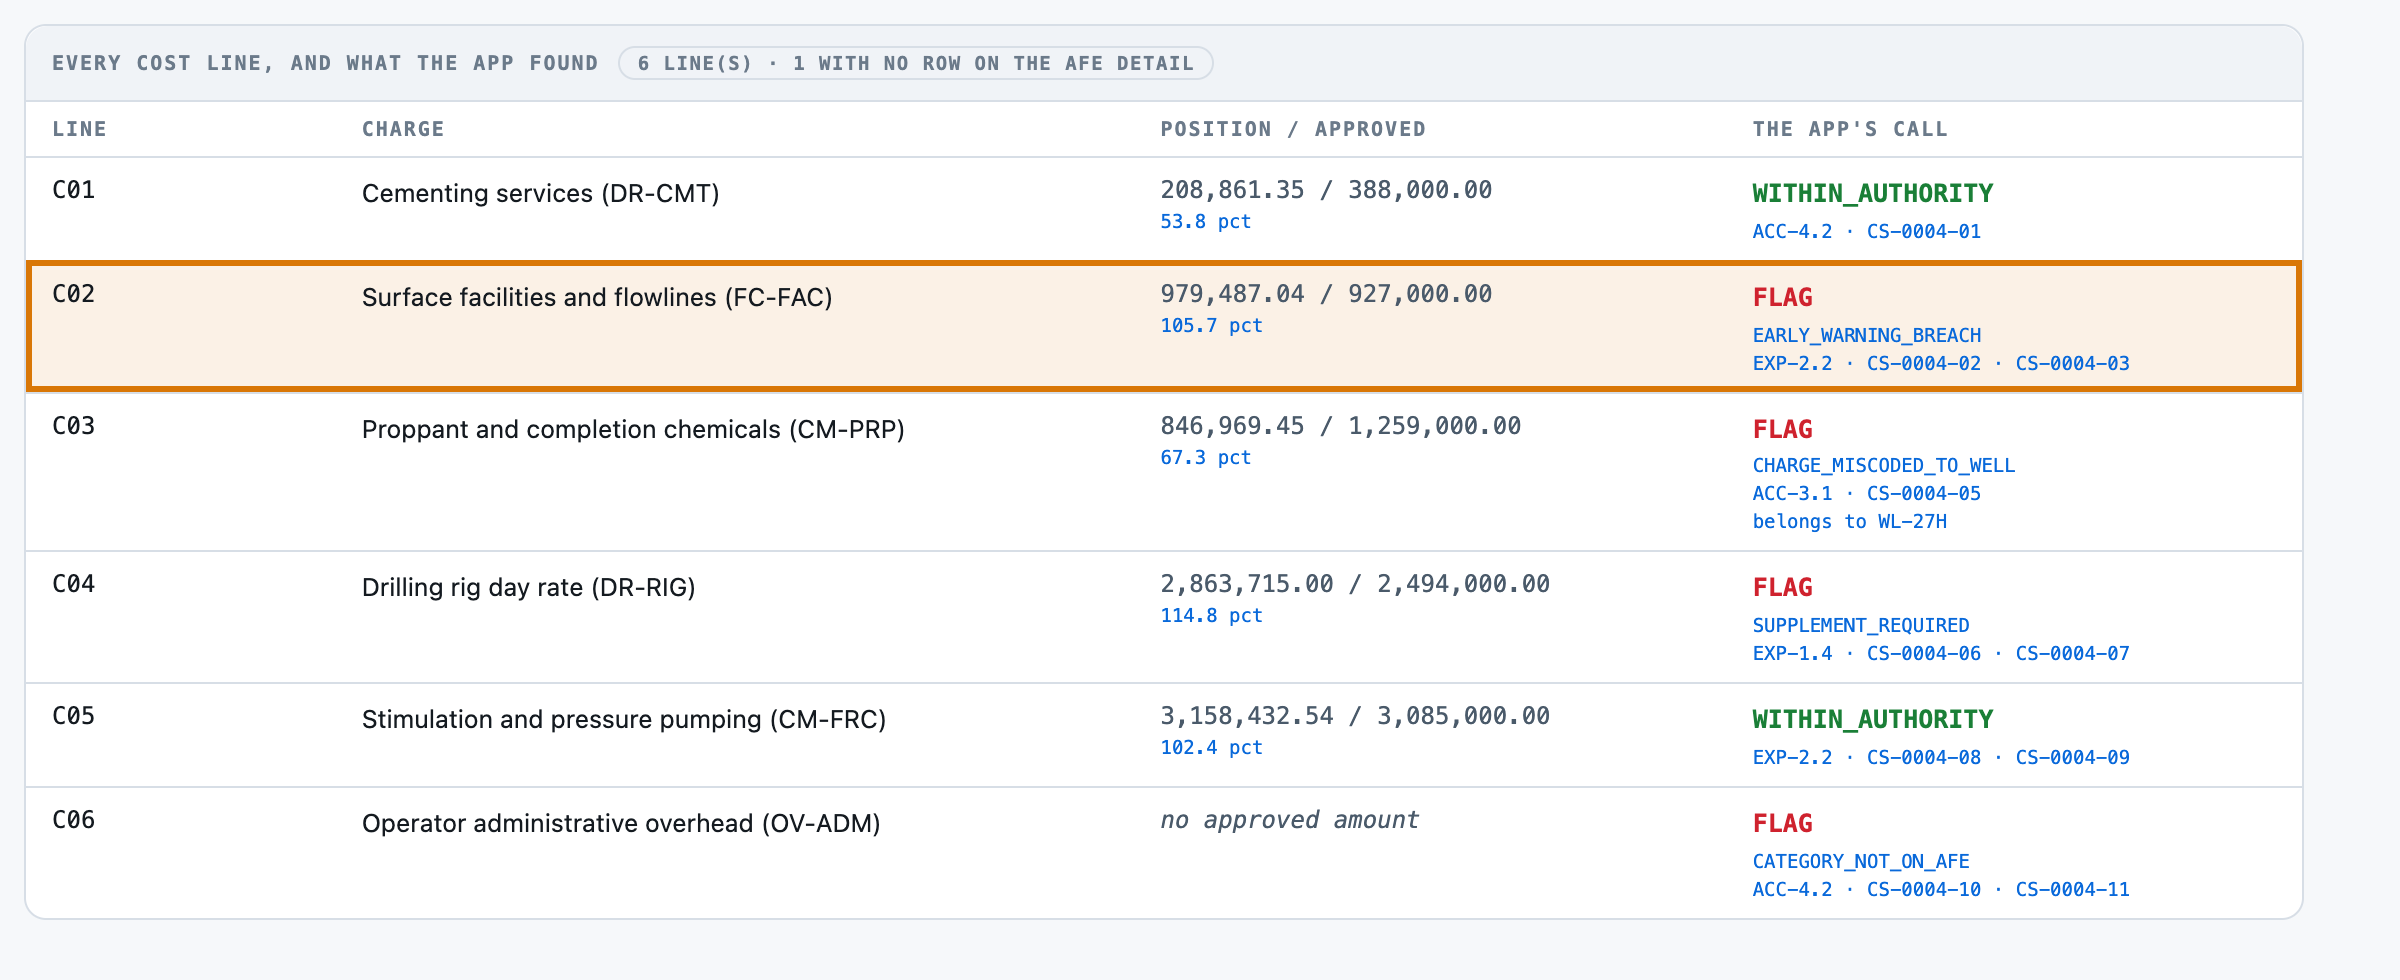
- 2The finding Flagged as an early-warning breach, citing the governing term and the forecast.
- 3A second catch This charge was booked to the wrong well and belongs to a different authorization.
- 4What does not count Reads over the threshold, but the firm price keeps it in authority.
- 5The outcome Raised with the partners: two breaches, a miscoded charge, a category outside the AFE.
For engineers
How it is built, and how we measured it
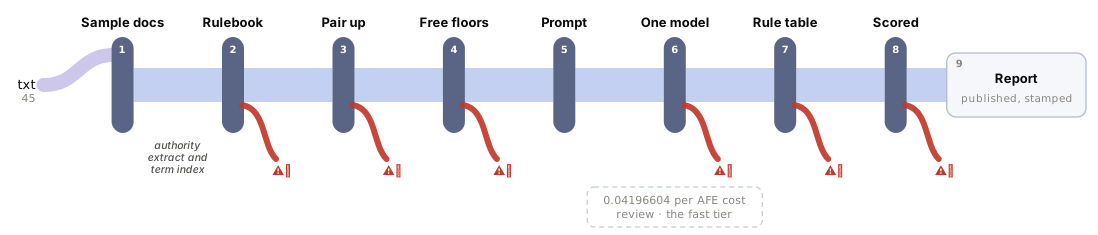
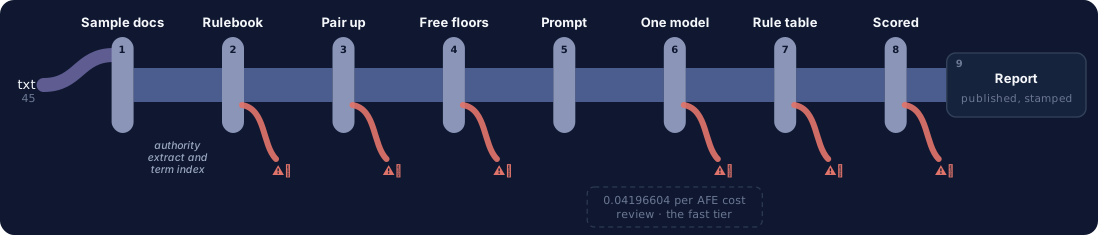
All fourteen steps of the build are written up, from the business case to running it in your own environment.
115 of 120real cost breaches caughtmeasured in 06 Evals →
23 of 24findings only visible in the notes, caughtmeasured in 06 Evals →
117 of 130clean lines correctly left alonemeasured in 06 Evals →
4.2¢to draft one AFE's overrun memomeasured in 07 Unit cost →
The build, step by step
14 steps06 Evals · the graders
Make it yours
What you see is a reference app. We shape it to how you work.
Every part of it is built to change, and none of it means starting over.
Your rulesYour own AFE thresholds, permitted-overrun ceilings and which contract term governs each category.
Your recordsYour own authority extracts, cost ledgers, alert logs and cost review notes, as you already keep them.
Your systemsReads from your cost accounting system; memo drafts go to whoever signs off on AFEs.
Your screensThe categories, thresholds and wording your own cost control team already uses.
Want this for your team?
Talk to us
We can run this on your own AFEs and cost ledgers, inside your own environment.
Talk to us →