OverviewWhat it is
An embedding model maps content to a vector so that things similar in meaning are close together in space. That turns 'search by meaning' into 'find the nearest vectors' - the engine behind semantic search, recommendations, clustering, and the retrieval step of RAG.
At a glanceEmbeddings & Vector Search
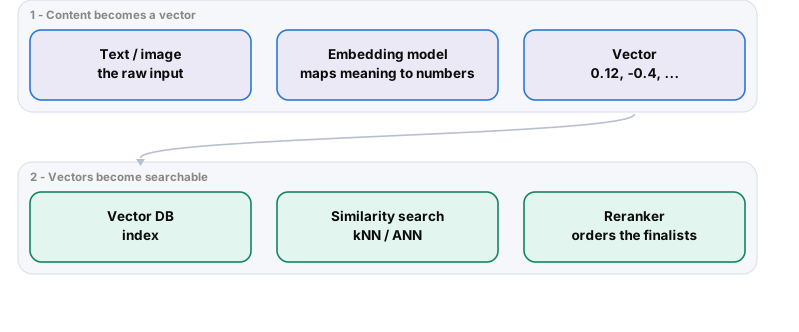
Similar meanings land close together, so 'search by meaning' becomes 'find the nearest vectors'.
CompareEmbedding models, side by side
Every embedding model worth knowing — hosted APIs and open weights — grouped by access. Filter or search across dimensions, context window, and language reach. Cost is shown as a model (per-token API vs self-host), not a price; see Costing for token math.
Every row has a page — what it does, what it costs you, and how to tell when it is the thing biting you.
CompareVector databases, side by side
The stores that hold the vectors, split into purpose-built engines and add-ons to a database you already run. Filter or search across hosting, index type, hybrid search, and license — the choice that governs recall, latency, and ops load.
Every row has a page — what it does, what it costs you, and how to tell when it is the thing biting you.
MechanicsHow it works
Embed content once and store the vectors in a vector database with an index for fast approximate nearest-neighbour (ANN) search. At query time, embed the question and pull the closest vectors; a reranker can reorder for precision.
Ground levelWhat you actually build


Meaning in, neighbours out — and four decisions wrapped around it. Retrieval breaks quietly, so the lane that matters is the one about what limits it.
LandscapeTypes & approaches
Click a highlighted type to open its own page — concept, use case, and diagram.
FeasibilityArchitecture & feasibility
Architecture & feasibility
- Embedding model + vector store + index type set recall, latency, and cost. ANN trades a little accuracy for big speed at scale - a key feasibility knob.
- Vector dimensionality and corpus size drive memory and cost; at large scale, index choice (HNSW, IVF) becomes a real capacity-planning decision.
- Re-embedding when you change models is expensive - version your embeddings and plan migrations.
In practiceWhat it means for building
Embeddings are why 'search that understands what I mean' works. They power the retrieval that lets a chatbot answer from your data.
Your embedding model, vector store (Pinecone, pgvector, FAISS, Weaviate), and index type govern recall, latency, and cost of any retrieval system.
GlossaryKey terms
CheckCheck your understanding
Semantic vs keyword search?
Keyword matches exact words; semantic search matches meaning via embeddings, so 'car trouble' can find 'engine won't start'.
What is a vector database for?
Storing embeddings and returning the nearest ones fast - the retrieval backbone of RAG and recommendations.
What limits retrieval quality?
Embedding model fit, chunking, index recall, and reranking - each is a tunable part of the pipeline.
What changedWhat changed here
Nothing in the daily brief has touched this page since 2026-09-25. The sweep runs every morning and checks every page on this site; when it finds something for this one, it lands here.
Three kinds of claim, strongest first. Signal runs every morning.